Paid vs. Free subcategories
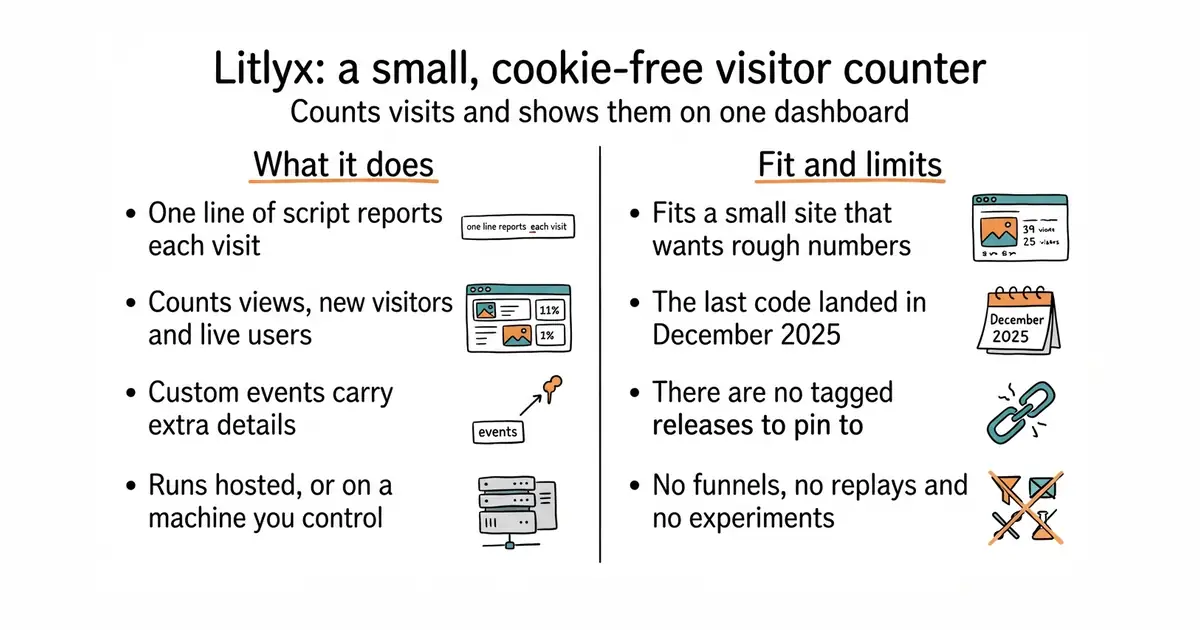

Litlyx/litlyx 💎 hidden gem
A small, cookie-free visitor counter with its own dashboard, which you can run yourself.
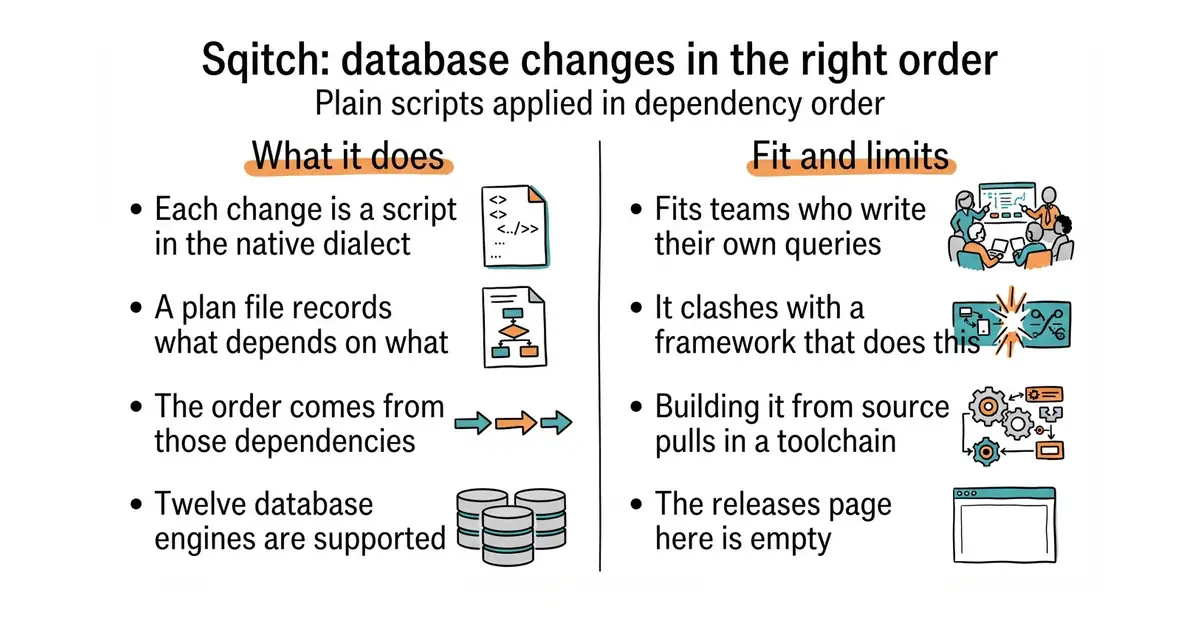

sqitchers/sqitch
Applies database changes in dependency order, written as plain SQL files rather than numbered migrations.
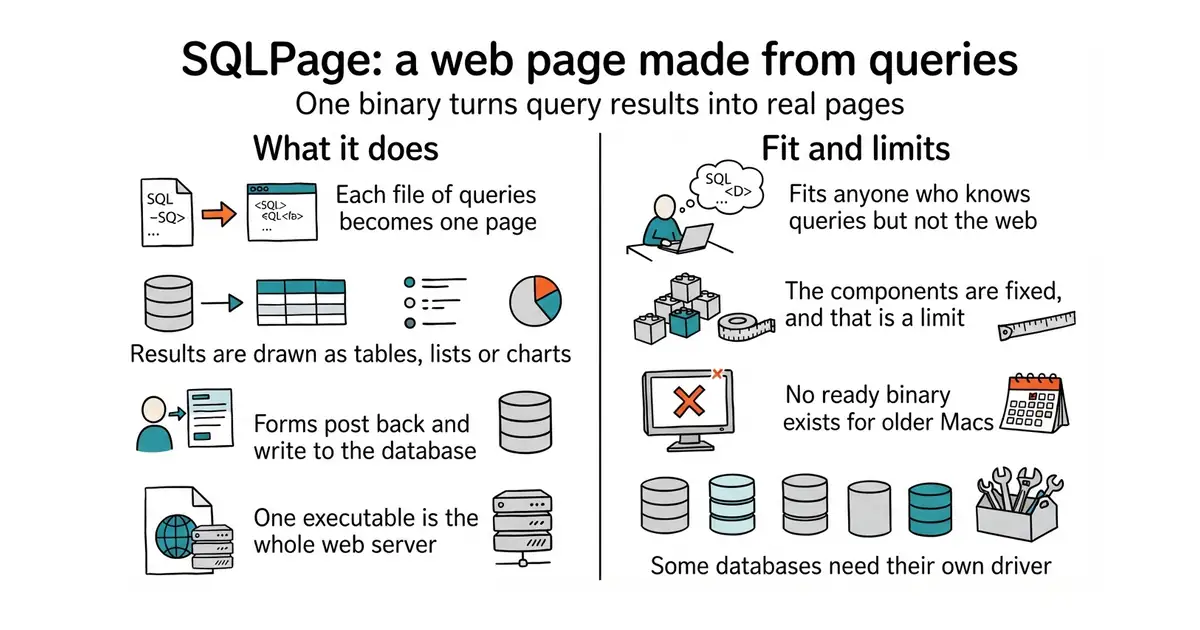

sqlpage/SQLPage 💎 hidden gem
A single-file web server that turns SQL query results into real web pages, forms and charts.
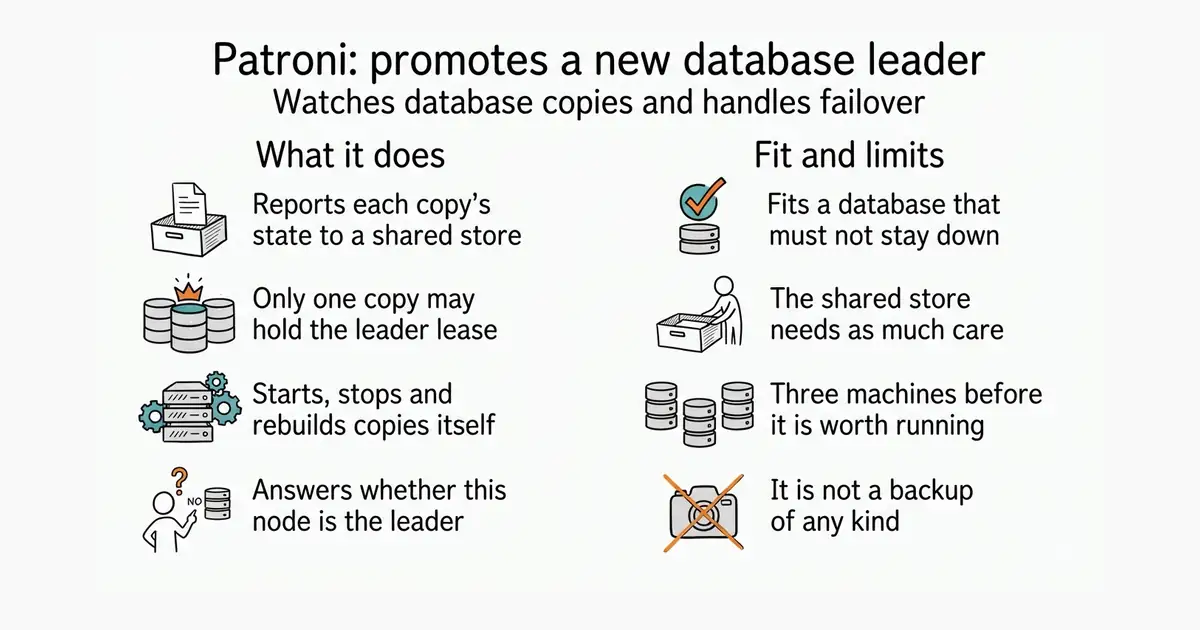

patroni/patroni
Watches a group of PostgreSQL copies and promotes a new leader when the leader fails.
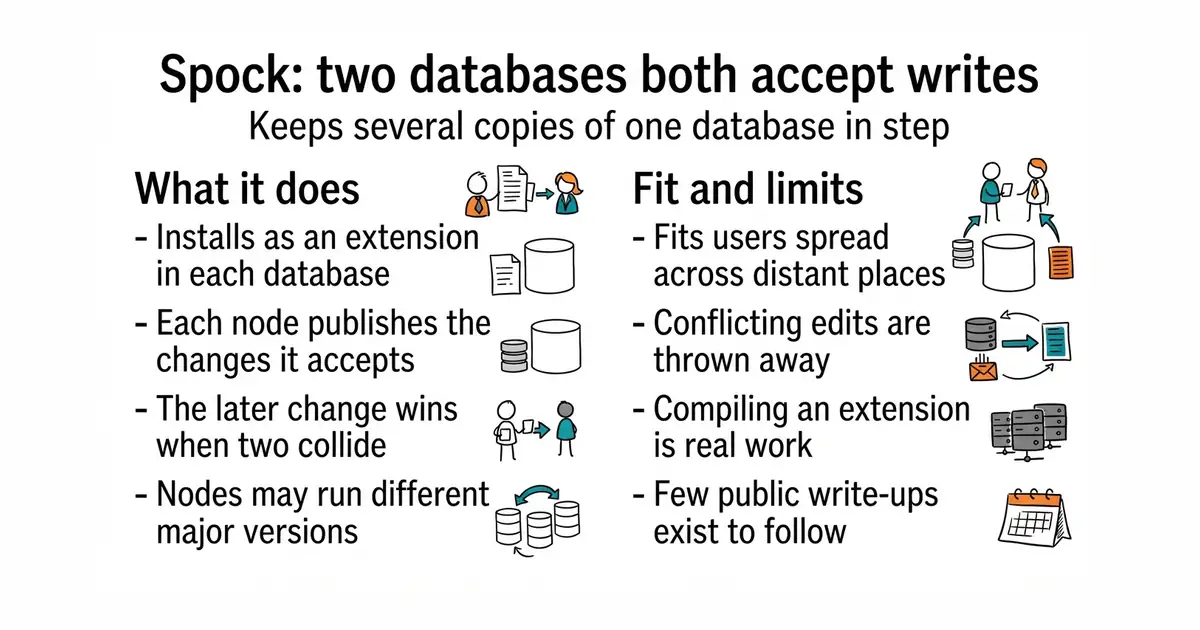

pgEdge/spock 💎 hidden gem
An add-on that lets several PostgreSQL databases all accept changes and keep each other in step.
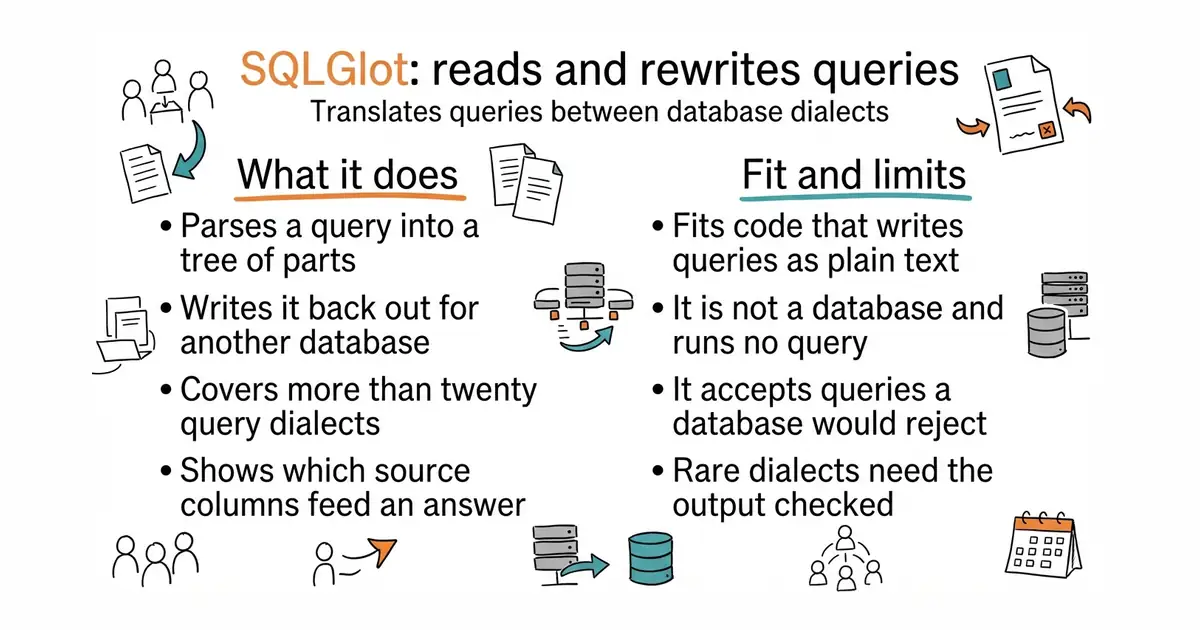

tobymao/sqlglot
Reads, rewrites and translates SQL between more than twenty database dialects, without a database.
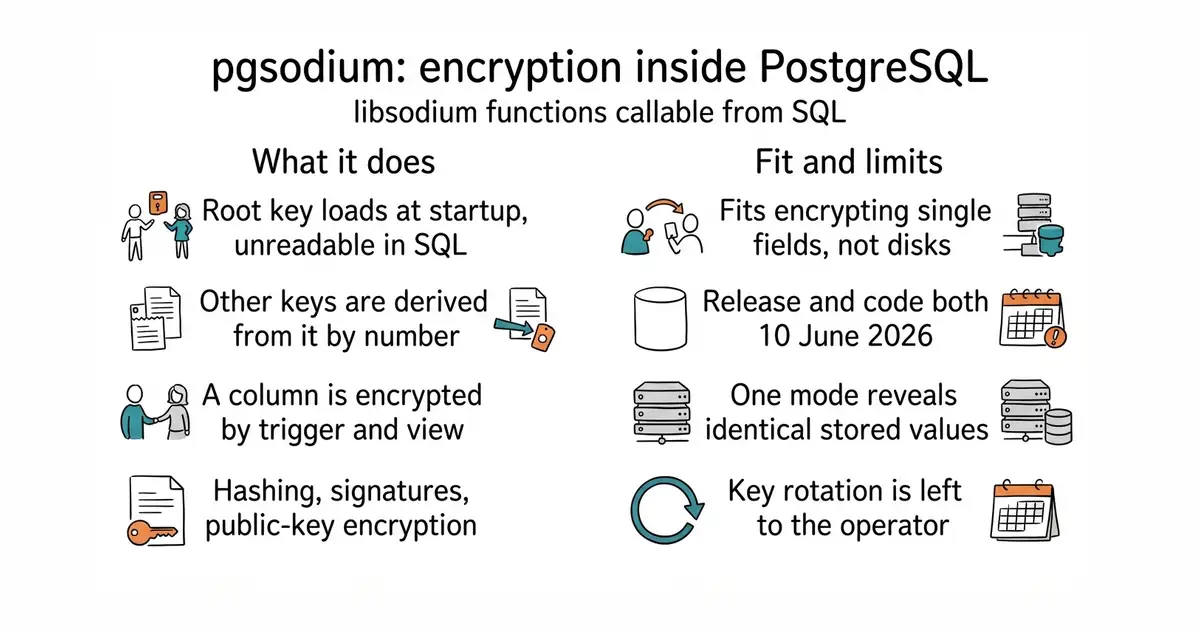

michelp/pgsodium 💎 hidden gem
A PostgreSQL extension that brings libsodium's encryption functions into SQL, with a root key the database cannot read back.
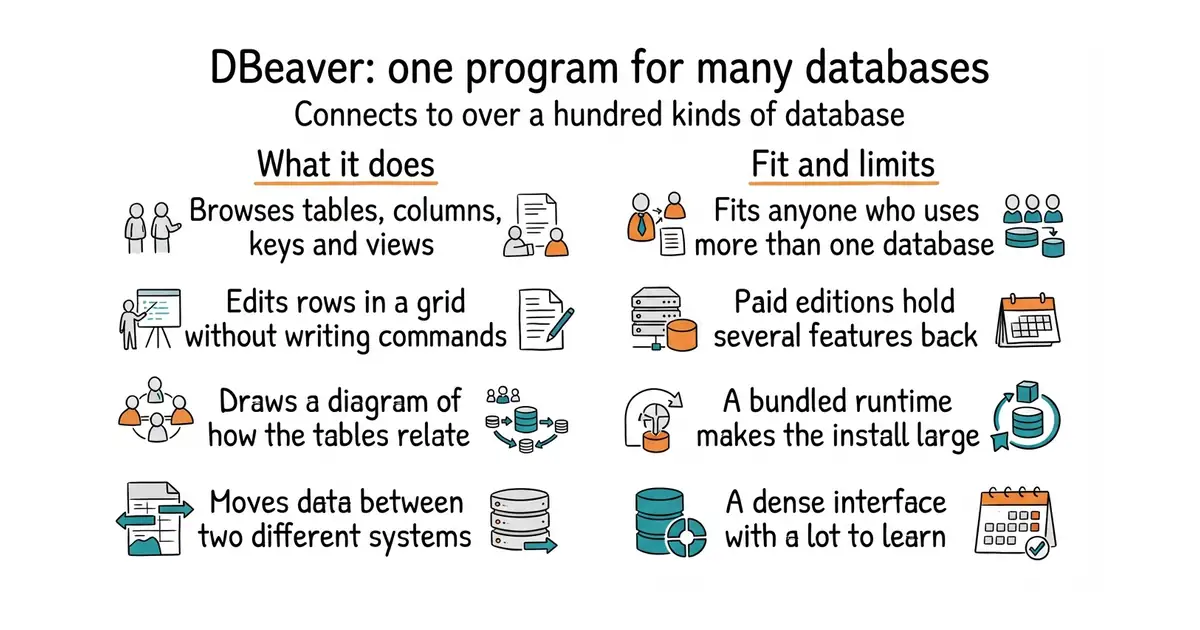

dbeaver/dbeaver
A free desktop program that connects to more than a hundred kinds of database and lets you browse and edit them.
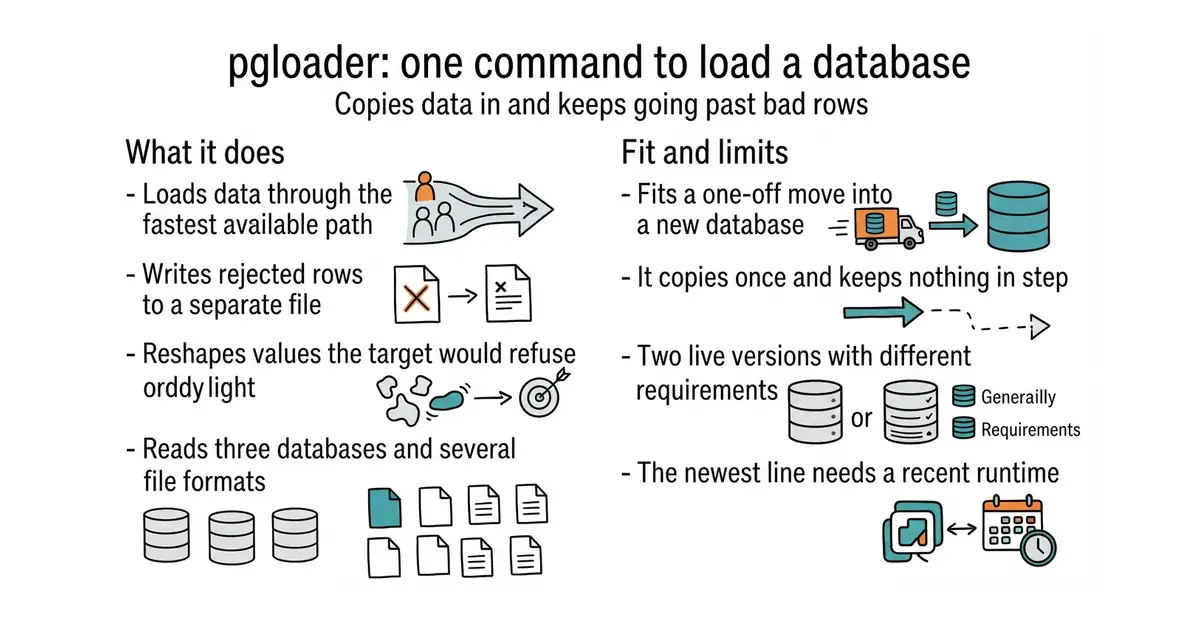

dimitri/pgloader
Loads data into PostgreSQL from other databases and from files, keeping going when individual rows fail.

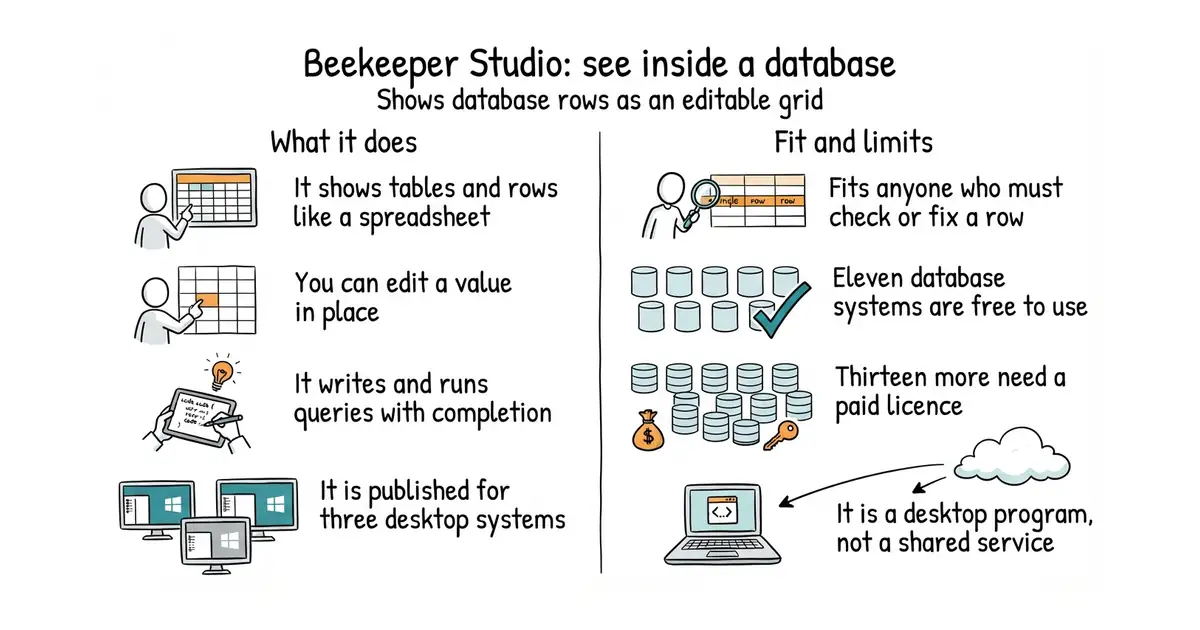

beekeeper-studio/beekeeper-studio
A desktop window onto a database, so you can read and edit rows without writing commands.
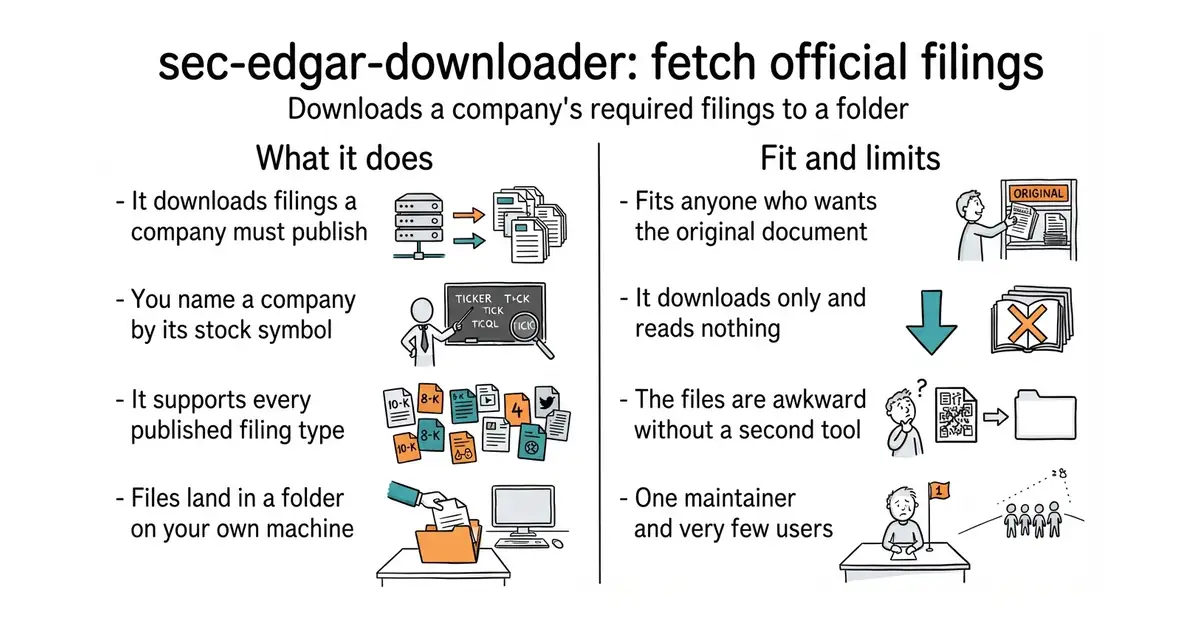

jadchaar/sec-edgar-downloader 💎 hidden gem
A small Python package that downloads a United States company's official filings to a local folder.
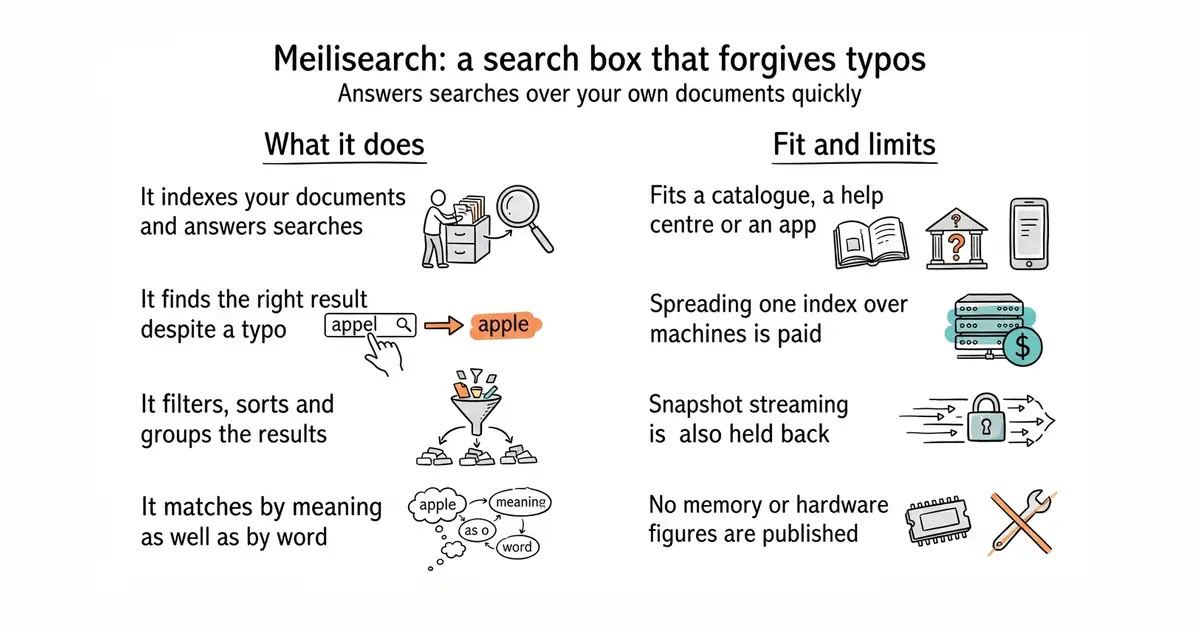

meilisearch/meilisearch
A search engine you run yourself, built for fast answers and forgiving spelling.
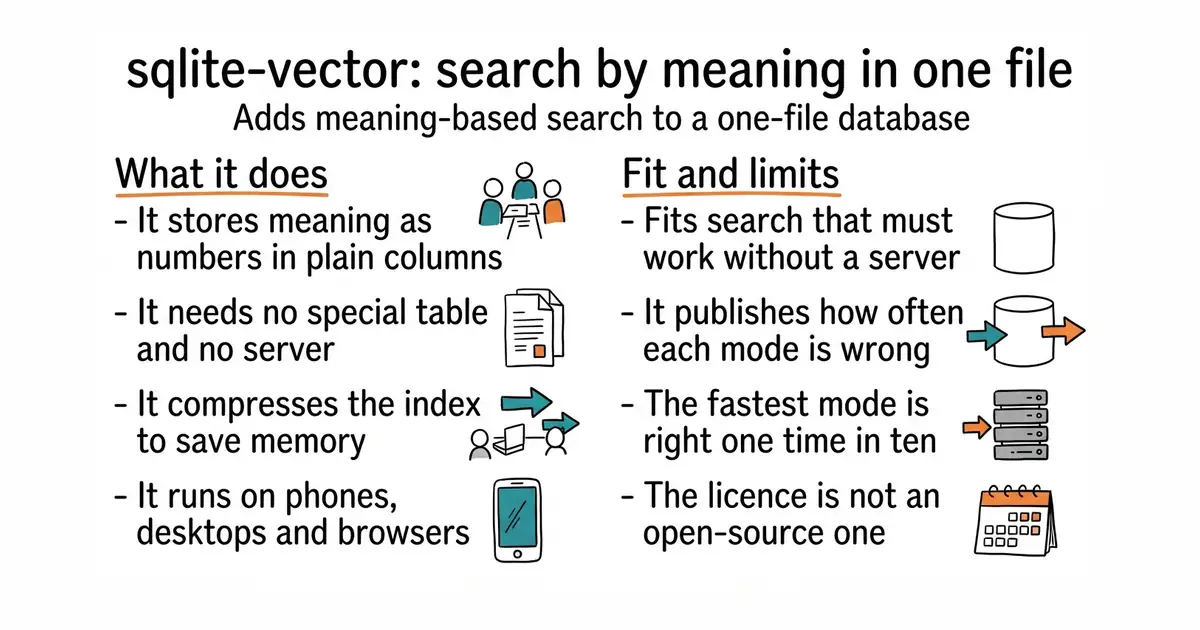

sqliteai/sqlite-vector 💎 hidden gem
An add-on that gives the single-file SQLite database meaning-based search, with its own accuracy figures printed in the README.
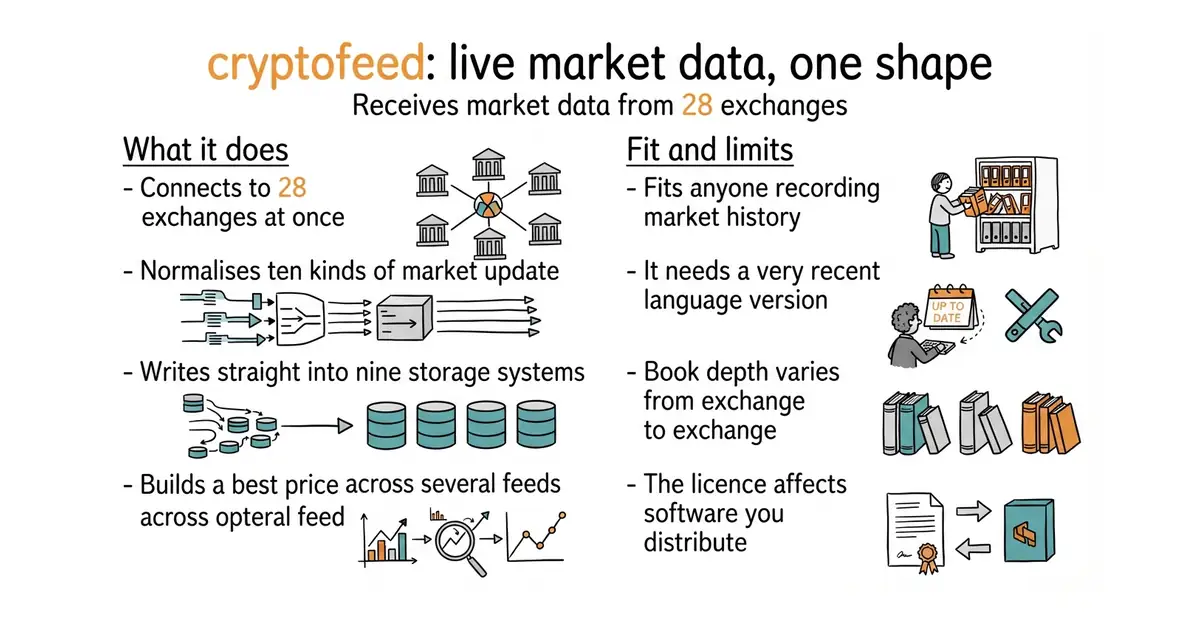

bmoscon/cryptofeed 💎 hidden gem
Receives live market data from 28 exchanges, normalises it to one shape, and can write it straight into nine kinds of store.
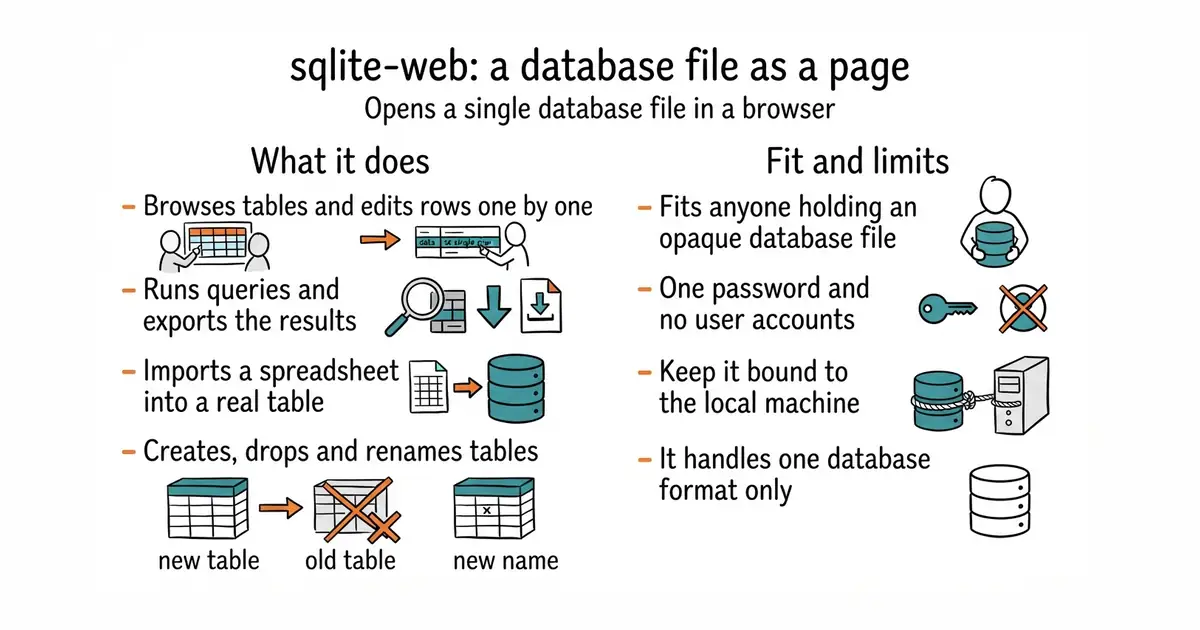

coleifer/sqlite-web
Opens a single SQLite database file as a web page for browsing, editing, querying, importing and exporting.
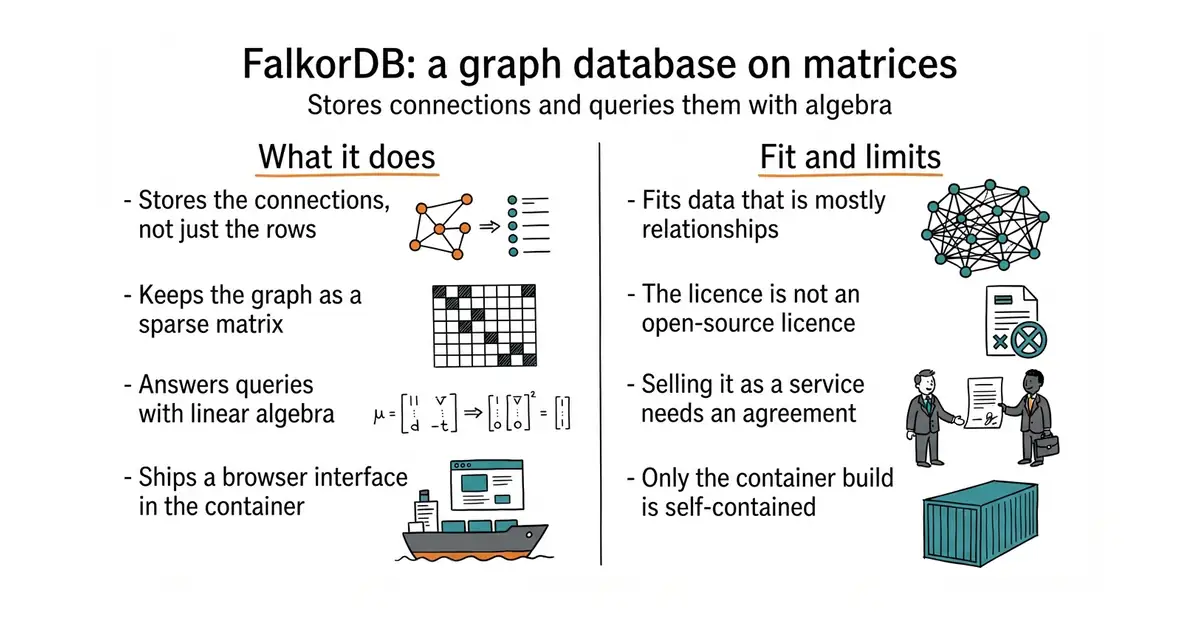

FalkorDB/FalkorDB
A graph database that keeps the connections as sparse matrices and answers queries with linear algebra.
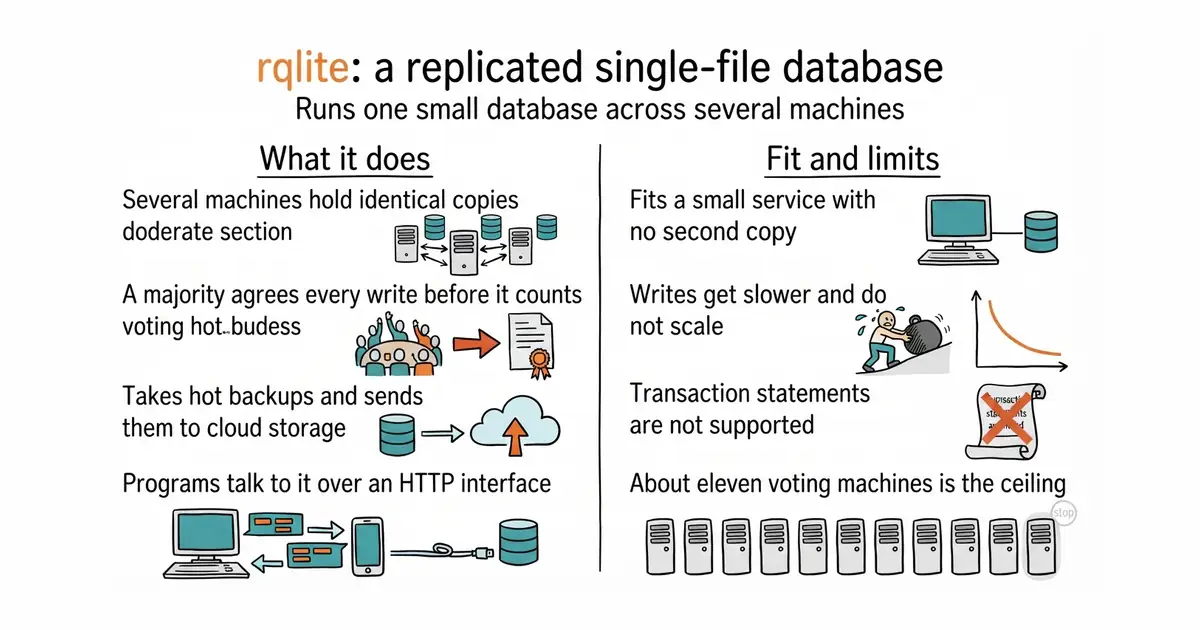

rqlite/rqlite
Runs one small single-file database across several machines so a single failure does not take it down.
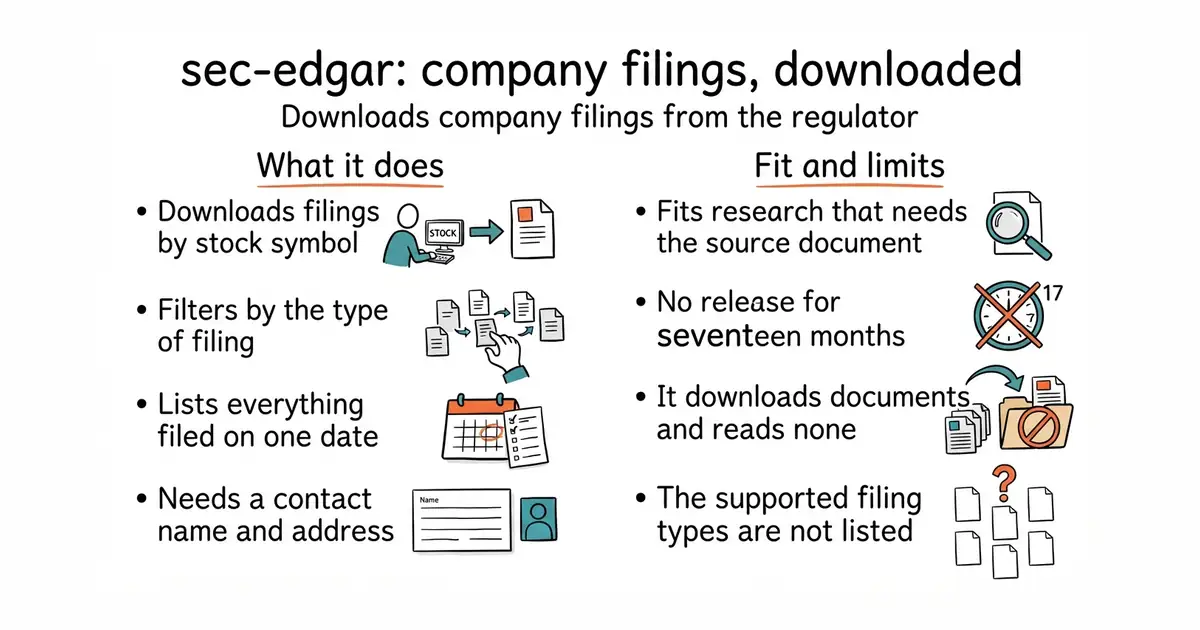

sec-edgar/sec-edgar 💎 hidden gem
Downloads a company's filings from the United States regulator's public archive, by stock symbol or company number.
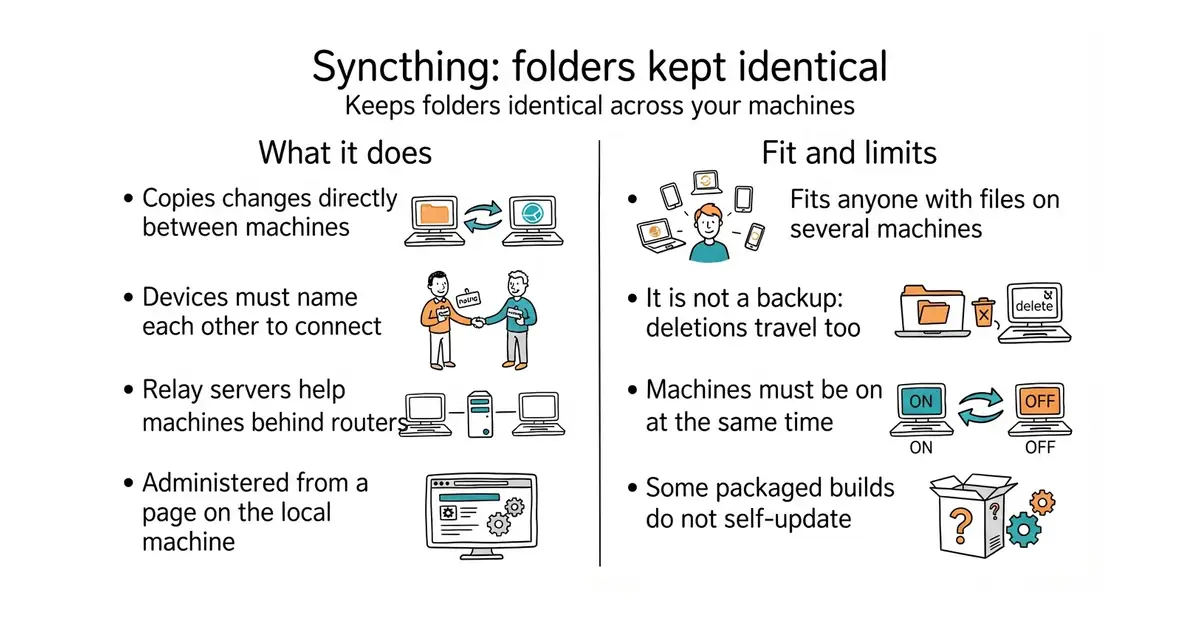

syncthing/syncthing
Keeps chosen folders identical across two or more machines, continuously, with no company's server holding the files.
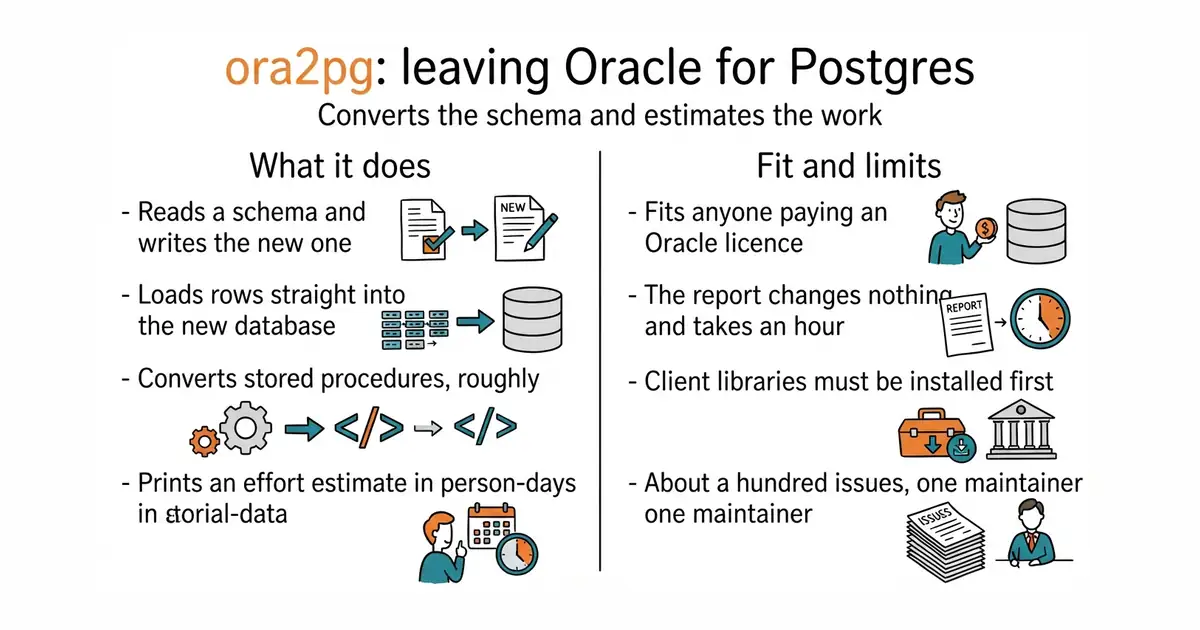

darold/ora2pg 💎 hidden gem
It converts an Oracle database schema and data into PostgreSQL, and estimates the effort first.
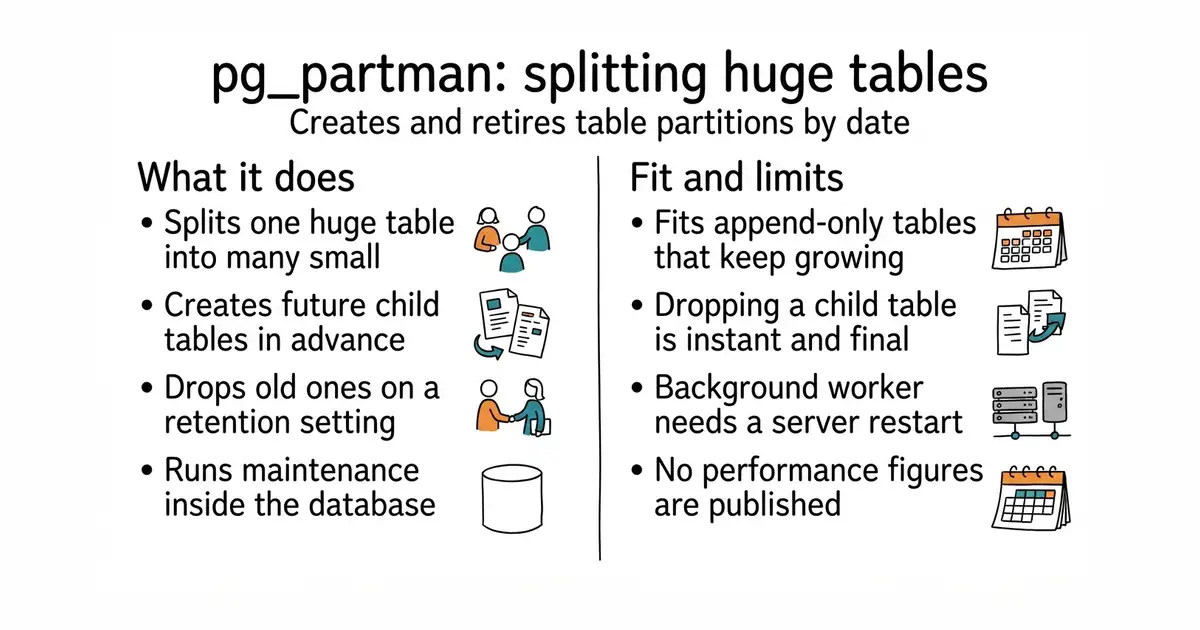
pgpartman/pg_partman 💎 hidden gem
A PostgreSQL extension that creates and maintains partitioned tables by time or by number.
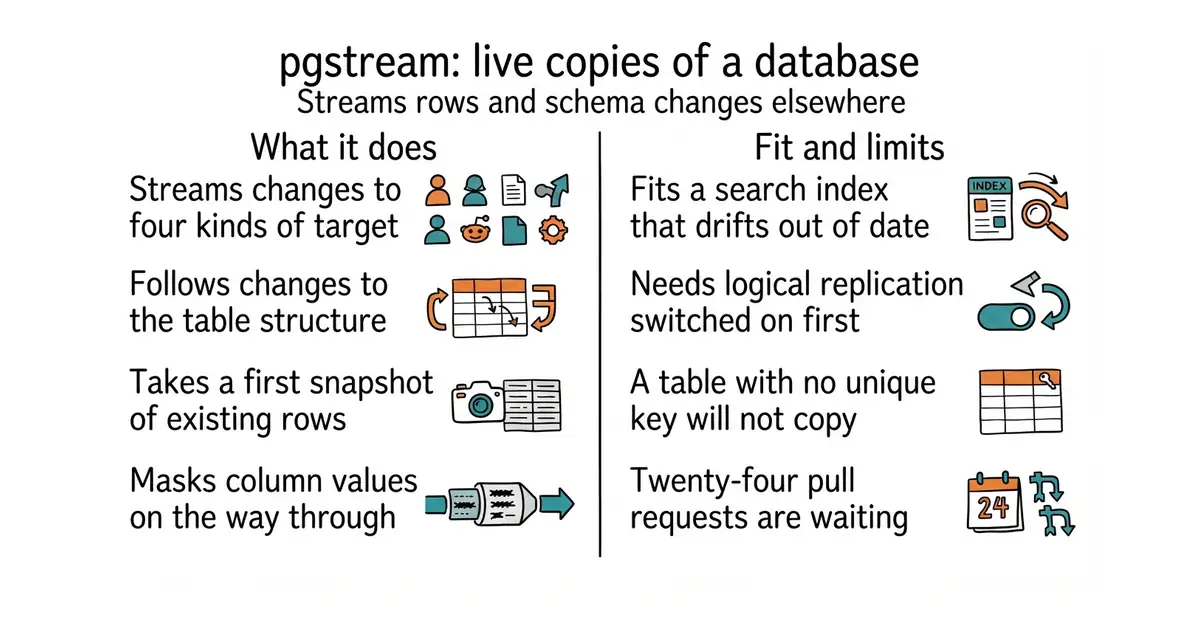

xataio/pgstream 💎 hidden gem
It streams PostgreSQL changes, including changes to the table structure, to another system.
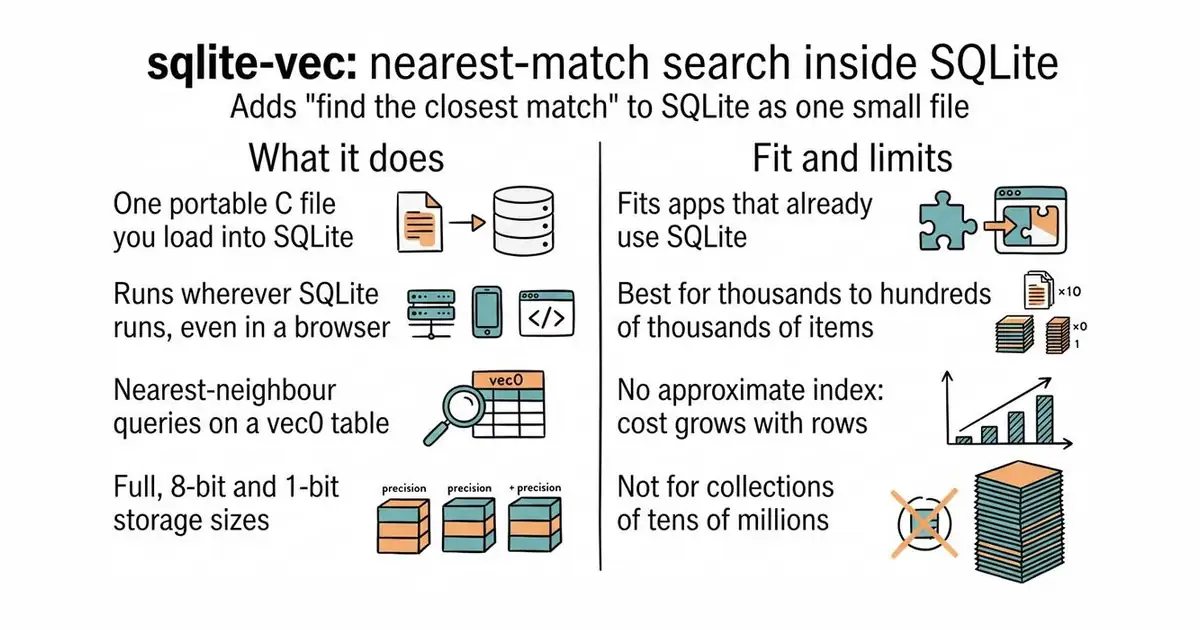

asg017/sqlite-vec
Adds find-the-closest-match to SQLite as one small portable file, with no server and nothing to compile.
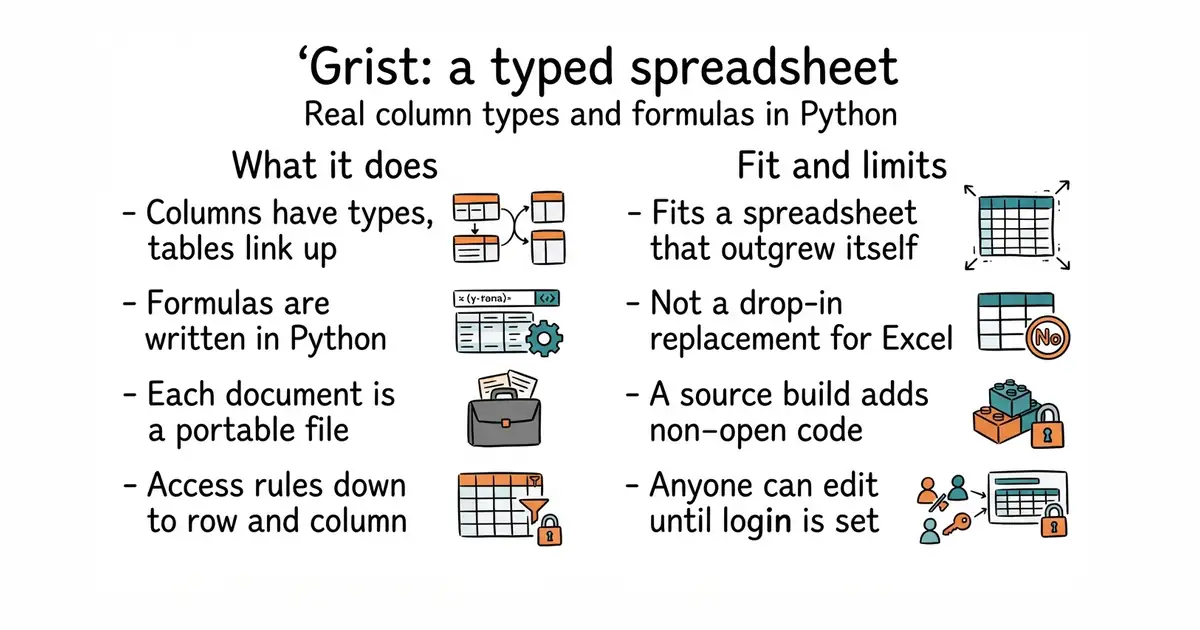

gristlabs/grist-core
A self-hosted spreadsheet with real column types, table references and Python formulas.
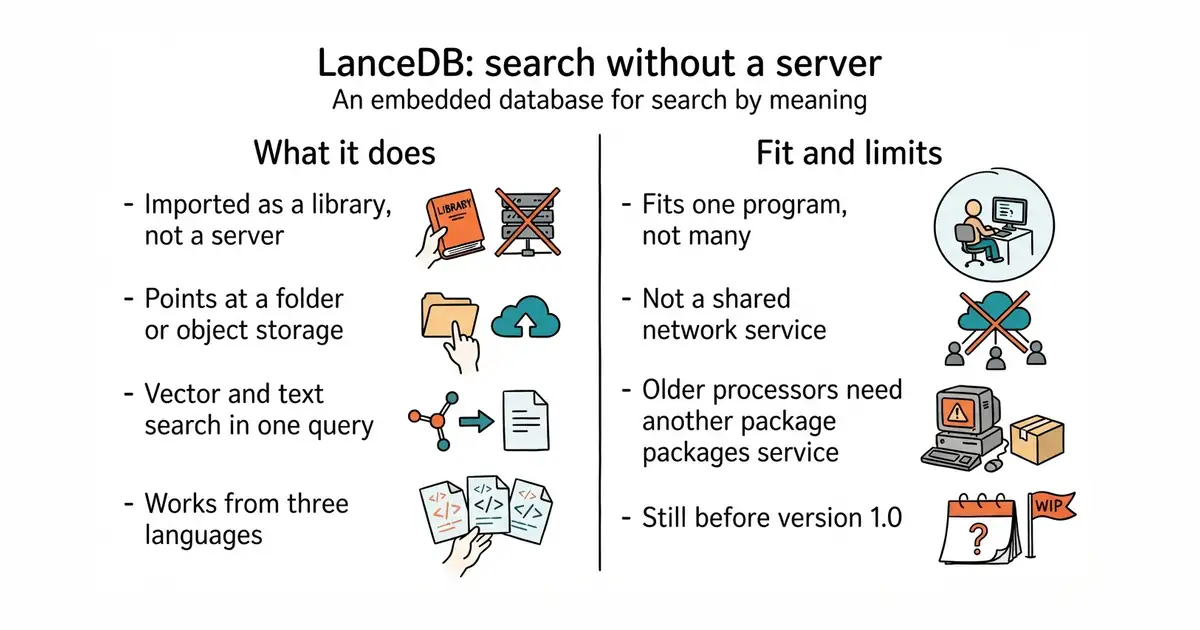

lancedb/lancedb
An embedded database for embeddings, imported as a library rather than run as a server.
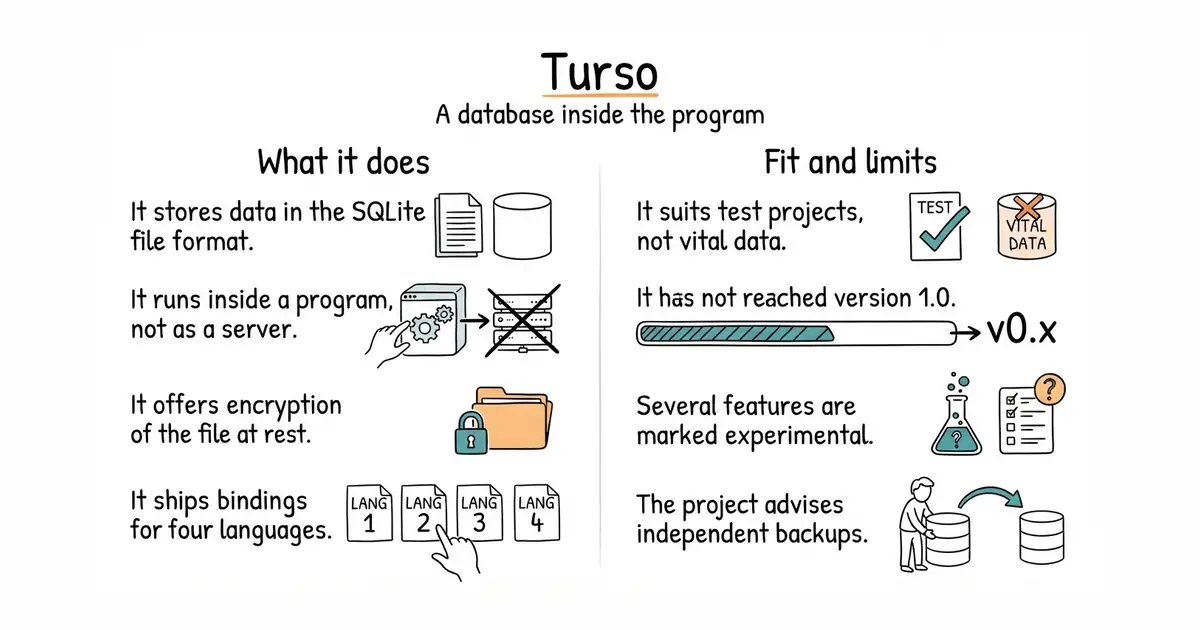

tursodatabase/turso
A rewrite of SQLite in Rust that reads the same files and has not yet reached version 1.0.


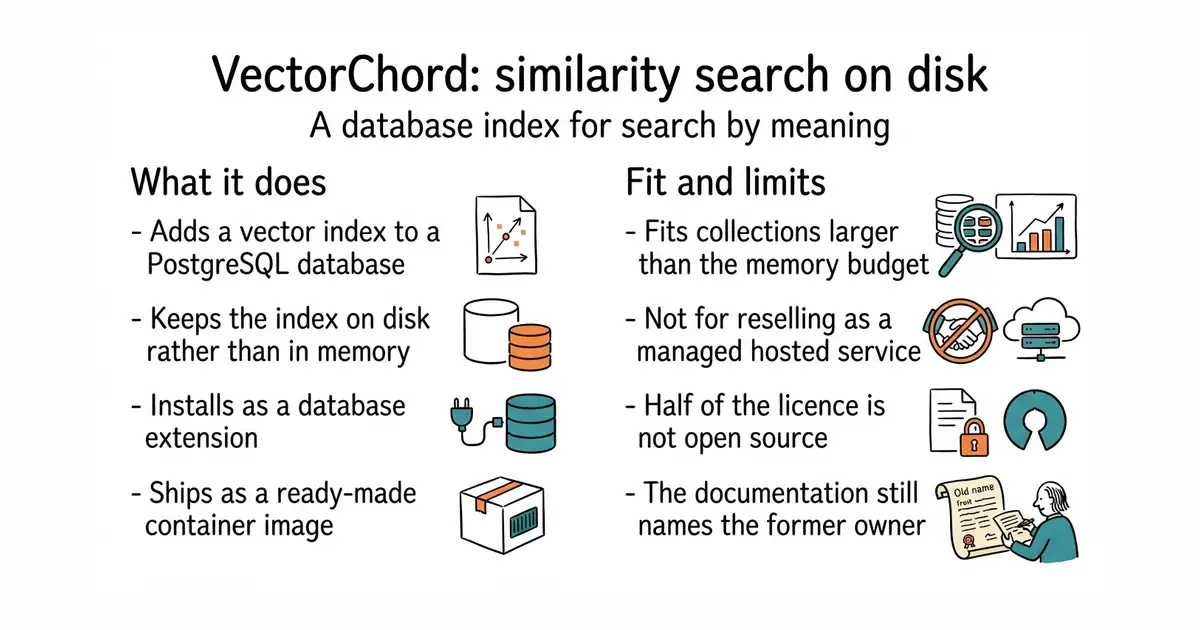
supervc-stack/VectorChord 💎 hidden gem
A PostgreSQL index for similarity search that lives on disk rather than in memory.

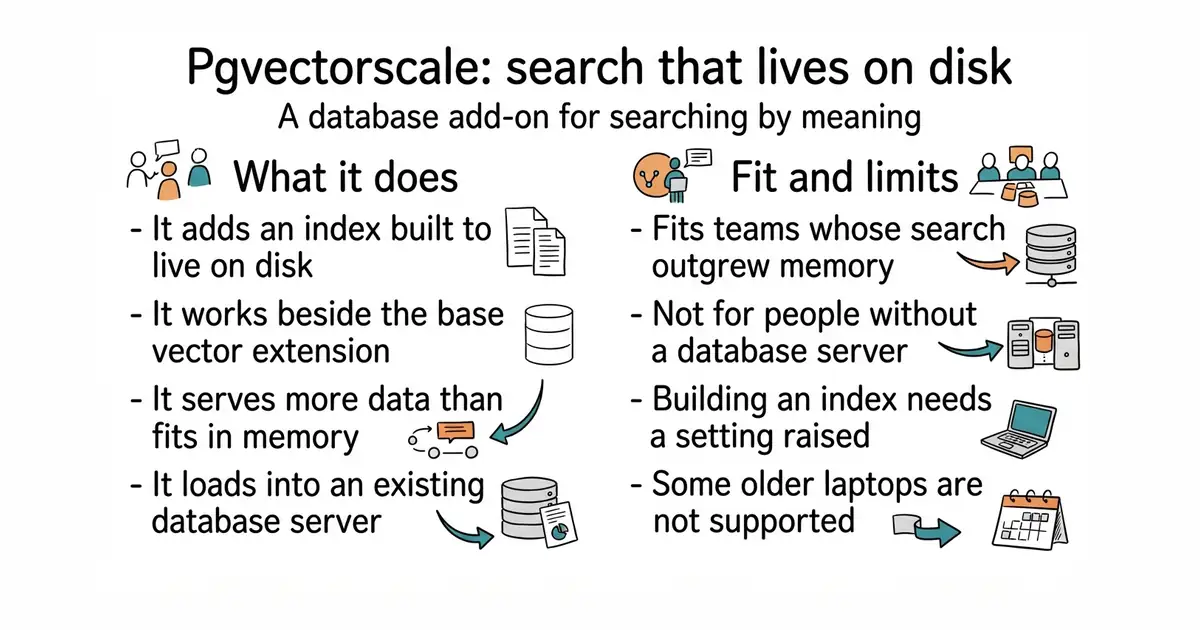

timescale/pgvectorscale
A PostgreSQL add-on that makes similarity search work on more data than fits in memory.




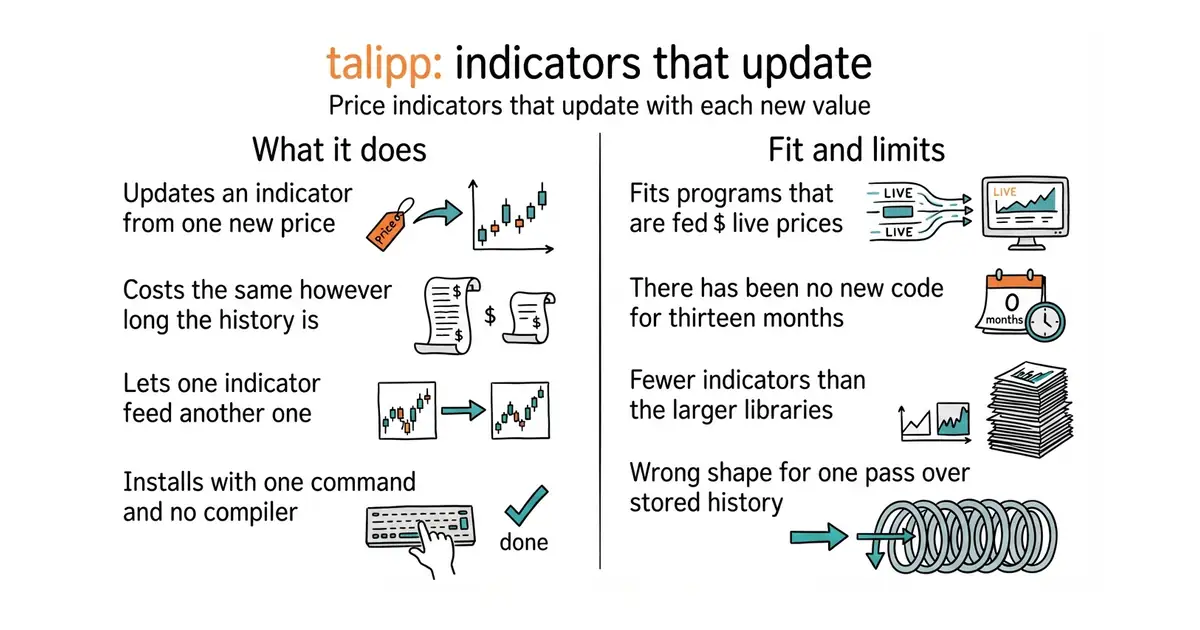

nardew/talipp 💎 hidden gem
Python financial indicators that update as each new price arrives, instead of recalculating the whole series.
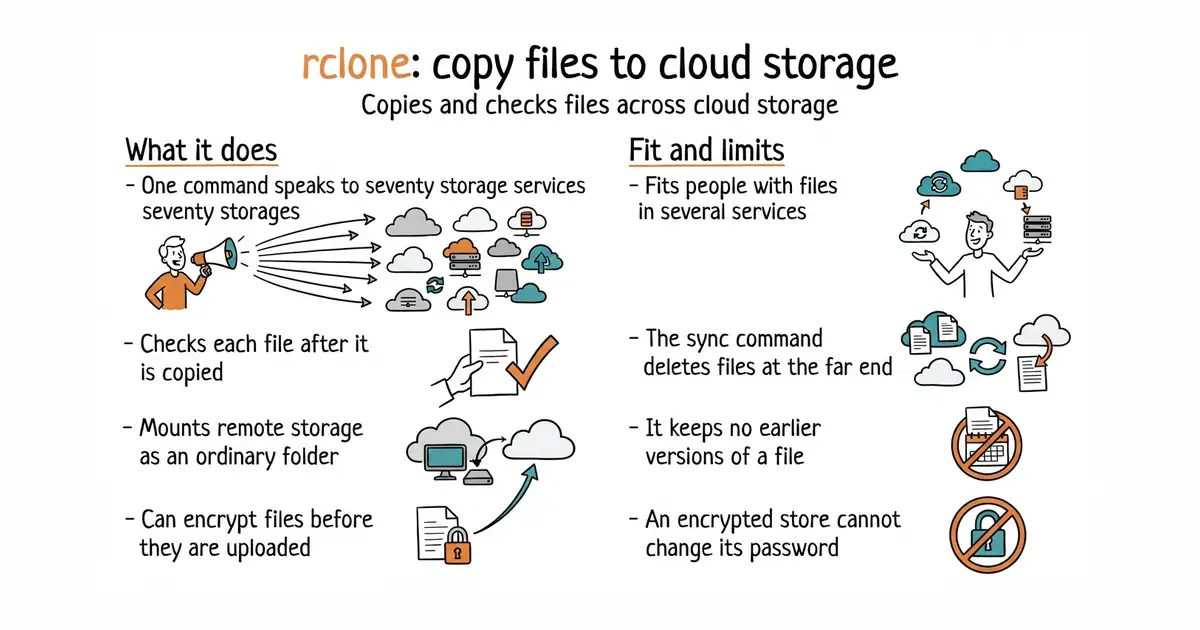

rclone/rclone
A command-line program that copies, syncs and verifies files across more than seventy kinds of cloud storage.
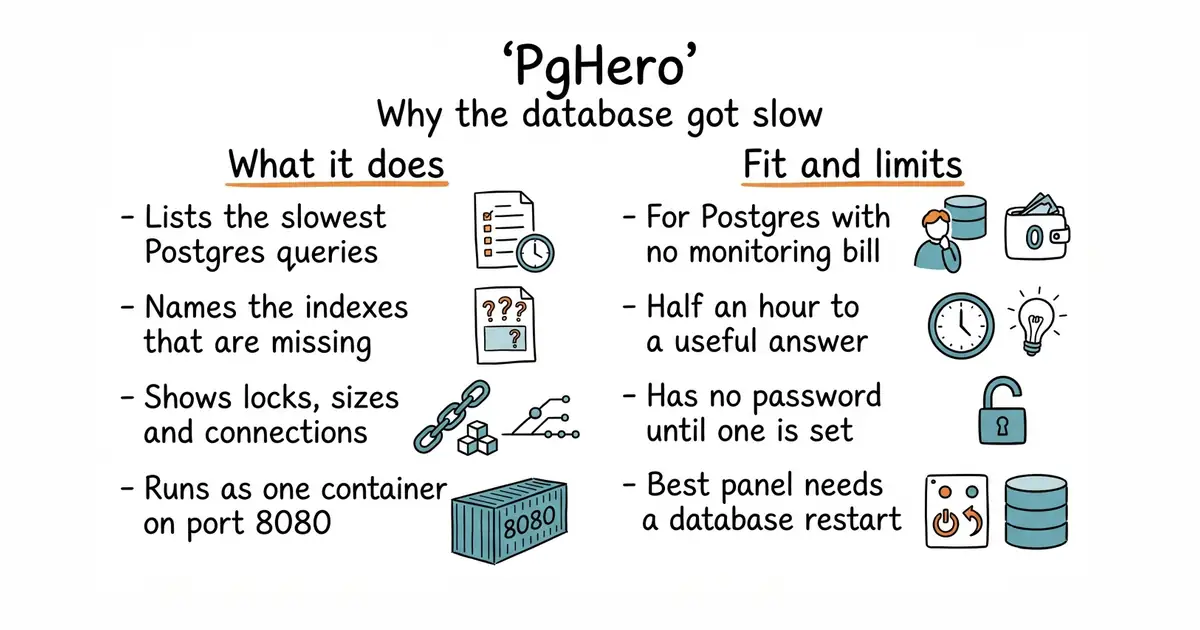

ankane/pghero
A web dashboard that shows which PostgreSQL queries are slow and which indexes are missing.
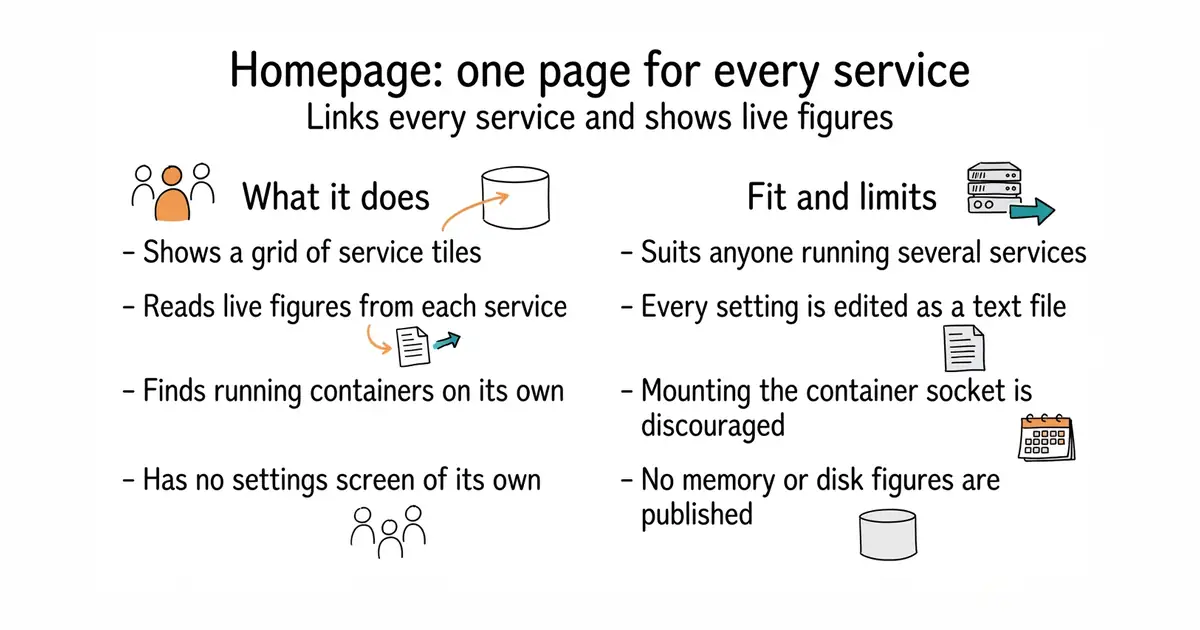

gethomepage/homepage
One page that links to every service you run and shows live figures from each of them.
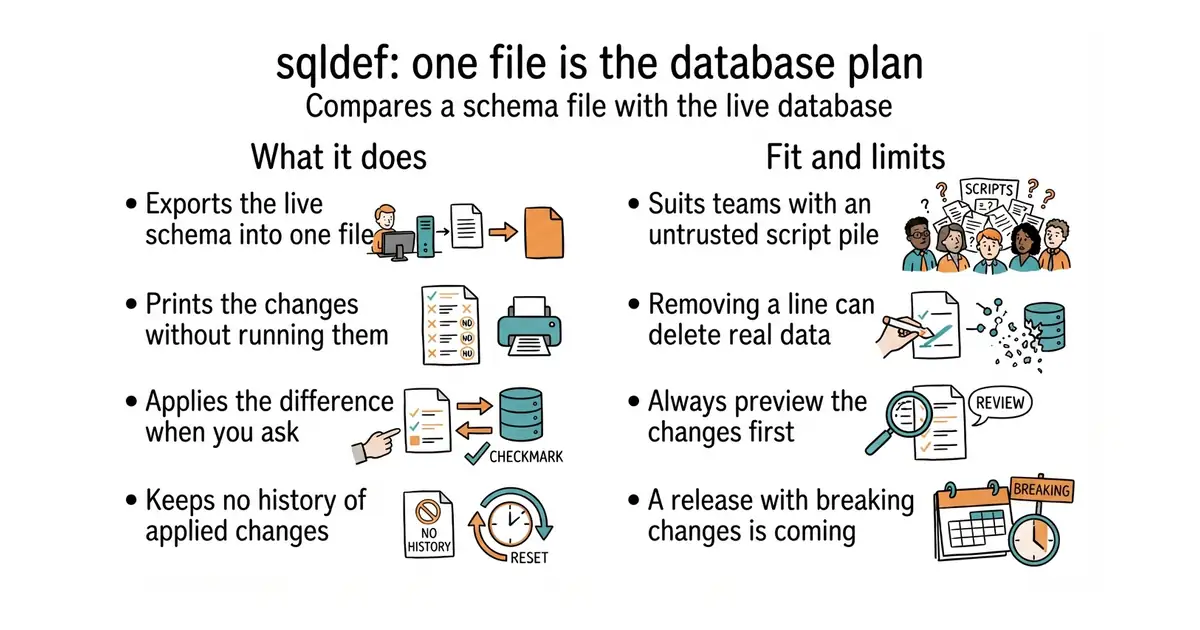

sqldef/sqldef
You keep one file describing the database you want, and it works out and applies the difference.
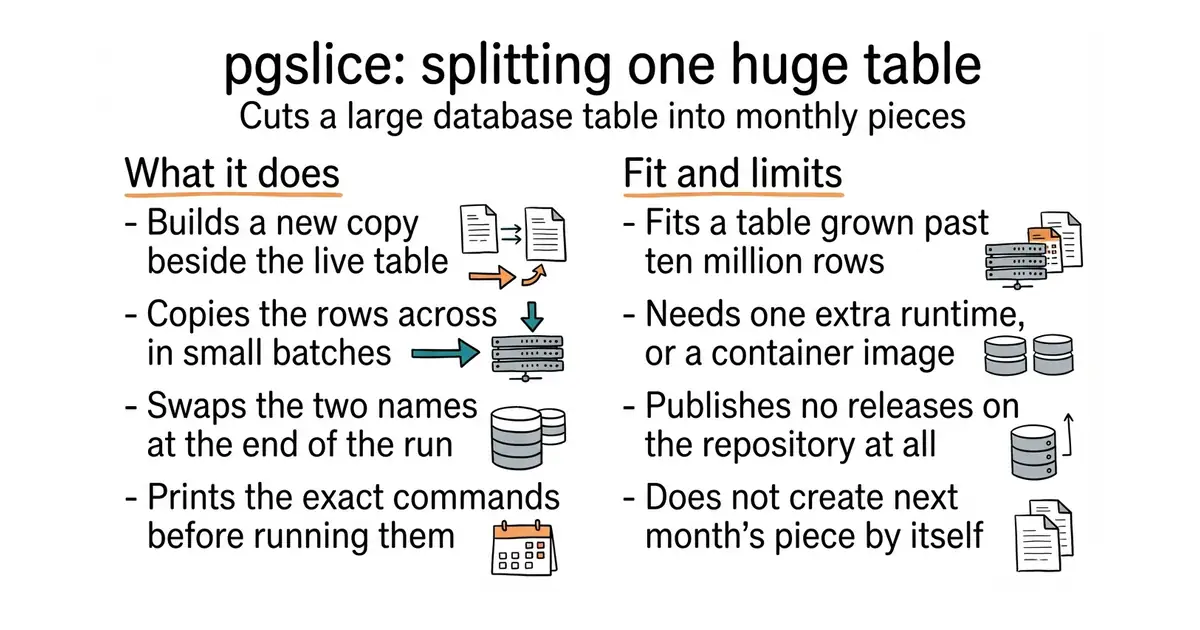

ankane/pgslice 💎 hidden gem
It splits a huge PostgreSQL table into monthly pieces without stopping the database.

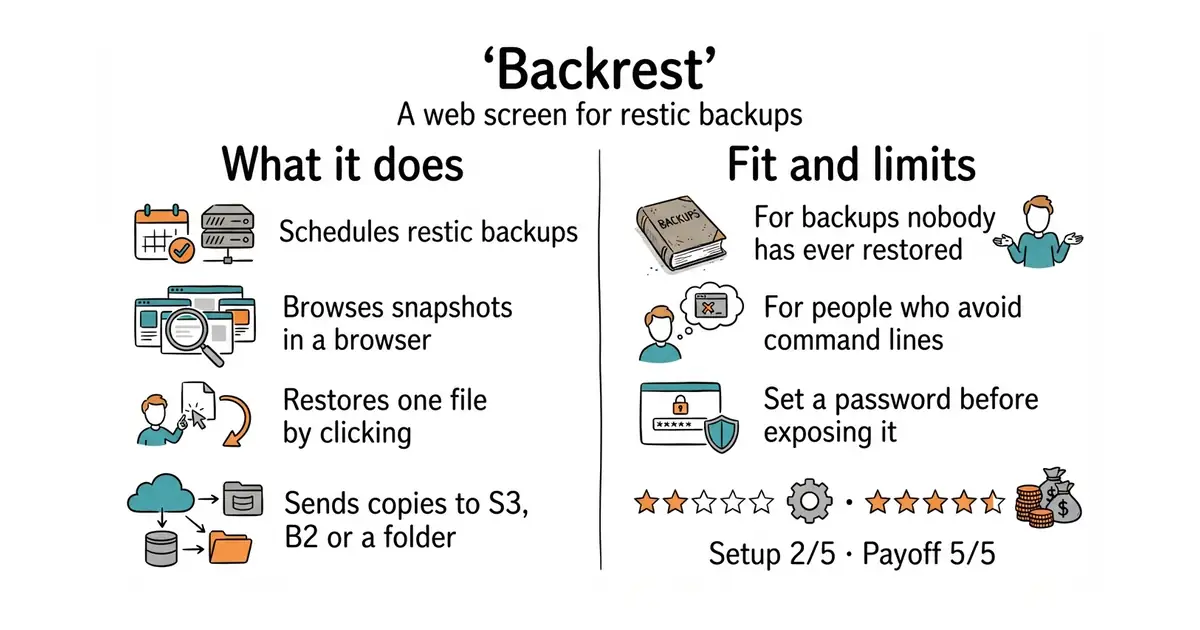

garethgeorge/backrest
A web screen that schedules restic backups and restores single files by clicking.


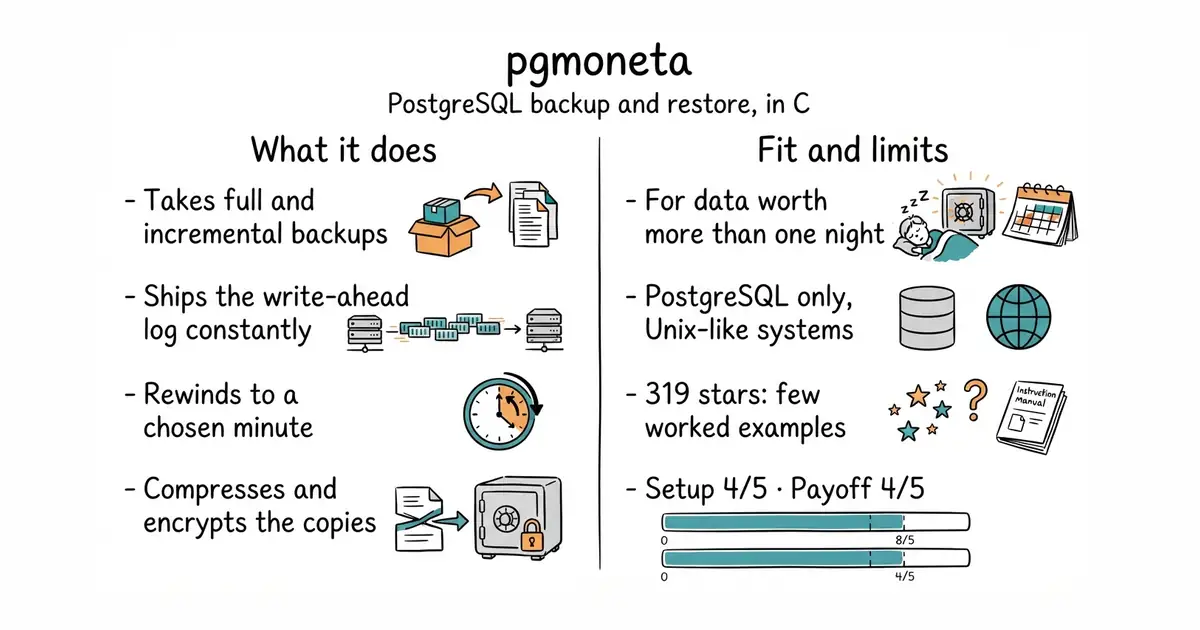

pgmoneta/pgmoneta 💎 hidden gem
Backup and restore for PostgreSQL, written in C, able to rewind to a chosen moment.


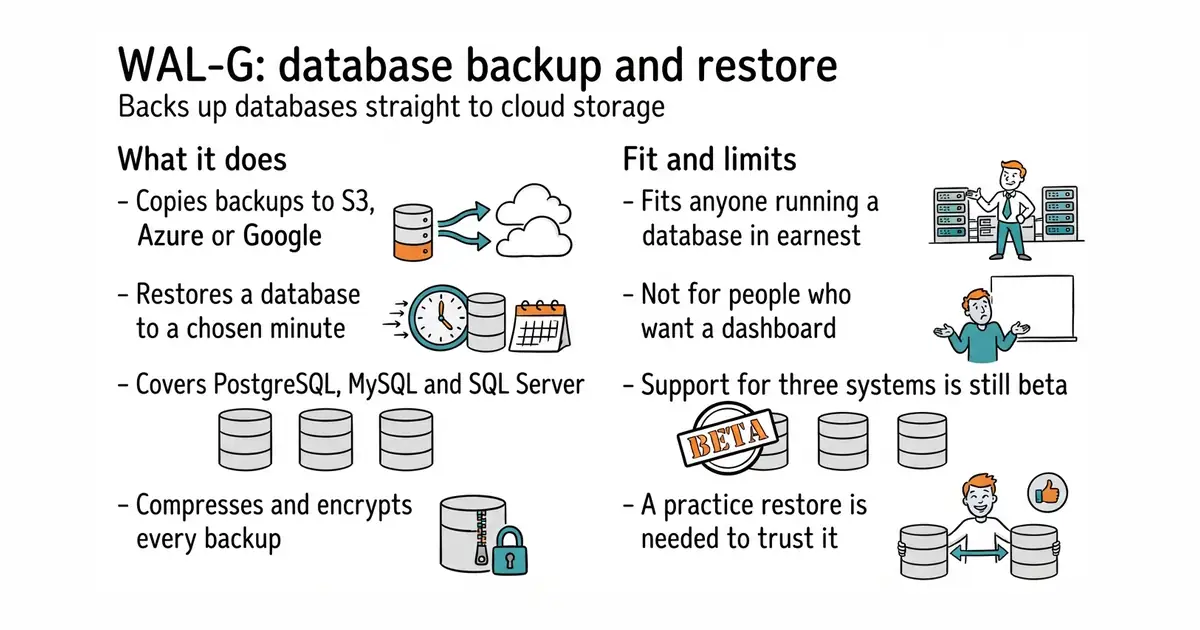

wal-g/wal-g
Backup and restore for several database systems, straight into cloud storage, able to rewind to any chosen point in time.
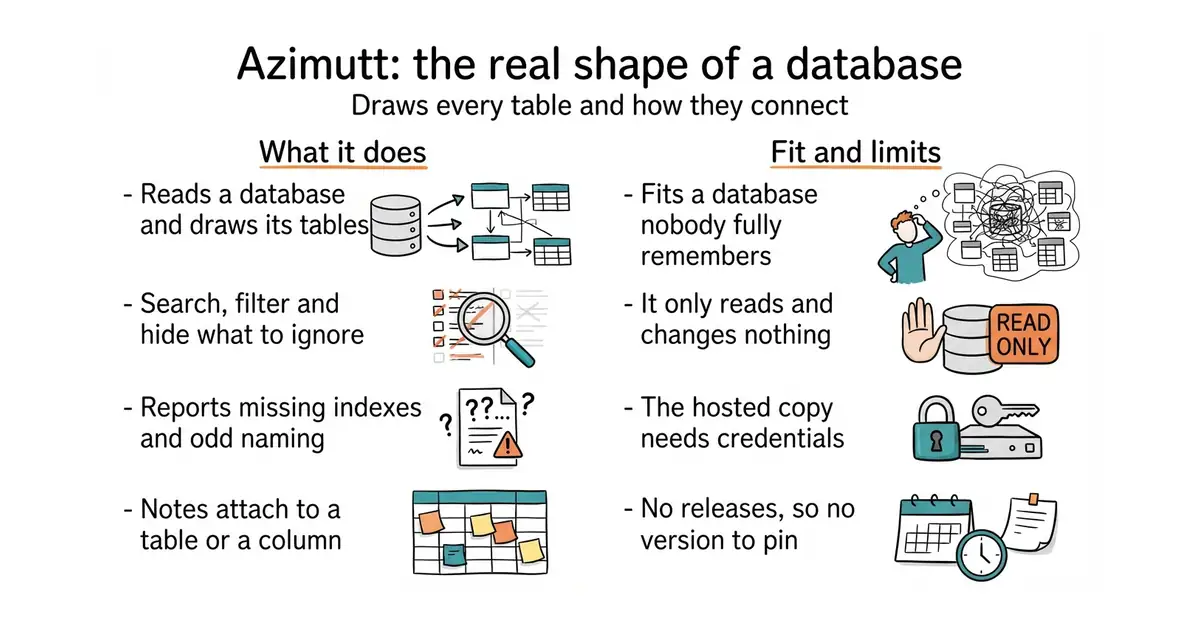

azimuttapp/azimutt 💎 hidden gem
It draws the real shape of a database so it can be explored instead of guessed at.
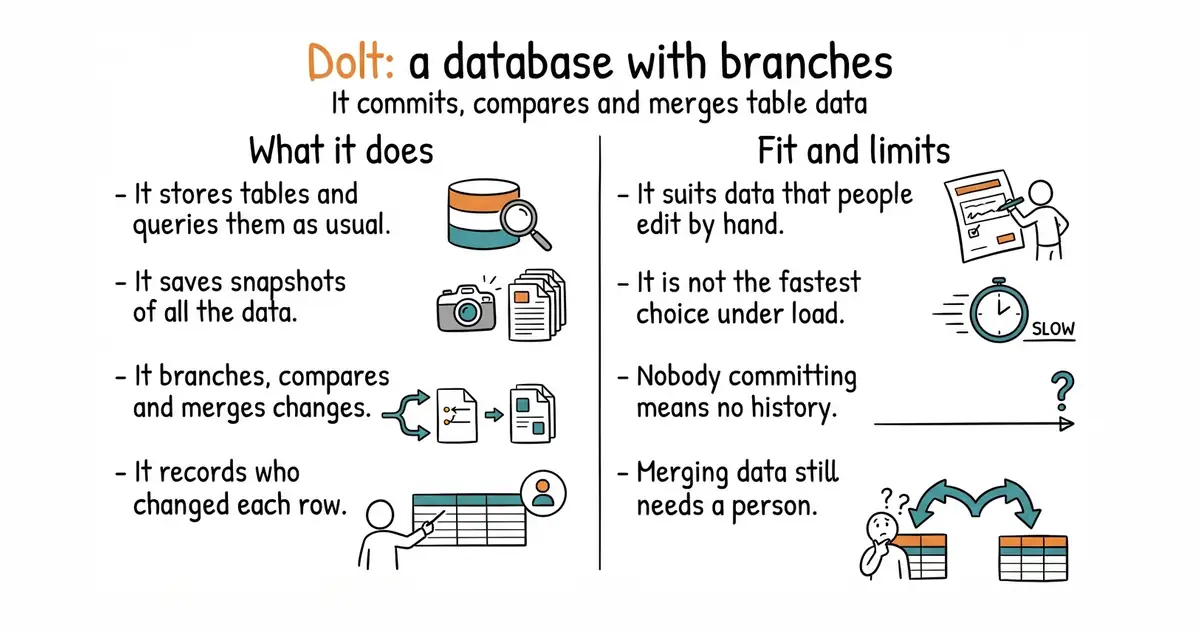

dolthub/dolt
A SQL database that can be branched, committed, compared and merged like a code repository.
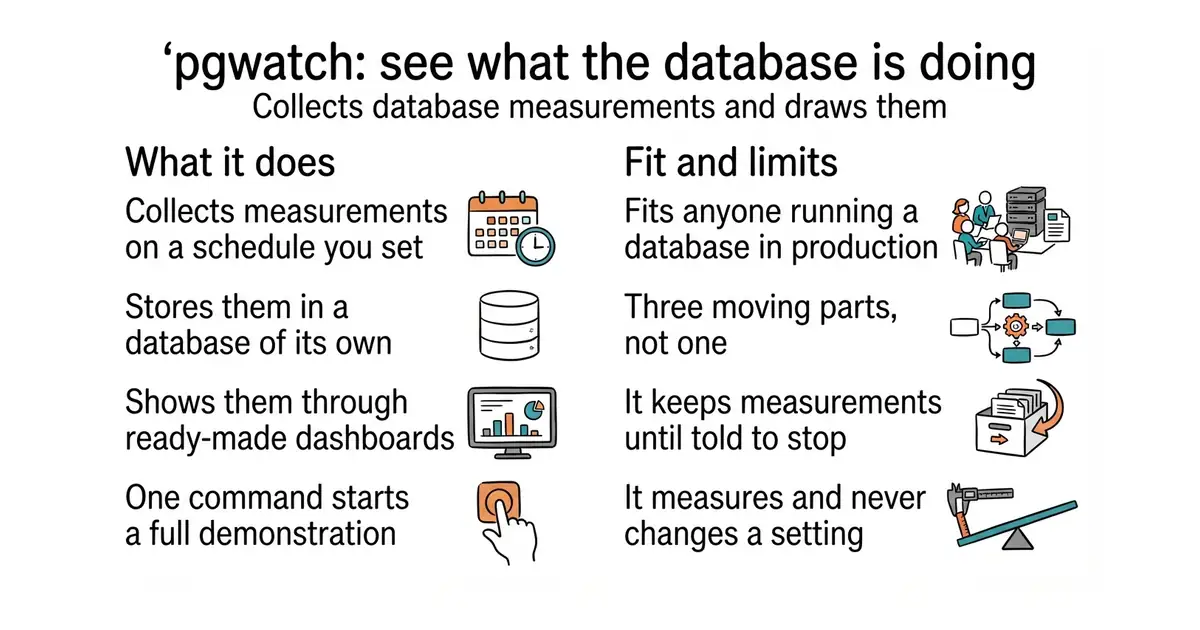

cybertec-postgresql/pgwatch 💎 hidden gem
Continuous PostgreSQL monitoring with ready-made dashboards.
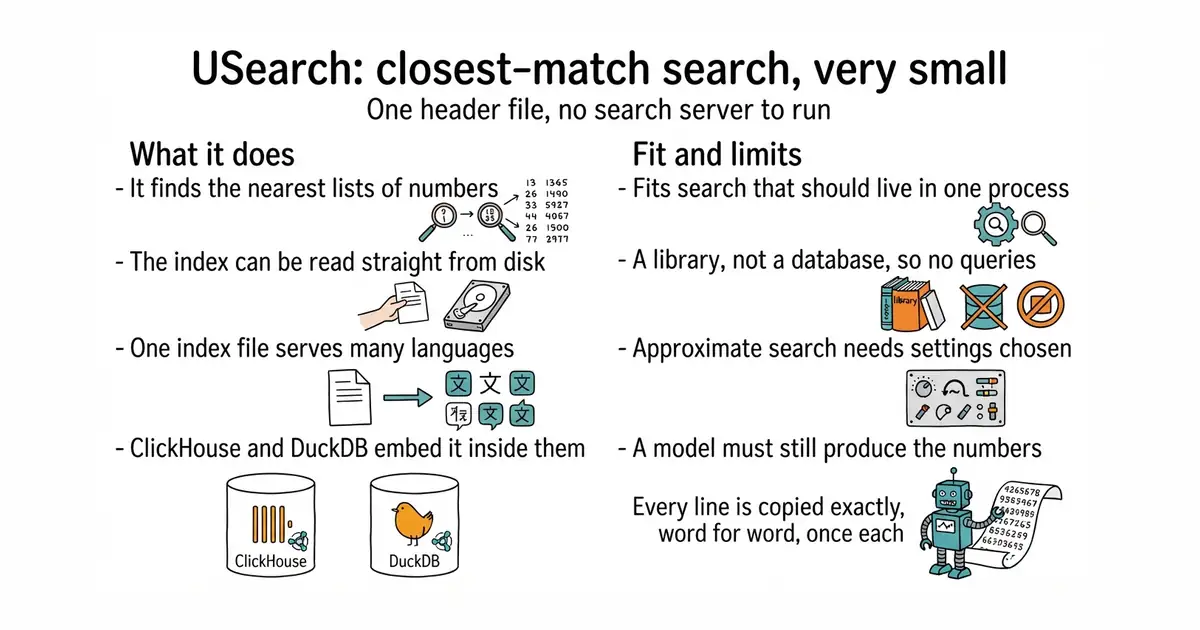

unum-cloud/usearch
A small, fast engine for finding the closest matches among millions of number lists.


benbjohnson/litestream
It copies a SQLite database to cloud storage as it changes, so the data can be restored after a failure.


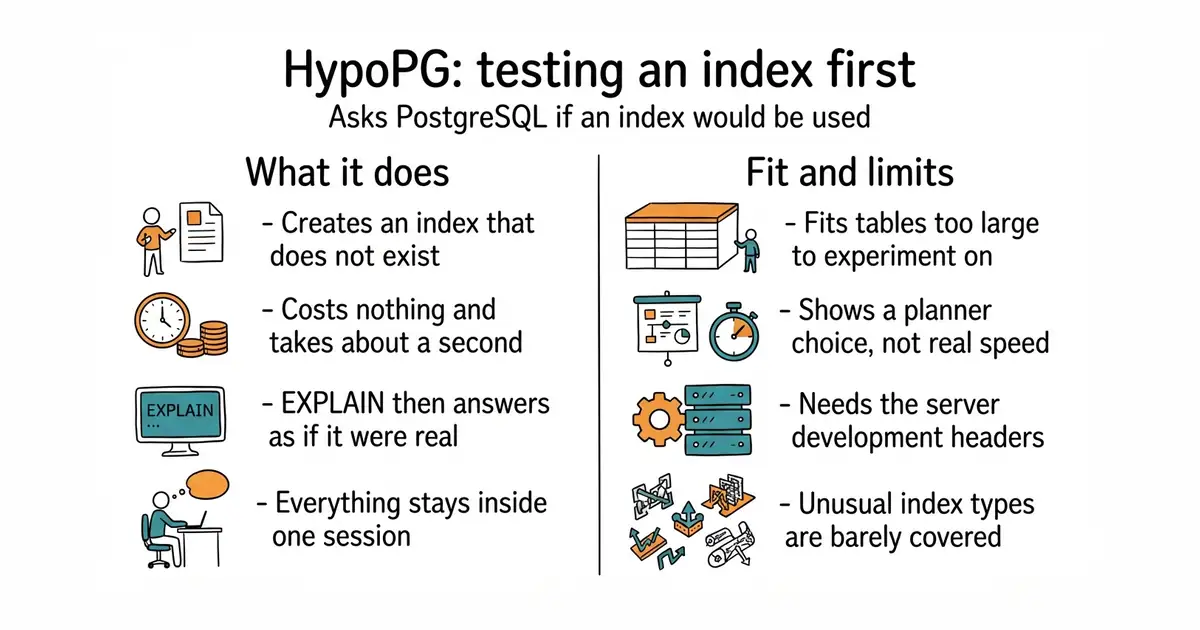
HypoPG/hypopg 💎 hidden gem
It creates a pretend index in one second so PostgreSQL can say whether a real one would help.
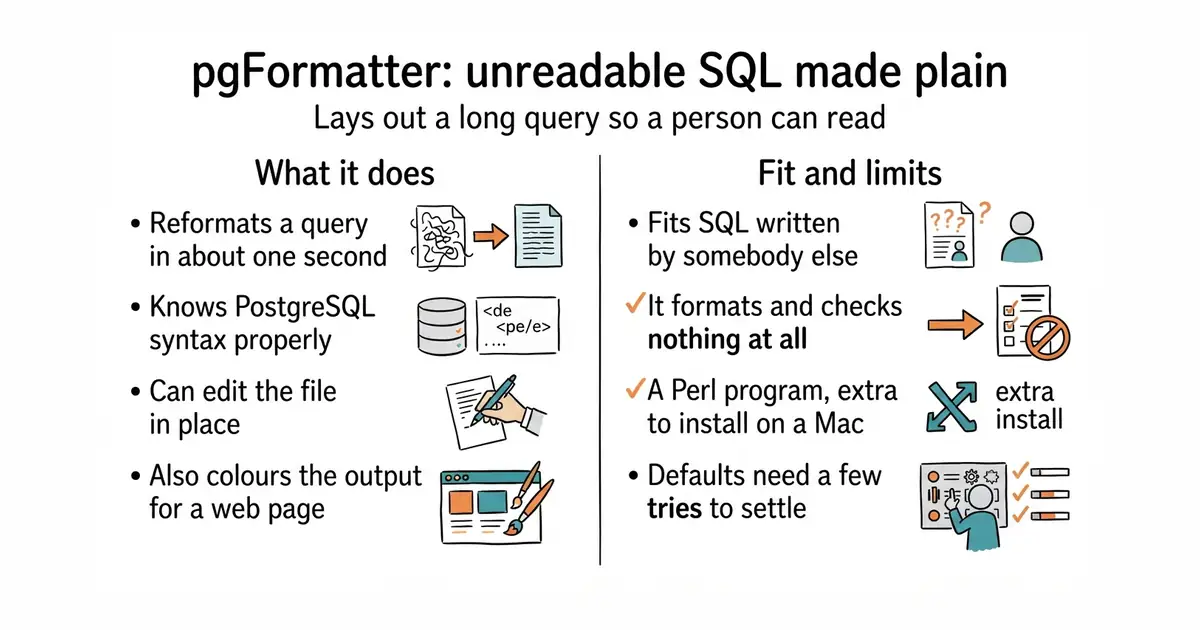

darold/pgFormatter 💎 hidden gem
It lays out an unreadable database query so that a person can read it.
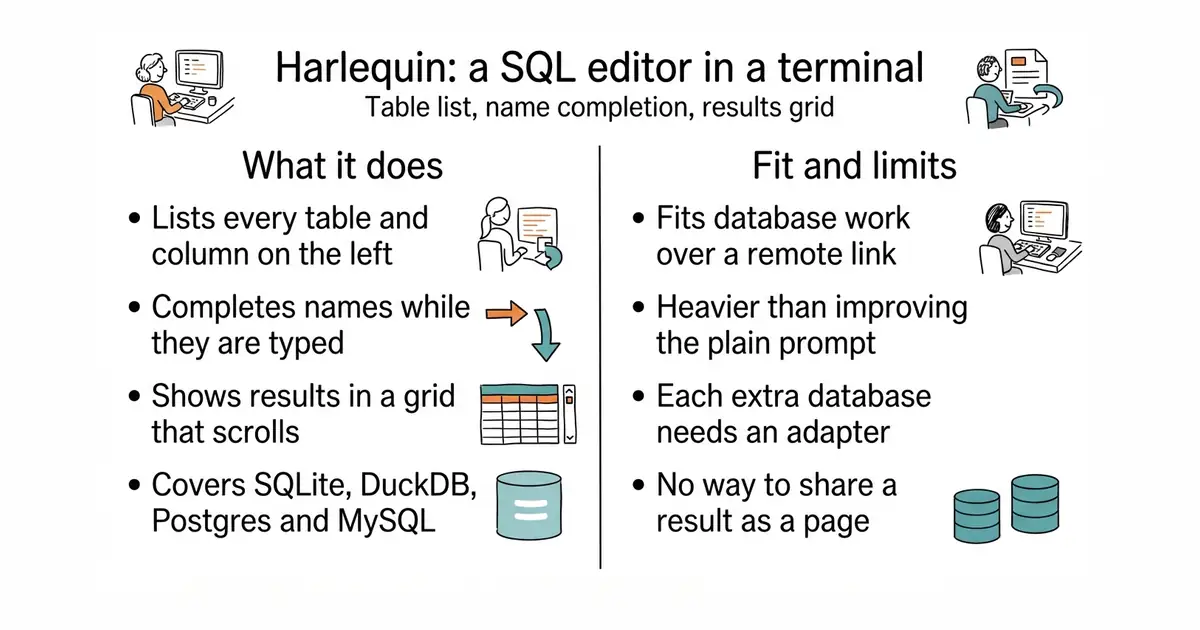

tconbeer/harlequin
A SQL editor that runs inside a terminal window, with a table list and name completion.
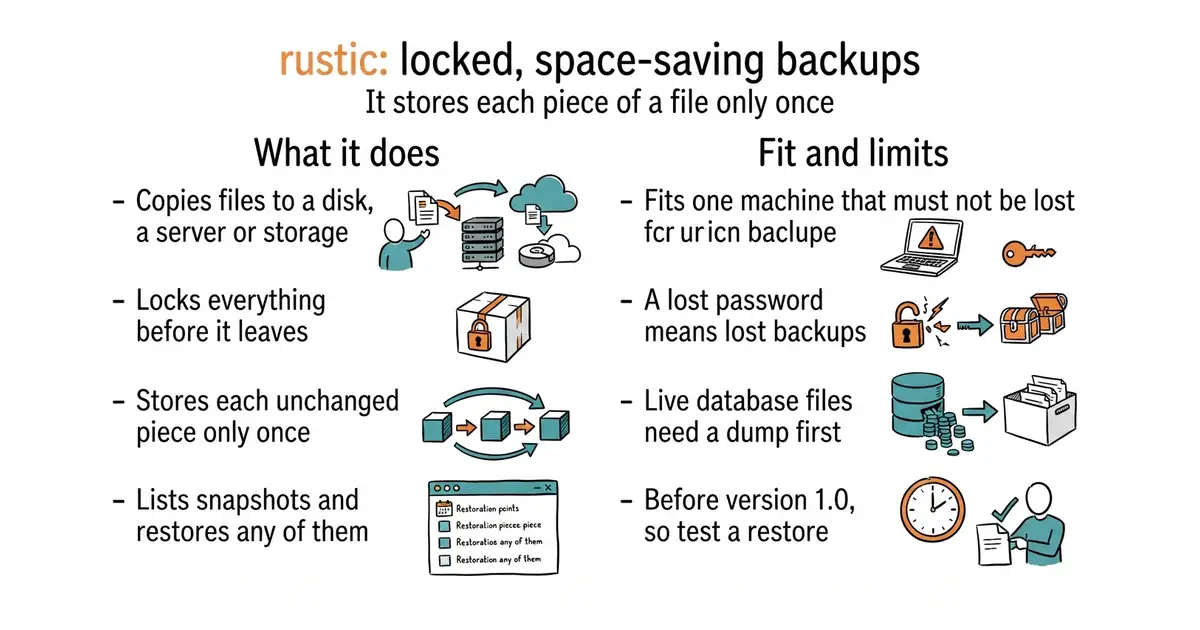



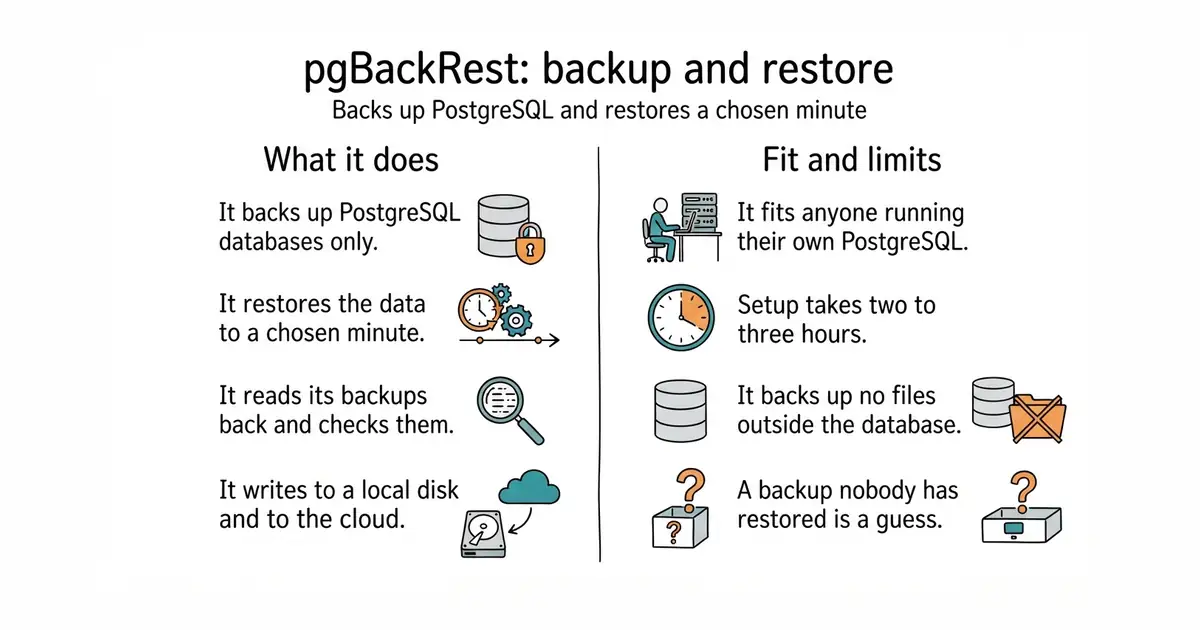

pgbackrest/pgbackrest
Backup and restore for PostgreSQL, including a restore to a chosen minute in the past.


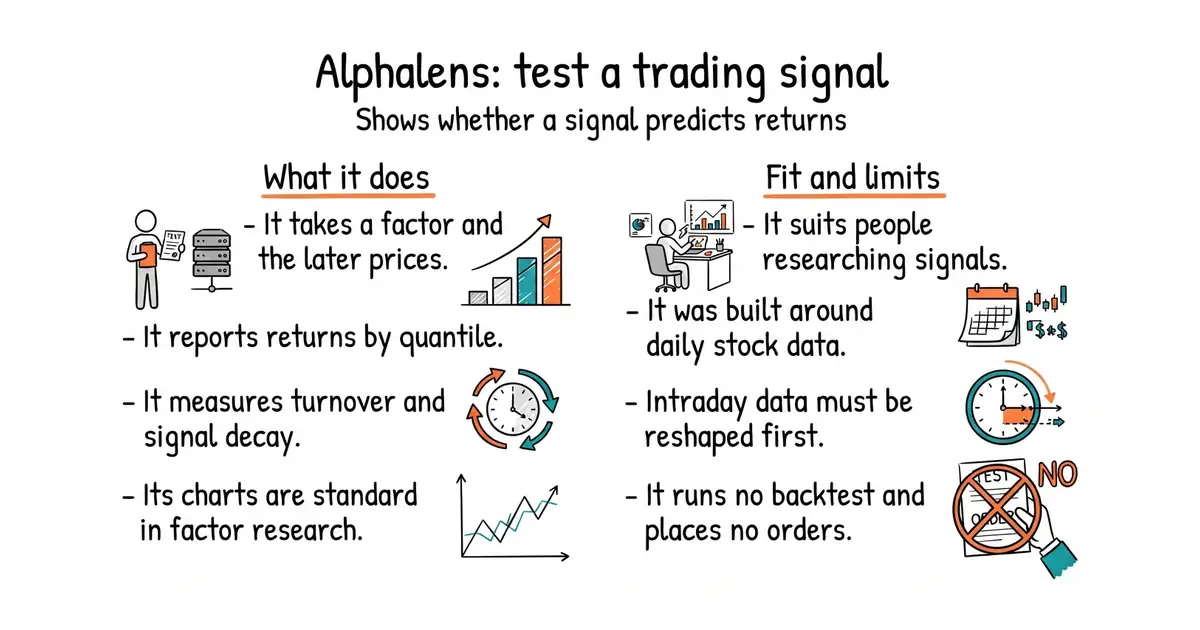

stefan-jansen/alphalens-reloaded 💎 hidden gem
A check on whether a trading signal actually predicts returns, before anything is built on it.



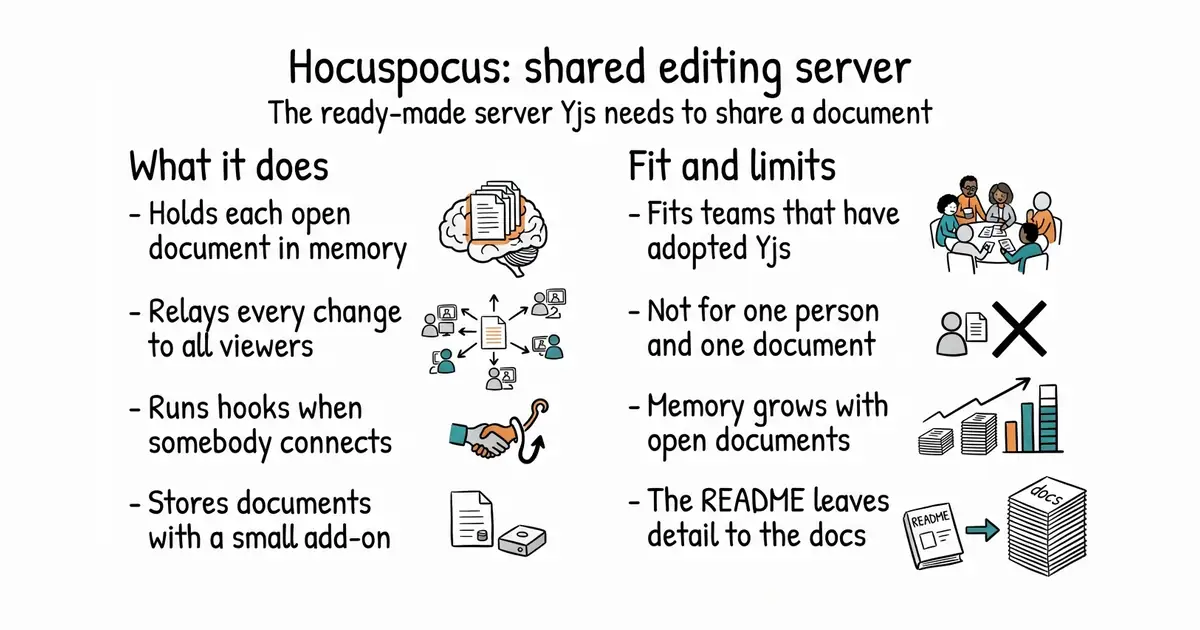

ueberdosis/hocuspocus 💎 hidden gem
The ready-made server Yjs needs to share one document between people.
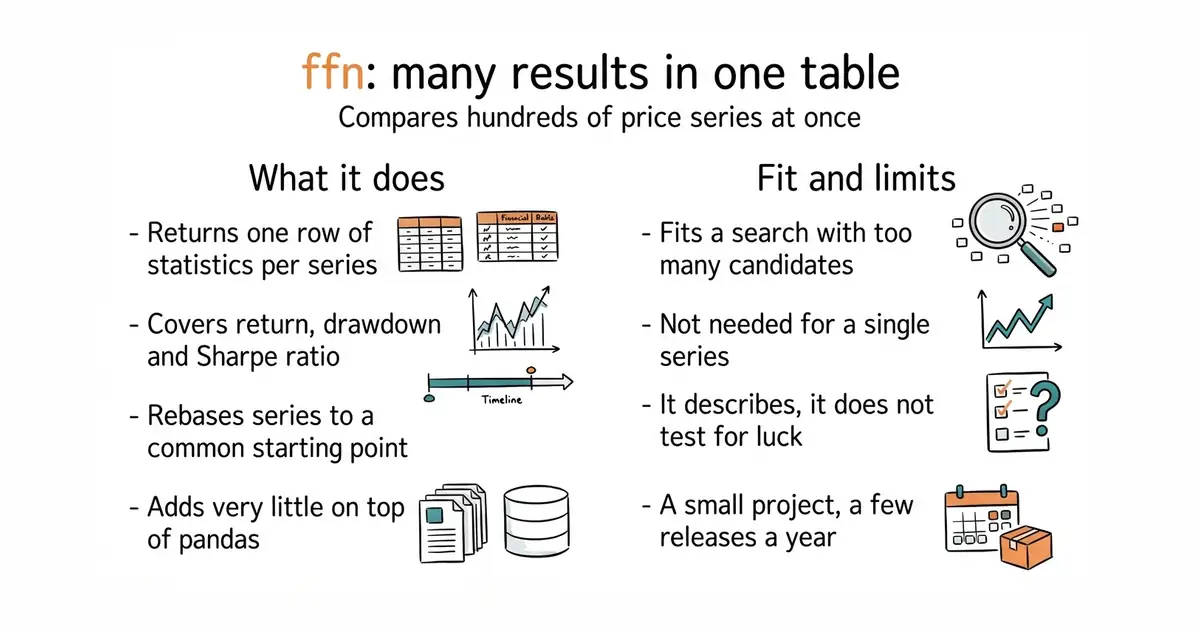

pmorissette/ffn 💎 hidden gem
GroupStats: hand it a DataFrame of many equity curves and get one table of performance statistics for all of them.

unionai-oss/pandera
Schema validation for DataFrames — the error that fires before a backtest quietly reports a fictional edge.
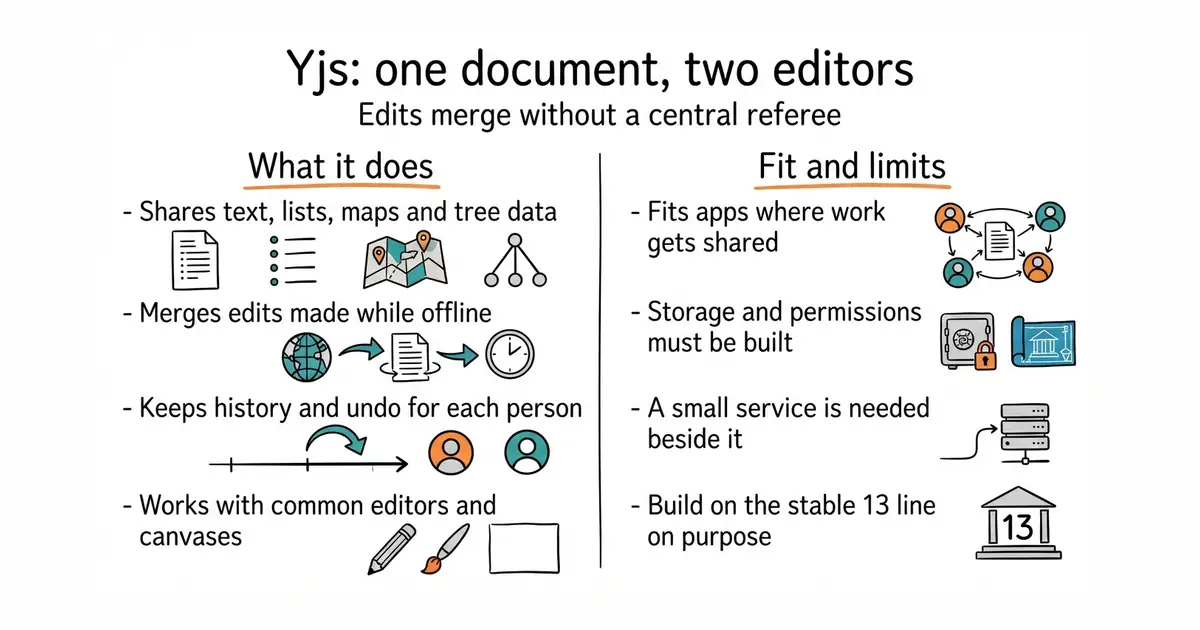

yjs/yjs
The CRDT everyone uses — several people editing one document at once, offline edits merging cleanly later.
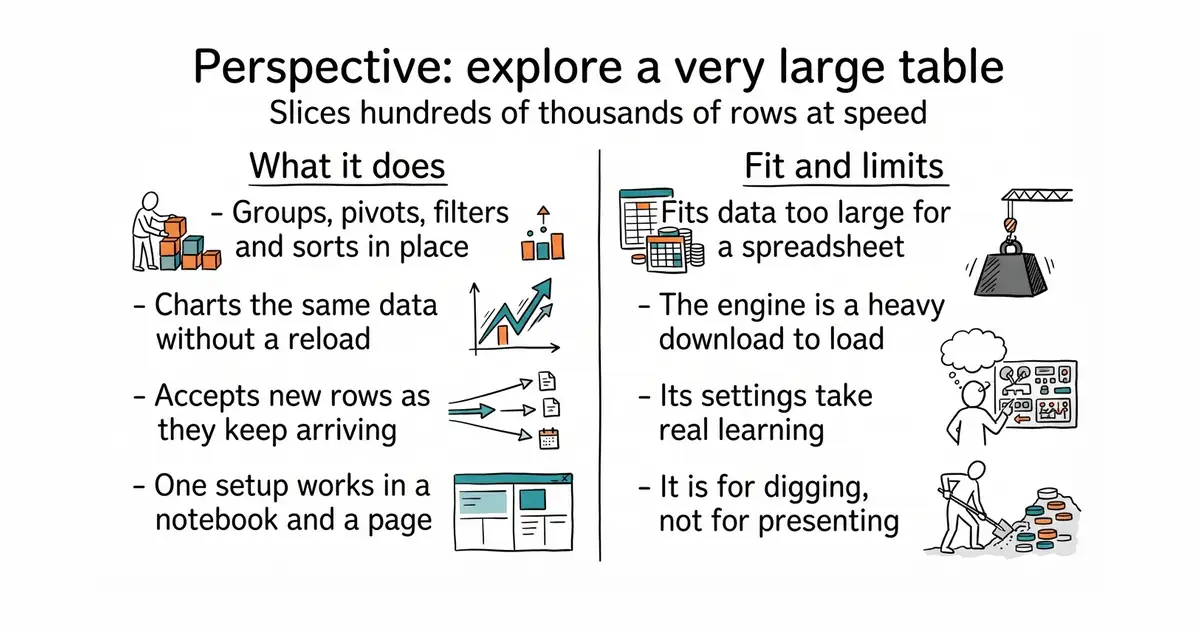

perspective-dev/perspective
A browser component for exploring and charting very large or continuously updating tables.
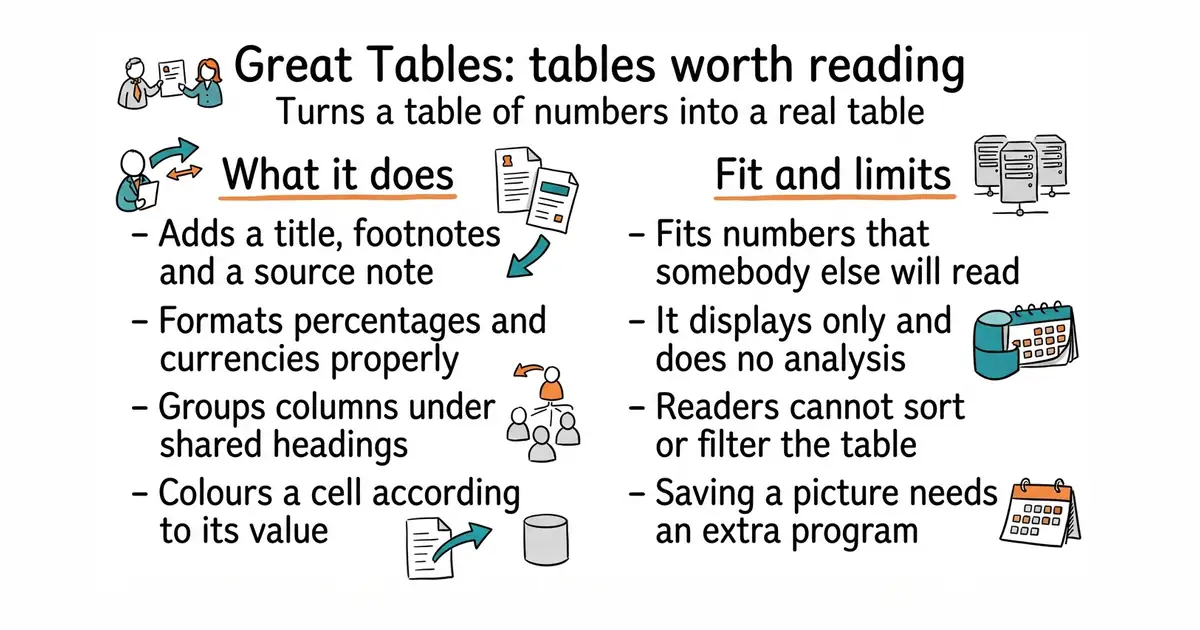

posit-dev/great-tables 💎 hidden gem
Display tables in Python with titles, spanners, footnotes and real number formatting — from a pandas or Polars frame.
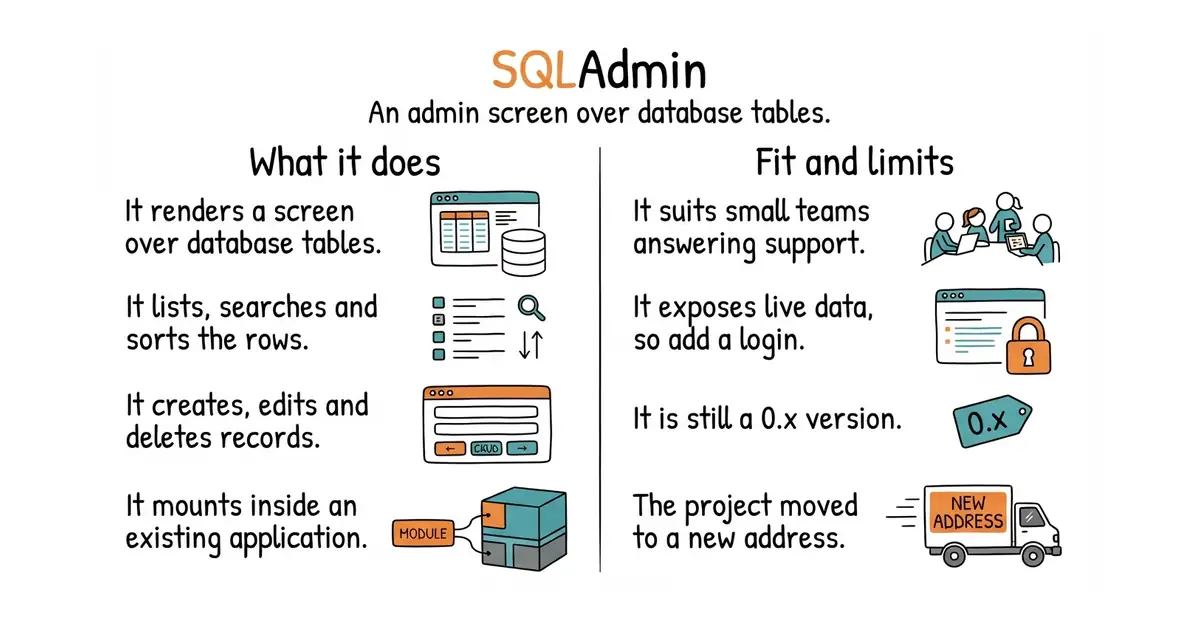

smithyhq/sqladmin 💎 hidden gem
An admin interface over SQLAlchemy tables, mounted inside a FastAPI or Starlette application.

tradingview/lightweight-charts
TradingView's own charting library — the chart a forex trader already knows how to read.
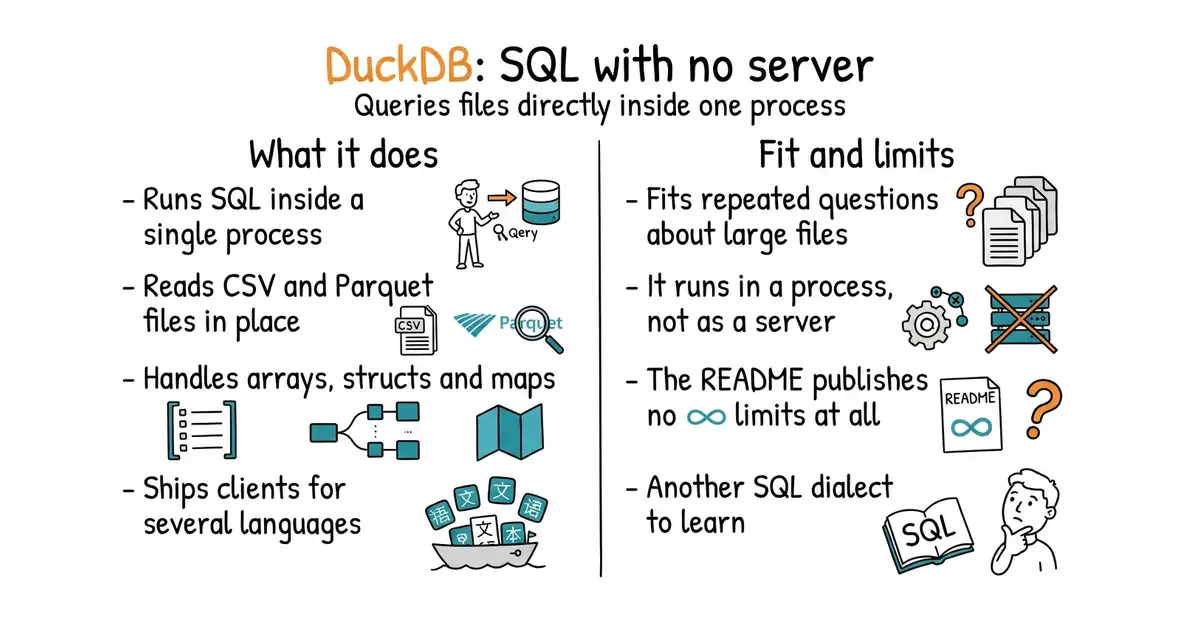

duckdb/duckdb
An analytical SQL database that runs inside your own process and queries files directly.
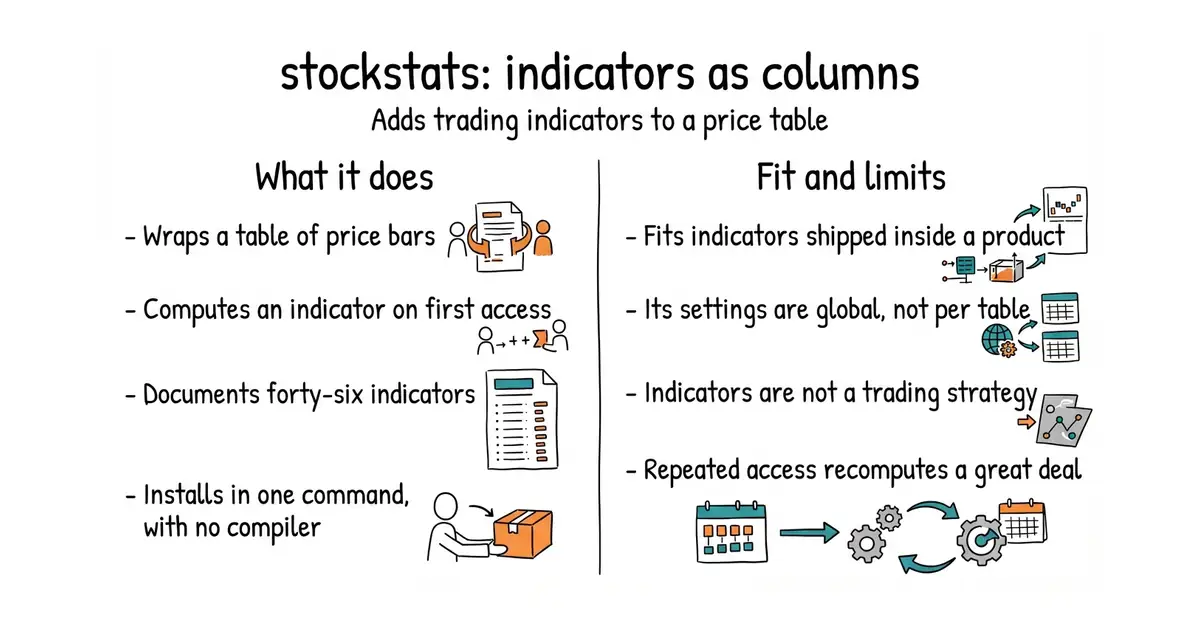

jealous/stockstats 💎 hidden gem
A Python wrapper that turns a table of price bars into one where trading indicators are columns.
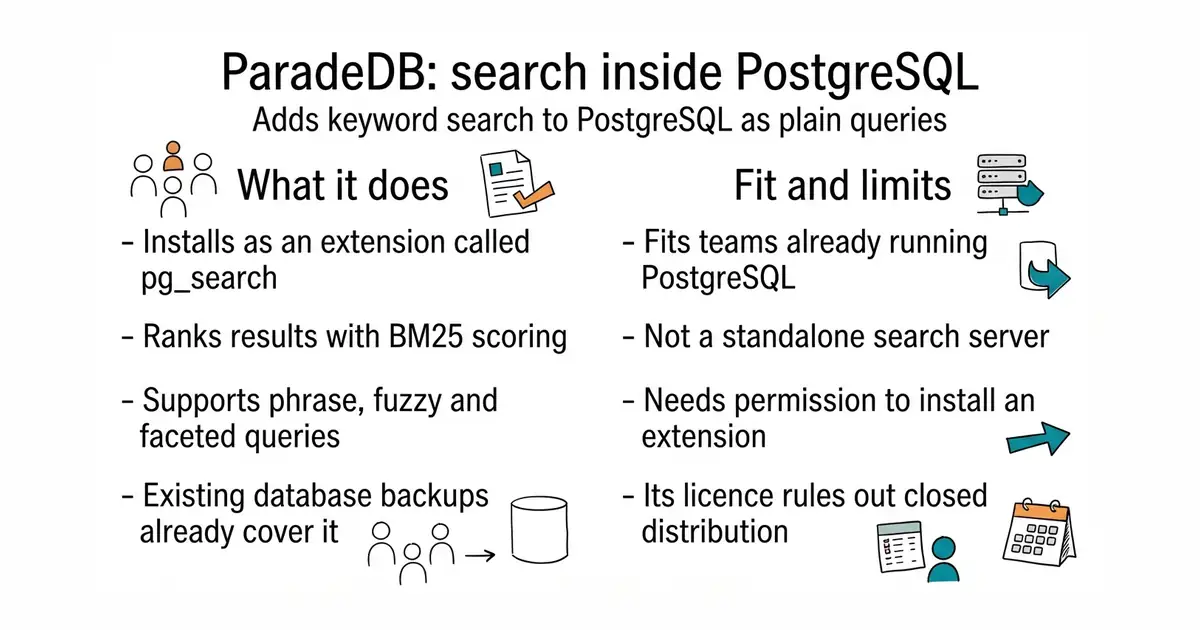

paradedb/paradedb
A PostgreSQL extension that adds search-engine-quality keyword search as ordinary SQL.
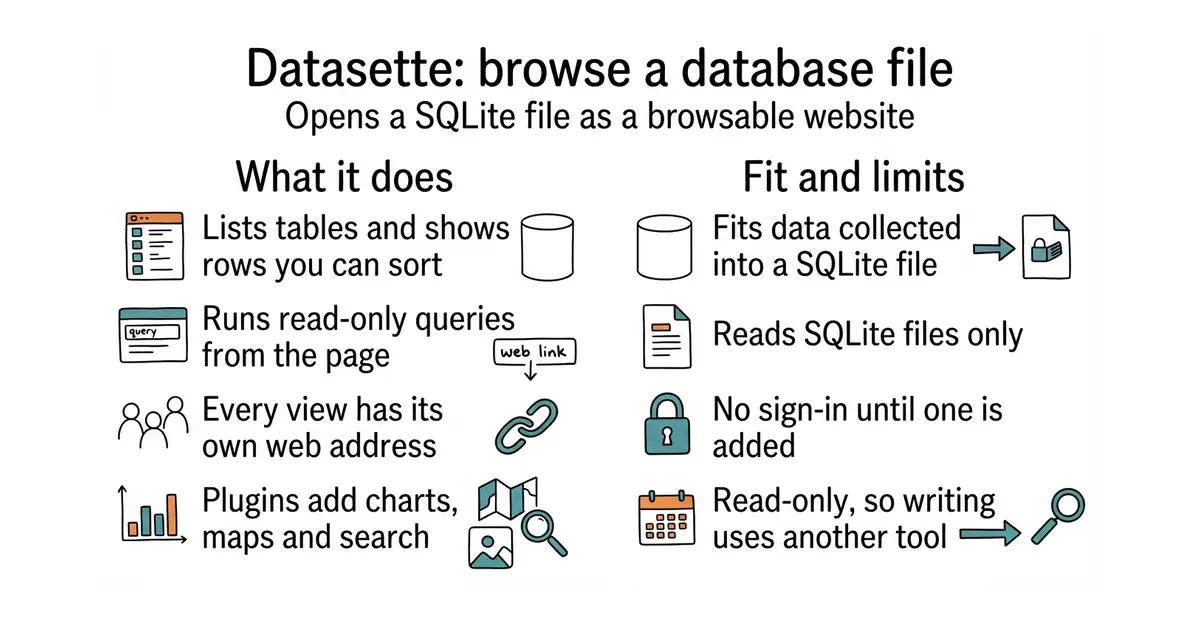

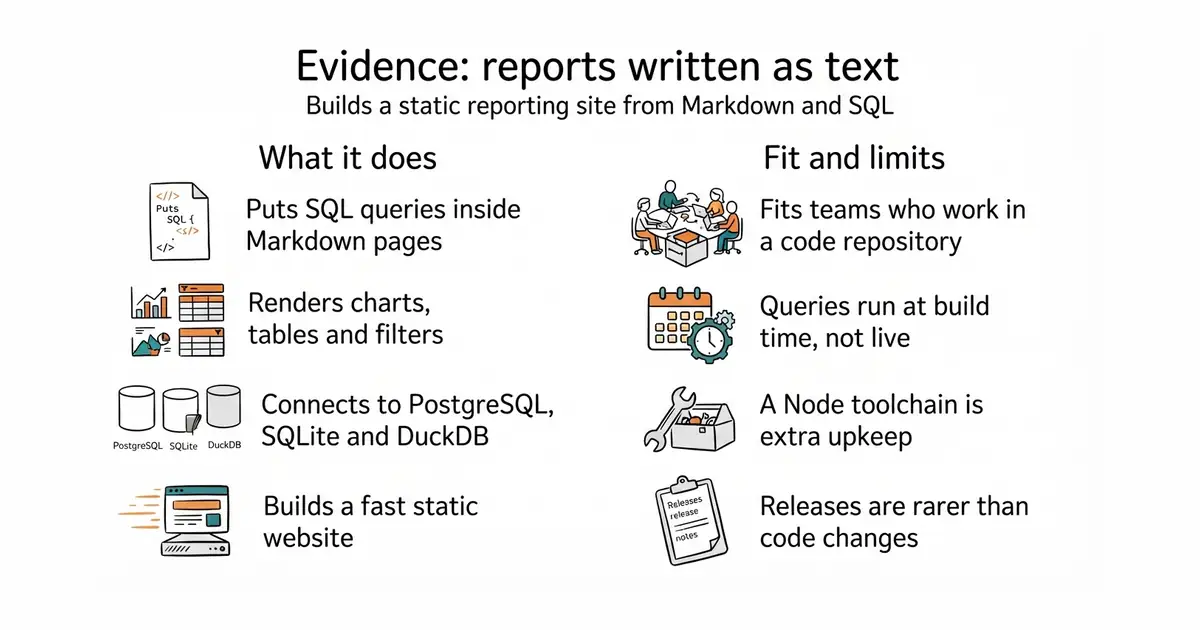

evidence-dev/evidence
A reporting tool where every page is a Markdown file containing SQL queries and chart components.
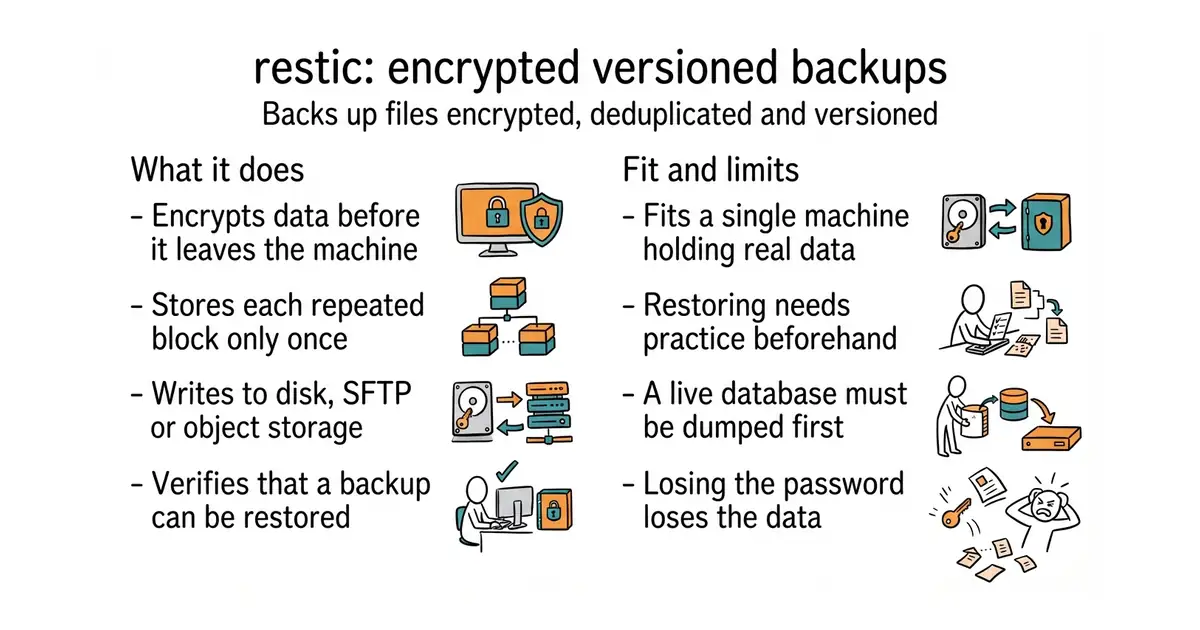

restic/restic
A backup program that makes encrypted, deduplicated, versioned snapshots to local disk, SFTP or object storage.
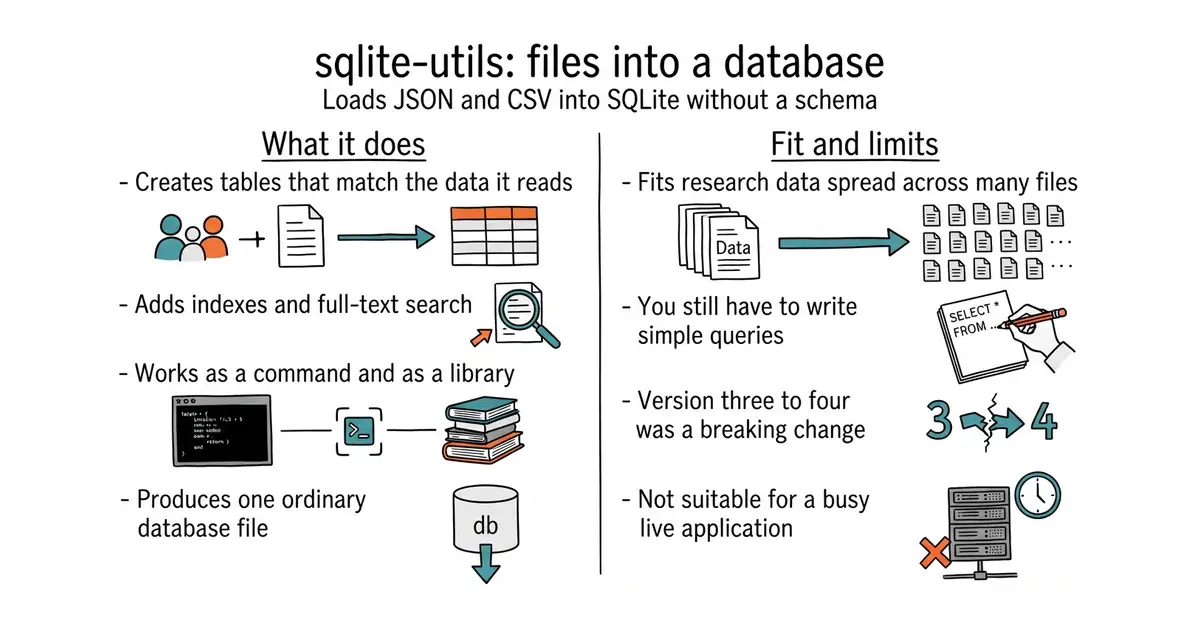

simonw/sqlite-utils 💎 hidden gem
A command-line tool that loads JSON and CSV files into a SQLite database without designing a schema first.
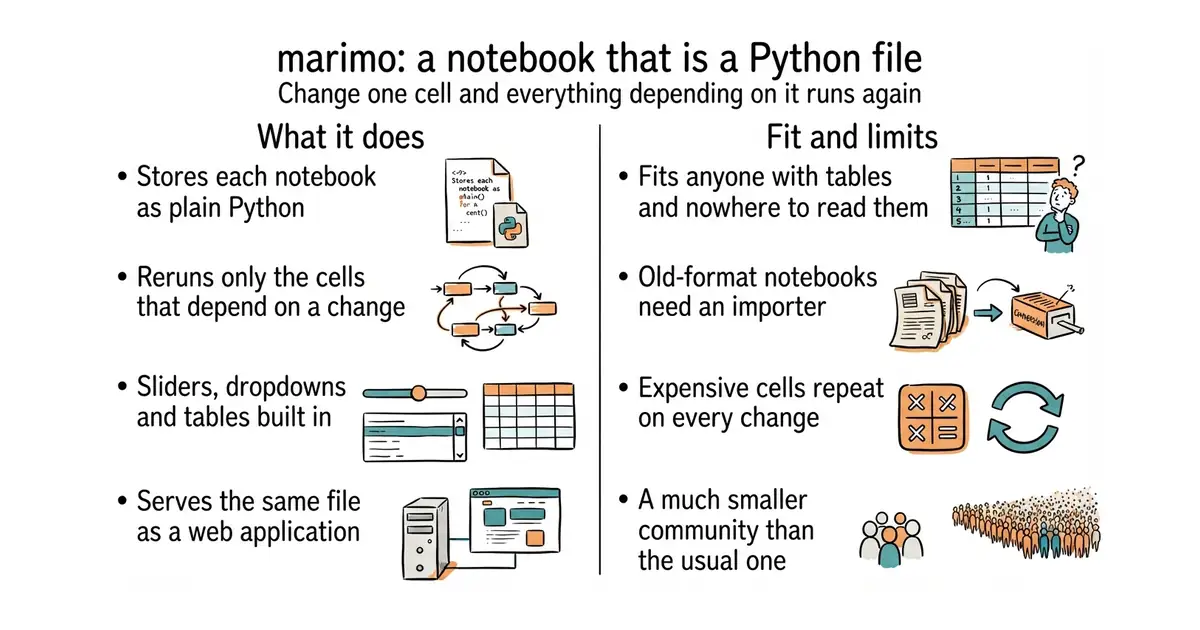

marimo-team/marimo
A Python notebook stored as a plain code file, where changing one cell updates every cell that depends on it.
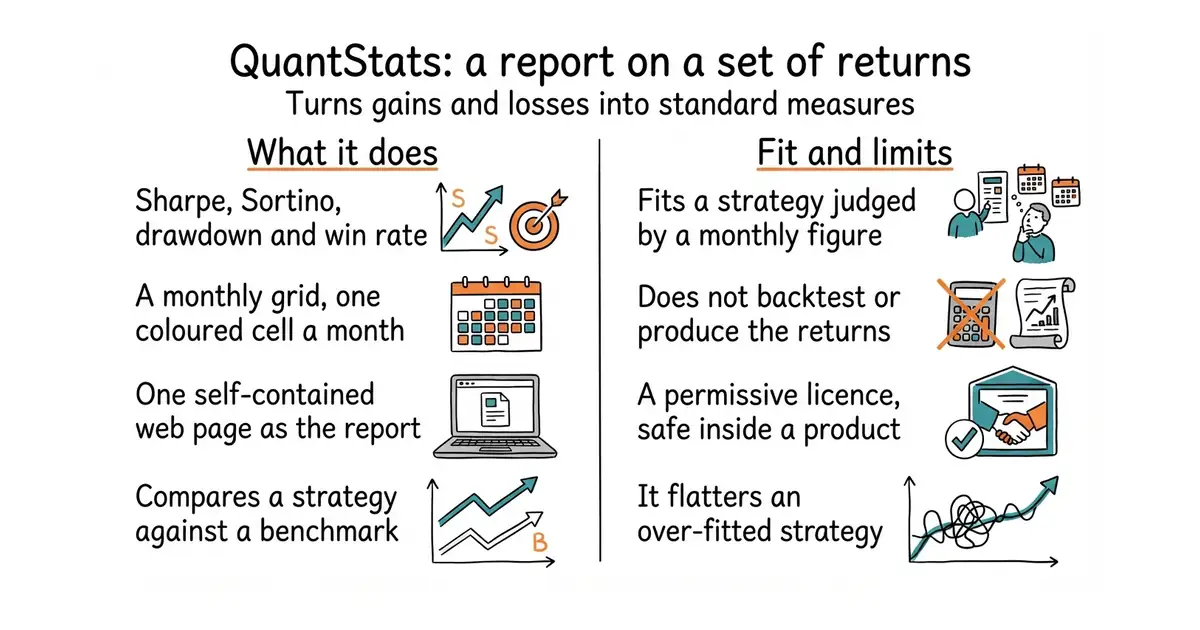

ranaroussi/quantstats
Portfolio tearsheets from a returns series — the monthly-returns heatmap that tests the 2%-a-month claim, under a licence he can ship.
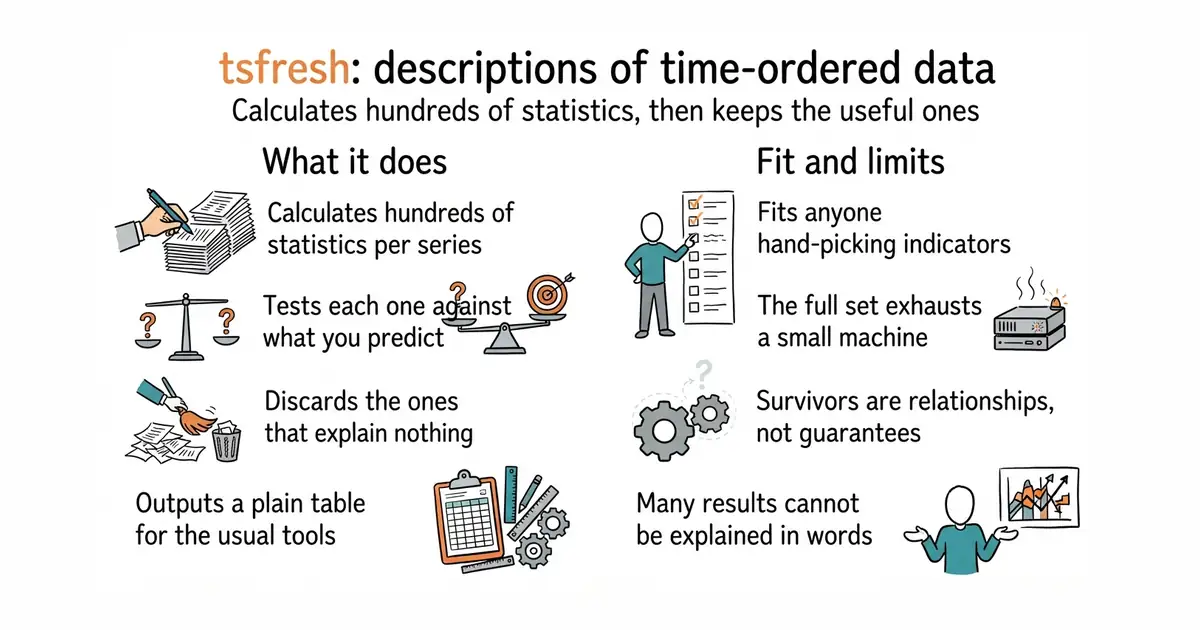

blue-yonder/tsfresh
A Python library that extracts hundreds of statistical descriptions from time-ordered data and keeps only the ones related to your target.

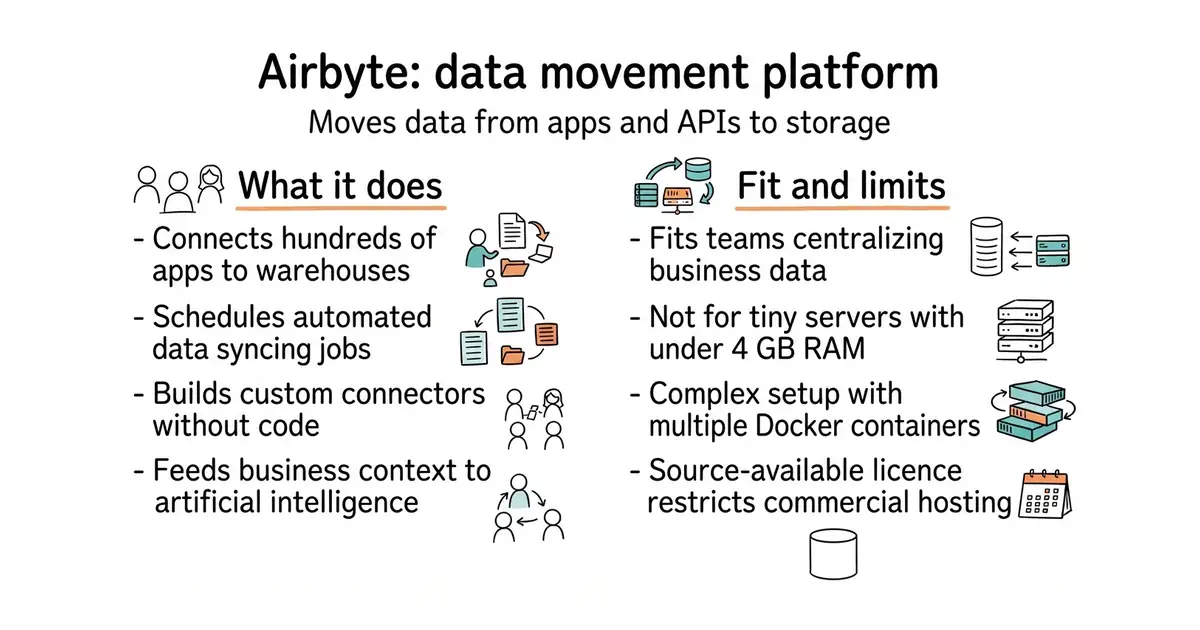

airbytehq/airbyte
Open-source data movement for ELT pipelines and AI agents — from APIs, databases & files to warehouses, lakes, and AI applications. Both self-hosted and Cloud.
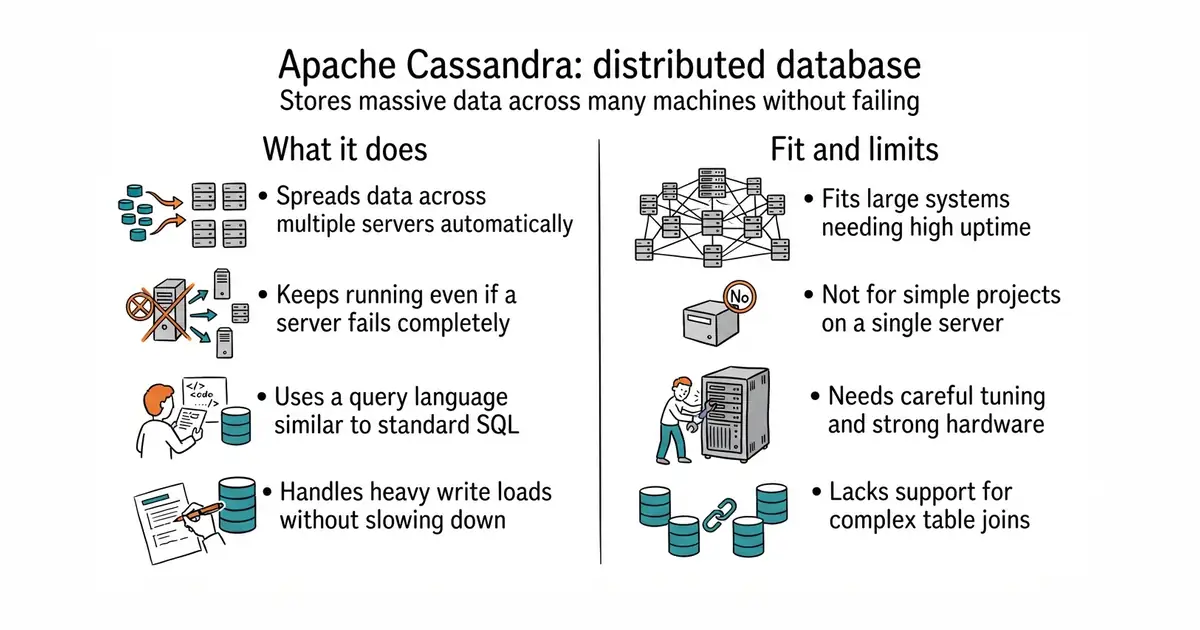

apache/cassandra
Open source transactional distributed database. Linear scalability and proven fault-tolerance on commodity hardware or cloud infrastructure without compromising performance.
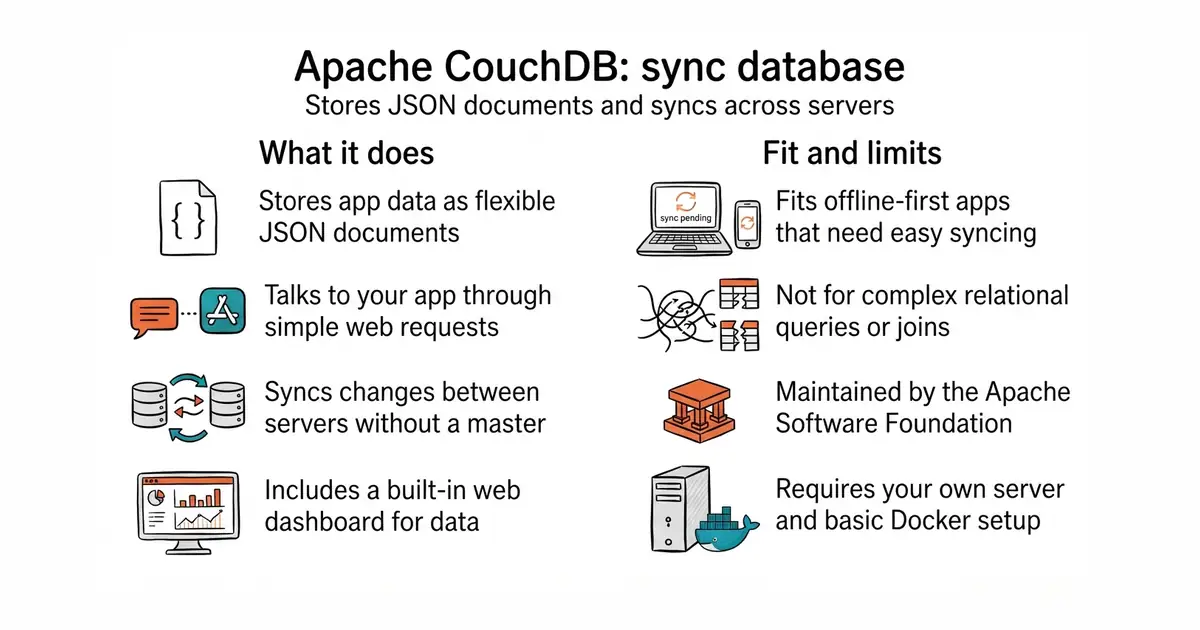

apache/couchdb
Seamless multi-primary syncing database with an intuitive HTTP/JSON API, designed for reliability
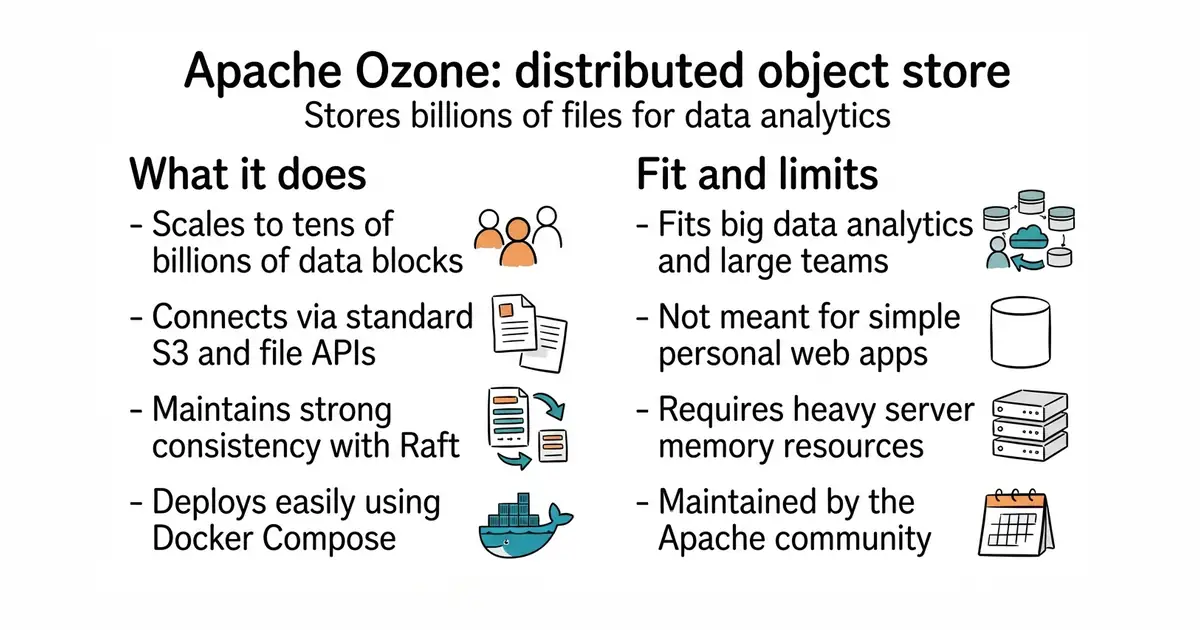

apache/ozone
Scalable, reliable, distributed storage system optimized for data analytics and object store workloads.
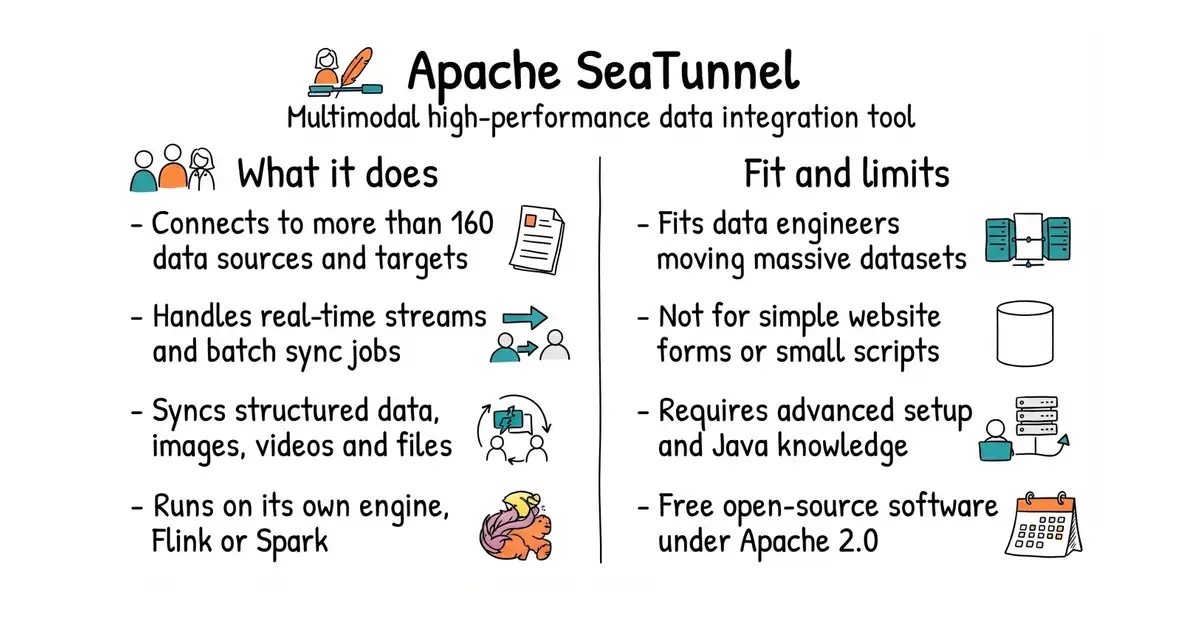

apache/seatunnel
SeaTunnel is a multimodal, high-performance, distributed, massive data integration tool.

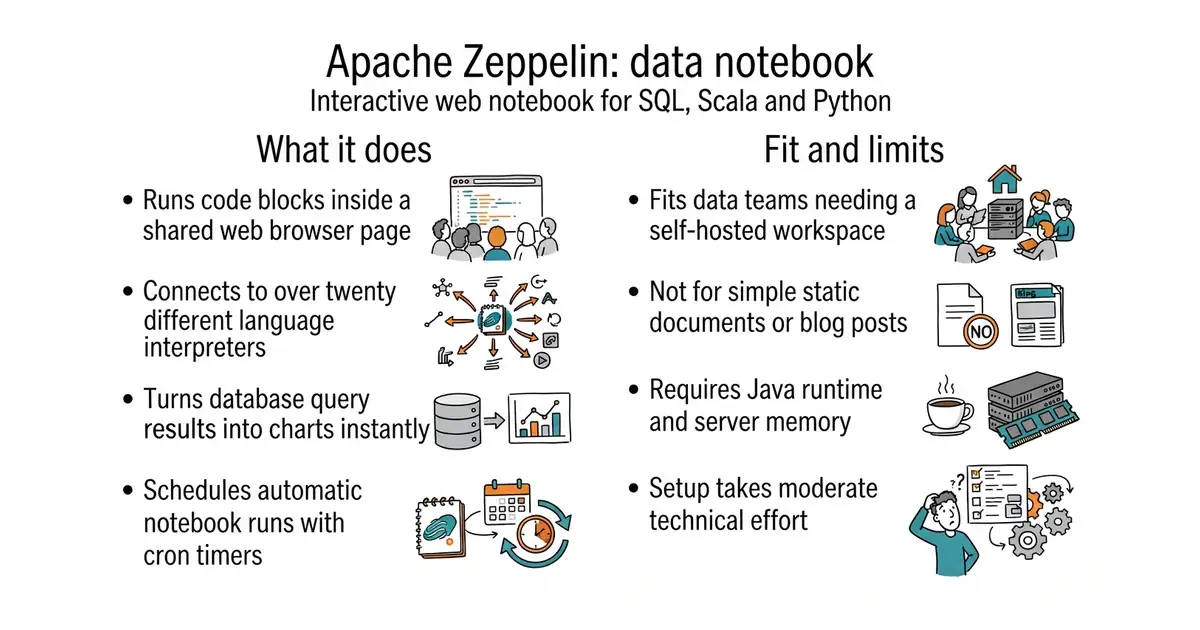

apache/zeppelin
Web-based notebook that enables data-driven, interactive data analytics and collaborative documents with SQL, Scala and more.

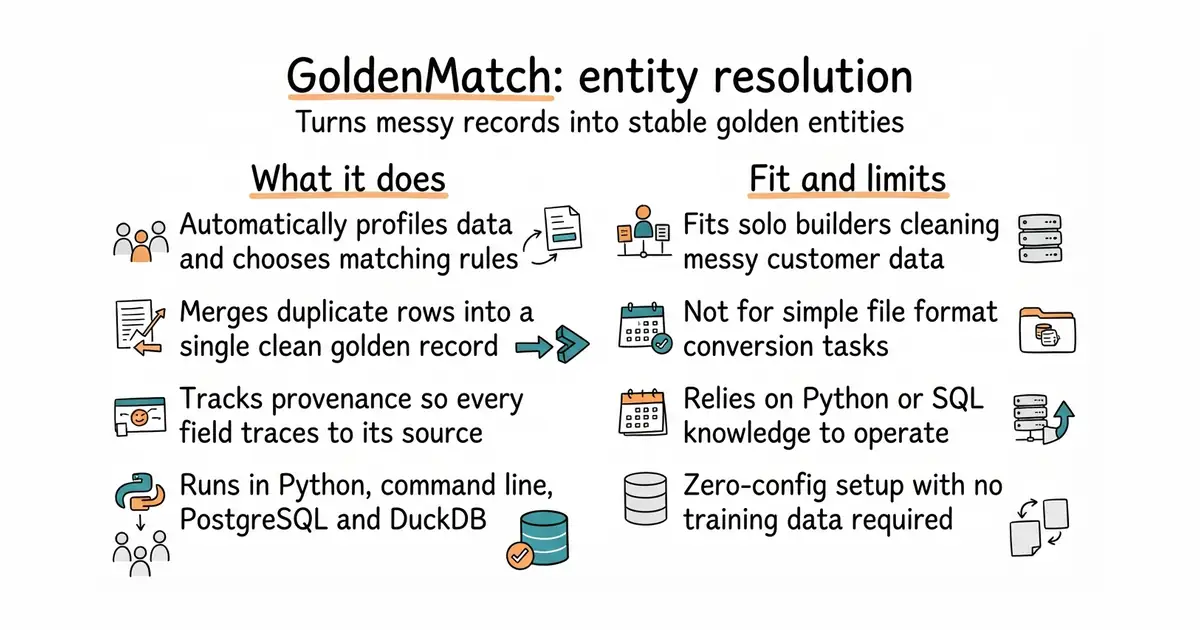

benseverndev-oss/goldenmatch
Zero-config entity resolution feeding a durable identity layer: messy records from any source become stable golden entities, a Customer 360 with provenance, merge/split and audit. Fellegi-Sunter beats hand-tuned Splink. Arrow-native/Rust, 250M rows in 11.2 min. Python + edge TypeScript (WASM), SQL-native in Postgres & DuckDB, 97 MCP tools + REST.

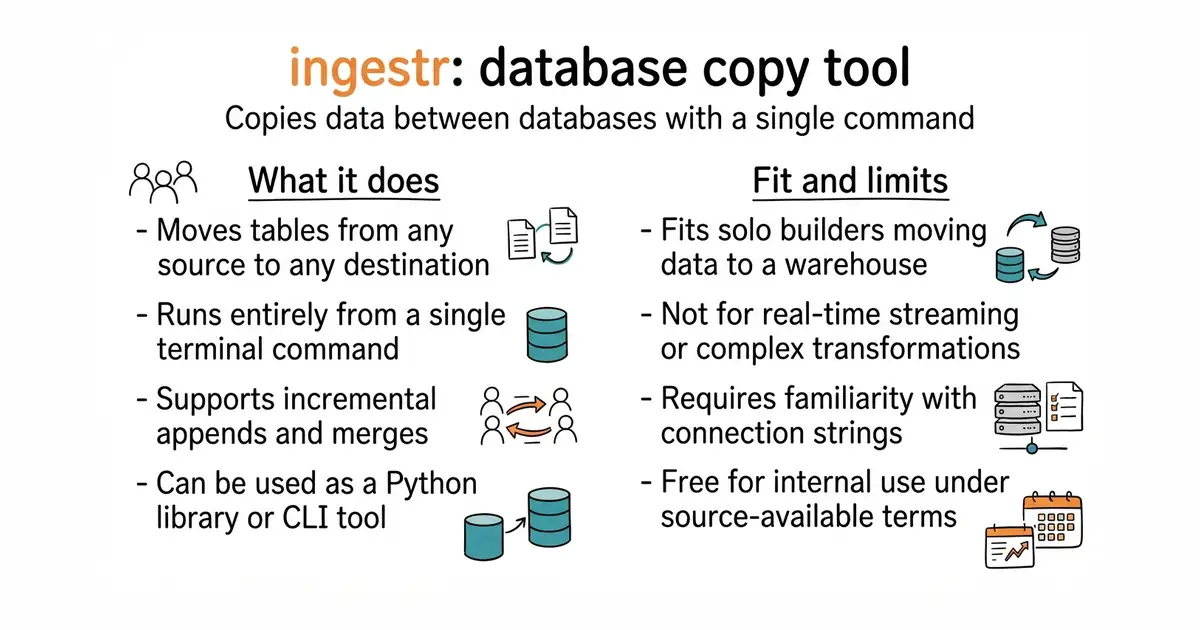

bruin-data/ingestr
ingestr is a CLI tool to copy data between any databases with a single command seamlessly.

Canner/WrenAI
GenBI (Generative BI) for AI agents, an open-source, governed text-to-SQL through an open context layer that turns natural-language questions into trusted dashboards, charts, and SQL across 20+ data sources, such as BigQuery, Snowflake, PostgreSQL, ClickHouse, Amazon Redshift, Databricks and more.


cloudquery/cloudquery
Data pipelines for cloud config and security data. Build cloud asset inventory, CSPM, FinOps, and vulnerability management solutions. Extract from AWS, Azure, GCP, and 70+ cloud and SaaS sources.

cloudreve/cloudreve
🌩 Self-hosted file management and sharing system, supports multiple storage providers
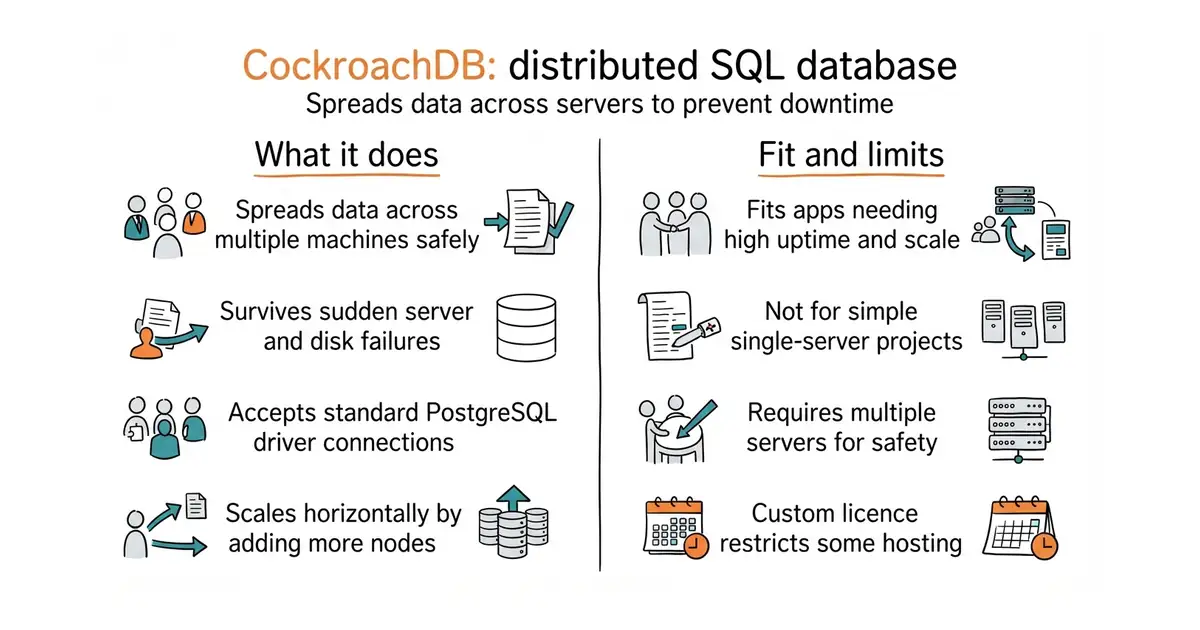

cockroachdb/cockroach
CockroachDB — the cloud native, distributed SQL database designed for high availability, effortless scale, and control over data placement.




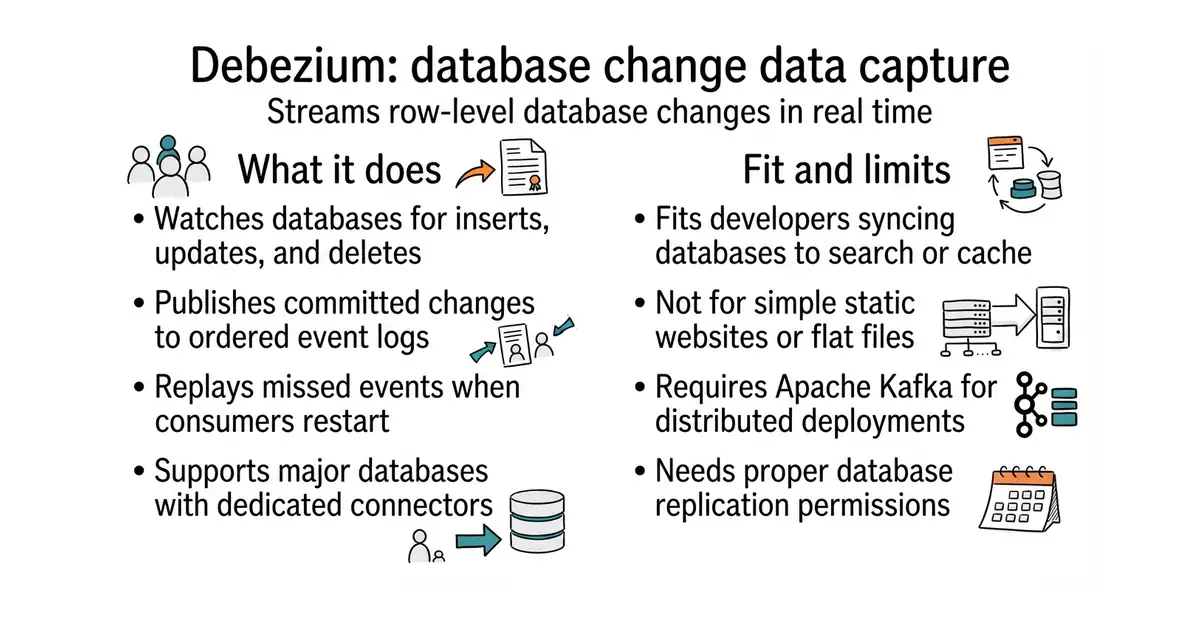

debezium/debezium
Change data capture for a variety of databases. Please log issues at https://github.com/debezium/dbz/issues.

dedupeio/dedupe
:id: A python library for accurate and scalable fuzzy matching, record deduplication and entity-resolution.
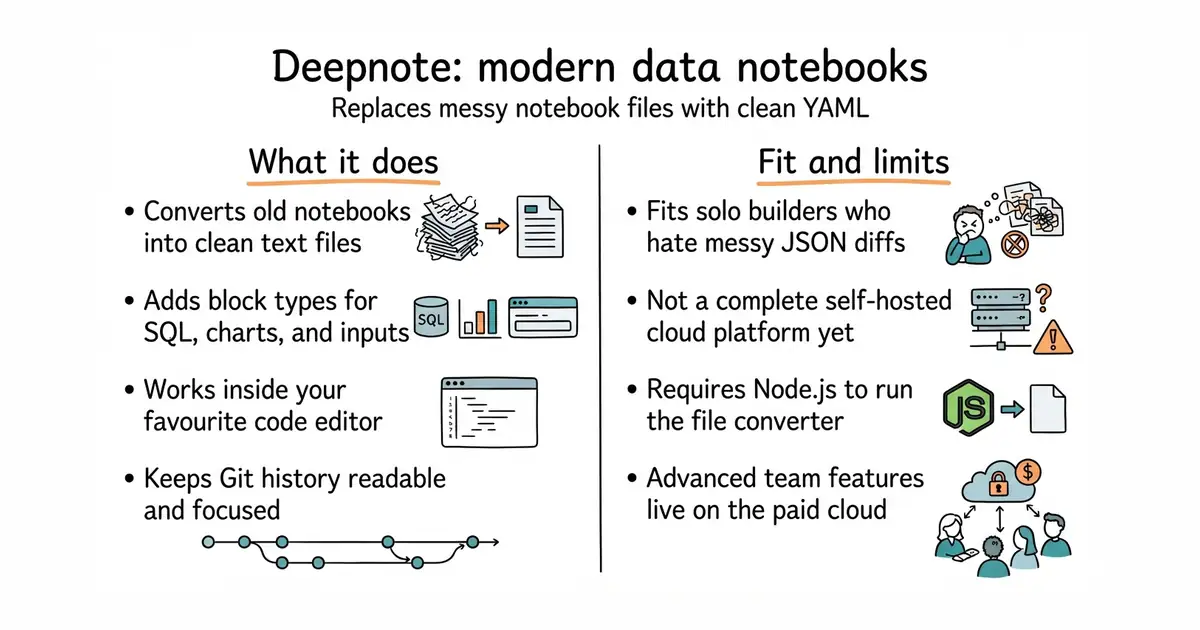

deepnote/deepnote
Deepnote is a drop-in replacement for Jupyter with an AI-first design, sleek UI, new blocks, and native data integrations. Use Python, R, and SQL locally in your favorite IDE, then scale to Deepnote cloud for real-time collaboration, Deepnote agent, and deployable data apps. https://deepnote.com/
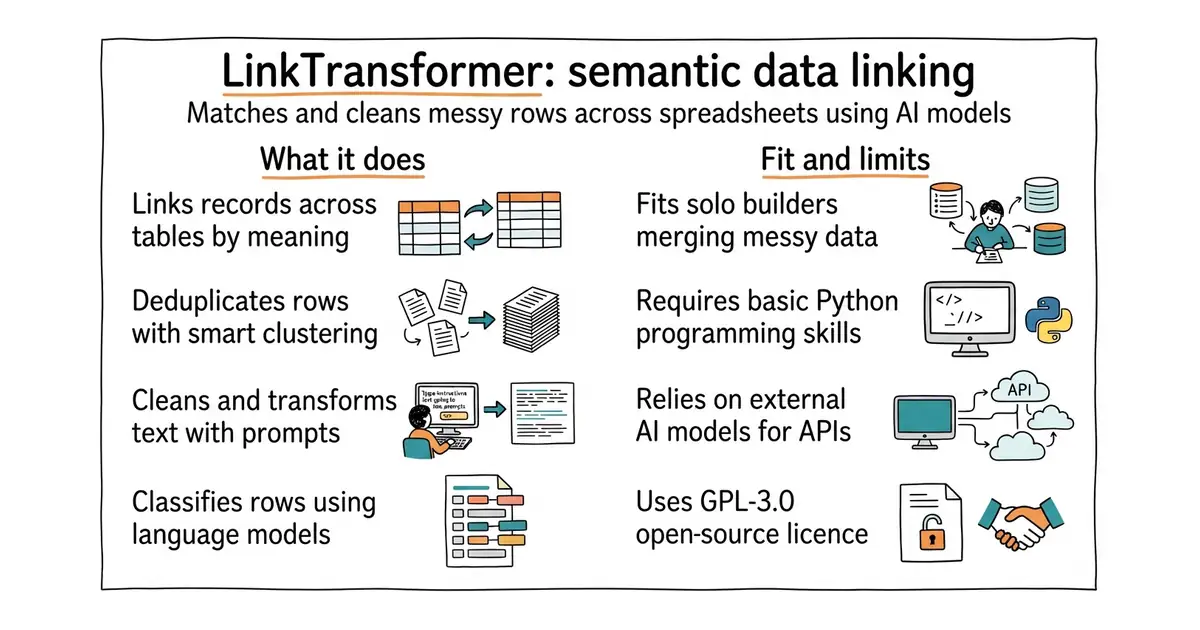
dell-research-harvard/linktransformer
A convenient way to link, deduplicate, aggregate and cluster data(frames) in Python using deep learning
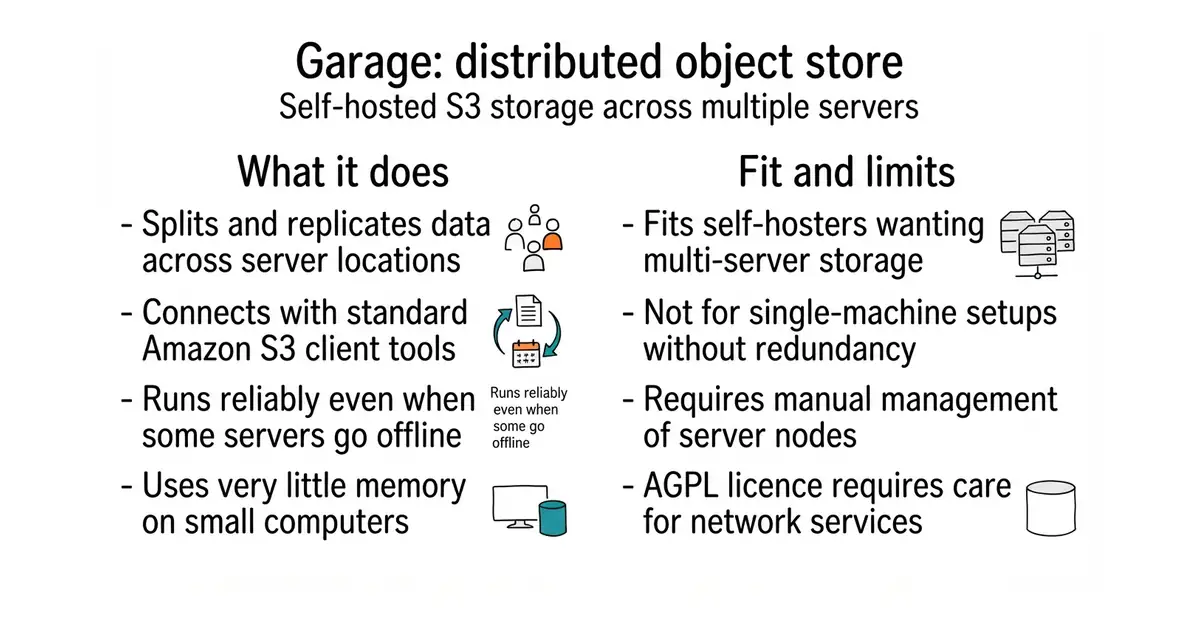

deuxfleurs-org/garage
(Mirror) S3-compatible object store for small self-hosted geo-distributed deployments. Main repo: https://git.deuxfleurs.fr/Deuxfleurs/garage
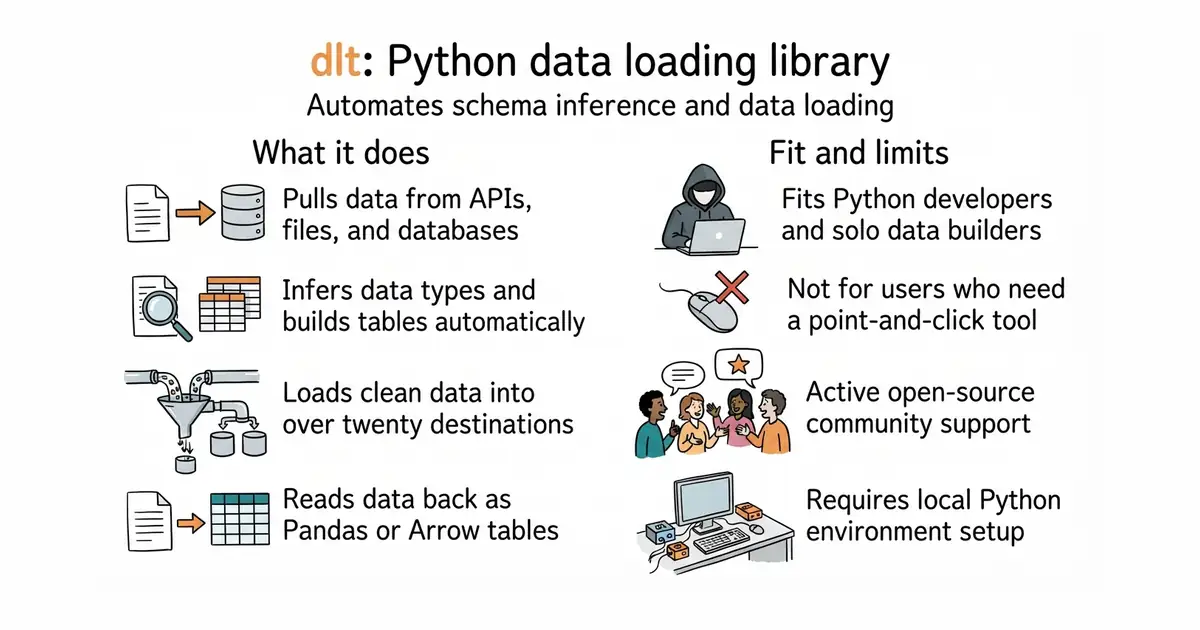

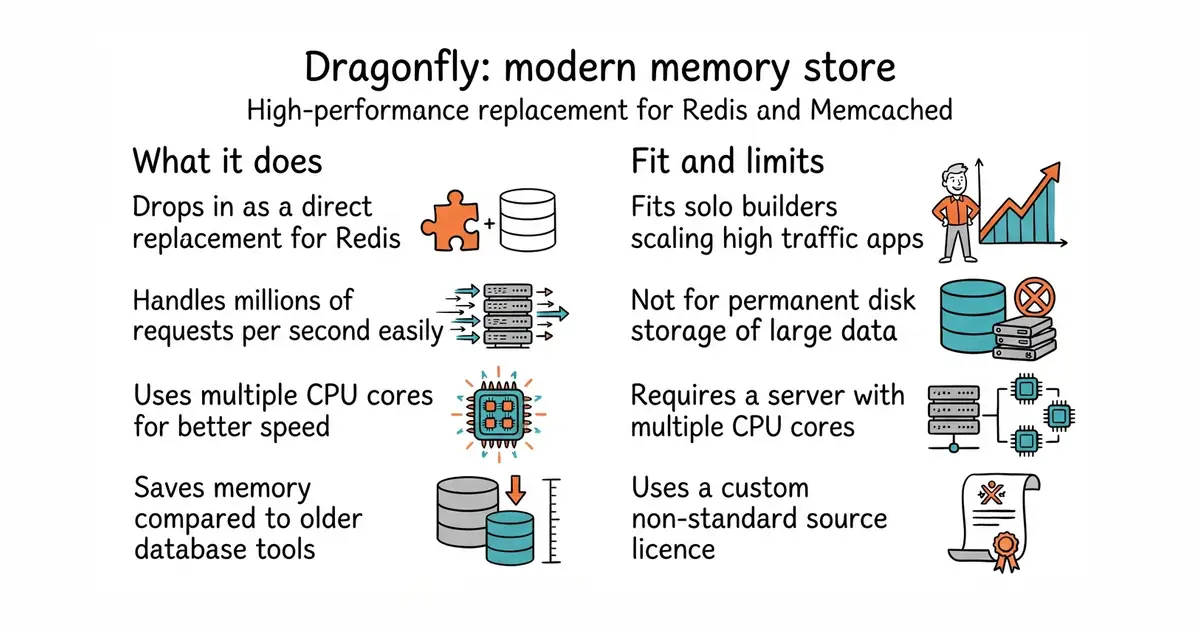

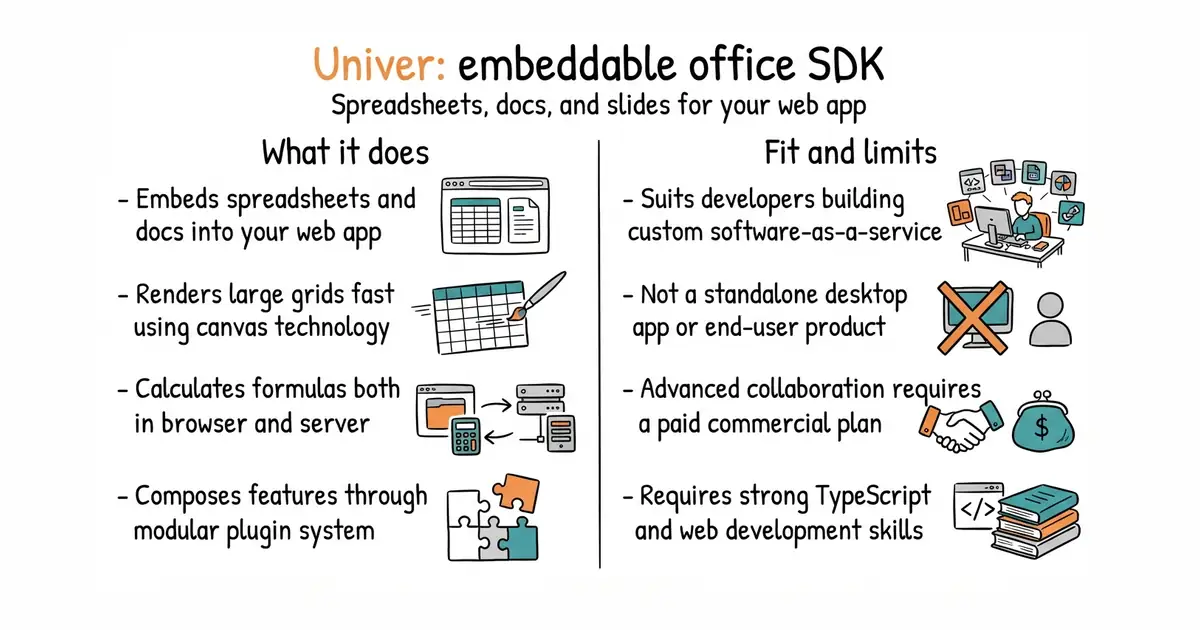

dream-num/univer
The Office Harness for AI Agents — Spreadsheets, Docs, Slides, Canvas, Relational Tables, and PDF in one runtime.


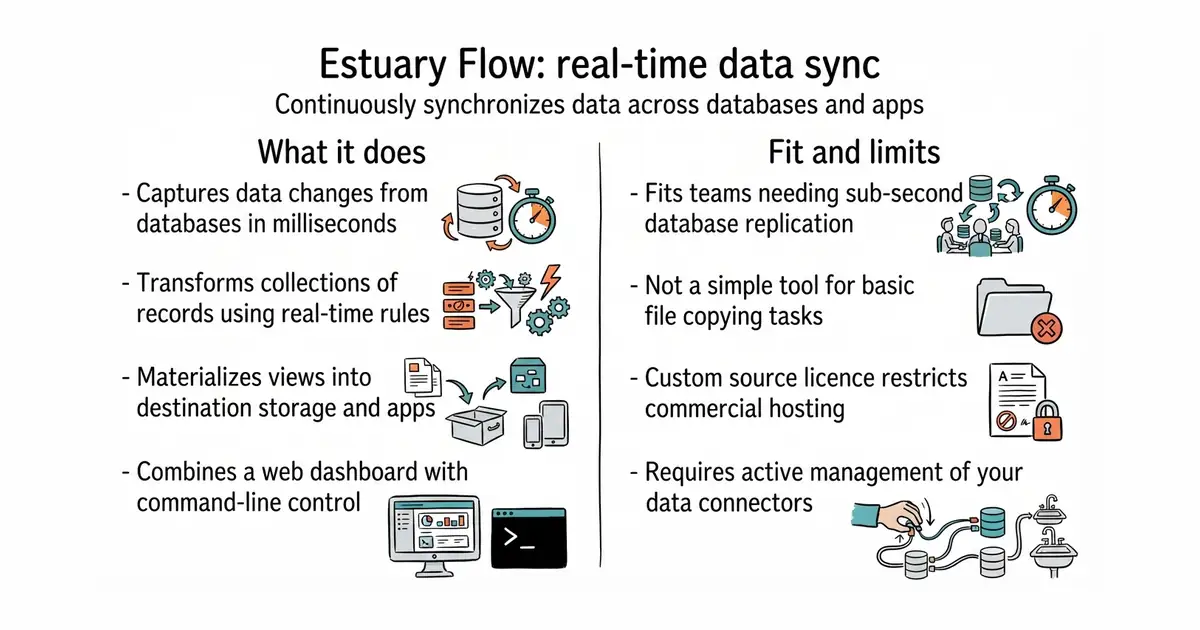

estuary/flow
🌊 Continuously synchronize the systems where your data lives, to the systems where you _want_ it to live, by managing your data flows with Estuary. 🌊

explorerhq/sql-explorer
SQL reporting that Just Works. Fast, simple, and confusion-free. Write and share queries in a delightful SQL editor, with AI assistance.

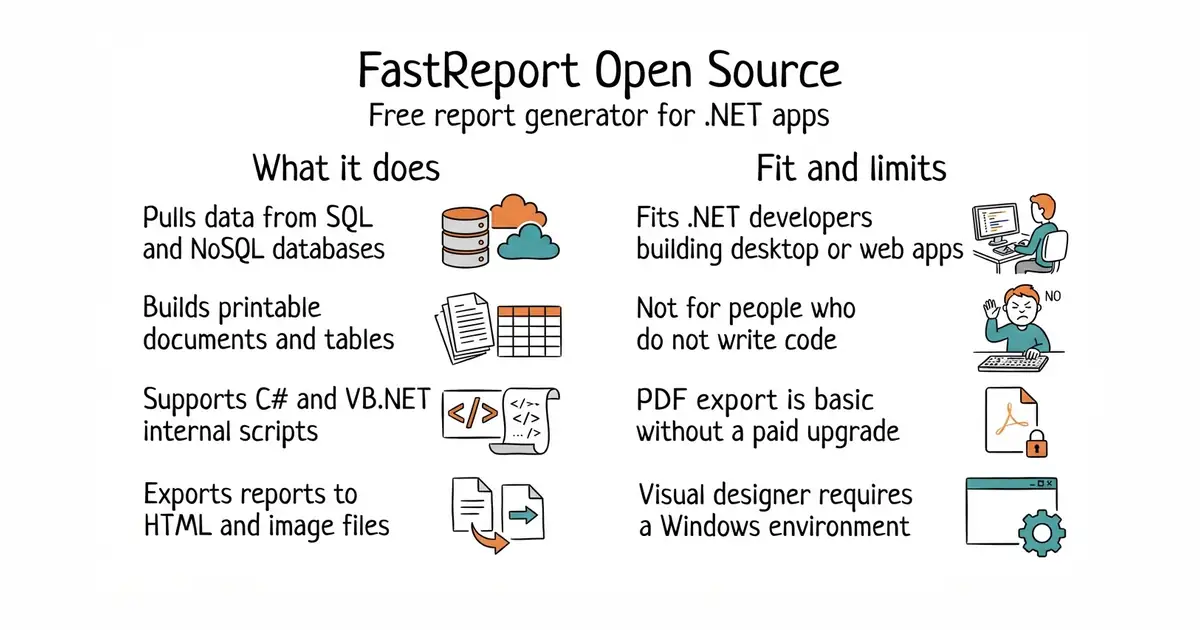

FastReports/FastReport
Free Open Source Reporting tool for .NET6/.NET Core/.NET Framework that helps your application generate document-like reports


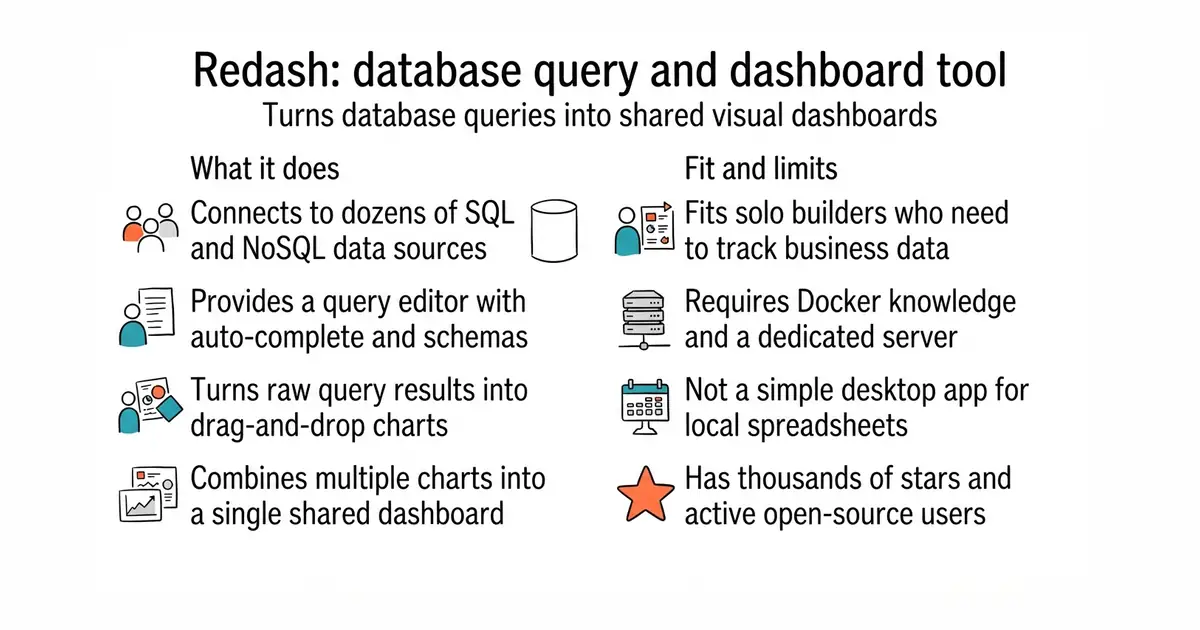
getredash/redash
Make Your Company Data Driven. Connect to any data source, easily visualize, dashboard and share your data.
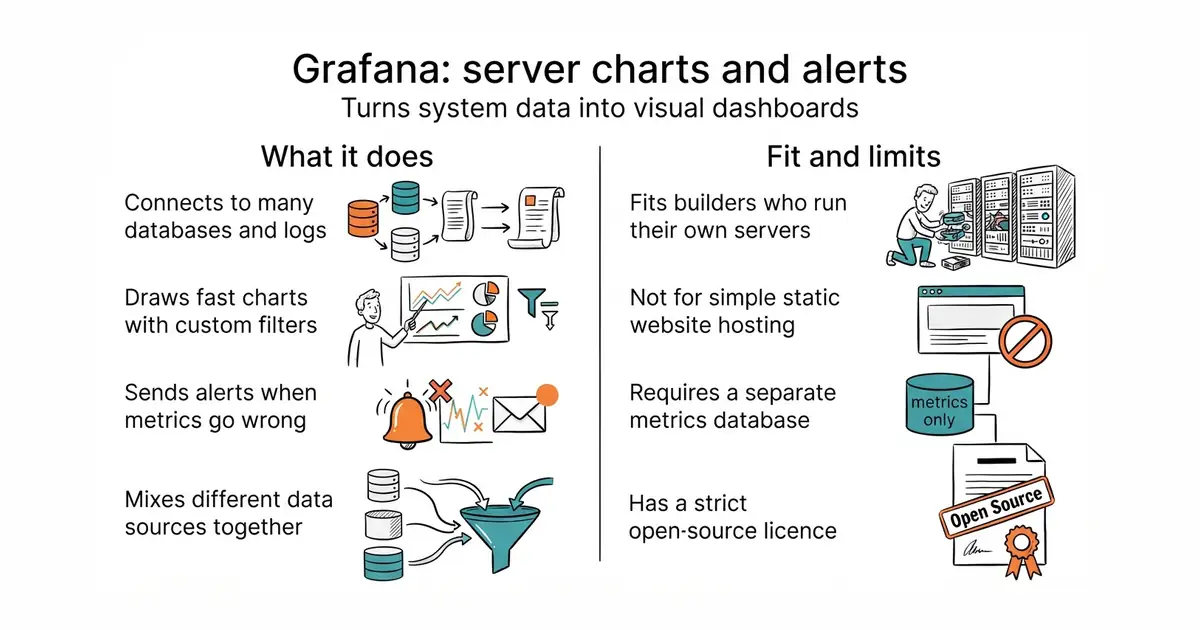

grafana/grafana
The open and composable observability and data visualization platform. Visualize metrics, logs, and traces from multiple sources like Prometheus, Loki, Elasticsearch, InfluxDB, Postgres and many more.
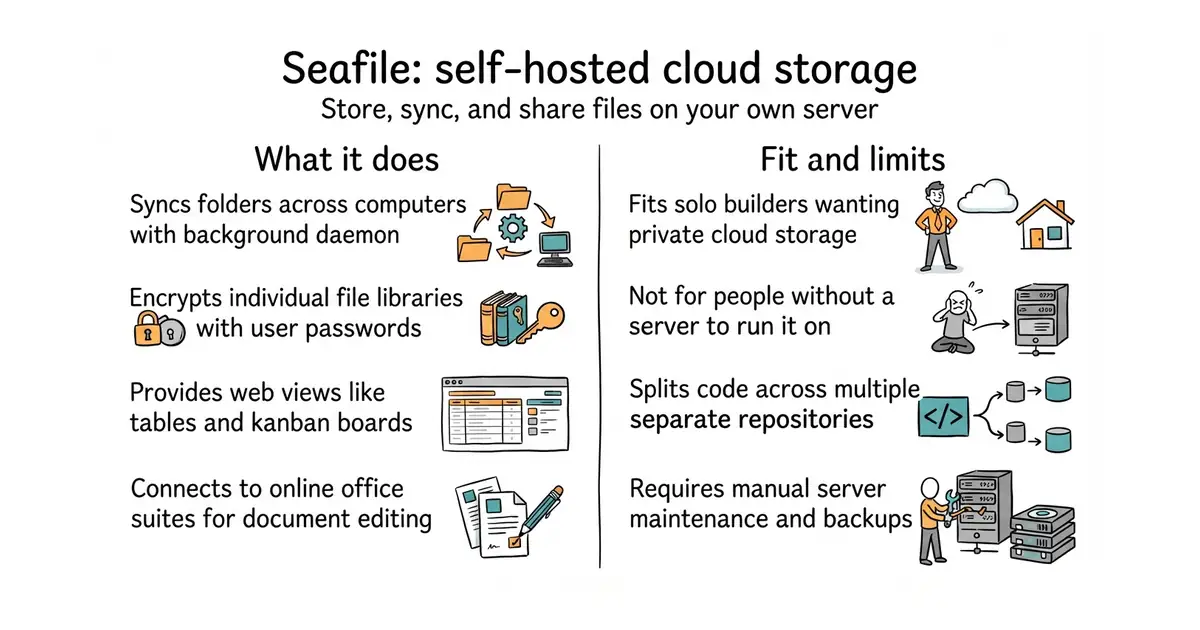

haiwen/seafile
Beyond file syncing and sharing, a new way to organize your files with extensible file properties and flexible views

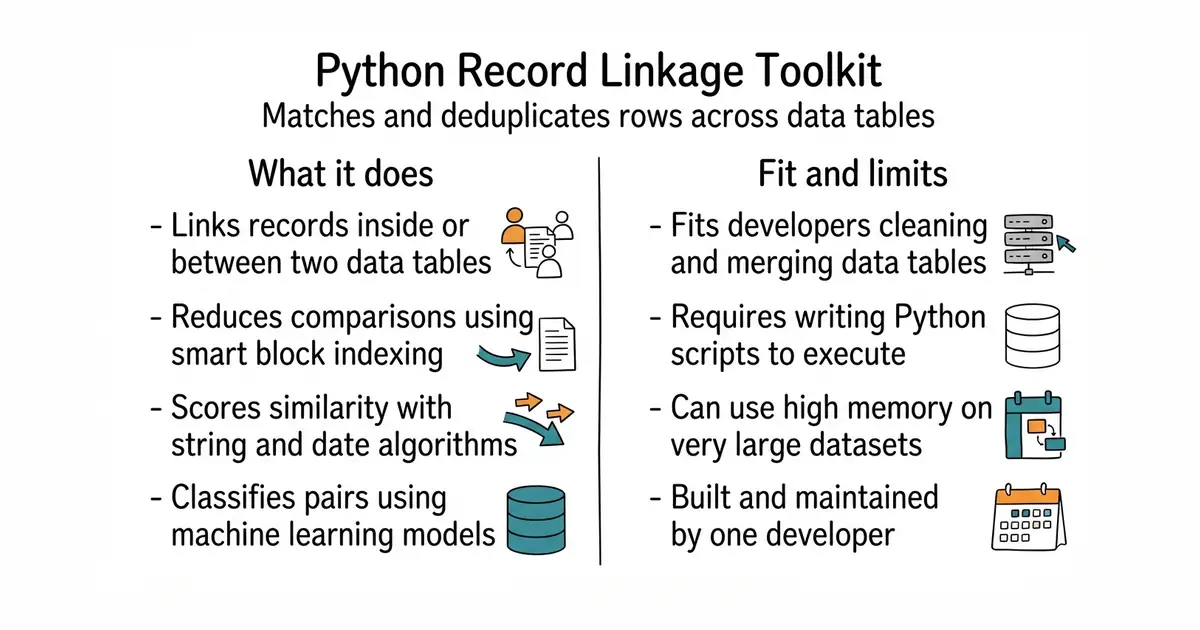

J535D165/recordlinkage
A powerful and modular toolkit for record linkage and duplicate detection in Python




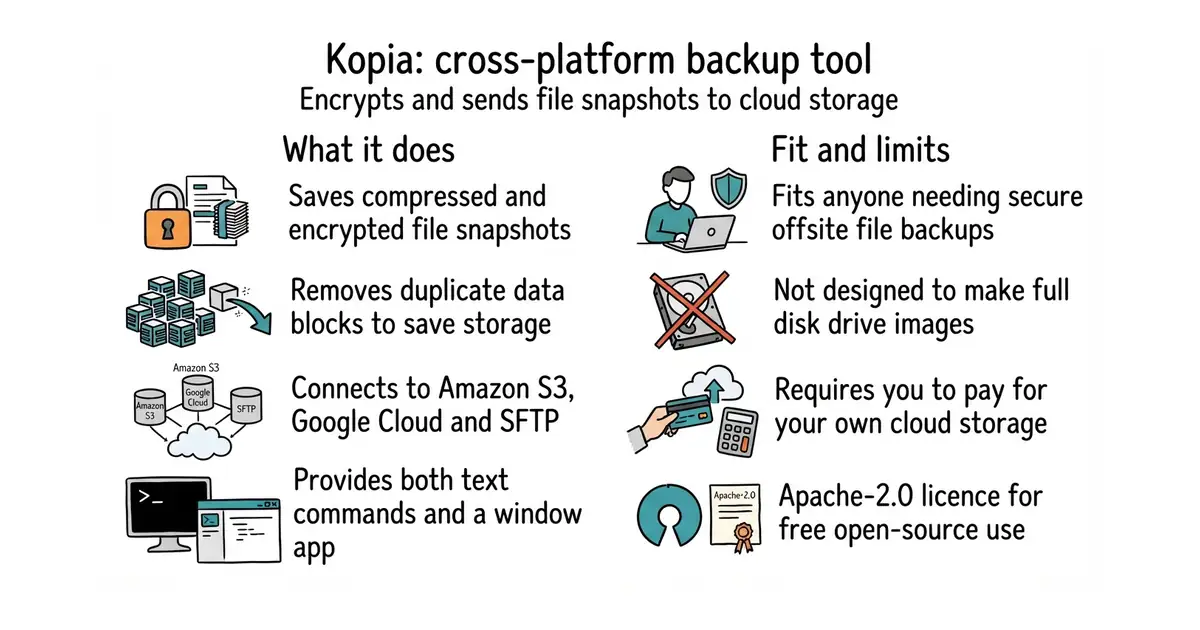

kopia/kopia
Cross-platform backup tool for Windows, macOS & Linux with fast, incremental backups, client-side end-to-end encryption, compression and data deduplication. CLI and GUI included.
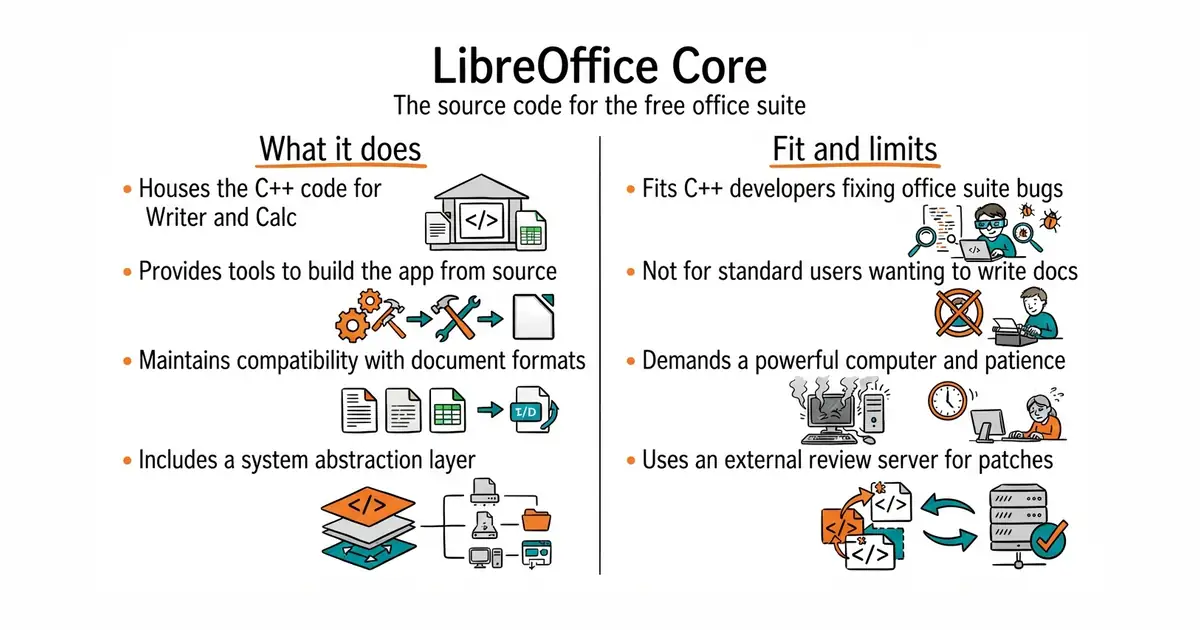

LibreOffice/core
Read-only LibreOffice core repo - no pull request (use gerrit instead https://gerrit.libreoffice.org/) - don't download zip, use https://dev-www.libreoffice.org/bundles/ instead




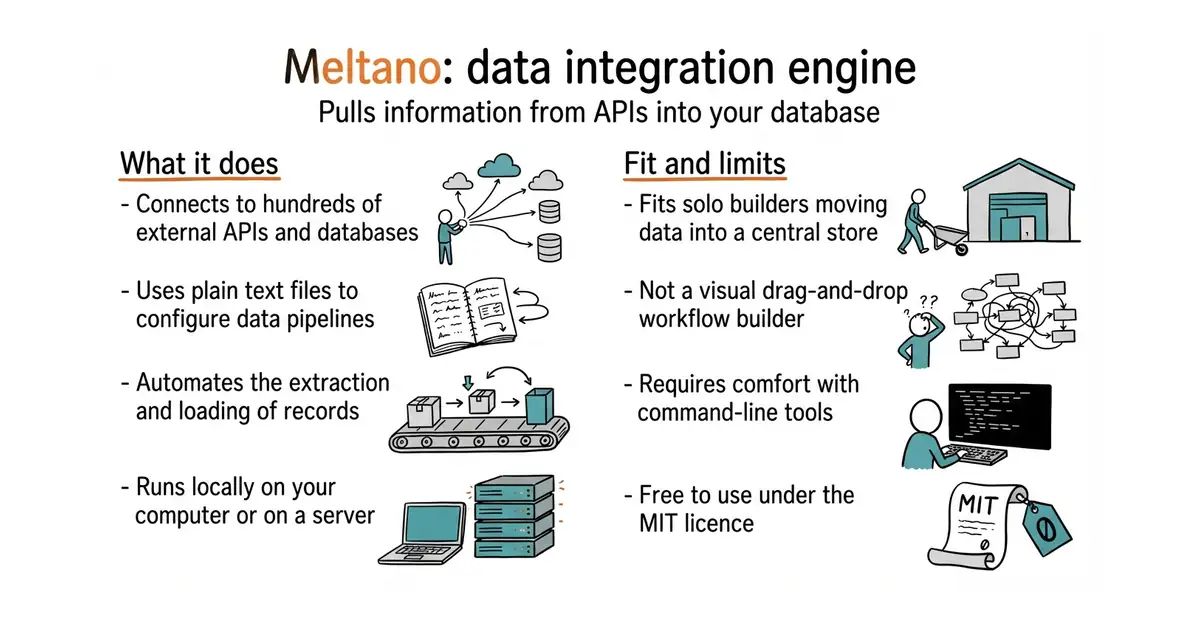

meltano/meltano
Meltano: the declarative code-first data integration engine that powers your wildest data and ML-powered product ideas. Say goodbye to writing, maintaining, and scaling your own API integrations.
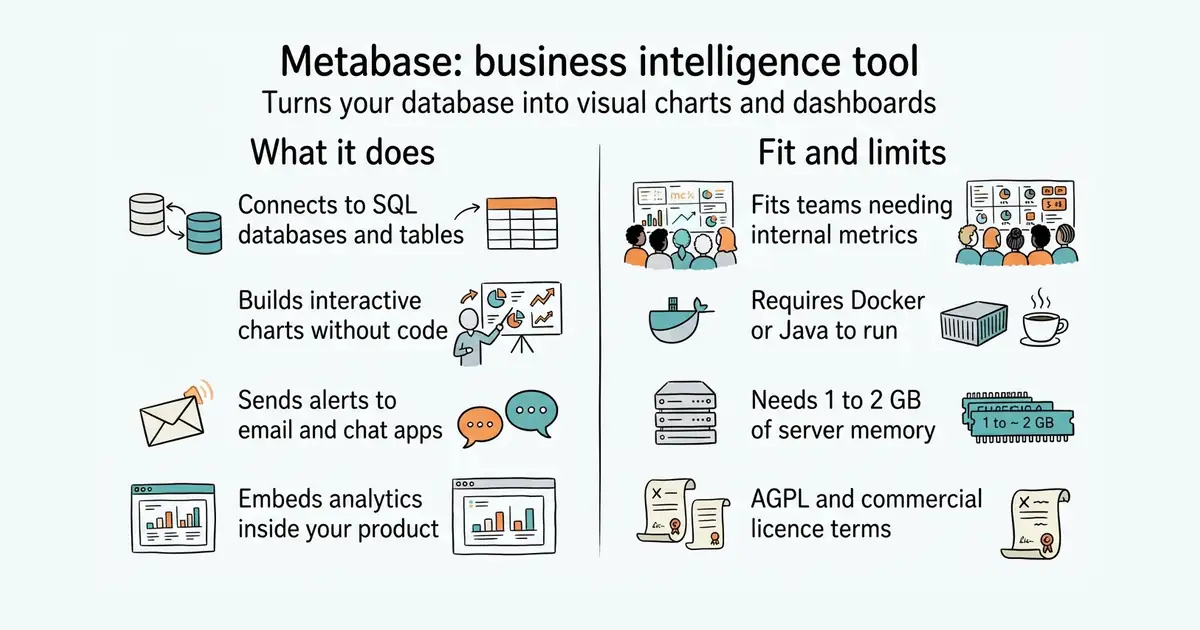

metabase/metabase
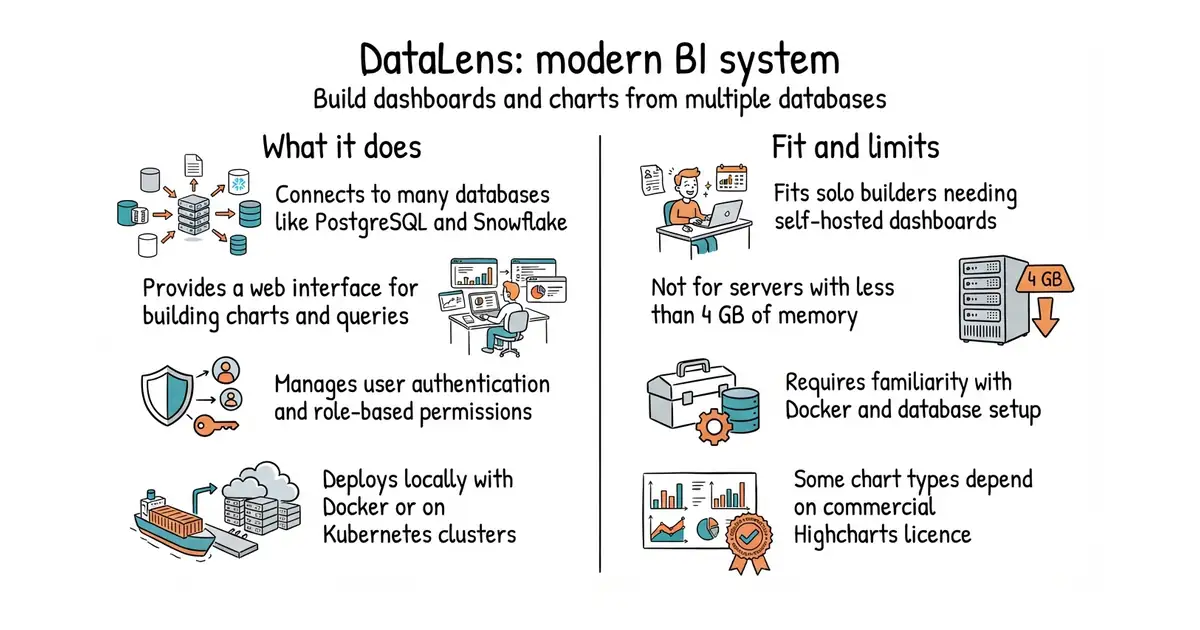
The easy-to-use open source Business Intelligence and Embedded Analytics tool that lets everyone work with data :bar_chart:
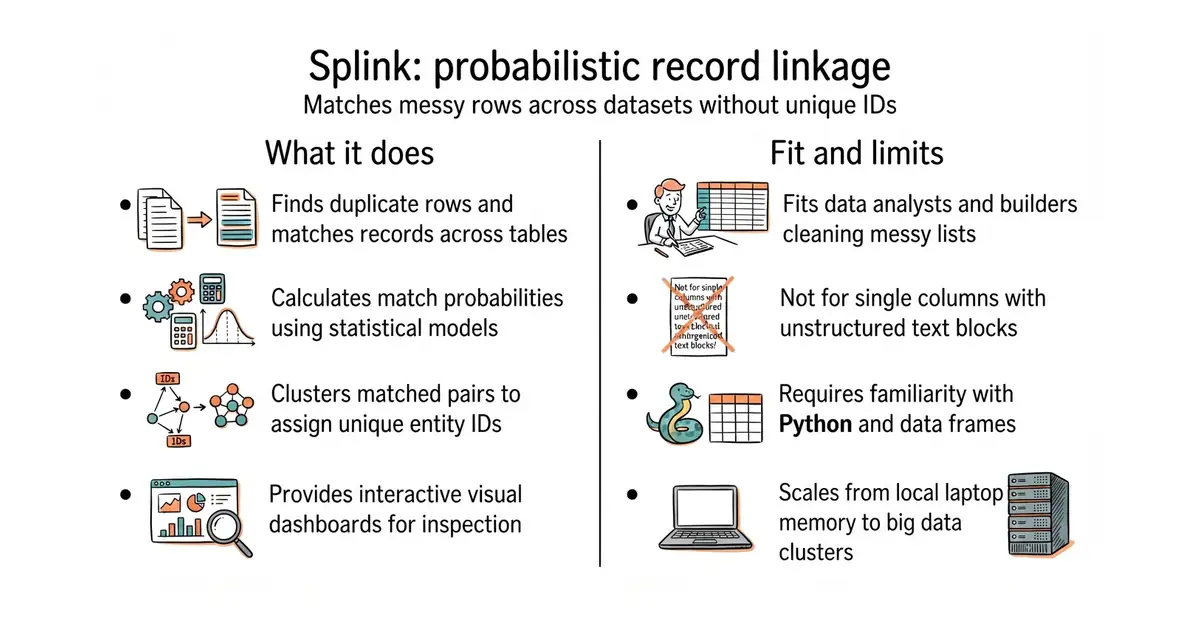

moj-analytical-services/splink
Fast, accurate and scalable probabilistic data linkage with support for multiple SQL backends


neondatabase/neon
Neon: Serverless Postgres. We separated storage and compute to offer autoscaling, code-like database branching, and scale to zero.



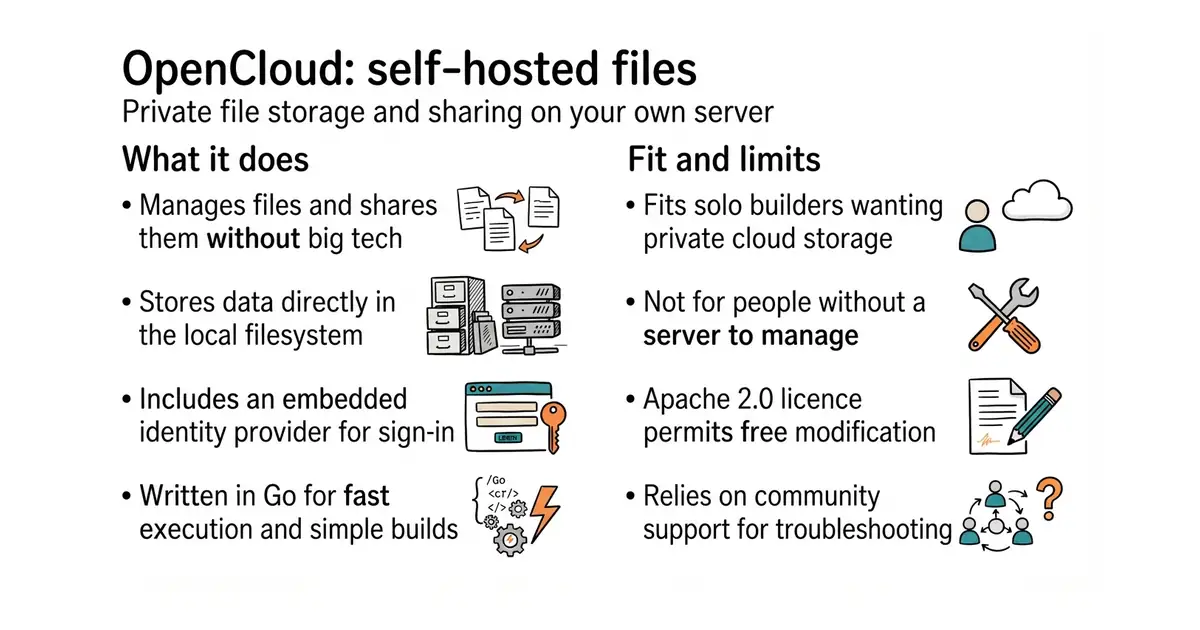

opencloud-eu/opencloud
🌤️ OpenCloud is the open source platform for file management, sharing and collaboration. Simple and sovereign.


openvenues/libpostal
A C library for parsing/normalizing street addresses around the world. Powered by statistical NLP and open geo data.
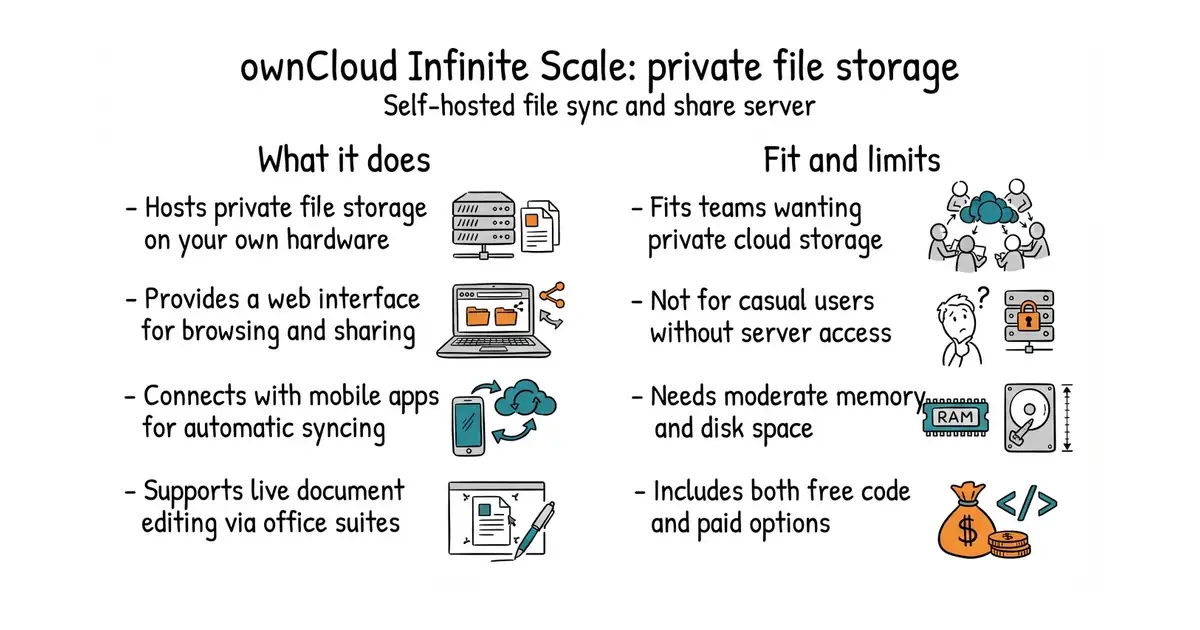

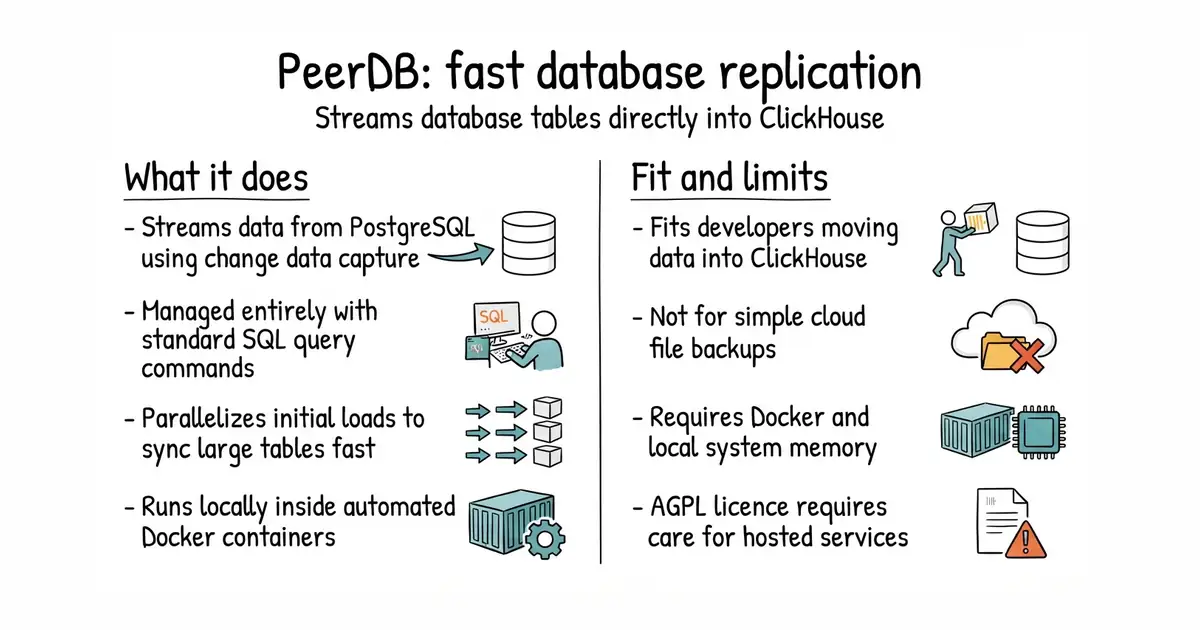

PeerDB-io/peerdb
Fast, Simple and a cost effective tool to replicate data from Postgres to Data Warehouses, Queues and Storage
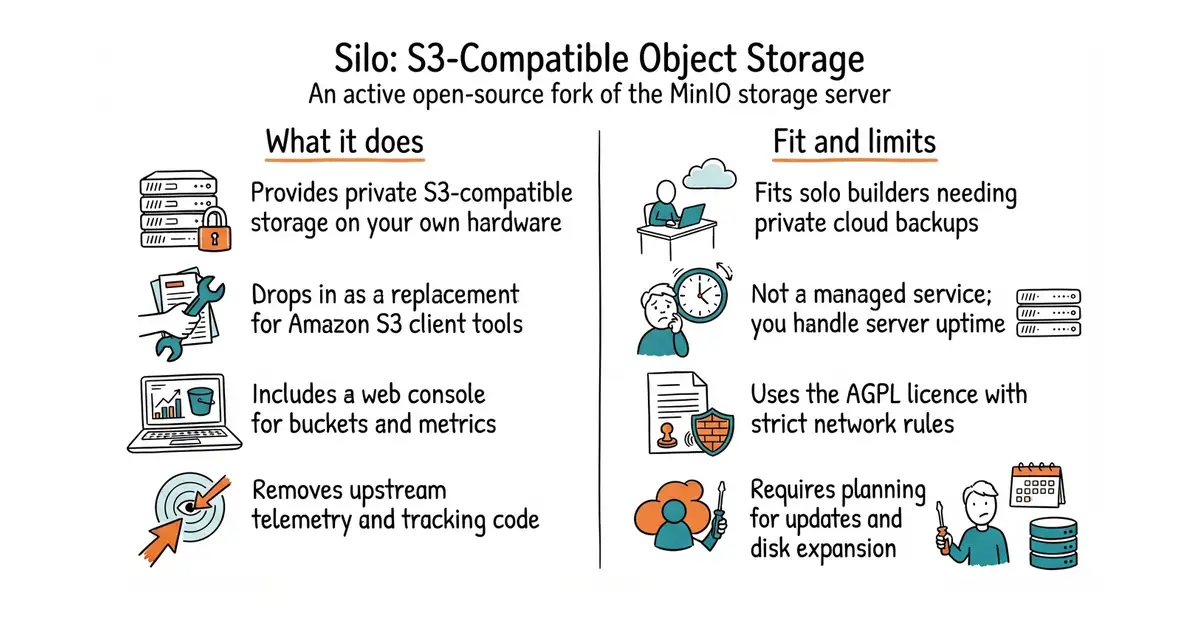

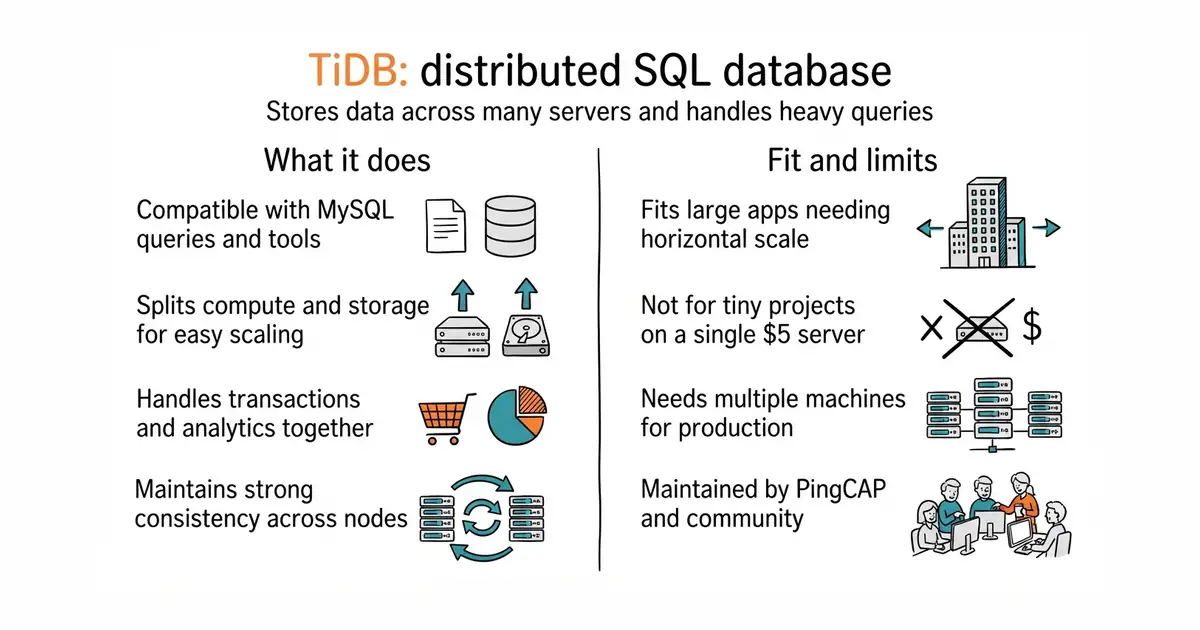

pingcap/tidb
TiDB is built for agentic workloads that grow unpredictably, with ACID guarantees and native support for transactions, analytics, and vector search. No data silos. No noisy neighbors. No infrastructure ceiling.
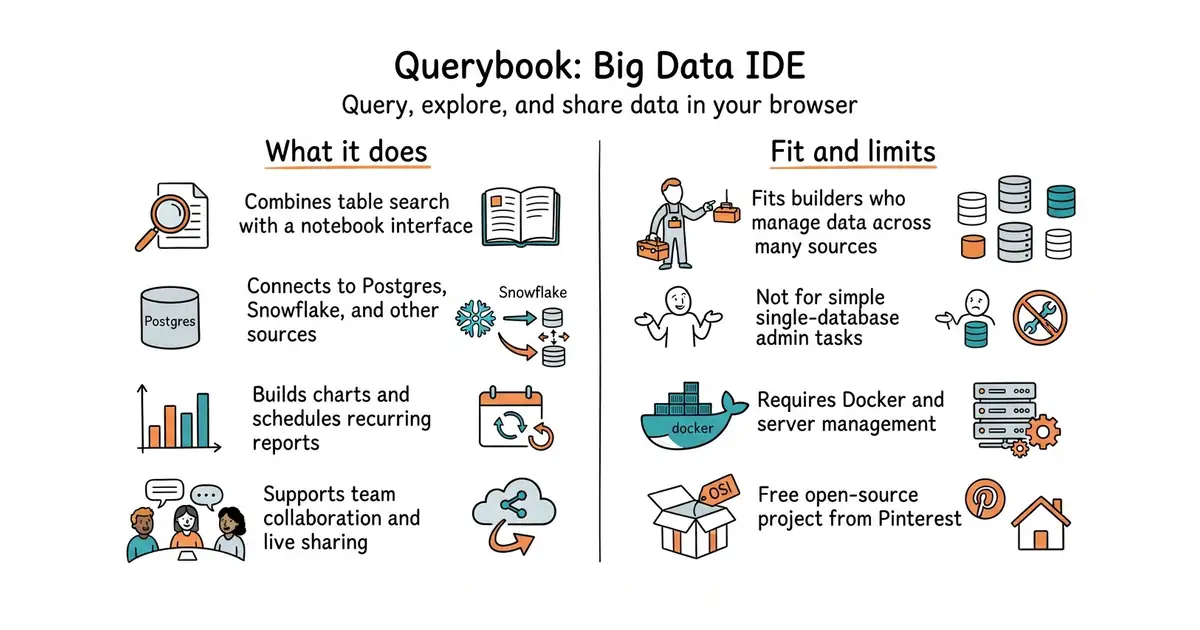

pinterest/querybook
Querybook is a Big Data Querying UI, combining collocated table metadata and a simple notebook interface.

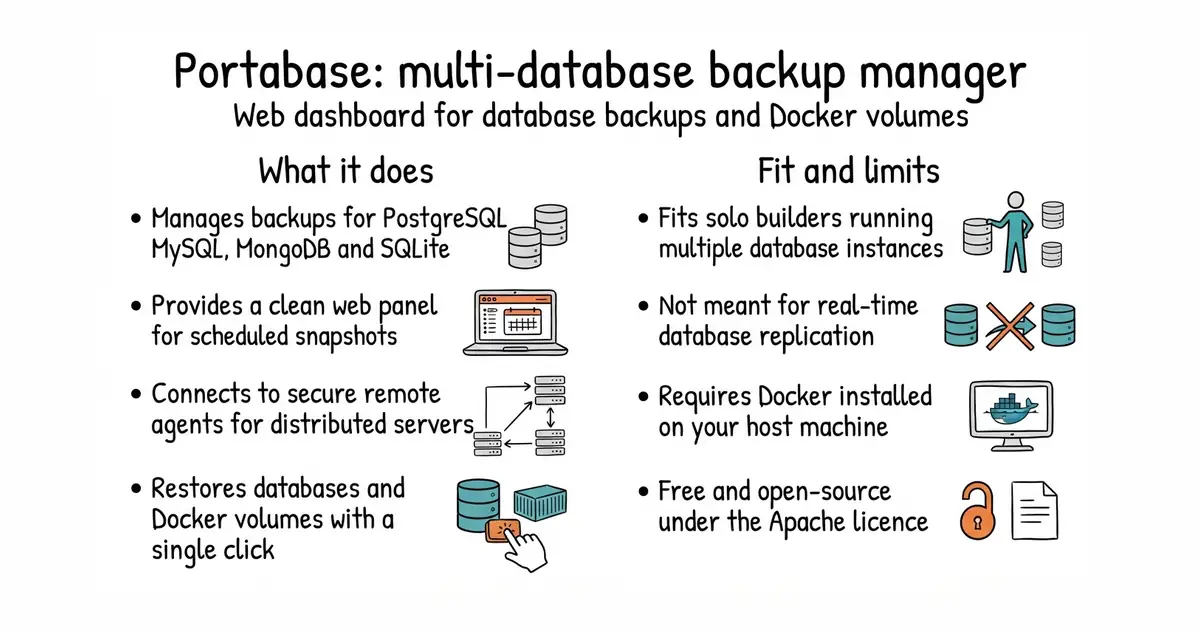

Portabase/portabase
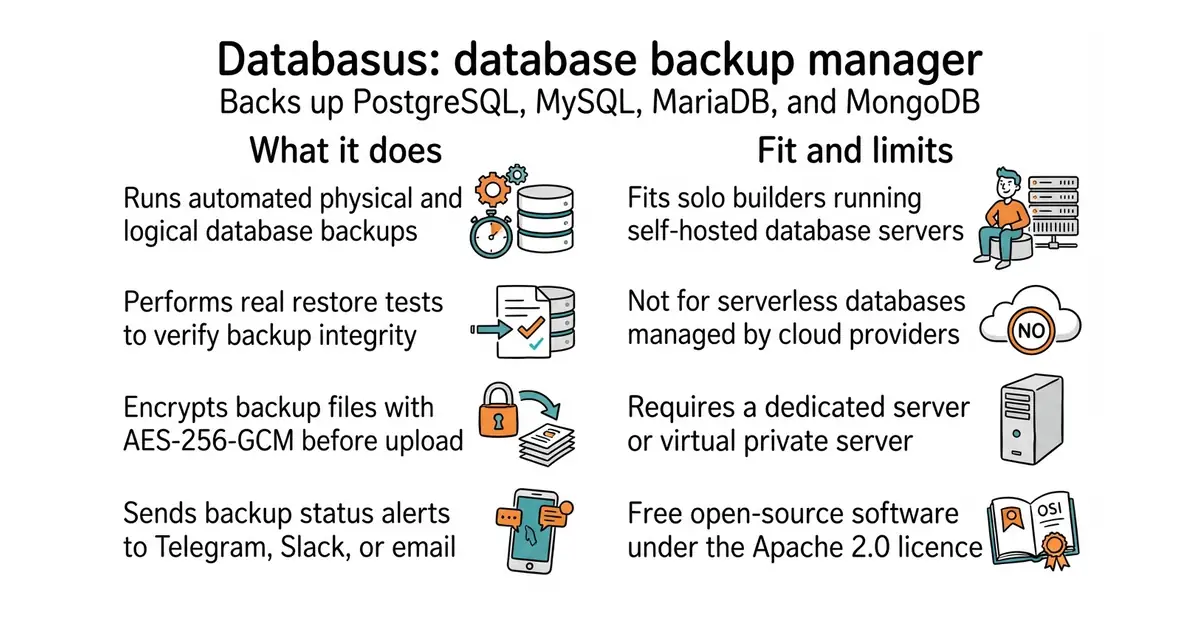
Portabase - Database backup & restore tool for PostgreSQL, MySQL, MsSQL, MariaDB, Firebird SQL, SQLite, MongoDB, Redis and Docker Volume



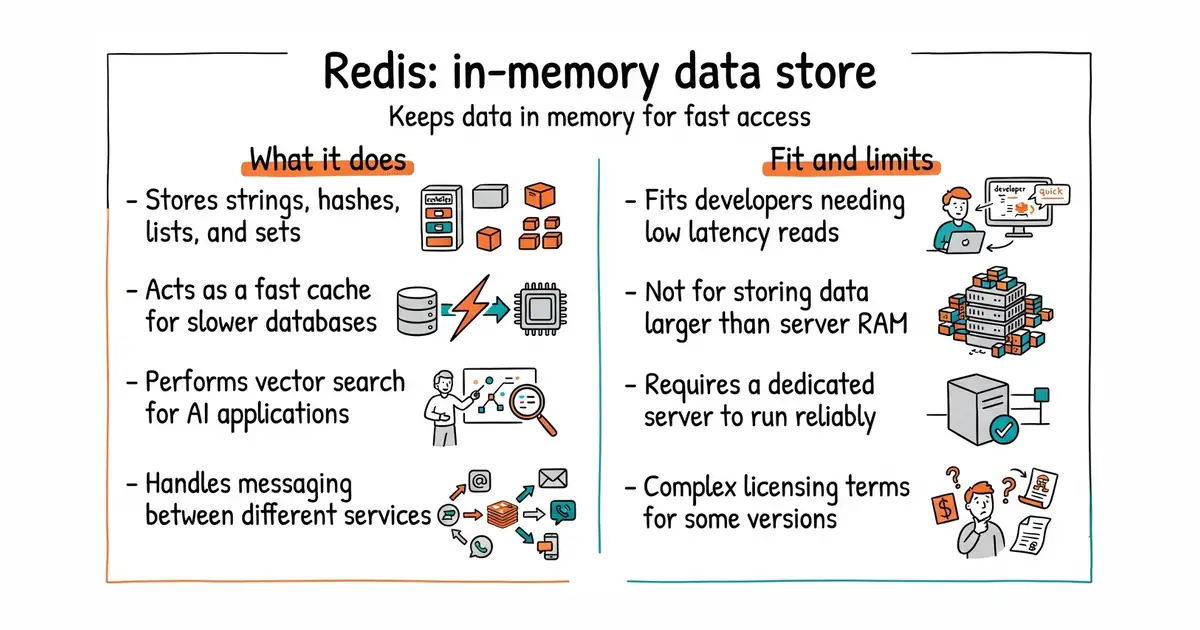

redis/redis
For developers, who are building real-time data-driven applications, Redis is the preferred, fastest, and most feature-rich cache, data structure server, and document and vector query engine.
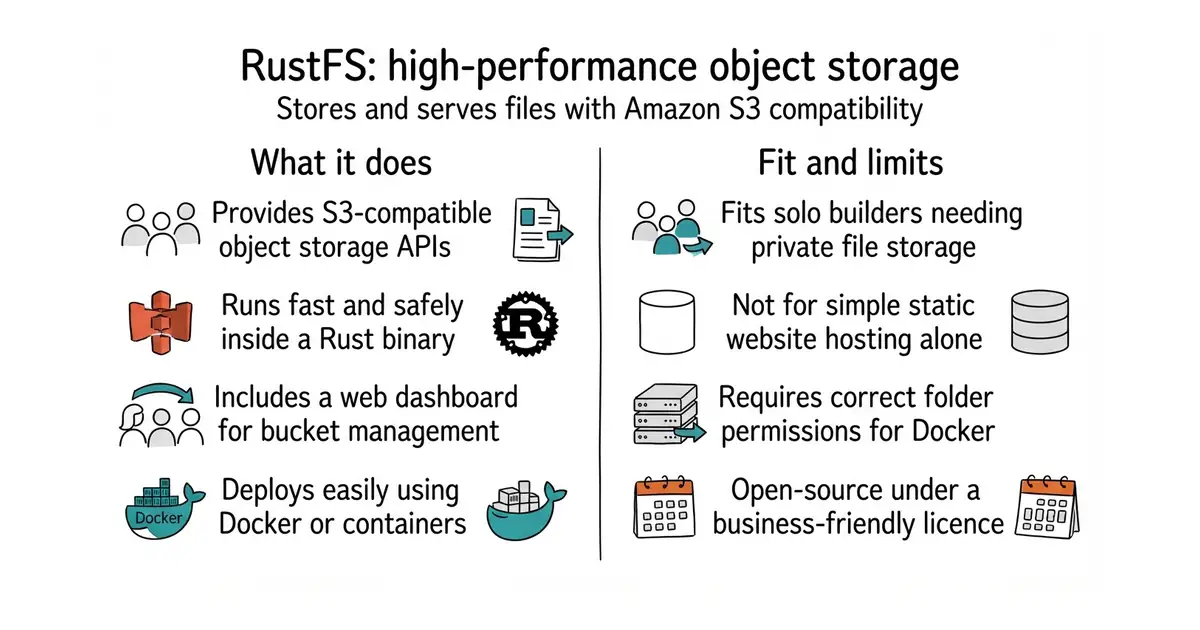

rustfs/rustfs
RustFS is an open-source, S3-compatible high-performance object storage system supporting migration and coexistence with other S3-compatible platforms such as MinIO and Ceph.
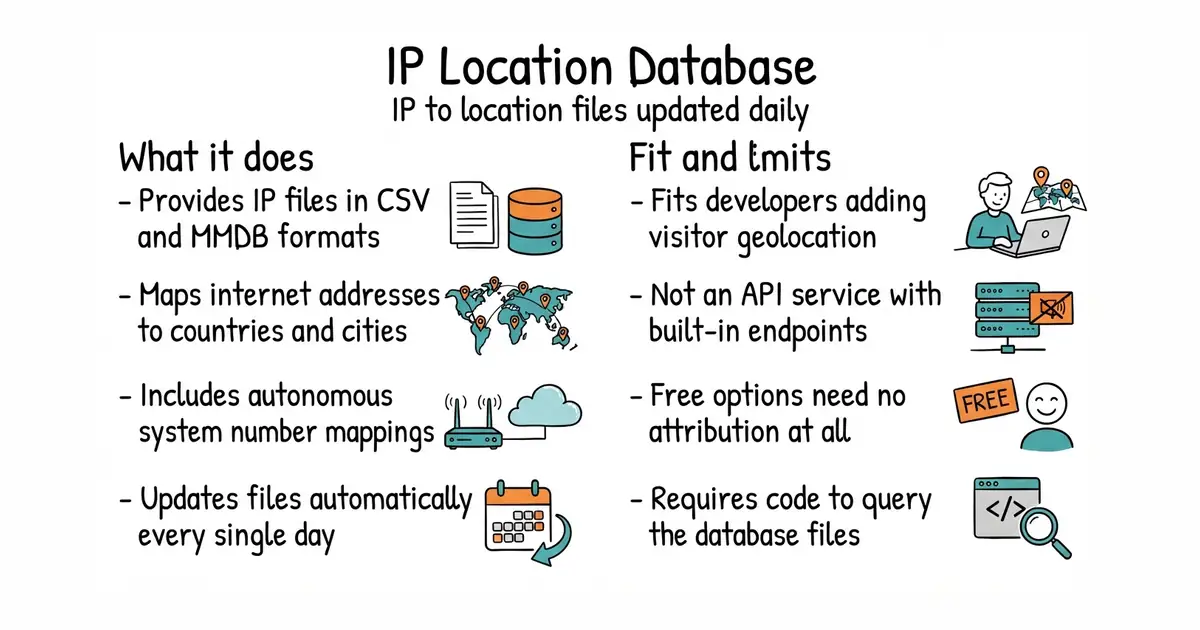
sapics/ip-location-db
ip to location database by ASN, GeoFeed, Whois, iptoasn.com, db-ip lite, GeoLite2
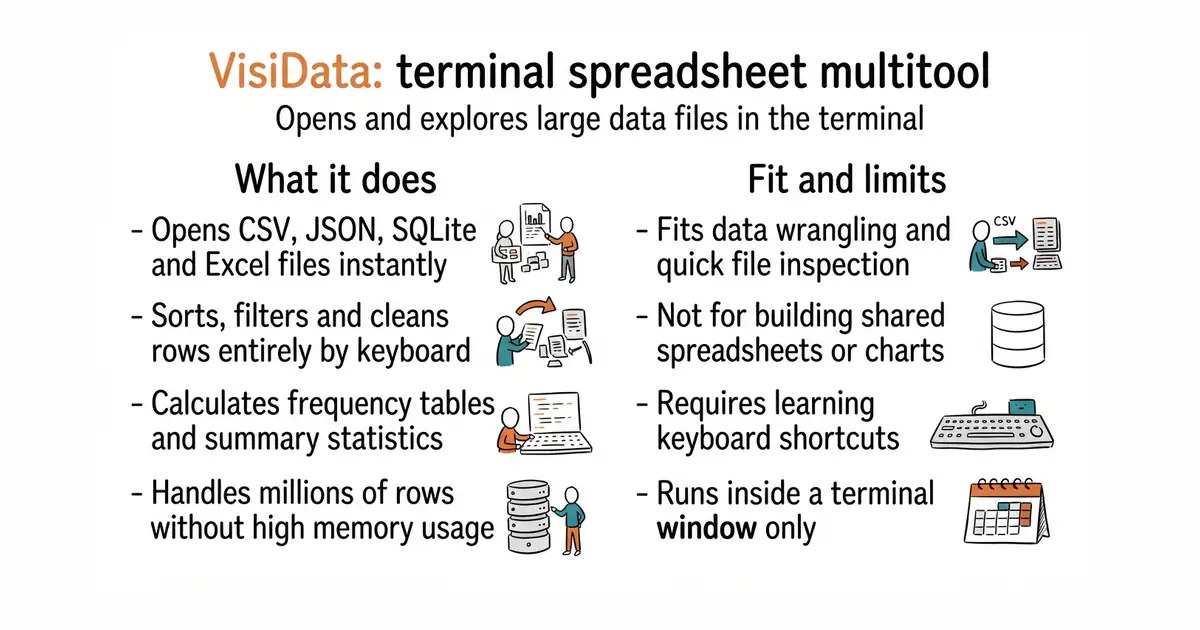


scality/cloudserver
Zenko CloudServer, an open-source Node.js implementation of the Amazon S3 protocol on the front-end and backend storage capabilities to multiple clouds, including Azure and Google.
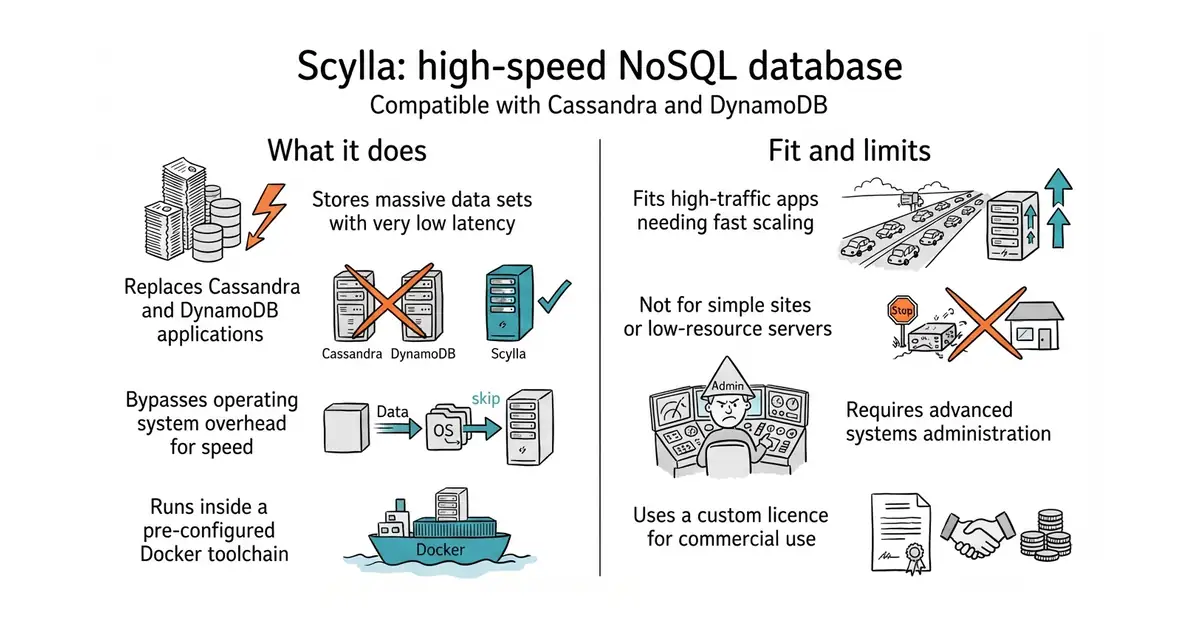

scylladb/scylladb
NoSQL data store using the Seastar framework, compatible with Apache Cassandra and Amazon DynamoDB
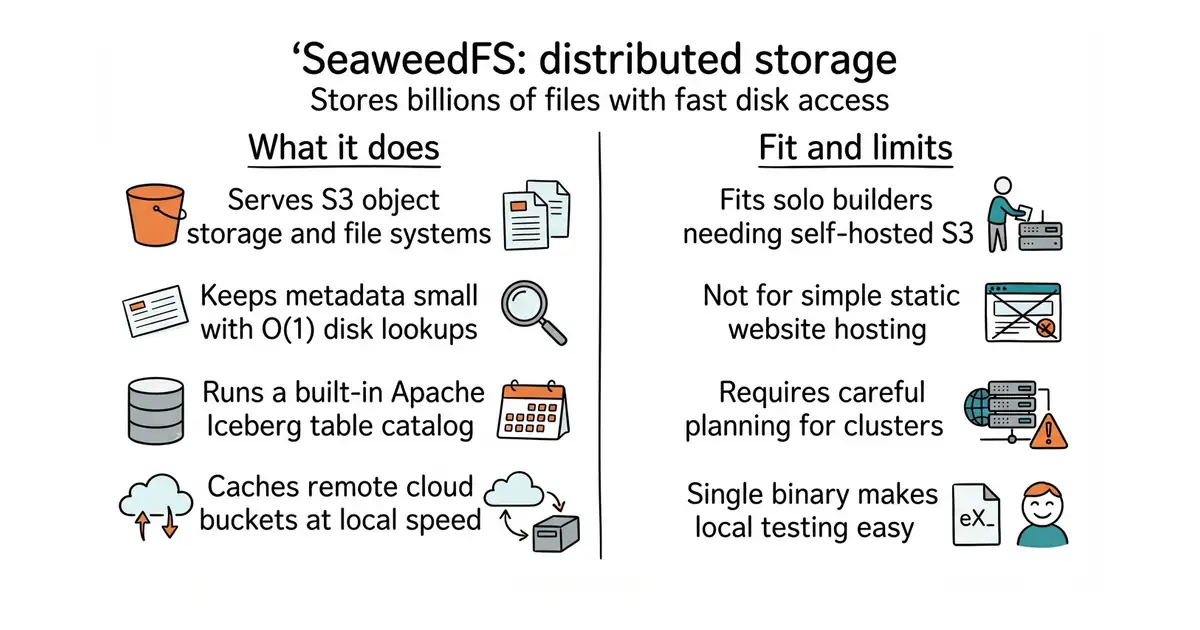

seaweedfs/seaweedfs
SeaweedFS is a distributed storage system for object storage (S3), file systems, and Iceberg tables, designed to handle billions of files with O(1) disk access and effortless horizontal scaling.

slingdata-io/sling-cli
Sling is a CLI tool that extracts data from a source storage/database and loads it in a target storage/database.
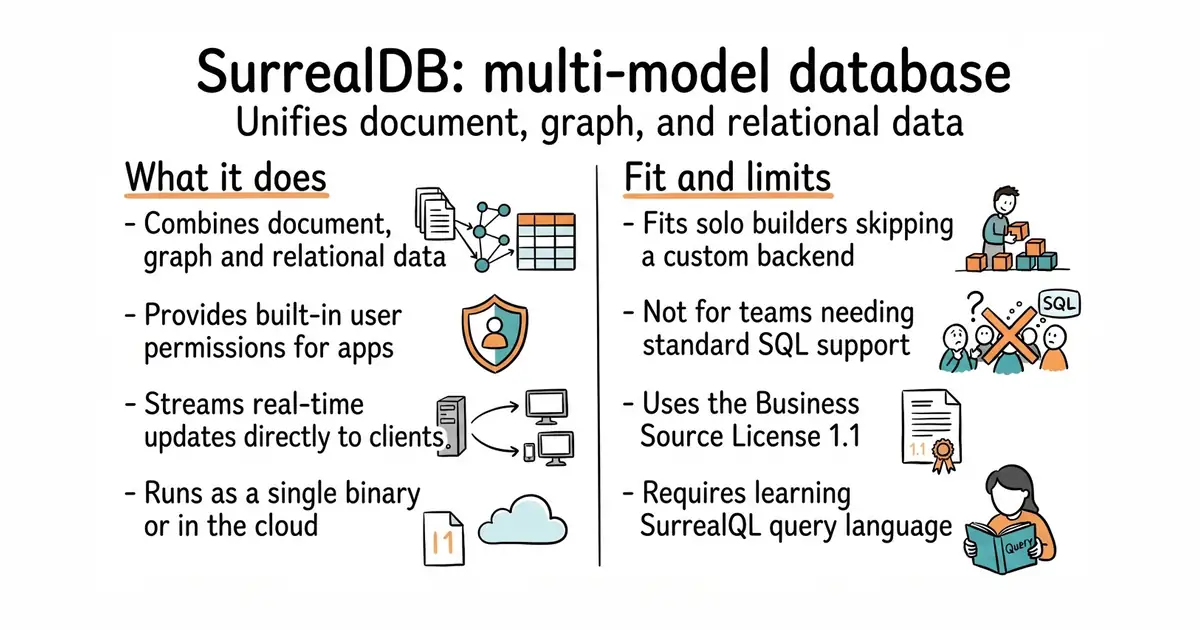

surrealdb/surrealdb
A scalable, distributed, collaborative, document-graph database, for the realtime web
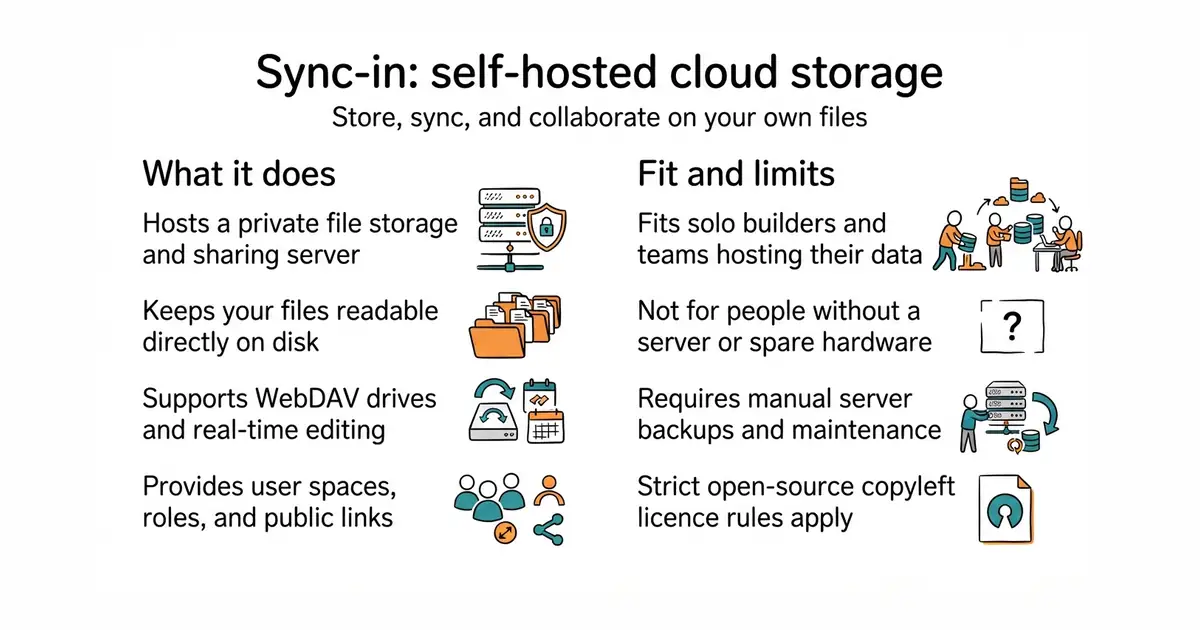

Sync-in/server
Sync-in · Sovereign platform for file storage, sharing, synchronization, and collaboration.
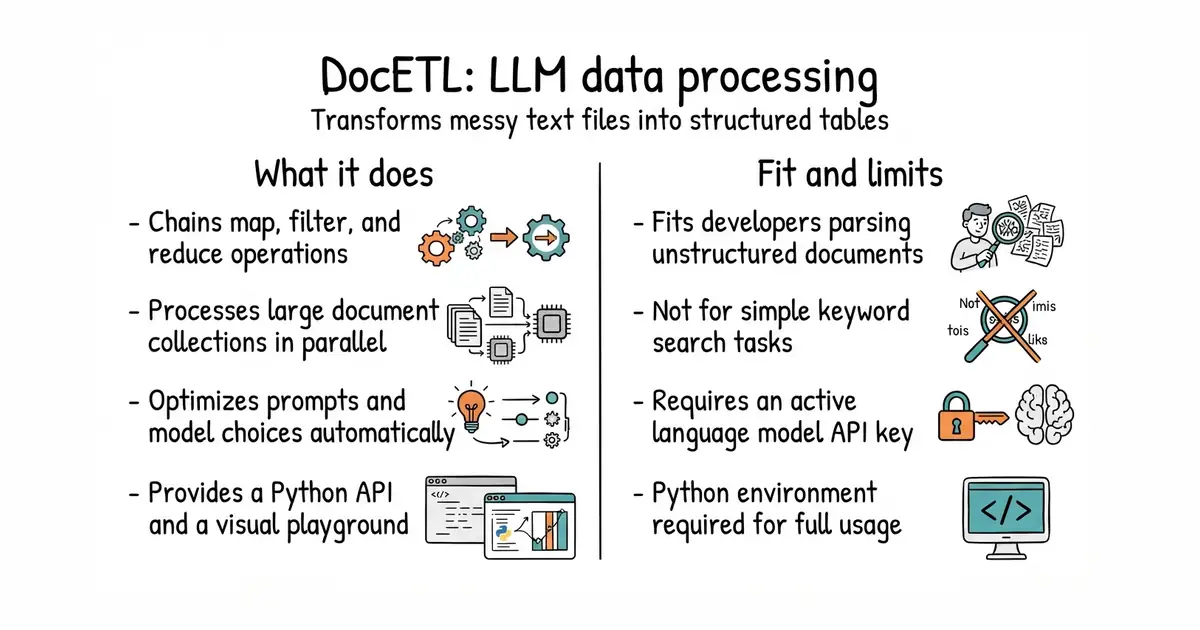


upgini/upgini
Data search & enrichment library for Machine Learning → Easily find and add relevant features to your ML & AI pipeline from hundreds of public and premium external data sources, including open & commercial LLMs
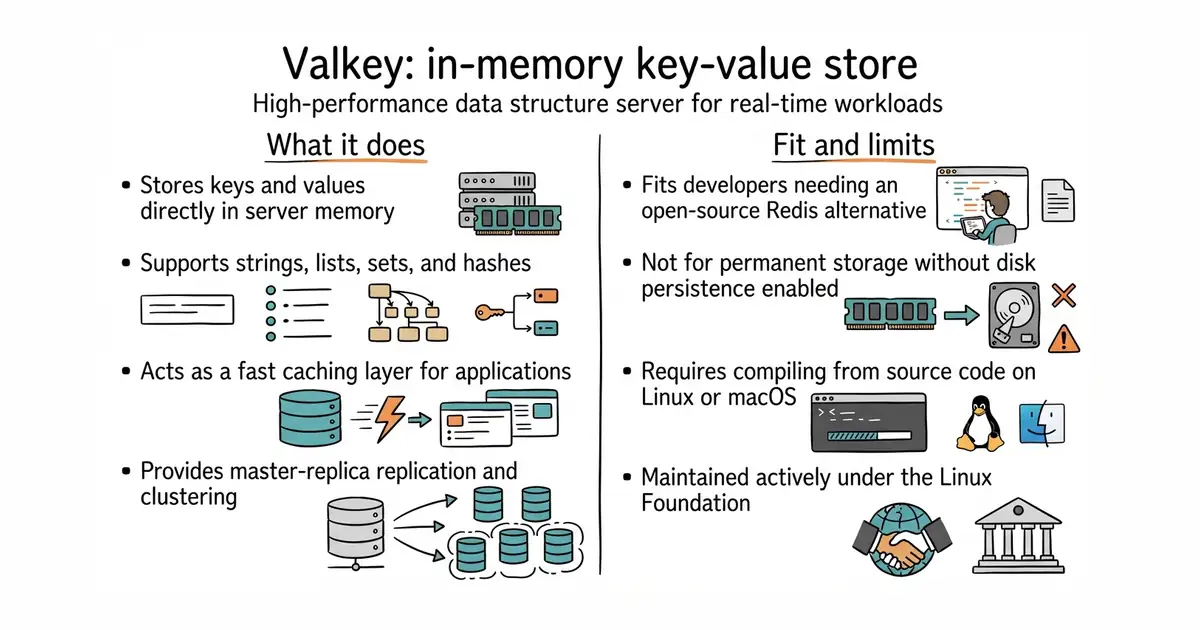

valkey-io/valkey
A flexible distributed key-value database that is optimized for caching and other realtime workloads.
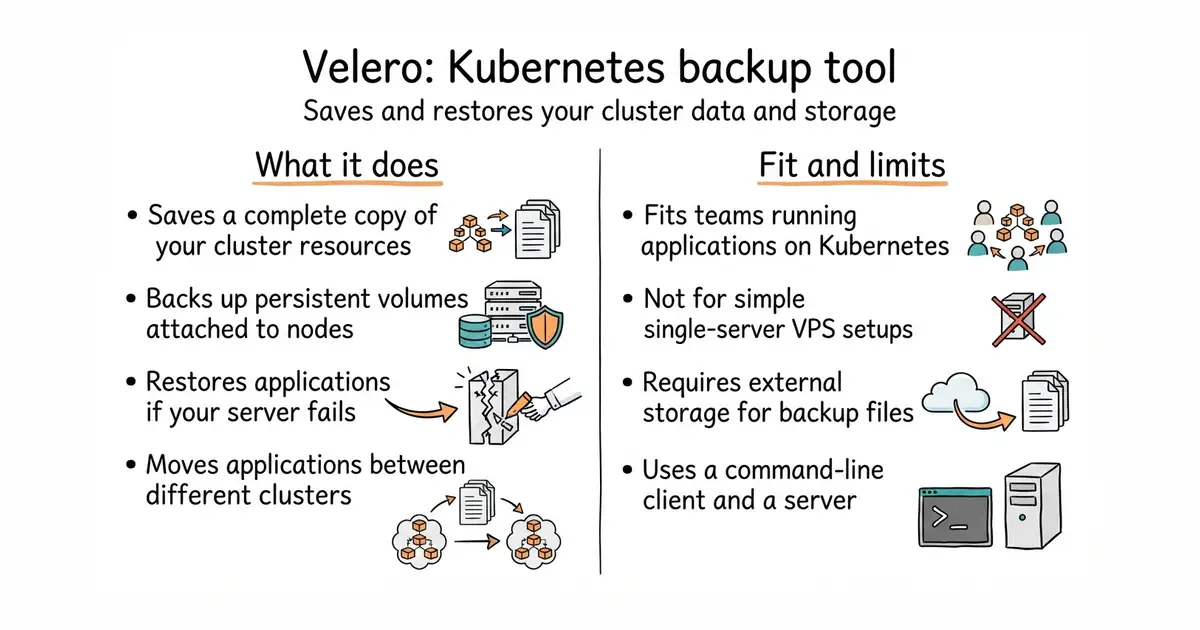

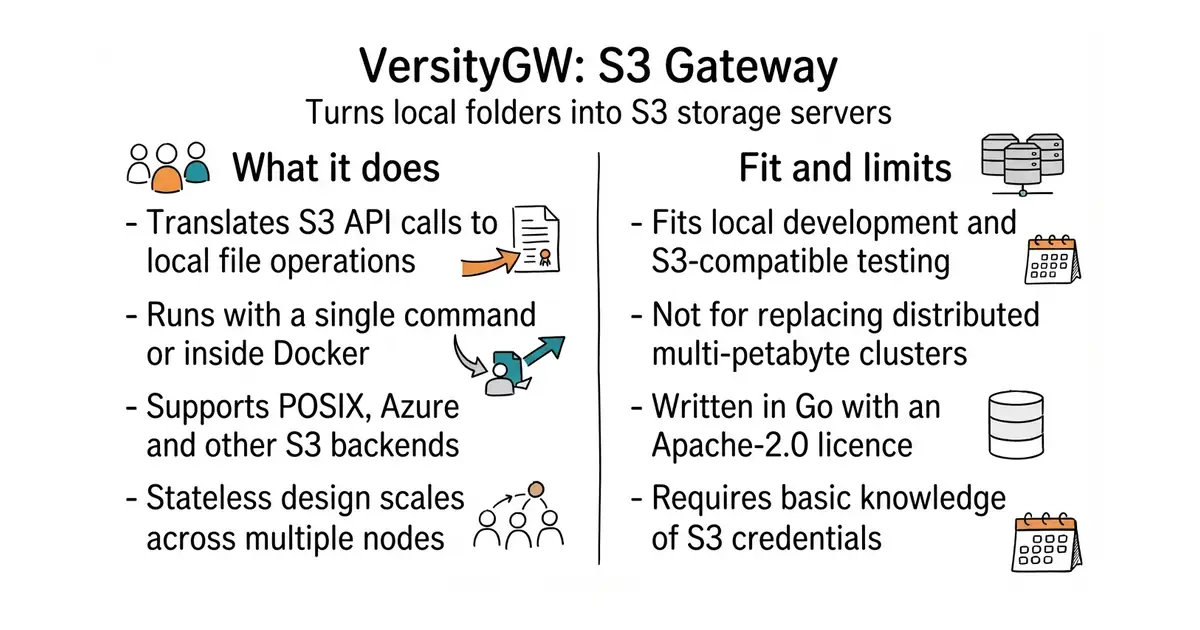




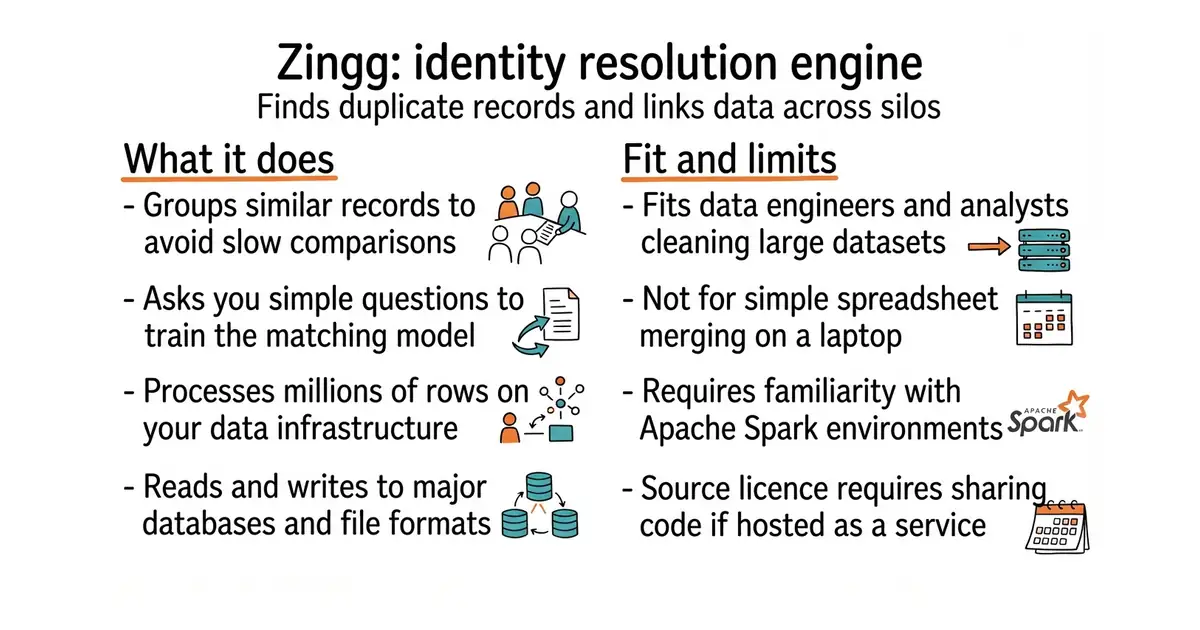

zinggAI/zingg
Scalable master data management, identity resolution, entity resolution, and deduplication using ML
No repository in this area carries every tag you picked.
Get the next edition in your inbox
A dozen repositories, opened and checked. The licence read, the last release dated, and the ones that did not make it named with the reason. It is the half most lists leave out.
No tracking pixels. One click to leave. The archive stays free either way.
We use your address to send the edition and nothing else. Confirm by email, leave in one click. How we handle it.
Suggest a repository
Any public GitHub repository, any size. If it is your own, that is welcome too. We read every suggestion, and some picks are made at random, so stars do not decide. Whatever we pick goes through the same checks as every other entry, and the review is written either way.
Thanks — it is in.
Every suggestion is read. The ones we pick appear in an edition, credited to you if you left a name.