Radar check
What we found when we opened it. Every bar is one fact, with its date.
Last code pushed 15 Oct 2026, 10 days before this check.
No releases published on GitHub; the code date above is the one to trust.
Public since August 2023, a little over 3 years.
147 stars and 16 forks.
1 commits and 0 new issues in the last 90 days.
5 contributors. 1 pull requests merged in 90 days. A small team carries it.
No security policy file says how to report a problem. No published security advisories.
How the bars are scored
- Alive. Days since the last code push: a week or less 100, a month 90, three months 70, six months 50, a year 30, eighteen months 15, older 0.
- Releases. Age of the latest GitHub release, on a similar scale; no bar when the project publishes no releases.
- Maturity. Age of the project: eight years 100, five 90, three 70, two 55, one 40, six months 25, younger 10.
- Adoption. Stars on a log scale: 100,000 stars is 100, 10,000 is 80, 1,000 is 60, 100 is 40.
- Activity. Commits in the last 90 days: 300 or more 100, 100 85, 30 65, 10 45, any 25.
- Community. People who have contributed: 100 or more 100, 30 80, 10 60, 5 40, 2 25, one 10.
- Security. A published security policy 80, none 40; published advisories are listed, not scored.
Checked by Repo Radar on 26 Oct 2026 from the repository on GitHub.
In simple English
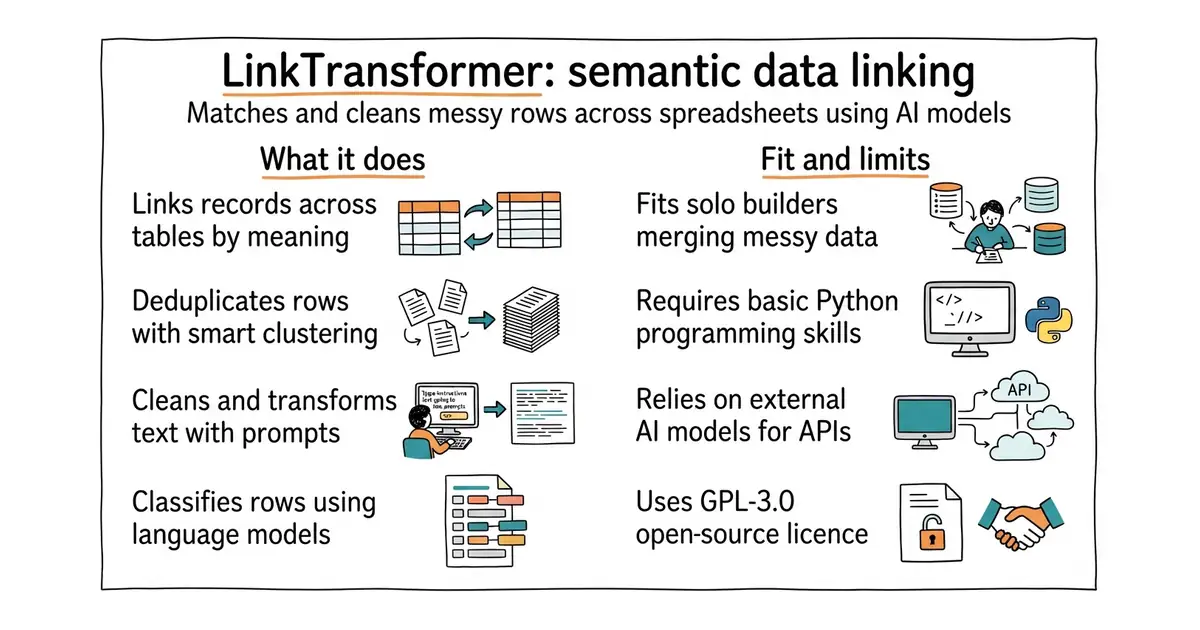
Data from different spreadsheets often has spelling mistakes or slight differences. Fixing these errors by hand takes hours of tedious work. This tool matches similar rows and cleans up text automatically using artificial intelligence. You write simple Python commands to run the process on your computer. It needs some basic programming knowledge to set up and use.
What it is
LinkTransformer is an open-source Python package for record linkage, data deduplication, and row classification using deep learning models. It connects tabular datasets by comparing text semantics rather than exact spelling.
What it is good for
Solo builders and researchers who need to merge messy customer lists, product catalogs, or survey results from different sources without writing complex matching rules.
- Matches rows even when spelling differs.
- Combines local models and cloud APIs.
- Supports deduplication and text classification.
- Requires writing Python code to run.
- Needs an internet connection or a fast computer for large models.
- GPL-3.0 licence may restrict how you share modified versions.
manual spreadsheet matching and fuzzy lookup scripts
pandas

- Athou/commafeed3.6k stars
A feed reader you run yourself, which collects new articles from the sites you follow.
- apache/airflow47k stars
Runs chains of scheduled jobs written in Python, and keeps a record of every run.
- cybertec-postgresql/pg_timetable1.4k stars
A job scheduler for PostgreSQL whose jobs and schedules live in the database itself.
source venv/bin/activate
pip install linktransformer