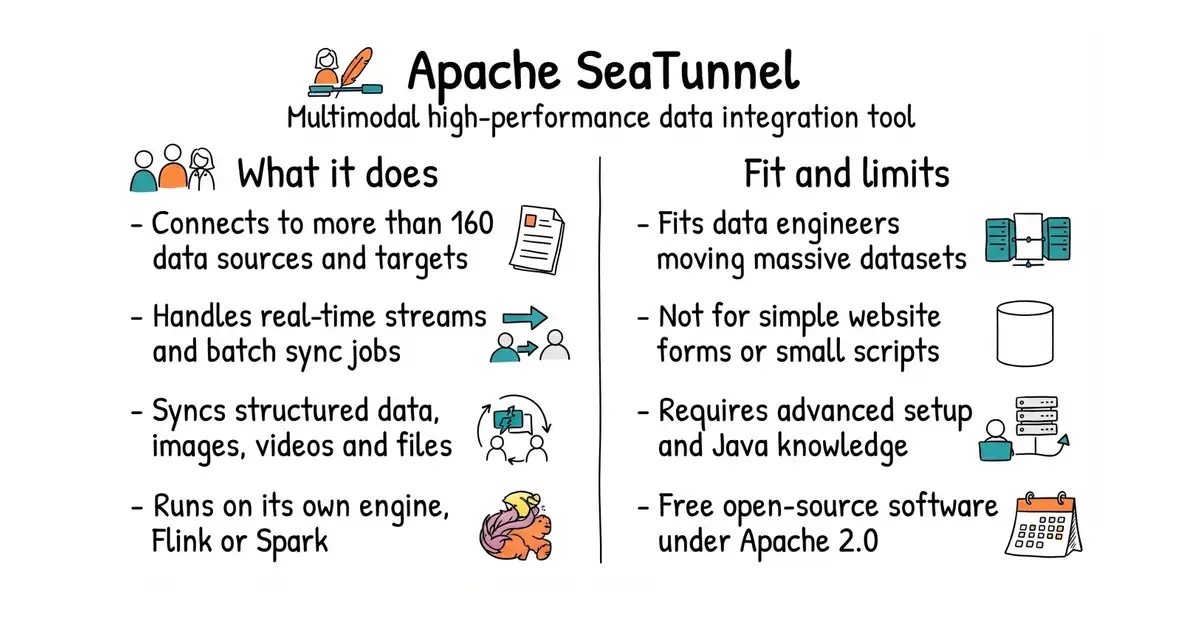
In simple English
This tool copies data from one place to another. It handles large files, live streams and whole databases at once. It connects to more than one hundred and sixty different systems. You can run it on its own engine or use it with other big data tools. It is free to use under an open-source licence.
What it is
Apache SeaTunnel is a distributed data integration platform written in Java (a programming language used for large enterprise software). It synchronizes structured and unstructured information across different storage systems in real time or in batches.
What it is good for
Data engineers and solo builders who need to move huge datasets between different databases without losing records or slowing down their servers.
- Connects to more than 160 different data sources and destinations.
- Supports real-time streaming and scheduled batch syncs.
- Maintains data consistency across multiple database tables.
- Complex setup process that requires a strong background in data engineering.
- Needs significant memory and server resources to run distributed jobs.
- Heavy dependency on the Java ecosystem and configuration files.
custom data sync scripts and manual database exports
Apache Kafka for stream processing
- airbytehq/airbyte22k stars
Airbyte offers a web interface and many connectors for syncing data, while SeaTunnel focuses on high-performance distributed streaming.
- apache/flink26k stars
Apache Flink is a stream processing framework that SeaTunnel can use as an underlying execution engine.
- apache/spark44k stars
Apache Spark is a large-scale data processing engine that SeaTunnel supports alongside its own Zeta engine.


- meilisearch/meilisearch59k stars
A search engine you run yourself, built for fast answers and forgiving spelling.
- beekeeper-studio/beekeeper-studio24k stars
A desktop window onto a database, so you can read and edit rows without writing commands.
- sqliteai/sqlite-vector1.1k stars
An add-on that gives the single-file SQLite database meaning-based search, with its own accuracy figures printed in the README.
Download the release archive from the official website and follow the local deployment guide.