Radar check
What we found when we opened it. Every bar is one fact, with its date.
Last code pushed 21 Feb 2024, 32 months before this check.
Latest release v0.16 on 20 Jul 2023.
Public since October 2015, about 11 years.
1,065 stars and 153 forks.
0 commits and 0 new issues in the last 90 days.
21 contributors. No pull requests merged in 90 days; changes go in directly.
No security policy file says how to report a problem. No published security advisories.
How the bars are scored
- Alive. Days since the last code push: a week or less 100, a month 90, three months 70, six months 50, a year 30, eighteen months 15, older 0.
- Releases. Age of the latest GitHub release, on a similar scale; no bar when the project publishes no releases.
- Maturity. Age of the project: eight years 100, five 90, three 70, two 55, one 40, six months 25, younger 10.
- Adoption. Stars on a log scale: 100,000 stars is 100, 10,000 is 80, 1,000 is 60, 100 is 40.
- Activity. Commits in the last 90 days: 300 or more 100, 100 85, 30 65, 10 45, any 25.
- Community. People who have contributed: 100 or more 100, 30 80, 10 60, 5 40, 2 25, one 10.
- Security. A published security policy 80, none 40; published advisories are listed, not scored.
Checked by Repo Radar on 26 Oct 2026 from the repository on GitHub.
In simple English
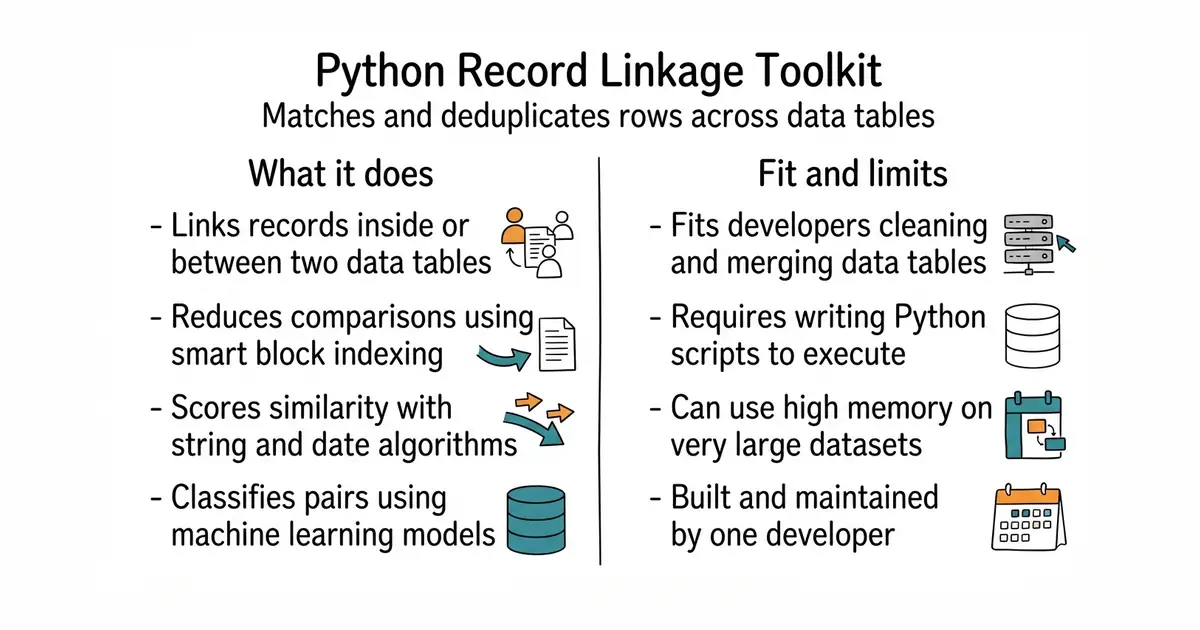
When you collect data from two different places, the same person or item often appears twice with slightly different spellings. Matching them by hand takes too many hours. This software checks your lists automatically and finds the duplicates. It runs inside your own Python programs. You need to know basic programming to use it, and your computer needs standard memory to hold your tables.
What it is
A Python library (a bundle of pre-written code that you add to your own program) that joins records inside or between data tables. It handles indexing, string comparisons, and classification.
What it is good for
Solo builders cleaning messy customer lists, merging data imports, or finding duplicate accounts in a database.
Status
No code changes since 2024-02-21.
- Compares text using methods like Jaro-Winkler and Levenshtein distance.
- Provides both supervised and unsupervised classifiers to decide if two rows match.
- Integrates directly with pandas (a Python library for reading and manipulating data tables) for easy data loading.
- Requires writing Python code to set up and run.
- Large data tables can use a lot of RAM (computer memory for active programs) during comparisons.
- Maintained by a single developer, so major updates depend on one person.
matching rows manually in a spreadsheet
pandas
- dedupeio/dedupe4.5k stars
A Python library for accurate duplicate detection using active learning, though it requires more configuration.

- tobymao/sqlglot9.7k stars
Reads, rewrites and translates SQL between more than twenty database dialects, without a database.
- patroni/patroni8.8k stars
Watches a group of PostgreSQL copies and promotes a new leader when the leader fails.
- pgEdge/spock758 stars
An add-on that lets several PostgreSQL databases all accept changes and keep each other in step.
source venv/bin/activate
pip install recordlinkage