In simple English
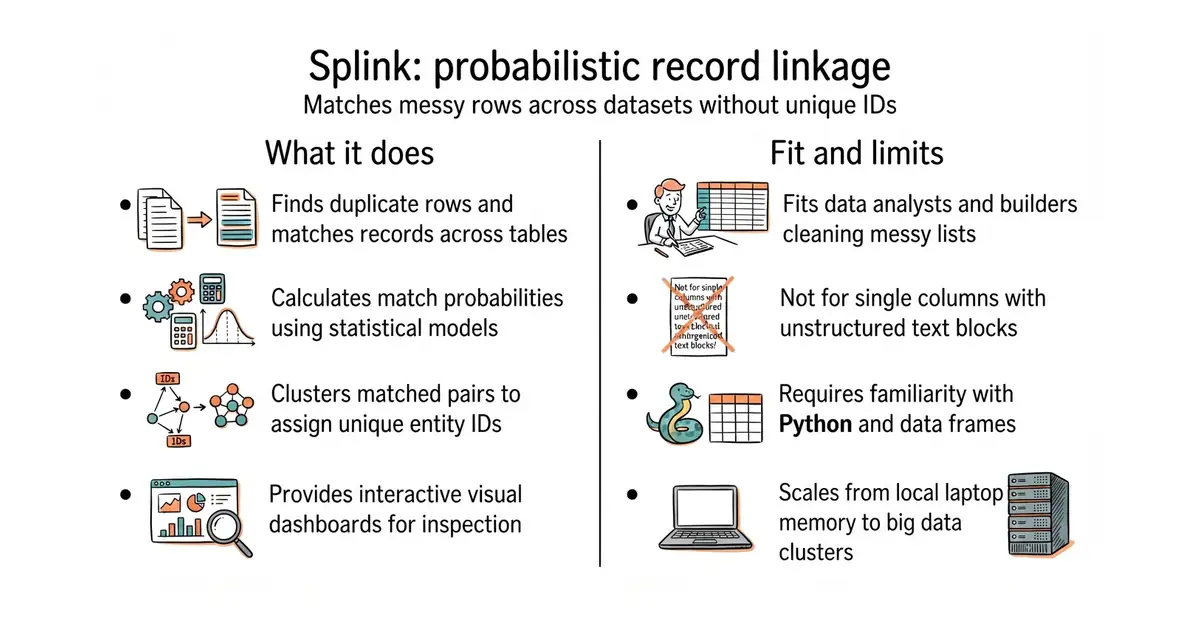
Real-world data is messy. Names are misspelled. Addresses change slightly. This Python tool compares messy lists and finds rows that refer to the same person or company. It works even when your data lacks a unique ID number. It does not cost money, but you need some Python programming skills to run it.
What it is
Splink is a Python package for probabilistic record linkage and entity resolution. It runs locally using DuckDB (an in-memory database designed for fast analysis) or scales to handle hundreds of millions of records using Spark.
What it is good for
Solo builders and data analysts cleaning up duplicate customer lists, merging user databases, or matching records from different sources where names and dates have typos.
- Runs quickly on a standard laptop for datasets up to a million rows.
- Includes interactive web dashboards to inspect match quality and tune settings.
- Works without needing pre-labelled training data.
- Requires comfort with Python scripting and data frames.
- Performance drops if all columns in your dataset are strongly correlated.
- Handling massive datasets requires setting up an external Spark cluster.
manual data cleaning in spreadsheets
pandas
- dedupeio/dedupe4.5k stars
A Python library for accurate record deduplication using active learning, though less focused on massive SQL backends than Splink.

- dbeaver/dbeaver52k stars
A free desktop program that connects to more than a hundred kinds of database and lets you browse and edit them.
- dimitri/pgloader6.5k stars
Loads data into PostgreSQL from other databases and from files, keeping going when individual rows fail.
pip install splink