Overview
Summary
The useful answer before the supporting detail.
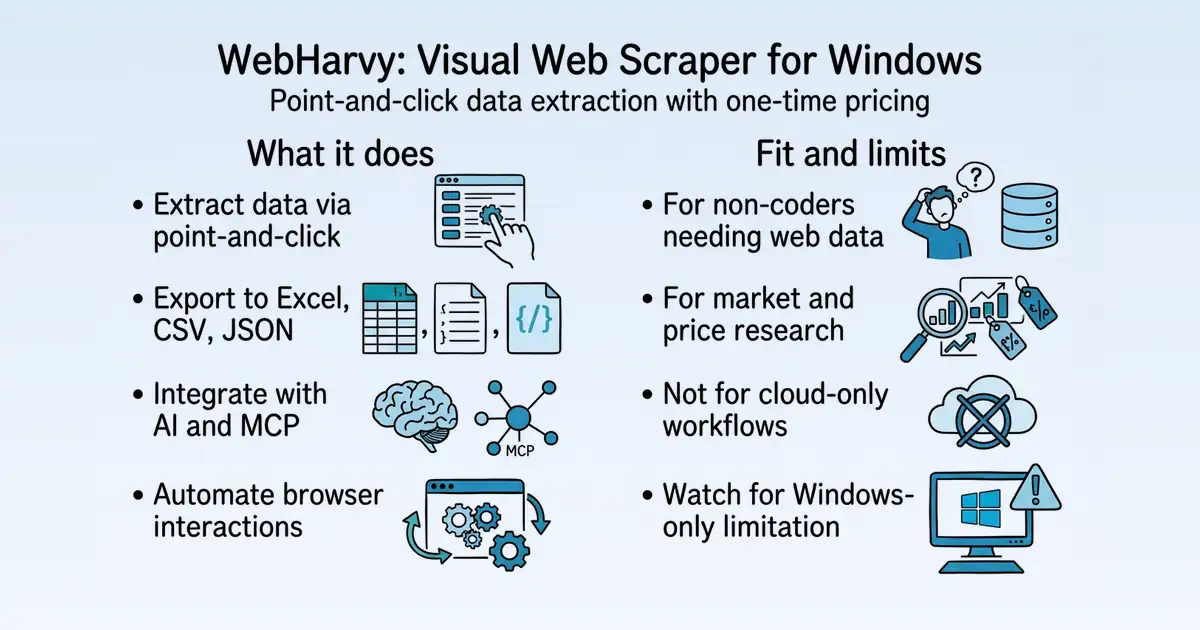
WebHarvy is a visual web scraping software for Windows that allows users to extract data from websites through a point-and-click interface S5. It is used by individuals and businesses to collect structured data for market research, price monitoring, and lead generation, solving the problem of manual data collection S5 S100. Its main practical value is its one-time purchase model with no recurring charges, making it a cost-effective alternative to subscription-based scrapers S5 S92.
Product identity and positioning
Name, category, positioning, audience, and first-party claims.
- Identity: WebHarvy is a visual web scraping software for Windows S5.
- Core purpose: It enables users to extract data from websites without coding, using a point-and-click interface S5.
- Intended users: It targets individuals and businesses needing web data for research, price monitoring, and lead generation S5 S100.
- Product scope: It is a desktop application, not a platform, with features for scraping, exporting, and AI integration S5.
- Positioning: The vendor emphasizes a one-time payment model, contrasting with subscription-based cloud scrapers S5 S92.
- Claimed distinction: It claims to handle Cloudflare-protected sites by simulating a genuine user session S5.
Use cases and audiences
Who the product serves and the jobs it is designed to handle.
| Audience | Practical use case |
|---|---|
| Market researchers | Extract product data from e-commerce sites for price comparison and trend analysis S92 S100. |
| E-commerce sellers | Scrape competitor listings for pricing and product details to inform dropshipping and inventory decisions S100. |
| Real estate professionals | Scrape property price history from sites like Zillow for market analysis S83. |
| Lead generation teams | Build B2B contact lists from directories and business listing sites S5. |
| Retail analysts | Monitor product data from major retailers like Walmart and Home Depot for competitive intelligence S92 S103. |
Traffic and search
SEO analysis
Collected Oct 22, 2026webharvy.com: an estimated 12,791 total monthly visits and about 206 monthly organic visits across 237 ranking keywords. Scout crawled 15 pages and measured a technical health score of 99/100.
Search summary
The useful answer before the supporting detail.
Easily scrape data from any website with a point-and-click user interface. No coding required. webharvy.com: an estimated 12,791 total monthly visits and about 206 monthly organic visits across 237 ranking keywords. Scout crawled 15 pages and measured a technical health score of 99/100.
- Total traffic (modeled): 12,791 monthly visits across all channels.
- Organic search traffic (estimated): 206 monthly visits from search.
- Strongest sampled ranking: webharvy at position 1.
- Leading page in the collected evidence: https://www.webharvy.com/.
- Closest measured organic competitor: reddit.com, appearing 2 times in the sampled first-page SERPs.
- Technical crawl: 15 pages, health score 99/100.
Website intelligence — Collected evidence
Company identity and positioning
| Page type | Evidence | Source |
|---|---|---|
| other | Easily scrape data from any website with a point-and-click user interface. No coding required. Supports cloud or local AI providers / LLMs. | https://www.webharvy.com/ |
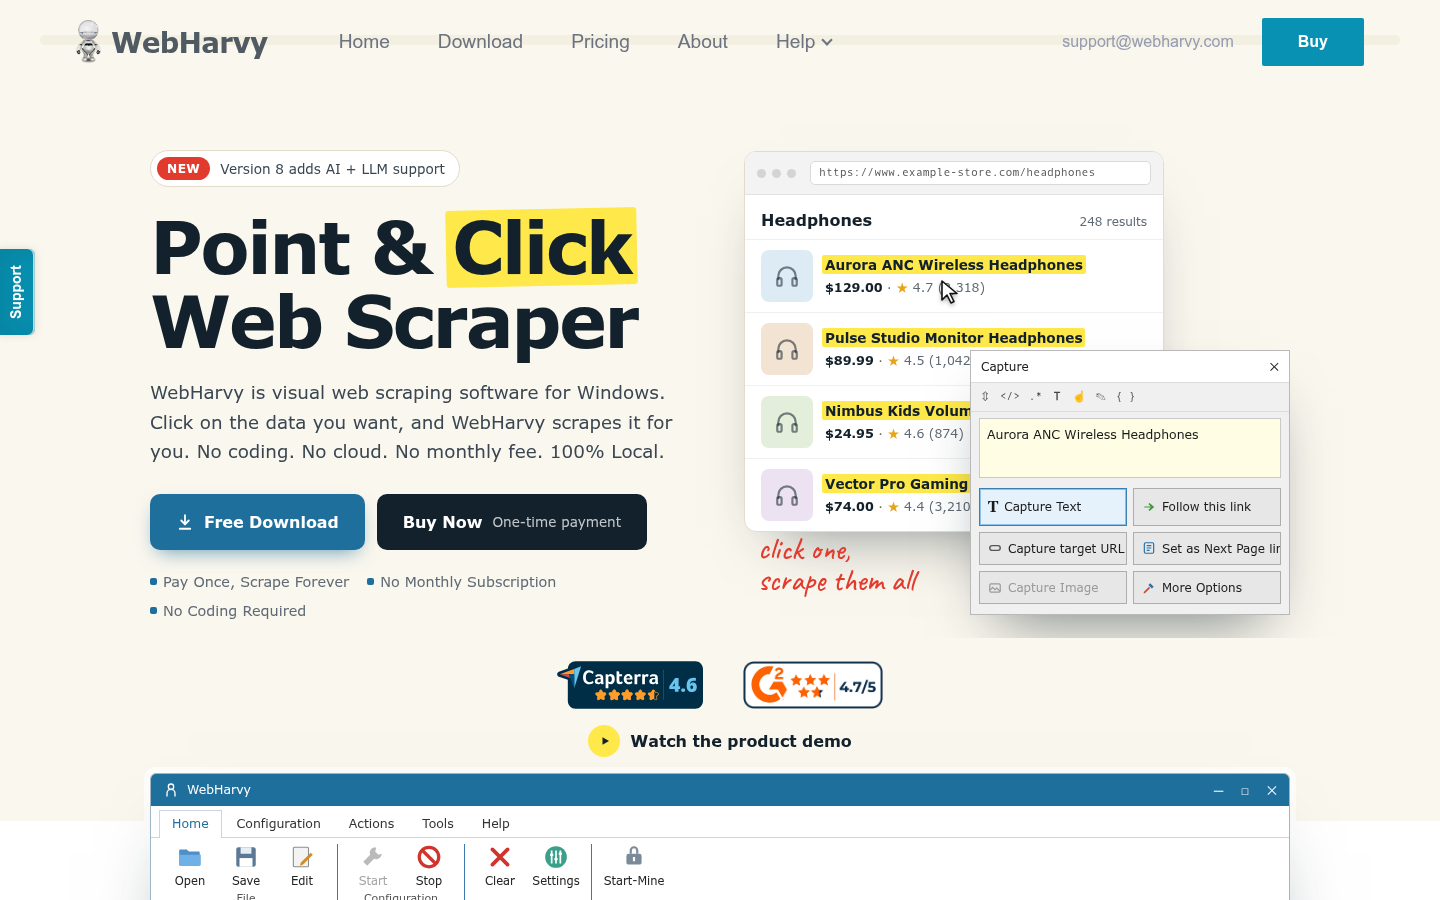
| other | WebHarvy is visual web scraping software for Windows. Click on the data you want, and WebHarvy scrapes it for you. No coding. No cloud. No monthly fee. 100% Local. | https://www.webharvy.com/ |
| other | JavaScript \[ON\] Proxy \[OFF\] Timeout \[PageLoad: 30s AJAX 5s\] Miner Options \[10,2\] Help for www.example-store.com | https://www.webharvy.com/ |
| other | Load any website in WebHarvy's built-in browser. Log in, search and filter just as you would in Chrome, then press `Start` to begin a configuration. | https://www.webharvy.com/ |
| other | Extra columns for free. Add the page URL, a page screenshot, the date and time, or fixed text to every row. | https://www.webharvy.com/ |
| other | Give WebHarvy a list of keywords, and it fills in search forms and scrapes the results for each one automatically. Works with multiple input fields at once, so you can cover every keyword combination without lifting a finger. | https://www.webharvy.com/ |
| other | WebHarvy's browser simulates a genuine user session, so it gets through Cloudflare-protected sites where many headless scraping tools get blocked. For scraping at scale, you can also route requests through a proxy server, VPN, or rotating proxy list. | https://www.webharvy.com/ |
| other | Download images directly to your computer, or just scrape the image URLs if that's all you need. Works for pages with multiple images per item, like product galleries, listings, or profile pages. | https://www.webharvy.com/ |
| other | Deploy WebHarvy on AWS, Azure, or any cloud platform that supports Windows virtual machines with Remote Desktop. Keep your scraping tasks running 24/7, without tying up your own computer. | https://www.webharvy.com/ |
| other | [Apply Regular Expressions](articles/regex.html) to a page's text or HTML source when a simple click isn't precise enough. [Inject custom JavaScript](docs/selecting-data.html#RunScript) to click hidden elements, modify the DOM, or trigger functions built into the site, before scraping begins. | https://www.webharvy.com/ |
| other | Use AI where it helps: to drive WebHarvy in plain English, or to read the text you scrape and turn it into clean columns. | https://www.webharvy.com/ |
| other | WebHarvy exposes an MCP server, so you can connect it to Claude Desktop and other MCP-compatible tools. Just describe what you want to scrape in plain language, and let the AI drive WebHarvy's browser for you. [Learn more](./mcp-server.html) | https://www.webharvy.com/ |
Website intelligence — Scout synthesis
WebHarvy is a visual web scraping software for Windows, positioned as a one-time-payment, local, no-coding tool W2. The homepage emphasizes a free download and a one-time purchase model W3. Version 8 adds AI and LLM support W1, and the documentation details AI integration with local and cloud LLMs, plus MCP server support for AI assistants like Claude Desktop W210W211. The site includes a blog with feature announcements and use-case tutorials, and a user guide covering configuration, pagination, data export, scheduling, and more W25W73W120W163W169W184W208. Evidence supports a mature product with a strong documentation and tutorial ecosystem.
Domain performance
Modeled total traffic, six-month trend, engagement, countries, and domain identity.
Total website traffic
| Month | Modeled visits |
|---|---|
| 2026-04 | 17,714 |
| 2026-05 | 19,420 |
| 2026-06 | 21,810 |
| 2026-07 | 24,998 |
| 2026-08 | 16,152 |
| 2026-09 | 12,791 |
Top visitor countries
| Country | Name | Traffic share |
|---|---|---|
| US | United States | 19.7% |
| BR | Brazil | 9.8% |
| PK | Pakistan | 7.9% |
| ID | Indonesia | 7.6% |
| NG | Nigeria | 7.1% |
Domain identity
| Signal | Value |
|---|---|
| Registered | Nov 5, 2010 |
| Last changed | Dec 1, 2023 |
| Expires | Nov 5, 2027 |
| WHOIS server | whois.verisign-grs.com |
| DNSSEC | Not signed |
| Nameservers | NS53.DOMAINCONTROL.COM, NS54.DOMAINCONTROL.COM |
Website capture
Organic keywords
Top keywords and an independent Google result page.
Top organic keywords
| Keyword | Volume | CPC | Estimated value |
|---|---|---|---|
| webharvy | 890 | $8.18 | $920 |
| webharvy disable auto updates | 170 | $0.00 | $200 |
| scraping hevy web site | 520 | $0.00 | $160 |
| webharvy 2025 manual pdf | 170 | $0.00 | $160 |
| webharvy training manual pdf | 150 | $0.00 | $140 |
Independent Google result page
Query: webharvy
| Position | Title | URL | Description |
|---|---|---|---|
| 1 | WebHarvy - Visual Web Scraper. Pay Once, Scrape Forever. | https://www.webharvy.com/ | An easy-to-use web scraping tool. WebHarvy can scrape data from any website, handle login, form submission, navigation, pagination, categories & keywords. |
| 2 | Easy Web Scraping using WebHarvy | https://www.sysnucleus.com/webharvy.html | WebHarvy is a visual web scraping software, which helps you to easily create web scrapers for any website via a visual interface. |
| 3 | WebHarvy Web Scraper for Windows | https://download.cnet.com/webharvy-web-scraper/3000-2381_4-75330408.html | WebHarvy is an intelligent web scraper that simplifies data extraction from web pages. It allows users to easily select and capture data, saving ... |
| 4 | Scrape the Web Without Coding! | WebHarvy Step-by-Step Guide | https://www.youtube.com/watch?v=bWljYHfTBq8 | ... WebHarvy tutorial, I'll show you how to scrape websites effortlessly—no programming skills required. Whether you're a researcher, marketer ... |
| 5 | WebHarvy Alternative 2026 – Best Replacement | https://www.scraperapi.com/comparisons/webharvy-alternative/ | Looking for a WebHarvy alternative? ScraperAPI gets you advanced JS rendering, CAPTCHA management, worldwide geotargeting, and IP rotation. |
| 6 | [Part 1] WebHarvy Tutorial : Introduction : How to easily scrape ... | https://www.youtube.com/watch?v=AY1OmghoJ5w | WebHarvy is a very simple, intuitive yet powerful web scraper. we see how WebHarvy can be configured to scrape basic details like name, address ... |
| 7 | WebHarvy Web Scraper Review: Capabilities & Alternatives | https://data-ox.com/resources/blog/webharvy-web-scraper-review/ | WebHarvy tool is an easy-to use and intuitive scraper, which can automatically parse text information, emails, URL's, and images from all kinds ... |
Important pages
Pages earning the most estimated search traffic in the sample.
Website intelligence — Collected evidence
Prioritized website intelligence pages
| Type | Page | Words | Change | URL |
|---|---|---|---|---|
| other | WebHarvy - Visual Web Scraper. Pay Once, Scrape Forever. | 2,504 | new | https://www.webharvy.com/ |
| features | Scrape Target.com Product Data & Images – WebHarvy Blog | 1,192 | new | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | WebHarvy Feature – WebHarvy Blog | 1,237 | new | https://www.webharvy.com/blog/category/webharvy-feature/ |
| integrations | Editing Scraper Configuration \ | playwright | 727 | new |
| integrations | How to Scrape Data by Following Links \ | playwright | 477 | new |
| integrations | Scraping Data from Multiple Pages \ | playwright | 1,328 | new |
| integrations | How to Register? \ | playwright | 385 | new |
| integrations | Saving Scraper Configuration \ | static | 104 | new |
| integrations | Export Scraped Data \ | static | 349 | new |
| integrations | Scheduler & Command line options \ | static | 460 | new |
| integrations | Web Scraping Using AI \ | static | 1,174 | new |
| integrations | Scrape Data from Multiple Categories \ | static | 580 | new |
| integrations | Scraping Data \ | static | 129 | new |
Features
| Page type | Evidence | Source |
|---|---|---|
| features | [Skip to content](#content "Skip to content") | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | 0 | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | WebHarvy Blog | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | Web Scraping Made Easy | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | Scrape Target.com Product Data & Images | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | May 8, 2026 by [Sreejith Sreekumar](https://www.webharvy.com/blog/author/webharvy-editor/ "View all posts by Sreejith Sreekumar") | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | Target is one of the largest retail chains in the United States, where customers can shop a wide range of products including electronics, clothing, groceries, home essentials, beauty products, toys, and more. Target.com is the online eCommerce website of Target. In this article you will learn how to scrape product data from Target.com using WebHarvy. | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | Product details including name, price, reviews, rating, images, specifications, product description etc. can be easily scraped from Target.com using WebHarvy. WebHarvy is a generic web scraping software which can scrape data from any website including eCommerce websites of Amazon, Walmart, Target, BestBuy etc. | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | Install WebHarvy | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | WebHarvy is a desktop application which can be locally installed in your computer. You may download and install the free trial version of WebHarvy. | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | WebHarvy allows you to select the data which you need to scrape from a webpage by just clicking over them. It is one of the easiest web scrapers to use. Being a desktop application, there is no need to even create an account. Just download, install and scrape – you should be able to scrape data within 2 minutes of installing the software. | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | The following video shows how WebHarvy can be used to scrape data from Target.com product listings. | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | As shown in the above video, scraping data from Target.com is very easy using WebHarvy. The entire workflow is designed for ease of use. | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | Step-by-Step Guide | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | After downloading and installing the free trial version of WebHarvy in your computer, please follow the steps explained below (as shown in the video above) to scrape product data from Target.com | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | Starting Configuration | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | Load the page from which you need to scrape data within WebHarvy’s browser. | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | Click on the Start button in main menu to start configuration. Once in configuration mode, you can click and select the data which you need to scrape. | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | Ref: Loading Page and Starting Configuration | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
| features | Selecting Data | https://www.webharvy.com/blog/scrape-target-product-data-images/ |
Pricing and plans
No supporting public-page evidence was collected for this category.
Integrations and supported platforms
| Page type | Evidence | Source |
|---|---|---|
| integrations | WebHarvy | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | support@webharvy.com [Buy](buy.html) | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | [WebHarvy user guide](starting-configuration.html) | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | Editing Configuration | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | [1\. Editing Configuration](#EditConfig) | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | [2\. Add / Delete data](#AddDeleteData) | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | [3\. Add / Remove URLs from Configuration](#AddURLsManually) | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | [4\. Edit Keywords](#EditKeywords) | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | [5\. Edit Start URL, PostData, Headers](#EditStartURL) | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | [6\. Manually editing the configuration XML file](../articles/xml-config-format.html) | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | [7\. Disable auto pattern detection in start page](#DisablePatterns) | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | How to edit configuration ? | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | To edit an already saved configuration, open the configuration XML file by clicking the Open button in Home menu. | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | WebHarvy will then ask you whether to start mining using the configuration or edit it. Click the Edit configuration button. | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | You may also click the Edit button in Home menu to start editing a loaded configuration. | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | When the Edit button is clicked, WebHarvy will start loading the configuration. The starting page of the configuration will be loaded and displayed in the browser window. The preview of data selected for scraping will also be displayed. After this, WebHarvy automatically switches to configuration mode and you can start selecting more data to be scraped or delete existing data selections. You may also edit [URLs](#AddURLsManually) and [keywords](#EditKeywords) associated with the configuration. | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | Add / Delete data | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | To select new data just click on it. To delete already selected data, right click in the 'Captured Data Preview' pane and select the data to be removed from the 'Delete' menu as shown below. | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | Once you have finished editing the configuration, click the Stop button within Configuration panel of Home menu. You may now save the configuration by clicking the Save button or run the configuration by clicking the Start-Mine button. | https://www.webharvy.com/docs/editing-configuration.html |
| integrations | Add / Remove URLs from Configuration | https://www.webharvy.com/docs/editing-configuration.html |
Product and company updates
No supporting public-page evidence was collected for this category.
Website intelligence — Scout synthesis
Key pages identified from the catalog:
- Homepage: `https://www.webharvy.com/` – primary landing page with product pitch, demo, and download CTA W1W2W3W14
- Blog: `https://www.webharvy.com/blog/` – hosts feature announcements and tutorials W25W49
- User Guide: `https://www.webharvy.com/docs/` – documentation hub with pages for configuration, pagination, AI, export, scheduler, etc. W73W120W208W169W184
- Download page: `https://www.webharvy.com/download.html` – referenced for free trial W3W32W36
- Buy page: `https://www.webharvy.com/buy.html` – referenced for one-time purchase W3W149
Rank tracking
Persistent keyword baselines and position movement.
This analysis created the first position baseline at 2026-10-22T09:14:12.189Z. Movement appears after the next fresh analysis using the same location and language.
Website intelligence — Scout synthesis
No evidence in the catalog supports rank tracking or keyword position data. W1–W240 contain no rank tracking information.
Features
Features and capabilities
Core functions and evidence-backed product capabilities.
| Capability | What it does |
|---|---|
| Visual point-and-click scraping | Users select data elements by clicking on them in the built-in browser, with no coding required S5 S118. |
| Export to multiple formats | Scraped data can be saved to Excel, CSV, JSON, XML, or TSV files, or directly to databases like MySQL, SQL Server, or Oracle S5. |
| AI/LLM integration | Connects to local or cloud LLMs (OpenAI, Anthropic, AI model, Ollama, LM Studio) for summarization, sentiment analysis, and data transformation S5. |
| MCP server support | Exposes an MCP server, allowing AI assistants like AI modelDesktop to drive WebHarvy's browser via plain English S5. |
| Automated browser interactions | Handles login, form submission, navigation, pagination, and keyword-based search form submissions S5. |
| Regular expressions | Users can apply regex to page text or HTML for precise data extraction S5 S118. |
| Image scraping | Downloads images directly or scrapes image URLs S5. |
| Cloud deployment | Can be deployed on AWS, Azure, or any cloud platform supporting Windows VMs with Remote Desktop S5. |
Integrations and ecosystem
Connected products, exports, APIs, and workflow compatibility.
| Integration or interface | Type | What it enables |
|---|---|---|
| MCP server | AI interface | Allows MCP-compatible tools like AI modelDesktop to drive WebHarvy's browser via plain English S5. |
| OpenAI, Anthropic, AI model | AI integration | Connects to cloud LLMs for data extraction, summarization, and sentiment analysis S5. |
| Ollama, LM Studio | AI integration | Connects to local LLMs for on-premise data processing S5. |
| Excel, CSV, JSON, XML, TSV | Data export | Saves scraped data to common file formats S5. |
| MySQL, SQL Server, Oracle | Database export | Writes scraped data directly to SQL databases S5. |
| AWS, Azure | Cloud deployment | Allows running WebHarvy on cloud Windows VMs S5. |
Pricing
Pricing and plans
Published plans, free access, trials, credits, and pricing limitations.
| Plan or offer | Verified price and billing | Included | Limits |
|---|---|---|---|
| Single User Licence | $99 one-time S83 | 1 year of updates and email support S83 | Up to 3 computers, one at a time S83 |
| 2 User Licence | $169 one-time S83 | 1 year of updates and email support S83 | 2 users S83 |
| Site Licence | $699 one-time S83 | 1 year of updates and support S83 | Unlimited computers and users S83 |
| Free trial | Free for 15 days S83 | Full features during trial S83 | Not established |
Competition
Competitive landscape
Domains competing for the same organic search demand.
Sampled competitors
| Competitor | First-page appearances | Sampled queries | Average position | Queries observed |
|---|---|---|---|---|
| reddit.com | 2 | 2 | 4 | webharvy, heavy web |
| scraperapi.com | 1 | 1 | 1 | webharvy |
| facebook.com | 1 | 1 | 2 | webharvy |
| uptrends.com | 1 | 1 | 2 | heavy web |
| herman.bearblog.dev | 1 | 1 | 3 | heavy web |
| help.hcss.com | 1 | 1 | 4 | heavy web |
| en.wikipedia.org | 1 | 1 | 5 | heavy web |
| marrplugs.squarespace.com | 1 | 1 | 6 | heavy web |
| clickrank.ai | 1 | 1 | 7 | heavy web |
| cssauthor.com | 1 | 1 | 8 | heavy web |
Website intelligence — Collected evidence
Customers, testimonials, and first-party review claims
No supporting public-page evidence was collected for this category.
Independent review sources discovered
No links to supported independent review platforms were discovered on the collected pages.
Website intelligence — Scout synthesis
No direct competitor comparisons are present in the catalog. The homepage positions WebHarvy against generic web scrapers by highlighting its visual, no-code, local, one-time-payment approach W2. The blog mentions it can scrape from Amazon, Walmart, Target, BestBuy, etc., implying broad eCommerce applicability W31.
Backlink profile
Authority and referring-domain signals.
Backlink comparison profile
- Domain rating: 41/100
- Backlinks: 4,842
- Referring domains: 2,179
- Dofollow backlinks: 43.0%
- Dofollow referring domains: 42.0%
Collection decision
The Scout search index remains intentionally excluded from automatic Scout analysis. This Scout traffic model profile costs 5 credits (0.5 cents) and is included in the first comparison run so its usefulness can be judged before the recurring collection is finalized.
Website intelligence — Scout synthesis
No evidence in the catalog supports backlink profile or link-building data. W1–W240 contain no backlink metrics.
AI visibility
Measured ChatGPT and Google AI mentions with cited sources.
AI-assistant referral traffic
- Estimated current generative-AI referral share: 1.5%
Scout traffic model did not return a separate AI-referral trend series for this domain.
Website intelligence — Collected evidence
Site-stated AI capabilities
| Page type | Evidence | Source |
|---|---|---|
| other | Easily scrape data from any website with a point-and-click user interface. No coding required. Supports cloud or local AI providers / LLMs. | https://www.webharvy.com/ |
| other | Use AI where it helps: to drive WebHarvy in plain English, or to read the text you scrape and turn it into clean columns. | https://www.webharvy.com/ |
| other | WebHarvy exposes an MCP server, so you can connect it to Claude Desktop and other MCP-compatible tools. Just describe what you want to scrape in plain language, and let the AI drive WebHarvy's browser for you. [Learn more](./mcp-server.html) | https://www.webharvy.com/ |
| features | WebHarvy 8.0 features built-in AI support, an intelligent troubleshooting wizard, and many other enhancements. | https://www.webharvy.com/blog/category/webharvy-feature/ |
| features | Version 8.0.1.252 – WebHarvy with AI | https://www.webharvy.com/blog/category/webharvy-feature/ |
| features | WebHarvy 8.0 features built-in AI support, an intelligent troubleshooting wizard, and many other enhancements. | https://www.webharvy.com/blog/category/webharvy-feature/ |
These are first-party product claims, not independent measurements of AI-search visibility.
Website intelligence — Scout synthesis
WebHarvy has significant AI-related content:
- Version 8 adds AI + LLM support W1
- Blog post: 'Version 8.0.1.252 – WebHarvy with AI' W52W54
- Dedicated documentation page: 'Web Scraping Using AI' W208
- Supports AI for summarization, sentiment analysis, and data extraction W230W231
- Can run as an MCP server for AI assistants like Claude Desktop W211W219
- Connects to local LLMs (Ollama, LM Studio) and cloud LLMs (OpenAI, Anthropic) W226W227
Marketing opportunities
Actions calculated directly from the collected evidence.
| Opportunity | Recommended action | Evidence |
|---|---|---|
| Striking-distance keyword | Move “heavy web” from position 4 toward the top three. | Volume 90 · https://www.webharvy.com/ |
| Important page | Strengthen the page already earning search visibility before creating an unrelated page. | https://www.webharvy.com/free-email-extractor.html · 4 sampled keywords · best position 7 |
| Competitor gap | Review the sampled queries where reddit.com appears. | 2 first-page appearances across webharvy, heavy web |
Website intelligence — Collected evidence
Website evidence gaps
- pricing: no usable public page was collected; verify whether the site publishes this evidence.
- customers: no usable public page was collected; verify whether the site publishes this evidence.
- reviews: no usable public page was collected; verify whether the site publishes this evidence.
- changes: no usable public page was collected; verify whether the site publishes this evidence.
- identity: no usable public page was collected; verify whether the site publishes this evidence.
- technical: no usable public page was collected; verify whether the site publishes this evidence.
Website intelligence — Scout synthesis
Marketing opportunities evident from the catalog:
- Emphasize the 'pay once, scrape forever' pricing model, a differentiator from subscription-based competitors W2W3
- Highlight the no-coding, visual point-and-click interface for ease of use W2W33
- Promote the 100% local processing and no cloud requirement for privacy-conscious users W2
- Leverage AI capabilities (LLM integration, MCP server) to attract tech-savvy users W210W211
- Showcase use-case tutorials for popular eCommerce sites like Target, Amazon, Walmart, BestBuy W31
- Feature the free trial download to lower entry barriers W3W32
- Use blog posts to announce new features and updates, keeping the product top-of-mind W52W55W58W61W64W67
Trust and proof
Customers, proof, and reviews
Published proof, customer signals, and review evidence.
Independent reviews
| Platform | Page | How it was found | Note |
|---|---|---|---|
| Capterra | WebHarvy Pricing, Cost & Reviews - Capterra UK 2026 | Grounded web search | ### Overall rating Based on 74 reviews 4.6 ... ### Reviews sentiment Positive 91% Neutral 7% Negative 3% ... With such an advanced feature set, it is often not obvious how a feature works. The documentation is okay and there is a healthy community of active users willing to help (and even some YouTube How-To videos) but I've had to invest a lot of effort into learning to use the product properly. Suggest a guided tutorial from start-to-finish highlighting the features. Individual FAQs are docume |
| Thunderbit | In-depth WebHarvy Review: What You Need to Know | Grounded web search | To get a true sense of how WebHarvy performs in the real world, I dug into reviews on Capterra, G2, and user forums. Here’s what I found: ... ### Ratings at a Glance - Capterra: 4.6/5 stars (75+ reviews) - G2: 4.5/5 stars - Trustpilot: Not enough reviews to be meaningful (WebHarvy is B2B-focused) |
| Prospeo | WebHarvy Pricing, Reviews, Pros & Cons (2026) | Grounded web search | Speed and stability on large jobs is the most common frustration. Capterra reviewers describe spending "all night" collecting data, jobs stopping mid-run, and the blunt assessment that "unattended operation for big data is not possible." If you're planning to scrape thousands of pages overnight and wake up to a clean dataset, temper your expectations. ... Anti-bot protection is a dealbreaker for many sites. A Reddit user in r/webscraping reported that Cloudflare's checkbox challenge consistently |
| Which 50 | WebHarvy / Which 50 | Grounded web search | ### Ratings g2(4.6/5) capterra(4.6/5) ... for its intuitive GUI that simplifies scraping text, images, and URLs from ... . Some note a learning curve for advanced options and occasional challenges with complex pages requiring support intervention |
| Tekpon | WebHarvy Reviews for 2026 | Grounded web search | # WebHarvy Reviews for 2026 Visual Web Scraping Software Tekpon Score: 4.2/5 Score is based on User Sentiment from reviews and public chatter. We weight volume, recency, and consistency, then normalize to 5. |
| Subscribed.fyi | WebHarvy Reviews 2026: Details, Pricing, & Features / Subscribed.fyi | Grounded web search | ### No Reviews Yet! Be the first to share your experience and help others in the community. 5 4 3 2 Reviews from G2, Capterra, Trustpilot 4.5 (7) 4.5 (7 Reviews) G2 Review 4.6 (72) 4.6 (72 Reviews) Capterra Review |
| Rankite | Best Data Scraping Tools for Web Automation in 2026: 7 Tools Compared | Grounded web search | ### WebHarvy Best for: Windows users who want to pay once and scrape forever 4.7/5 on G2 (10 reviews, checked Oct 2026) ... one-time purchase in a category that has moved almost entirely to subscriptions and usage billing |
| ProxyLook | WebHarvy Review 2026 — Pricing, Pros & Cons · ProxyLook | Grounded web search | No reader reviews yet — be the first below. 4.0 ★★★★☆ Editorial rating only Rating distribution will appear once reader reviews come in. ... you've used this provider, share your experience using the form below — we publish moderated reviews within |
Customer proof
| Proof type | Named customer or source | Evidence |
|---|---|---|
| Testimonial | WebHarvy Official Site | testimonial — used WebHarvy for over 9 months to data mine weekly specials from Australia's 2 major supermarket chains covering 20 different regional areas and approx. (WebHarvy - Visual Web Scraper. Pay Once, Scrape Forever.) |
Independent mentions
- WebHarvy – Discover the software and services from companies across the world — has received positive user reviews, often praised for its ease of use and effectiveness in extracting data from ... 3. G2 Crowd: WebHarvy has been featured on G2 Crowd, where users have rated it favorably for its features and customer support.
External links were grounded in one live web search. Search snippets are leads, not independently scraped page content; rejected links remain available in Review evidence.
Company, security, and trust
Ownership, policies, security signals, and public trust evidence.
| Signal | Finding | Source |
|---|---|---|
| Company and ownership | Not published on the collected pages. | — |
| Contact and support | support@webharvy.com Buy | source |
| Legal and privacy | Scraping publicly available data is generally legal, but you should always review a website's terms of service and applicable laws before scraping it, and avoid collecting personal or copyrighted data without permission. | source |
| Security and compliance | Not published on the collected pages. | — |
| Uptime and status page | Not published on the collected pages. | — |
| Domain registered | 2010-11-05 | — |
| Domain expires | 2027-11-05 | — |
Not found on the collected pages: company and ownership, security and compliance, uptime and status page. This only means Scout did not find it on the pages it read; it says nothing about the company itself.
Documentation and product updates
Help resources, product guidance, and visible changes over time.
| Resource or update | Type | What is available | Date or freshness |
|---|---|---|---|
| Product FAQ | FAQ | Answers common product, workflow, pricing, privacy, ownership, API, and team questions. (source) | Not dated |
| How to Register? / WebHarvy User Guide | Guide | Learn how to unlock and register the trial version using your license key file (source) | Not dated |
| Scrape Price History of Properties from Zillow | Guide | Explains how price history of properties listed on Zillow can be scraped using WebHarvy. (source) | Not dated |
| How to scrape data from eBay product listings ? (price, images, specification, seller description etc.) – WebHarvy Blog | Guide | Public tutorials and product guidance. (source) | Not dated |
| How to scrape Amazon product data using WebHarvy? | Guide | Guides, comparisons, pricing breakdowns, use cases, and how-to articles. (source) | Not dated |
| How to Scrape Conrad.de Product Data using WebHarvy – WebHarvy Blog | Guide | Public tutorials and product guidance. (source) | Not dated |
| Scrape eBay Product Data to Excel / 2026 Guide – WebHarvy Blog | Guide | Public tutorials and product guidance. (source) | Not dated |
| Scrape Home Depot Product Data (2026 Guide) – WebHarvy Blog | Guide | Public tutorials and product guidance. (source) | Not dated |
Not found in the collected public sources: public roadmap, changelog or release notes, status page, separate help center or knowledge base.
Technical
Technical and delivery signals
Delivery model, platforms, API, data ownership, reliability claims and release activity.
| Signal | Finding | Source |
|---|---|---|
| Delivery model (cloud, self-hosted, desktop, browser extension) | WebHarvy is a desktop application installed locally on Windows S5 S103. | S5 S103 |
| Platforms and apps | Runs on Windows S5. | S5 |
| API and extensibility (API, SDK, webhooks, MCP, plugins) | Exposes an MCP server for AI integration S5. | S5 |
| Data ownership and export | Data can be exported to files or databases, with no lock-in S5. | S5 |
| Performance and reliability claims | Claims to handle Cloudflare-protected sites by simulating a genuine user session S5. | S5 |
| Release activity | Version 8 added AI + LLM support S5. | S5 |
Measured infrastructure
Domain, certificate, and hosting signals, measured directly.
| Signal | Finding |
|---|---|
| Domain registered | 2010-11-05 — GoDaddy.com, LLC |
| Domain expires | 2027-11-05 |
| TLS certificate | Let's Encrypt, valid, expires 2026-12-28 |
| Security headers | none served |
| Headers not served | HSTS, CSP, X-Content-Type-Options, X-Frame-Options, Referrer-Policy |
| Server header | nginx |
| Mail handled by | mx.zoho.in, mx2.zoho.in |
| Nameservers | ns54.domaincontrol.com, ns53.domaincontrol.com |
Not measurable: wayback: rate limited by archive.org, ladder stopped after 1 probe(s); rdap: exceeded the overall budget; wayback: exceeded the overall budget; tls: exceeded the overall budget; dns: exceeded the overall budget; headers: exceeded the overall budget. A gap here means the lookup was unavailable, not that the finding is negative.
Technical site audit
A bounded multi-page crawl with page-level issues and URLs.
Scout — Bounded technical crawl
- Pages crawled: 15 of 15 maximum
- Technical health: 99/100
- Critical issues: 0
- Warnings: 2
- Notices: 4
Issues
| Severity | Issue | Value | Affected URL |
|---|---|---|---|
| notice | Meta description length should be reviewed | 171 | https://www.webharvy.com/articles/scraping_with_local_llms.html |
| warning | Title length should be reviewed | 68 | https://www.webharvy.com/buy.html |
| notice | Meta description length should be reviewed | 19 | https://www.webharvy.com/demo/demo.html |
| notice | Low visible word count | 93 | https://www.webharvy.com/demo/demo.html |
| warning | Missing meta description | — | https://www.webharvy.com/blog/run-webharvy-on-aws-ec2/ |
| notice | Meta description length should be reviewed | 30 | https://www.webharvy.com/mcp-server.html |
Crawled pages
| Status | Title | H1s | Words | Response | URL |
|---|---|---|---|---|---|
| 200 | WebHarvy - Visual Web Scraper. Pay Once, Scrape Forever. | 1 | 2408 | 269 ms | https://www.webharvy.com/ |
| 200 | Web Scraping with Local LLMs using Ollama, LM Studio and WebHarvy | 1 | 2055 | 73 ms | https://www.webharvy.com/articles/scraping_with_local_llms.html |
| 200 | Download WebHarvy Web Scraper | 1 | 343 | 227 ms | https://www.webharvy.com/download.html |
| 200 | Purchase WebHarvy - One-Time Payment Web Scraper \ | Perpetual License | 1 | 818 | 208 ms |
| 200 | WebHarvy Video Demo | 1 | 93 | 204 ms | https://www.webharvy.com/demo/demo.html |
| 200 | Data Selection and Page Interaction \ | WebHarvy User Guide | 1 | 2241 | 84 ms |
| 200 | How to Scrape Data by Following Links \ | WebHarvy User Guide | 1 | 459 | 79 ms |
| 200 | Export Scraped Data \ | WebHarvy User Guide | 1 | 355 | 82 ms |
| 200 | Scraping Data from Multiple Pages \ | WebHarvy User Guide | 1 | 1296 | 79 ms |
| 200 | Keyword Based Scraping \ | WebHarvy User Guide | 1 | 657 | 79 ms |
| 200 | How to anonymously scrape data from websites using WebHarvy? | 1 | 555 | 78 ms | https://www.webharvy.com/articles/anonymous-web-scraping.html |
| 200 | Scrape Data from Multiple Categories \ | WebHarvy User Guide | 1 | 646 | 73 ms |
| 200 | How to run WebHarvy on AWS ? – WebHarvy Blog | 1 | 403 | 228 ms | https://www.webharvy.com/blog/run-webharvy-on-aws-ec2/ |
| 200 | Regular Expressions For Web Scraping | 1 | 956 | 85 ms | https://www.webharvy.com/articles/regex.html |
| 200 | MCP Web Scraping - WebHarvy Local Browser MCP Server | 1 | 933 | 83 ms | https://www.webharvy.com/mcp-server.html |
This is a bounded Scout crawl. Core Web Vitals and Lighthouse scores are not claimed unless a dedicated performance audit is connected.
Search Console and Analytics
First-party search and behavioral data connection state.
Modeled acquisition channels
| Channel | Estimated share |
|---|---|
| direct | 40.8% |
| search | 33.8% |
| search organic | 32.3% |
| search paid | 1.6% |
| social | 6.3% |
| social organic | 5.7% |
| social paid | 0.7% |
| referrals | 10.4% |
| paid referrals | 2.8% |
| 2.8% | |
| gen ai | 1.5% |
| affiliate | 1.5% |
| other | 0.0% |
First-party connections
| Integration | Status | Data available after connection |
|---|---|---|
| Google Search Console | Not connected | Clicks, impressions, CTR, average position, queries, pages, countries, and devices |
| Google Analytics | Not connected | Organic sessions, engagement, landing pages, conversions, geography, and devices |
No first-party Search Console or Analytics numbers are shown until the site owner authorizes the corresponding Google account. Scout traffic model values above are modeled estimates, not private analytics totals.
Website intelligence — Scout synthesis
No evidence in the catalog supports search console or analytics data. W1–W240 contain no analytics or search console information.
Limits and method
Limitations and open questions
Known constraints and missing evidence from the collected pages.
The collected pages do not mention specific competitors by name. Evidence gaps include lack of detailed pricing for 3- and 4-user licenses S83, no explicit security or compliance certifications, and no independent review ratings or customer counts beyond testimonials. Open questions include the exact number of activations per license and the specifics of the AI integration's data handling.
Sources, method, and limitations
Evidence inventory, collection method, provider use, and constraints.
This report is based on 15 collected pages from webharvy.com, including the homepage, documentation, and blog articles. The evidence catalog includes 180 items, with sources ranging from product pages to user guides. External proof search was enabled but did not verify any additional claims. Limitations include the absence of third-party review sites and the reliance on vendor-provided testimonials.
- Official Websitehttps://www.webharvy.com/Verified
- Documentationhttps://www.webharvy.com/docs/register.htmlVerified
- Pricing Pagehttps://www.webharvy.com/articles/zillow-scraping-pricing-history.htmlVerified
- Pricing Pagehttps://www.webharvy.com/blog/how-to-scrape-data-from-ebay-product-listings-price-images-specification-seller-description-etc/Verified
- Pricing Pagehttps://www.webharvy.com/blog/scraping-walmart-product-data-images-skus-and-pricing/Verified
- Pricing Pagehttps://www.webharvy.com/blog/how-to-scrape-data-from-ebay-product-listings-price-images-specification-seller-description-etc/feed/Verified
- Official Websitehttps://www.webharvy.com/articles/scraping-amazon-product-data.htmlVerified
- Official Websitehttps://www.webharvy.com/blog/aliexpress-scraper-scraping-product-data-including-images-from-aliexpress/Verified
- Official Websitehttps://www.webharvy.com/blog/how-to-scrape-conrad-de-product-data-using-webharvy/Verified
- Official Websitehttps://www.webharvy.com/blog/scrape-ebay-product-data-to-excel-guide/Verified
- Official Websitehttps://www.webharvy.com/blog/scrape-home-depot-product-data/Verified
- Official Websitehttps://www.webharvy.com/blog/scrape-shopee-product-data-shopee-scraper/Verified
- Official Websitehttps://www.webharvy.com/blog/scrape-target-product-data-images/Verified
- Official Websitehttps://www.webharvy.com/blog/scraping-bestbuy-product-data-without-coding/Verified
- Official Websitehttps://www.webharvy.com/blog/scraping-prices-and-images-from-product-listings/Verified
- Review Sitehttps://www.capterra.co.uk/software/146258/webharvyVerified
- Review Sitehttps://thunderbit.com/blog/webharvy-review-and-alternativeVerified
- Review Sitehttps://prospeo.io/s/webharvy-pricing-reviews-pros-and-consVerified
- Review Sitehttps://which-50.com/app/webharvy.com/Verified
- Review Sitehttps://tekpon.com/software/webharvy/reviews/Verified
- Review Sitehttps://subscribed.fyi/webharvy/reviews/Verified
- Review Sitehttps://rankite.com/blog/best-data-scraping-tools-for-web-automationVerified
- Review Sitehttps://proxylook.com/providers/webharvyVerified
- Articlehttps://techcos.co/software/webharvy/Verified