In simple English
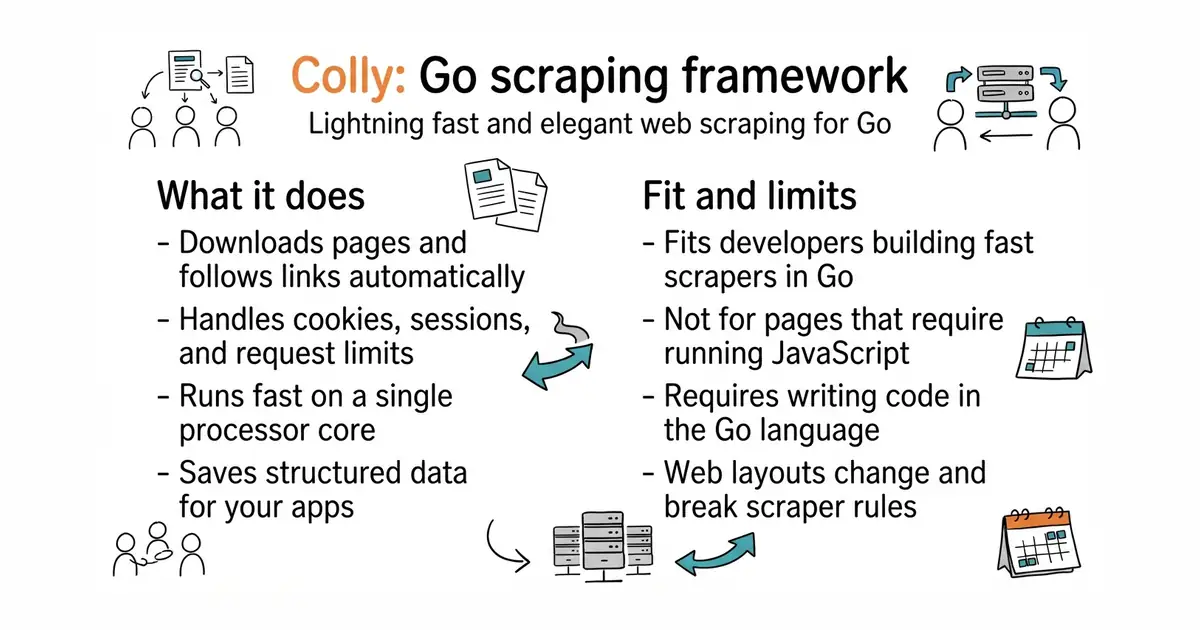
This tool downloads web pages and pulls out the text you need. It runs very fast on a single computer. You write small programs in Go (a programming language made by Google) to tell it what to collect. It handles cookies, limits requests so you do not crash websites, and saves data to disk. It costs nothing to use under an open source licence.
What it is
Colly is a web scraping framework for the Go programming language. It provides a clean set of functions to visit pages, follow links, and grab content.
What it is good for
Solo builders who need to gather data from websites, monitor prices, or build search indexes. It removes the need to write complex HTTP request logic and HTML parsing from scratch.
- Very fast execution, handling over one thousand requests per second on a single processor core.
- Built-in features for managing request delays and limits per domain to avoid getting blocked.
- Automatic handling of cookies, sessions, and character encoding.
- Requires writing code in Go, which means you need to know that language first.
- Does not execute JavaScript, so it cannot scrape pages that load content dynamically in the browser.
- Websites change their layouts often, requiring you to update your scraping rules over time.
Writing raw HTTP requests and HTML parsers from scratch in Go.
Go standard library
- PuerkitoBio/goquery15k stars
An HTML parsing library for Go that works like jQuery, often used alongside HTTP clients for scraping.
- chromedp/chromedp13k stars
A Go library for driving real web browsers, useful when you need to scrape pages that use JavaScript.


- cybertec-postgresql/pg_timetable1.4k stars
A job scheduler for PostgreSQL whose jobs and schedules live in the database itself.
- PrefectHQ/prefect24k stars
Adds scheduling, retries and a run history to Python functions you already have.
go get github.com/gocolly/colly/v2