In simple English
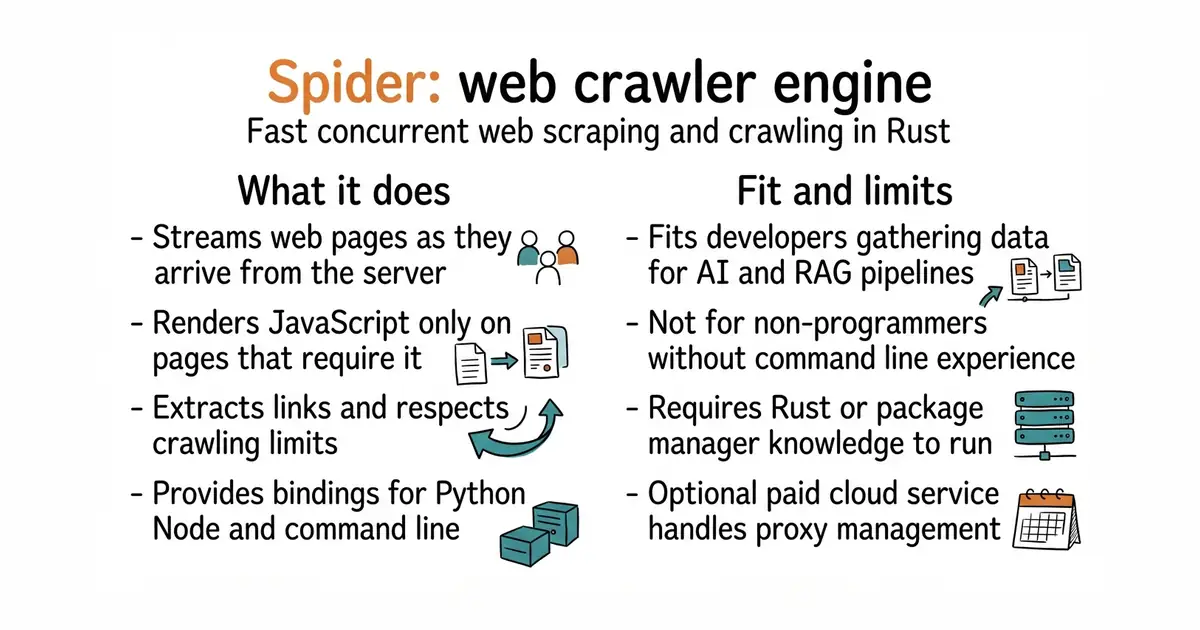
This tool downloads web pages automatically at high speed. It can fetch raw text or run a hidden web browser to read pages built with complex code. You can use it to gather training data for artificial intelligence or monitor websites for changes. It runs on your own computer for free, or through an optional paid cloud service. You need some programming knowledge to set it up.
What it is
Spider is a concurrent web crawling engine that streams pages as they arrive and handles JavaScript rendering only when needed. It is available as a Rust library, a command-line tool, a Python package, a Node.js package, and an MCP server.
What it is good for
Solo builders who need to scrape thousands of web pages quickly to feed data into artificial intelligence models or track competitor pricing.
- Streams pages as they download instead of waiting for the entire crawl to finish.
- Saves resources by using fast HTTP requests first and launching a browser only for pages that need JavaScript.
- Provides bindings for Python, Node.js, and a command-line interface alongside the core Rust library.
- Requires familiarity with programming and the command line to configure and run.
- Running headless Chrome for complex pages consumes significant memory and CPU.
- Managed cloud features require a paid subscription to Spider Cloud.
Writing custom web scrapers from scratch using basic HTTP libraries.
An LLM vector store or a local database for saving scraped content.
- psf/requests55k stars
Downloads web pages using Python, but lacks built-in crawling and JavaScript rendering.
- scrapy/scrapy65k stars
A popular web scraping framework for Python that handles large crawls with queues and pipelines.


- cybertec-postgresql/pg_timetable1.4k stars
A job scheduler for PostgreSQL whose jobs and schedules live in the database itself.
- PrefectHQ/prefect24k stars
Adds scheduling, retries and a run history to Python functions you already have.
cargo add spider