In simple English
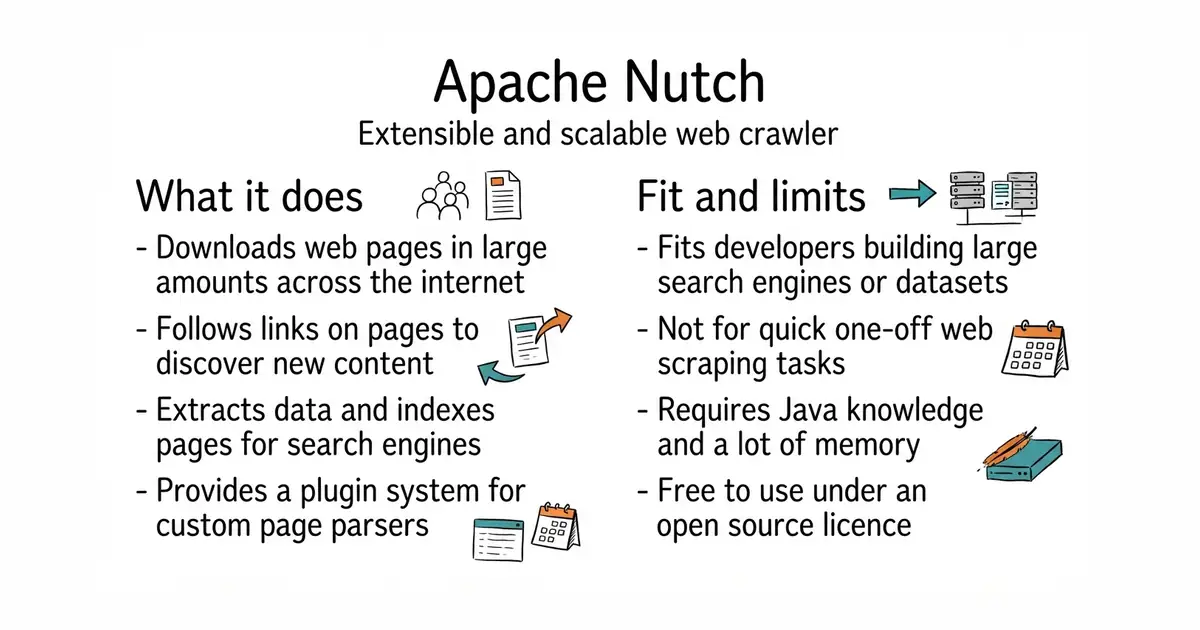
This tool downloads web pages from the internet in large amounts. It visits links on those pages to find more pages to read. You can use it to build your own search engine or gather research data. It is free to use under an open source licence. You need technical skills in Java (a programming language used to build large applications) to set it up and run it.
What it is
Apache Nutch is an open-source web crawler designed for scale and customisation. It reads lists of web addresses, fetches the pages, and extracts data or follows new links across the internet.
What it is good for
Solo builders and researchers who need to harvest millions of web pages for search indexes or datasets. It removes the need to write a web scraper from scratch.
- Scales to handle millions of web pages across many servers.
- Extensible plugin system lets you write custom page parsers.
- Free to use under the Apache-2.0 licence.
- Complex setup process requiring Java 17 and Apache Ant.
- High memory needs for running large crawl jobs, requiring 4 GB of RAM or more.
- Steep learning curve for non-Java developers.
Writing a custom web crawler from scratch.
Apache Hadoop (a framework for running large computations across multiple computers).
- scrapy/scrapy65k stars
A faster, Python-based web scraping framework that is easier to set up for smaller crawling tasks.
- siyuan-note/siyuan47k stars
Not a web crawler, but another complex Java-based project with a focus on local storage.


- cybertec-postgresql/pg_timetable1.4k stars
A job scheduler for PostgreSQL whose jobs and schedules live in the database itself.
- PrefectHQ/prefect24k stars
Adds scheduling, retries and a run history to Python functions you already have.
git clone https://github.com/apache/nutch.git
cd nutch
ant eclipse