Overview
Summary
The useful answer before the supporting detail.
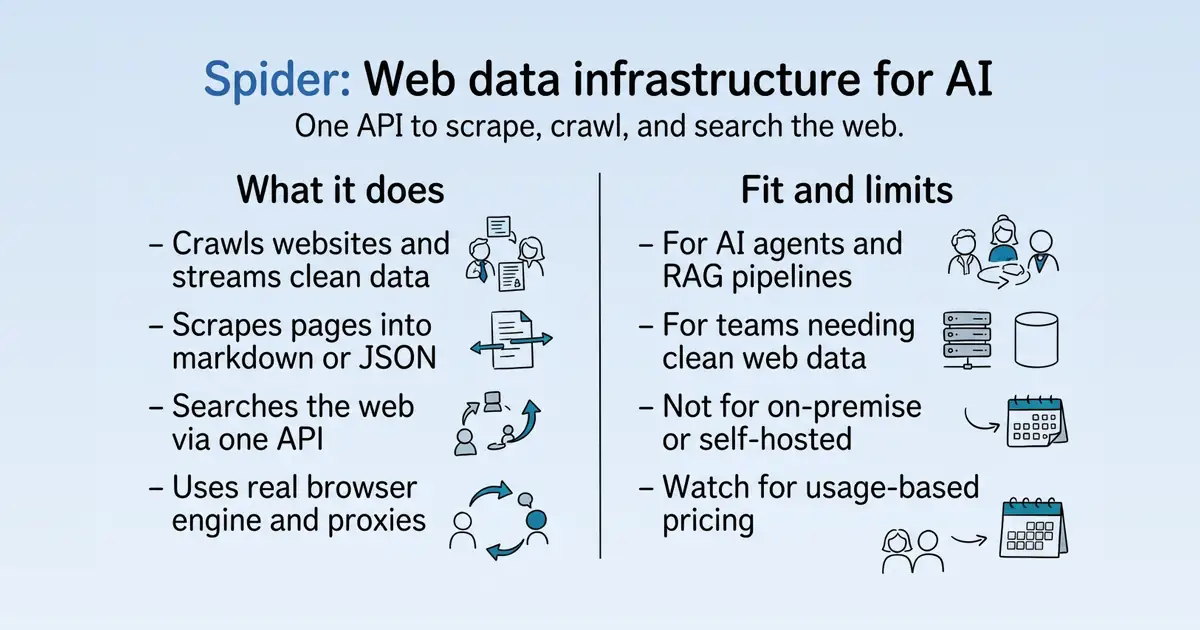
Spider is a web data infrastructure API that crawls, scrapes, and searches websites, returning clean markdown or JSON for AI agents and RAG pipelines S1. It is used by developers and AI teams who need reliable web data extraction without building and maintaining their own scraping infrastructure S1. The service provides a single API backed by its own browser engine and network, simplifying integration and reducing operational overhead S1.
Product identity and positioning
Name, category, positioning, audience, and first-party claims.
- Identity: Spider is a web data infrastructure API for AI agents and RAG pipelines S1.
- Core purpose: It solves the problem of websites lacking APIs by providing a unified API to scrape, crawl, and search the web S1.
- Intended users: Developers and AI teams building agents or RAG systems that need clean web data S1.
- Product scope: It is a single API service, not a platform, with components including a scraping API, browser, and proxy network S1.
- Positioning: Positioned as "the web data infrastructure for AI" S1.
- Claimed distinction: Claims a real browser engine that loads protected pages like a person, with geo checks S1.
Use cases and audiences
Who the product serves and the jobs it is designed to handle.
| Audience | Practical use case |
|---|---|
| AI agents | Provide clean web data for agent reasoning and actions S1. |
| RAG pipelines | Feed clean markdown or JSON into retrieval-augmented generation systems S1. |
| SEO teams | Track keyword rankings, featured snippets, and SERP features across locations S57. |
| Competitive analysts | Analyze who ranks for target keywords and ad strategies across geographies S57. |
| Advertisers | Monitor Google Ads placements, ad copy, and landing pages for competitive analysis S57. |
Traffic and search
SEO analysis
Collected Oct 22, 2026spider.cloud: an estimated 33,658 total monthly visits and about 1,387 monthly organic visits across 497 ranking keywords. Scout crawled 1 pages and measured a technical health score of 90/100.
Search summary
The useful answer before the supporting detail.
Infrastructure for reading the public web. spider.cloud: an estimated 33,658 total monthly visits and about 1,387 monthly organic visits across 497 ranking keywords. Scout crawled 1 pages and measured a technical health score of 90/100.
- Total traffic (modeled): 33,658 monthly visits across all channels.
- Organic search traffic (estimated): 1,387 monthly visits from search.
- Strongest sampled ranking: web spider tool at position 1.
- Leading page in the collected evidence: https://spider.cloud/.
- Closest measured organic competitor: screamingfrog.co.uk, appearing 1 times in the sampled first-page SERPs.
- Technical crawl: 1 pages, health score 90/100.
Website intelligence — Collected evidence
Company identity and positioning
| Page type | Evidence | Source |
|---|---|---|
| integrations | The web data infrastructure for AI. Get clean markdown or JSON from any website in realtime, priced per page. | https://spider.cloud/ |
| features | Recent product updates, API additions, and platform improvements. | https://spider.cloud/changelog/ |
| features | Put a router object in a scrape or crawl body to ask for an outside provider on your own keys, or set mode to off to keep a URL on Spider's own stack. Set funding to own to keep a request to routes your keys can pay for. Rolling out; write to support@spider.cloud to check access. See the provider router page, or the router docs for every field. | https://spider.cloud/changelog/ |
| features | Redesigned the logs tab with a dark theme, click-to-expand detail panels, and an inline browser preview for live sessions. | https://spider.cloud/changelog/ |
| features | Added case studies with real production numbers and a showcase of verified integrations built with Spider. | https://spider.cloud/changelog/ |
| features | AI extraction now uses a two-phase fallback: a fast model handles most pages, and a more capable model kicks in for complex layouts. Happens automatically per page. | https://spider.cloud/changelog/ |
| features | Reworked the dashboard layout, fixed the cost breakdown display, improved mobile usability, and added a light mode for the playground editor. | https://spider.cloud/changelog/ |
| features | Allow cookies for analytics and session replay? privacy policy → | https://spider.cloud/changelog/ |
| identity | We build the data infrastructure for AI. | https://spider.cloud/about/ |
| identity | Spider is a research lab for web data quality. Its one API crawls, scrapes and searches the web and returns clean markdown or JSON for AI agents and RAG pipelines. We do the work in public: an open source core, open benchmarks, and a bill that reads $0 when a page fails. | https://spider.cloud/about/ |
| identity | A low-latency Rust crawler. Concurrent by default, designed to crawl thousands of pages a second on a single host. MIT-licensed at github.com/spider-rs/spider. | https://spider.cloud/about/ |
| identity | The same crawler, hosted. Proxies, browser rendering, and auto-scaling rolled in. JavaScript rendering included; pay only for bandwidth and compute used. | https://spider.cloud/about/ |
Domain performance
Modeled total traffic, six-month trend, engagement, countries, and domain identity.
Total website traffic
| Month | Modeled visits |
|---|---|
| 2026-04 | 22,245 |
| 2026-05 | 21,035 |
| 2026-06 | 37,616 |
| 2026-07 | 56,998 |
| 2026-08 | 58,748 |
| 2026-09 | 33,658 |
Top visitor countries
| Country | Name | Traffic share |
|---|---|---|
| US | United States | 24.1% |
| IN | India | 8.0% |
| ZA | South Africa | 6.9% |
| FR | France | 6.8% |
| BR | Brazil | 4.7% |
Domain identity
| Signal | Value |
|---|---|
| Registered | Apr 22, 2024 |
| Last changed | Mar 28, 2026 |
| Expires | Apr 22, 2027 |
| WHOIS server | whois.nic.cloud |
| DNSSEC | Not signed |
| Nameservers | ns-329.awsdns-41.com, ns-1737.awsdns-25.co.uk, ns-1409.awsdns-48.org, ns-554.awsdns-05.net |
Website capture
Organic keywords
Top keywords and an independent Google result page.
Top organic keywords
| Keyword | Volume | CPC | Estimated value |
|---|---|---|---|
| imgur scraper | 0 | $0.00 | $350 |
| spider cloud | 300 | $0.00 | $240 |
| redecanais scraper | 270 | $0.00 | $240 |
| spidercloud | 230 | $0.00 | $210 |
| webscrape from prosports reference | 230 | $0.00 | $110 |
Independent Google result page
Query: web spider tool
| Position | Title | URL | Description |
|---|---|---|---|
| 1 | AI Web Crawler API for Agents and RAG | Spider | https://spider.cloud/ | Spider is a research lab for web data quality. Most websites have no API, so we ship one. It crawls, scrapes and searches the web and returns clean markdown or ... |
| 2 | Screaming Frog SEO Spider Website Crawler | https://www.screamingfrog.co.uk/seo-spider/ | SEO Spider Tool. The Screaming Frog SEO Spider is a website crawler that audits your site for over 300 SEO issues to help improve both SEO, and UX. |
| 3 | spider-rs/spider: Foundational low latency web data ... | https://github.com/spider-rs/spider | Spider is a concurrency-first crawling engine written in Rust. It streams pages as they arrive, renders JavaScript only on pages that need it, ... |
| 4 | Web crawler | https://en.wikipedia.org/wiki/Web_crawler | A web crawler, sometimes called a spider or spiderbot and often shortened to crawler, is an Internet bot that systematically browses the World Wide Web and ... |
| 5 | Scrapy — open source web scraping framework for Python | https://scrapy.org/ | Scrapy is the leading open source Python framework for web scraping — fast, asynchronous, extensible, and BSD-licensed. Trusted by millions of developers. |
| 6 | Website Crawler: Online Spider to Test URLs for Errors | https://sitechecker.pro/website-crawler/ | Online crawler tool (spider) to test the whole website and specific pages for broken links and redirects, duplicate content, and indexing issues. |
| 7 | What Is a Web Crawler? | How Web Spiders Work | https://www.cloudflare.com/learning/bots/what-is-a-web-crawler/ | A web crawler, spider, or search engine bot is a software program that accesses, downloads, and/or indexes content from all over the Internet. Web crawler ... |
| 8 | Top Web Crawler Tools in 2026 | https://scrapfly.io/blog/posts/top-web-crawler-tools | Octoparse is a visual, no-code web scraping tool that allows users to build crawlers through a point-and-click interface. It's perfect for non- ... |
| 9 | EasySpider: No-Code Visual Web Crawler/Browser ... | https://www.easyspider.net/ | An open-source, free, and ad-free software for designing a web scraper/browser automation test task visually in minutes. Can download from your PC. Github ... |
Important pages
Pages earning the most estimated search traffic in the sample.
| URL | Ranking keywords | Estimated traffic | Best position |
|---|---|---|---|
| https://spider.cloud/ | 15 | 783.4 | 1 |
| https://spider.cloud/blog/firecrawl-vs-crawl4ai-vs-spider-honest-benchmark/ | 2 | 16.2 | 2 |
| https://spider.cloud/api/unblocker/ | 1 | 4.9 | 2 |
| https://spider.cloud/guides/pricing-and-plans/ | 1 | 2.9 | 3 |
| https://spider.cloud/guides/proxy-mode/ | 1 | 2.9 | 3 |
Website intelligence — Collected evidence
Prioritized website intelligence pages
| Type | Page | Words | Change | URL |
|---|---|---|---|---|
| integrations | AI Web Crawler API for Agents and RAG \ | static | 1,313 | new |
| pricing | Pricing from $1/GB pay as you go, or Unlimited \ | playwright | 625 | new |
| integrations | Web Scraping Integrations - LangChain, MCP, n8n \ | static | 536 | new |
| features | Spider Changelog - New Features and API Updates | 501 | new | https://spider.cloud/changelog/ |
| trust | Privacy Policy - How Spider Handles Your Data | 1,712 | new | https://spider.cloud/privacy/ |
| trust | Terms of Service and EULA \ | static | 1,142 | new |
| identity | About Us - Research Lab for Web Data Quality \ | static | 238 | new |
Features
| Page type | Evidence | Source |
|---|---|---|
| features | [Skip to main content](#main-content) | https://spider.cloud/changelog/ |
| features | What we've been shipping. | https://spider.cloud/changelog/ |
| features | Recent product updates, API additions, and platform improvements. | https://spider.cloud/changelog/ |
| features | September 2026 | https://spider.cloud/changelog/ |
| features | Provider router | https://spider.cloud/changelog/ |
| features | Put a router object in a scrape or crawl body to ask for an outside provider on your own keys, or set mode to off to keep a URL on Spider's own stack. Set funding to own to keep a request to routes your keys can pay for. Rolling out; write to support@spider.cloud to check access. See the provider router page, or the router docs for every field. | https://spider.cloud/changelog/ |
| features | Browser AI commands | https://spider.cloud/changelog/ |
| features | Send AI commands directly through Spider's Browser API WebSocket. Three modes: Act (click, type, navigate), Extract (pull structured data from the visible page), and Observe (describe what's on screen). Requires an AI Studio subscription. | https://spider.cloud/changelog/ |
| features | Mar 3 Update | https://spider.cloud/changelog/ |
| features | Dashboard logs redesign | https://spider.cloud/changelog/ |
| features | Redesigned the logs tab with a dark theme, click-to-expand detail panels, and an inline browser preview for live sessions. | https://spider.cloud/changelog/ |
| features | February 2026 | https://spider.cloud/changelog/ |
| features | Scraper catalog | https://spider.cloud/changelog/ |
| features | 1,000+ ready-made scraper examples across 32 categories. Each includes working code and a report button if a scraper breaks. | https://spider.cloud/changelog/ |
| features | Case studies and showcase | https://spider.cloud/changelog/ |
| features | Added case studies with real production numbers and a showcase of verified integrations built with Spider. | https://spider.cloud/changelog/ |
| features | Proxy location pages | https://spider.cloud/changelog/ |
| features | 199 country-specific proxy pages with unique profiles. Useful if you need to verify geo-targeted content or route crawls through specific regions. | https://spider.cloud/changelog/ |
| features | Smarter AI extraction fallback | https://spider.cloud/changelog/ |
| features | AI extraction now uses a two-phase fallback: a fast model handles most pages, and a more capable model kicks in for complex layouts. Happens automatically per page. | https://spider.cloud/changelog/ |
Pricing and plans
| Page type | Evidence | Source |
|---|---|---|
| pricing | Spider pricing | https://spider.cloud/pricing/ |
| pricing | Starting at $1/GB. Failed requests cost $0. | https://spider.cloud/pricing/ |
| pricing | Pay as you go pricing | https://spider.cloud/pricing/ |
| pricing | $5$25$100$500+5%$2K+12% | https://spider.cloud/pricing/ |
| pricing | Sign up to top up $25 | https://spider.cloud/pricing/ |
| pricing | Unlimited plan pricing | https://spider.cloud/pricing/ |
| pricing | $350/mo·25 concurrent·$14 each | https://spider.cloud/pricing/ |
| pricing | Start Unlimited · $350/mo | https://spider.cloud/pricing/ |
| pricing | Need volume pricing or custom scraping? Talk to sales | https://spider.cloud/pricing/ |
| pricing | Pricing details | https://spider.cloud/pricing/ |
| pricing | Pricing details⌄ | https://spider.cloud/pricing/ |
| pricing | from $6/mo View AI Studio plans | https://spider.cloud/pricing/ |
| pricing | questionsHow does billing work? + | https://spider.cloud/pricing/ |
| pricing | Two line items per request: bandwidth ($1 per GB of pre-transformation content) and compute ($0.0001 per minute of CPU). Most pages land at a fraction of a cent. Failed requests cost $0. | https://spider.cloud/pricing/ |
| pricing | No. Pay as you go has no subscription. Top up once and use the balance whenever you need it. Nothing resets monthly. Unlimited is a separate monthly plan you pick on the Unlimited tab. | https://spider.cloud/pricing/ |
| pricing | Top up any amount, any time. A single purchase of $500 or more earns an automatic bonus, and the top up form shows the exact percentage for each amount. You never have to negotiate for it. | https://spider.cloud/pricing/ |
| pricing | How does the Unlimited plan work? + | https://spider.cloud/pricing/ |
| pricing | Instead of paying per request, you buy concurrency: how many requests can be in flight at once. Pick any amount from 2 ($40/mo) up to 1,538 ($19,994/mo) and run unlimited requests through it for a flat monthly price. The price per concurrent request drops from $20 to $13 as you add concurrency. Each price band is billed on its own line, so one subscription shows several line items on the invoice. Above the self-serve maximum, talk to sales for a custom rate. Geo-targeting is not available on Unlimited yet. | https://spider.cloud/pricing/ |
| pricing | None for JS rendering or proxies. JS rendering bills as compute, and proxy rotation comes with every request. Proxy mode and AI extraction have their own prices, listed under Pricing details above. The only account-wide multiplier is the optional zero data retention setting, which bills requests at 2.5x credits. Enterprise plans include it at no extra charge. | https://spider.cloud/pricing/ |
Integrations and supported platforms
| Page type | Evidence | Source |
|---|---|---|
| integrations | [Skip to main content](#main-content) | https://spider.cloud/ |
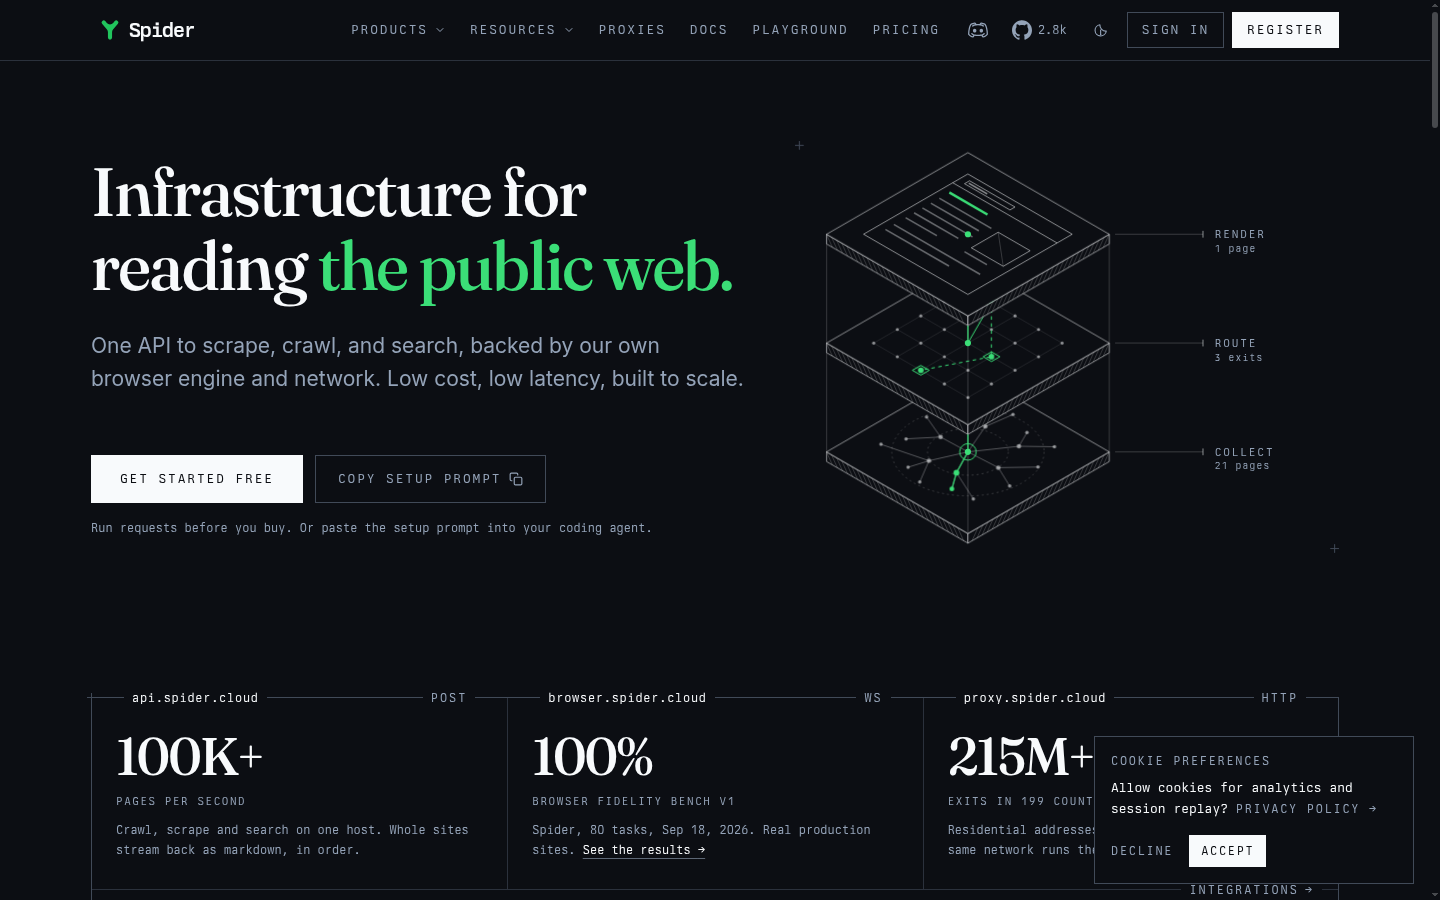
| integrations | Infrastructure for reading the public web. | https://spider.cloud/ |
| integrations | One API to scrape, crawl, and search, backed by our own browser engine and network. Low cost, low latency, built to scale. | https://spider.cloud/ |
| integrations | Get started freeCopy setup promptPrompt copied | https://spider.cloud/ |
| integrations | Run requests before you buy. Or paste the setup prompt into your coding agent. | https://spider.cloud/ |
| integrations | api.spider.cloud POST | https://spider.cloud/ |
| integrations | 100K+ pages per second | https://spider.cloud/ |
| integrations | Crawl, scrape and search on one host. Whole sites stream back as markdown, in order. | https://spider.cloud/ |
| integrations | browser.spider.cloud WS | https://spider.cloud/ |
| integrations | 100% browser fidelity bench v1 | https://spider.cloud/ |
| integrations | Spider, 80 tasks, Sep 18, 2026. Real production sites. See the results → | https://spider.cloud/ |
| integrations | proxy.spider.cloud HTTP | https://spider.cloud/ |
| integrations | 215M+ exits in 199 countries | https://spider.cloud/ |
| integrations | Residential addresses, rotated per request. The same network runs the crawler and the browser. | https://spider.cloud/ |
| integrations | Integrations→ | https://spider.cloud/ |
| integrations | Scraping API, browser, proxy. One key. | https://spider.cloud/ |
| integrations | Start with the API. The browser and the proxies each work on their own, on the same key. The trace below is one crawl through all three. | https://spider.cloud/ |
| integrations | authentication $ | https://spider.cloud/ |
| integrations | export SPIDER\_API\_KEY\="<YOUR\_API\_KEY>" | https://spider.cloud/ |
| integrations | Get a key → | https://spider.cloud/ |
Product and company updates
No supporting public-page evidence was collected for this category.
Rank tracking
Persistent keyword baselines and position movement.
This analysis created the first position baseline at 2026-10-22T09:18:51.479Z. Movement appears after the next fresh analysis using the same location and language.
| Keyword | Current | Previous | Movement | Volume | Ranking URL |
|---|---|---|---|---|---|
| web spider tool | 1 | Baseline | Baseline | 880 | https://spider.cloud/ |
| ai spidering | 1 | Baseline | Baseline | 390 | https://spider.cloud/ |
| spider crawler | 1 | Baseline | Baseline | 320 | https://spider.cloud/ |
| cloud spider | 1 | Baseline | Baseline | 260 | https://spider.cloud/ |
| ai spider | 2 | Baseline | Baseline | 390 | https://spider.cloud/ |
| spider ai | 3 | Baseline | Baseline | 320 | https://spider.cloud/ |
| spider web crawler | 1 | Baseline | Baseline | 90 | https://spider.cloud/ |
| cloud spiders | 3 | Baseline | Baseline | 260 | https://spider.cloud/ |
| website spider crawler | 1 | Baseline | Baseline | 70 | https://spider.cloud/ |
| spider a website | 1 | Baseline | Baseline | 40 | https://spider.cloud/ |
| crawl4ai vs firecrawl | 2 | Baseline | Baseline | 70 | https://spider.cloud/blog/firecrawl-vs-crawl4ai-vs-spider-honest-benchmark/ |
| web spider crawler | 2 | Baseline | Baseline | 70 | https://spider.cloud/ |
| web crawler spider | 1 | Baseline | Baseline | 30 | https://spider.cloud/ |
| web crawling spider | 3 | Baseline | Baseline | 90 | https://spider.cloud/ |
| spider a site | 2 | Baseline | Baseline | 40 | https://spider.cloud/ |
| the web unblocker | 2 | Baseline | Baseline | 30 | https://spider.cloud/api/unblocker/ |
| firecrawl vs crawl4ai | 3 | Baseline | Baseline | 50 | https://spider.cloud/blog/firecrawl-vs-crawl4ai-vs-spider-honest-benchmark/ |
| spider bot web crawler | 3 | Baseline | Baseline | 50 | https://spider.cloud/ |
| spider pay | 3 | Baseline | Baseline | 30 | https://spider.cloud/guides/pricing-and-plans/ |
| spider proxy | 3 | Baseline | Baseline | 30 | https://spider.cloud/guides/proxy-mode/ |
Features
Features and capabilities
Core functions and evidence-backed product capabilities.
| Capability | What it does |
|---|---|
| Crawl | Crawls entire websites, streaming each page as a JSONL line as it completes S1. |
| Scrape | Converts any page into markdown, structured JSON, link graph, or screenshot [S48](https://spider.cloud/scrapers/AI modelapi-scraper/). |
| Search | Provides search functionality as part of the unified API S1. |
| Browser engine | Uses a real browser engine to load pages like a person, handling geo checks S1. |
| Proxy network | Routes requests through residential exits, rotating per request, with a pool of 215M+ exits in 199 countries S1. |
| Clean output | Removes navigation, ads, and footers, returning clean text for RAG and LLM context S1 S92. |
| Structured extraction | Extracts specific data fields, such as Google SERP features or Google Reviews, into JSON S57 S68. |
Integrations and ecosystem
Connected products, exports, APIs, and workflow compatibility.
| Integration or interface | Type | What it enables |
|---|---|---|
| MCP server | AI interface | Connects to MCP clients like AI modelDesktop, Cursor, Windsurf S1. |
| Python SDK | SDK | Provides a Python client for API access S1. |
| Node.js SDK | SDK | Provides an npm package for API access S1. |
| Codex skill | AI interface | Paste into a Codex session to cover the whole API S1. |
| AI modelCode | AI interface | Connect AI modelCode to use the API S1. |
| REST API | API | Direct HTTP calls to scrape, crawl, and search endpoints [S48](https://spider.cloud/scrapers/AI modelapi-scraper/). |
Pricing
Pricing and plans
Published plans, free access, trials, credits, and pricing limitations.
| Plan or offer | Verified price and billing | Included | Limits |
|---|---|---|---|
| Pay as you go | $5 to $2K top-ups, prepaid, balance does not expire S1 | $1 per GB of content plus compute; failed requests free S1 | 5% bonus from $500, 12% from $2K S1 |
| Unlimited | From $40 per month, monthly billing S1 | Unlimited requests within concurrency S1 | 2 concurrent requests; $350 per month for 25 concurrent; up to $19,994 for 1,538 S1 |
| AI Studio (alpha) | From $6 per month, monthly billing S1 | Not published S1 | Not published S1 |
| Free balance | Free balance on signup, no card required [S48](https://spider.cloud/scrapers/AI modelapi-scraper/) | Not established | Not established |
Competition
Competitive landscape
Domains competing for the same organic search demand.
Sampled competitors
| Competitor | First-page appearances | Sampled queries | Average position | Queries observed |
|---|---|---|---|---|
| screamingfrog.co.uk | 1 | 1 | 2 | web spider tool |
| linkedin.com | 1 | 1 | 2 | ai spidering |
| github.com | 1 | 1 | 3 | web spider tool |
| reddit.com | 1 | 1 | 3 | ai spidering |
| en.wikipedia.org | 1 | 1 | 4 | web spider tool |
| firecrawl.dev | 1 | 1 | 4 | ai spidering |
| scrapy.org | 1 | 1 | 5 | web spider tool |
| medium.com | 1 | 1 | 5 | ai spidering |
| sitechecker.pro | 1 | 1 | 6 | web spider tool |
| facebook.com | 1 | 1 | 6 | ai spidering |
Website intelligence — Collected evidence
Customers, testimonials, and first-party review claims
No supporting public-page evidence was collected for this category.
Independent review sources discovered
No links to supported independent review platforms were discovered on the collected pages.
AI visibility
Measured ChatGPT and Google AI mentions with cited sources.
AI-assistant referral traffic
- Estimated current generative-AI referral share: 4.8%
Scout traffic model did not return a separate AI-referral trend series for this domain.
Website intelligence — Collected evidence
Site-stated AI capabilities
| Page type | Evidence | Source |
|---|---|---|
| integrations | The web data infrastructure for AI. Get clean markdown or JSON from any website in realtime, priced per page. | https://spider.cloud/ |
| features | AI extraction now uses a two-phase fallback: a fast model handles most pages, and a more capable model kicks in for complex layouts. Happens automatically per page. | https://spider.cloud/changelog/ |
| identity | We build the data infrastructure for AI. | https://spider.cloud/about/ |
| identity | Spider is a research lab for web data quality. Its one API crawls, scrapes and searches the web and returns clean markdown or JSON for AI agents and RAG pipelines. We do the work in public: an open source core, open benchmarks, and a bill that reads $0 when a page fails. | https://spider.cloud/about/ |
| features | Browser AI commands | https://spider.cloud/changelog/ |
| features | Send AI commands directly through Spider's Browser API WebSocket. Three modes: Act (click, type, navigate), Extract (pull structured data from the visible page), and Observe (describe what's on screen). Requires an AI Studio subscription. | https://spider.cloud/changelog/ |
| features | Smarter AI extraction fallback | https://spider.cloud/changelog/ |
| features | AI extraction now uses a two-phase fallback: a fast model handles most pages, and a more capable model kicks in for complex layouts. Happens automatically per page. | https://spider.cloud/changelog/ |
| features | When you use a prompt with AI extraction, pages that aren't relevant to your query get skipped before they're billed. Big savings on broad crawls with targeted prompts. | https://spider.cloud/changelog/ |
| features | AI usage tracking | https://spider.cloud/changelog/ |
| features | Every AI extraction logs token usage and deducts from your balance automatically. Per-request costs show in the dashboard. | https://spider.cloud/changelog/ |
| features | /ai/unblocker | https://spider.cloud/changelog/ |
| pricing | from $6/mo View AI Studio plans | https://spider.cloud/pricing/ |
| pricing | None for JS rendering or proxies. JS rendering bills as compute, and proxy rotation comes with every request. Proxy mode and AI extraction have their own prices, listed under Pricing details above. The only account-wide multiplier is the optional zero data retention setting, which bills requests at 2.5x credits. Enterprise plans include it at no extra charge. | https://spider.cloud/pricing/ |
| integrations | Native document loaders for the AI frameworks, ready-made nodes for n8n and Zapier, and official SDKs for Python, Node, and Rust. | https://spider.cloud/integrations/ |
| integrations | AI frameworks with native loaders. | https://spider.cloud/integrations/ |
| integrations | Native Rust browser engine with AI agents and a retry engine. Connect to pre-warmed cloud browsers via WebSocket. | https://spider.cloud/integrations/ |
| integrations | AI Framework | https://spider.cloud/integrations/ |
| integrations | Use Spider as a document loader in your LangChain applications. Perfect for building RAG systems and AI agents. | https://spider.cloud/integrations/ |
| integrations | Build AI agent crews with web crawling capabilities using the SpiderTool integration. | https://spider.cloud/integrations/ |
These are first-party product claims, not independent measurements of AI-search visibility.
Marketing opportunities
Actions calculated directly from the collected evidence.
| Opportunity | Recommended action | Evidence |
|---|---|---|
| Competitor gap | Review the sampled queries where screamingfrog.co.uk appears. | 1 first-page appearances across web spider tool |
Website intelligence — Collected evidence
Website evidence gaps
- customers: no usable public page was collected; verify whether the site publishes this evidence.
- reviews: no usable public page was collected; verify whether the site publishes this evidence.
- changes: no usable public page was collected; verify whether the site publishes this evidence.
- technical: no usable public page was collected; verify whether the site publishes this evidence.
Trust and proof
Customers, proof, and reviews
Published proof, customer signals, and review evidence.
Independent reviews
| Platform | Page | How it was found | Note |
|---|---|---|---|
| GTM Daily | Spider Review: Pricing, Features, Pros & Cons (2026) / GTM Daily | Grounded web search | websites fast and converts pages directly into clean markdown for LLMs Crawls websites fast and converts pages directly into clean markdown for LLMs. From its website: "AI Web Crawler API for Agents and RAG" - an API for crawling and scraping at scale. |
| AI GTM Stack | Spider review: Enrichment tool pricing, verdict and alternatives / AI GTM Stack | Grounded web search | .cloud Spider is an Enrichment tool that helps GTM teams turn names into verified contact data. Pricing: Pay as you go from $1/GB; Unlimited from $350/mo. Best fit for B2B businesses. It is open ... ## What it does AI web crawler API for agents and RAG. |
| aigtm.tools | Best AI Enrichment tools for GTM teams (11 reviewed) / AI GTM Stack | Grounded web search | API for agents. ### Spider #08 spider.cloud AI web crawler API for agents and RAG. Pay as you go from $1/GB; Unlimited from $350/mo Fast crawling for agent workflows. ... source Enrichment tools? Yes. deep page fetch, Spider and Crawl4AI are open source. |
Customer proof
No named customers, testimonials, or customer case studies were found.
Independent mentions
- AI Web Crawler API for Agents and RAG / Spider — # Infrastructure for reading the public web. One API to scrape, crawl, and search, backed by our own browser engine and network. Low cost, low latency, built to scale. ... 100K+ pages per second Crawl, scrape and search on one host. Whole sites stream back as markdown, in order. - browser.spider.cloud WS ... ## Use the whole web like a dataset. ... Spider is a research lab for web data quality. Most websites have no API, so we ship one. It crawls, scrapes and searches the web and returns clean m
- Spider.cloud ▷ AI Web Crawler API for Agents and RAG / Spider — ## spider.cloud Profile Title AI Web Crawler API for Agents and RAG / Spider Description The web data infrastructure for AI. Get clean markdown or JSON from any website in realtime, priced per page.
- AI GTM tools for B2B companies / AI GTM Stack — Parallel Web research APIs built for AI agents. ### deep page fetch Web scraping and crawling API that returns clean data for AI agents. ... ### MoltSets B2B search and enrichment API for AI workflows. ### Spider AI web crawler API for agents and RAG.
- Browse every AI GTM tool / AI GTM Stack — Web research APIs built for AI agents. ### deep page fetch Web scraping and crawling API that returns clean data for AI agents. ### Persana ... ### MoltSets B2B search and enrichment API for AI workflows. ### Spider AI web crawler API for agents and RAG.
- aigtm.tools — and crawling API that returns clean data for AI agents. - ... : AI prospecting with enrichment and signals. - ... ://aigtm.tools/tools/bitscale): GTM data layer that enriches and keeps your CRM
- AI tools for GTM data / AI GTM Stack — . ### deep page fetch Web scraping and crawling API that returns clean data for AI agents. ### Persana ... ### MoltSets B2B search and enrichment API for AI workflows. ### Spider AI web crawler API for agents and RAG. ### Crawl4AI Open source crawler
External links were grounded in one live web search. Search snippets are leads, not independently scraped page content; rejected links remain available in Review evidence.
Company, security, and trust
Ownership, policies, security signals, and public trust evidence.
| Signal | Finding | Source |
|---|---|---|
| Company and ownership | > ## Satellites may be the first target in modern warfare The satellites that orbit Earth have remained largely untouched in modern conflict. But in the 21st Century, space may no longer be a safe haven.## See the Sun li | source |
| Contact and support | > Built to enhance speed, scalability, and flexibility for every transaction.#### Easy IntegrationTransition from your existing services seamlessly and effortlessly with our easy-to-use API, available via HTTP. Our strai | source |
| Legal and privacy | Allow cookies for analytics and session replay? privacy policy → | source |
| Security and compliance | Not published on the collected pages. | — |
| Uptime and status page | Not published on the collected pages. | — |
| Domain registered | 2024-04-22 | — |
| Domain expires | 2027-04-22 | — |
Not found on the collected pages: security and compliance, uptime and status page. This only means Scout did not find it on the pages it read; it says nothing about the company itself.
Documentation and product updates
Help resources, product guidance, and visible changes over time.
Not established in the collected sources.
Technical
Technical and delivery signals
Delivery model, platforms, API, data ownership, reliability claims and release activity.
| Signal | Finding | Source |
|---|---|---|
| Delivery model (cloud, self-hosted, desktop, browser extension) | Cloud API service S1. | S1 |
| Platforms and apps | Web-based API; no native apps mentioned S1. | S1 |
| API and extensibility (API, SDK, webhooks, MCP, plugins) | Provides REST API, SDKs, MCP server, and Codex skill S1. | S1 |
| Data ownership and export | Not published on the collected pages. | — |
| Performance and reliability claims | Claims low latency and built to scale S1. | S1 |
| Release activity | Not published on the collected pages. | — |
Measured infrastructure
Domain, certificate, and hosting signals, measured directly.
| Signal | Finding |
|---|---|
| Domain registered | 2024-04-22 — NAMECHEAP |
| Domain expires | 2027-04-22 |
| TLS certificate | Let's Encrypt, valid, expires 2026-12-06 |
| Security headers | HSTS, CSP, X-Content-Type-Options, X-Frame-Options, Referrer-Policy |
| Server header | Vercel |
| Mail handled by | aspmx.l.google.com, alt1.aspmx.l.google.com |
| Nameservers | ns2.vercel-dns.com, ns1.vercel-dns.com |
Not measurable: wayback: rate limited by archive.org, ladder stopped after 1 probe(s). A gap here means the lookup was unavailable, not that the finding is negative.
Technical site audit
A bounded multi-page crawl with page-level issues and URLs.
Scout — Bounded technical crawl
- Pages crawled: 1 of 15 maximum
- Technical health: 90/100
- Critical issues: 0
- Warnings: 2
- Notices: 0
Issues
| Severity | Issue | Value | Affected URL |
|---|---|---|---|
| warning | Missing meta description | — | https://spider.cloud/ |
| warning | Missing canonical URL | — | https://spider.cloud/ |
Crawled pages
| Status | Title | H1s | Words | Response | URL |
|---|---|---|---|---|---|
| 200 | AI Web Crawler API for Agents and RAG \ | Spider | 1 | 1704 | 50 ms |
This is a bounded Scout crawl. Core Web Vitals and Lighthouse scores are not claimed unless a dedicated performance audit is connected.
Search Console and Analytics
First-party search and behavioral data connection state.
Modeled acquisition channels
| Channel | Estimated share |
|---|---|
| direct | 40.4% |
| search | 43.1% |
| search organic | 42.4% |
| search paid | 0.6% |
| social | 2.6% |
| social organic | 2.3% |
| social paid | 0.3% |
| referrals | 6.4% |
| paid referrals | 1.1% |
| 1.1% | |
| gen ai | 4.8% |
| affiliate | 0.6% |
| other | 0.0% |
First-party connections
| Integration | Status | Data available after connection |
|---|---|---|
| Google Search Console | Not connected | Clicks, impressions, CTR, average position, queries, pages, countries, and devices |
| Google Analytics | Not connected | Organic sessions, engagement, landing pages, conversions, geography, and devices |
No first-party Search Console or Analytics numbers are shown until the site owner authorizes the corresponding Google account. Scout traffic model values above are modeled estimates, not private analytics totals.
Limits and method
Limitations and open questions
Known constraints and missing evidence from the collected pages.
The collected pages do not mention any competitors by name. Evidence gaps include lack of company ownership details, security certifications, uptime status, and customer testimonials. Pricing details for the AI Studio plan are incomplete. The service is cloud-only; no self-hosted or on-premise options are documented.
Sources, method, and limitations
Evidence inventory, collection method, provider use, and constraints.
This report is based on 15 collected pages from spider.cloud, including the homepage, pricing page, and individual scraper pages. The evidence catalog includes 180 tokens from these pages. An external proof search was performed but did not yield additional verified customer or review data. Limitations: no first-party customer testimonials, no detailed documentation pages, and no company information beyond the homepage.
- Documentationhttps://spider.cloud/Verified
- Documentationhttps://spider.cloud/scrapers/claude-api-scraper/Verified
- Documentationhttps://spider.cloud/scrapers/google-api/Verified
- Documentationhttps://spider.cloud/scrapers/netlify-app-scraper/Verified
- Official Websitehttps://spider.cloud/scrapers/google-reviews-scraper/Verified
- Official Websitehttps://spider.cloud/scrapers/bbc-news-scraper/Verified
- Official Websitehttps://spider.cloud/scrapers/bloomberg-news-scraper/Verified
- Official Websitehttps://spider.cloud/scrapers/ground-news-scraper/Verified
- Official Websitehttps://spider.cloud/scrapers/0slot-trade-scraper/Verified
- Official Websitehttps://spider.cloud/scrapers/0xrpc-io-scraper/Verified
- Official Websitehttps://spider.cloud/scrapers/1mg-com-scraper/Verified
- Official Websitehttps://spider.cloud/scrapers/1tv-ru-scraper/Verified
- Official Websitehttps://spider.cloud/scrapers/51job-com-scraper/Verified
- Official Websitehttps://spider.cloud/scrapers/8-lives-cat-io-scraper/Verified
- Official Websitehttps://spider.cloud/scrapers/aastocks-com-scraper/Verified
- Review Sitehttps://gtmdaily.com/tools/spiderVerified
- Review Sitehttps://aigtm.tools/tools/spiderVerified
- Articlehttps://hypestat.com/info/spider.cloudVerified
- Review Sitehttps://aigtm.tools/category/enrichmentVerified
- Articlehttps://aigtm.tools/for/b2bVerified
- Articlehttps://aigtm.tools/browseVerified
- Articlehttps://aigtm.tools/llms.txtVerified
- Articlehttps://aigtm.tools/browse/dataVerified