177.7k stars · AGPL-3.0 · v2.11.289 (2026-09-02) · Track this in Scout
trafilatura on a single URL is 20ms and free. Firecrawl on a whole domain, JS-rendered, in structured JSON, is where the real research goes.
▶Repo detailsthe review · specs · pros & cons
What it is
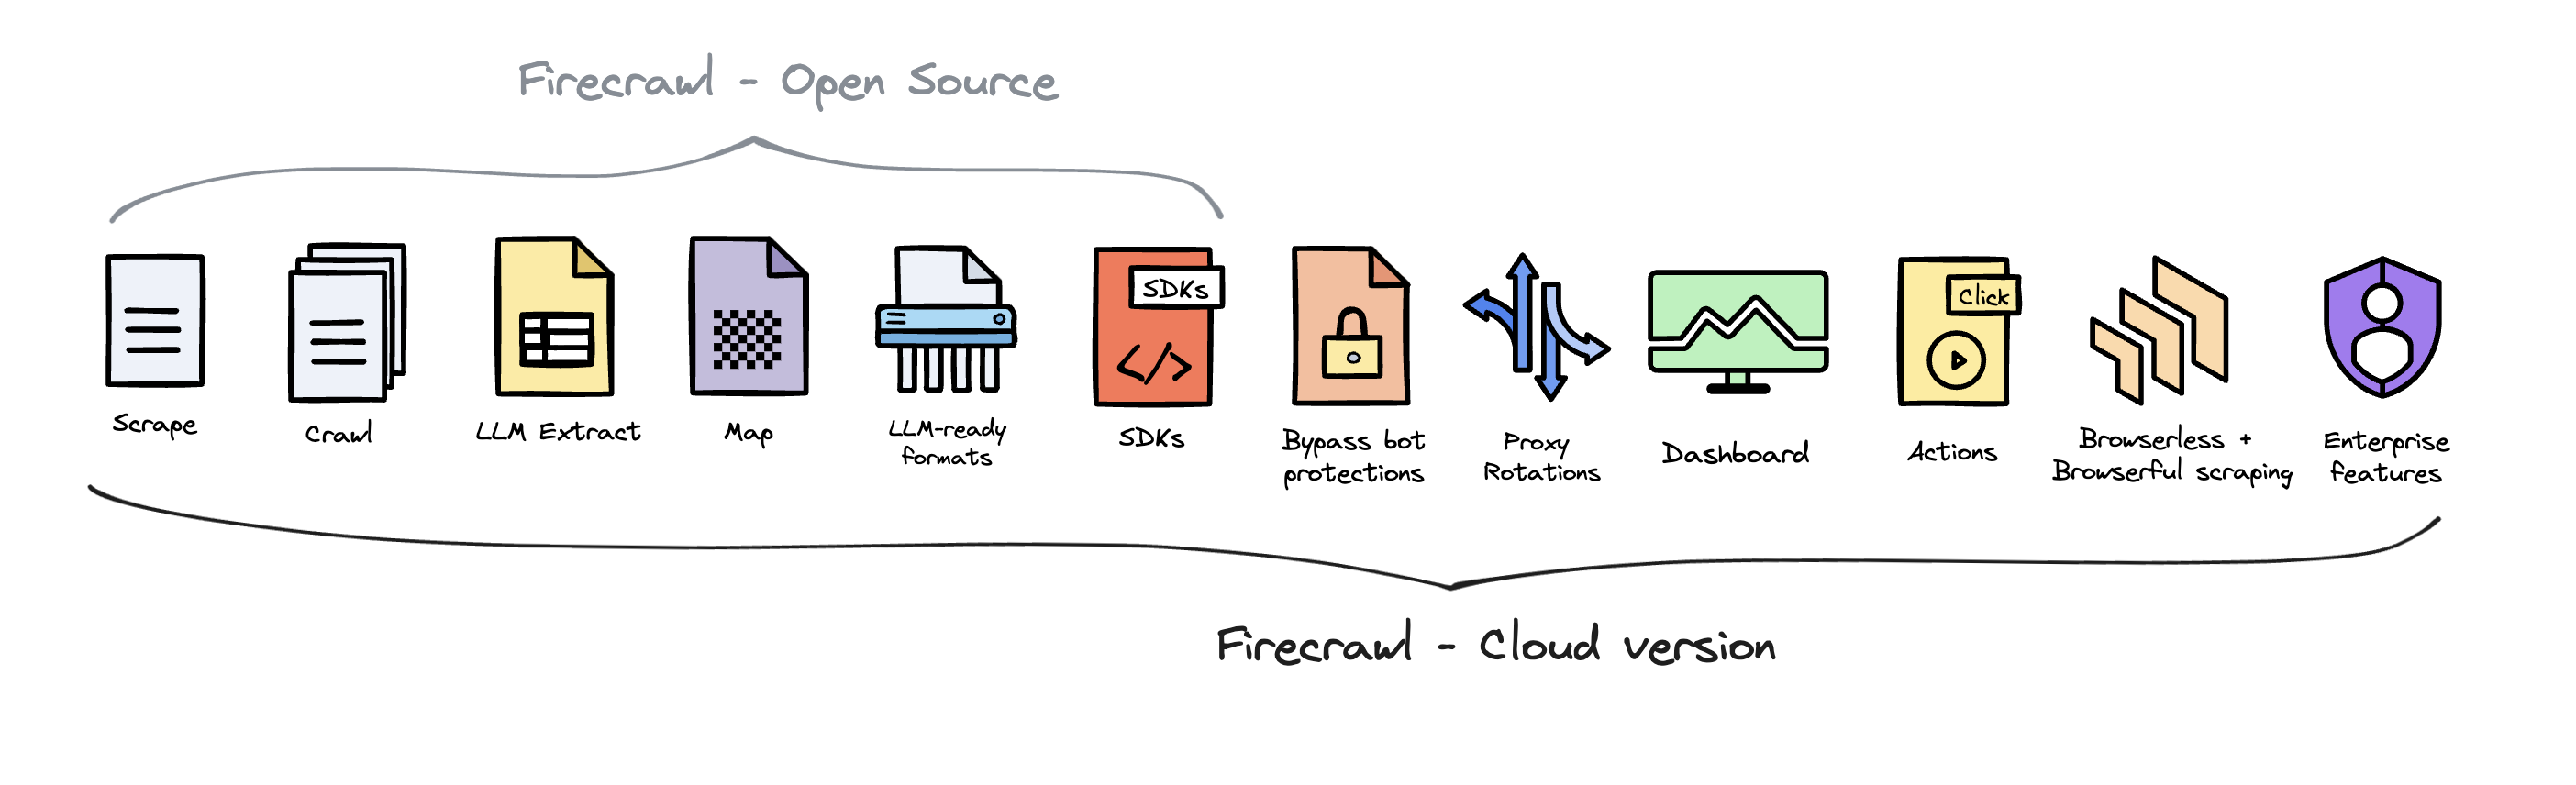
A crawler service that fetches pages (with a headless browser when needed), extracts clean Markdown, and offers structured JSON output tuned for LLMs. Ships as a hosted service and a self-hostable Docker stack. REDIRECT: mendableai/firecrawl now resolves to firecrawl/firecrawl (moved into a dedicated org).
What it is good for. Edition 6 covered trafilatura and yt-dlp for research. Edition 8 covered sqlite-utils to land the pile in one file. Firecrawl is the layer for when trafilatura is not enough: competitor documentation sites with heavy JavaScript, structured extraction of pricing tables, and — the real payoff — the "crawl the whole site and return JSON" mode that trafilatura does not have. That is the shape of "map a competitor's whole content universe" in one command.
- Releases ship daily — v2.11.289 was yesterday
- Both AGPL-3.0 self-hosted and firecrawl.dev hosted are available — pick per-job
- LLM-schema extraction is a real capability, not marketing copy
- Self-hosted is heavy: headless browser, queue, storage — same order as OpenReplay
- AGPL — same rule as Docmost or Papermark: self-host is fine, embedding is not
- Hosted tier is not cheap; a batched-token spend cap on day one is the discipline
Paid scraping APIs, and hand-rolled extraction on JavaScript-heavy sites
A SQLite research file as the landing place, and Datasette to browse what it collects