Overview
Summary
The useful answer before the supporting detail.
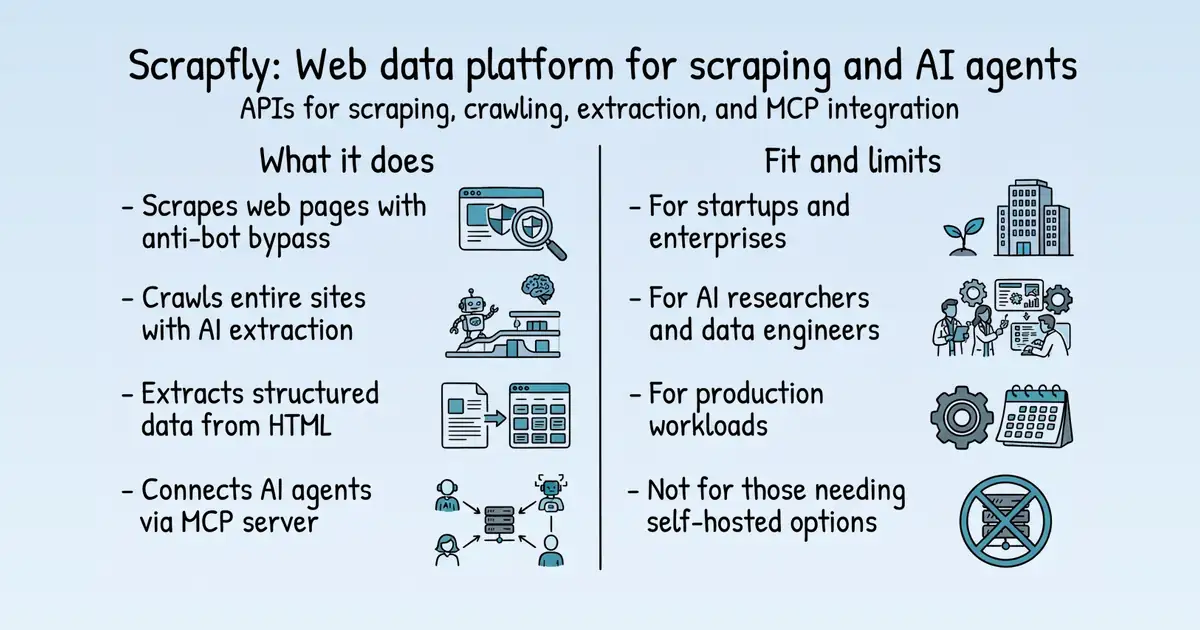
Scrapfly is a web data platform that provides APIs for scraping, crawling, extraction, and screenshots, with anti-bot bypass and JavaScript rendering built in S1. It is used by startups, enterprises, AI researchers, and data engineers to collect web data at scale S1. The platform offers a hosted MCP server for AI agents, enabling natural language access to its scraping infrastructure S17.
Product identity and positioning
Name, category, positioning, audience, and first-party claims.
- Identity: Scrapfly is a web data platform by Joam Intelligence, LLC S1.
- Core purpose: It solves the problem of collecting web data by handling anti-bot bypass, rendering, and extraction S1.
- Intended users: Startups, enterprises, AI researchers, and data engineers S1.
- Product scope: A platform with APIs for scraping, crawling, extraction, screenshots, and a hosted MCP server S12 S17.
- Positioning: Built by engineers for engineers, focused on production workloads S1.
- Claimed distinction: Powered by proprietary C/C++ projects, including a custom Chromium fork S1.
Use cases and audiences
Who the product serves and the jobs it is designed to handle.
| Audience | Practical use case |
|---|---|
| Startups | Build data collection infrastructure for products S1. |
| Enterprises | Run production workloads at scale S1. |
| AI researchers | Collect training corpora for AI models S133. |
| Data engineers | Automate extraction and crawling pipelines S1. |
| AI agents | Access web scraping via MCP for agentic workflows S17. |
Traffic and search
SEO analysis
Collected Oct 22, 2026scrapfly.io: an estimated 176,650 total monthly visits and about 91,731 monthly organic visits across 4,762 ranking keywords. Scout crawled 15 pages and measured a technical health score of 97/100.
Search summary
The useful answer before the supporting detail.
Power web scrapers and AI agents with Scrapfly's web data platform. One API key for reliable access to public web data, managed Chromium over CDP, residential proxies, screenshots, and structured extraction. scrapfly.io: an estimated 176,650 total monthly visits and about 91,731 monthly organic visits across 4,762 ranking keywords. Scout crawled 15 pages and measured a technical health score of 97/100.
- Total traffic (modeled): 176,650 monthly visits across all channels.
- Organic search traffic (estimated): 91,731 monthly visits from search.
- Strongest sampled ranking: json vs jsonl at position 1.
- Leading page in the collected evidence: https://scrapfly.io/blog/posts/jsonl-vs-json.
- Closest measured organic competitor: medium.com, appearing 2 times in the sampled first-page SERPs.
- Technical crawl: 15 pages, health score 97/100.
Website intelligence — Collected evidence
Company identity and positioning
| Page type | Evidence | Source |
|---|---|---|
| integrations | Power web scrapers and AI agents with Scrapfly's web data platform. One API key for reliable access to public web data, managed Chromium over CDP, residential proxies, screenshots, and structured extraction. | https://scrapfly.io/ |
| features | Master etsy scraper development with Python to extract product data, reviews, and shop information while bypassing anti-scraping measures for comprehensive e-commerce analysis. | https://scrapfly.io/blog/posts/how-to-scrape-etsy-com-product-review-data |
| features | Reverse engineer Etsy's hidden JSON data embedded in script tags for product details and variants | https://scrapfly.io/blog/posts/how-to-scrape-etsy-com-product-review-data |
| features | Implement error handling and retry logic for rate limiting and temporary blocking scenarios | https://scrapfly.io/blog/posts/how-to-scrape-etsy-com-product-review-data |
| features | Use ScrapFly SDK for automated Etsy scraping with built-in anti-blocking protection | https://scrapfly.io/blog/posts/how-to-scrape-etsy-com-product-review-data |
| features | If you are a buyer looking to buy certain items, manually exploring thousands of ad listings to figure out the best deal can be tedious and time-consuming. With etsy.com scraping, we can retrieve thousands of listings and compare them in no time, allowing for better decision-making. | https://scrapfly.io/blog/posts/how-to-scrape-etsy-com-product-review-data |
| features | Web scraping etsy.com also allows businesses and sellers to understand and analyze market trends to get insights into consumer behavior. | https://scrapfly.io/blog/posts/how-to-scrape-etsy-com-product-review-data |
| features | `scrapfly-sdk` for bypassing etsy.com web scraping blocking using ScrapFly's web scraping API. | https://scrapfly.io/blog/posts/how-to-scrape-etsy-com-product-review-data |
| features | `asyncio` for running our code in an asynchronous fashion, increasing our web scraping speed. | https://scrapfly.io/blog/posts/how-to-scrape-etsy-com-product-review-data |
| features | `parse_product_page()` for parsing the HTML and selecting the JSON data inside the script tag. | https://scrapfly.io/blog/posts/how-to-scrape-etsy-com-product-review-data |
| features | `scrape_product()` for scraping the product pages by adding the page URLs to a scraping list and scraping them concurrently. | https://scrapfly.io/blog/posts/how-to-scrape-etsy-com-product-review-data |
| features | "name": "Oakywood Dual Laptop Stand Wood, Vertical Stand for Desk, Adjustable Macbook Double Dock, Desk Organizer, Gift for Him, Work from Home", | https://scrapfly.io/blog/posts/how-to-scrape-etsy-com-product-review-data |
Domain performance
Modeled total traffic, six-month trend, engagement, countries, and domain identity.
Total website traffic
| Month | Modeled visits |
|---|---|
| 2026-04 | 215,059 |
| 2026-05 | 267,525 |
| 2026-06 | 276,381 |
| 2026-07 | 247,911 |
| 2026-08 | 215,234 |
| 2026-09 | 176,650 |
Top visitor countries
| Country | Name | Traffic share |
|---|---|---|
| US | United States | 11.1% |
| IN | India | 10.0% |
| VN | Vietnam | 4.2% |
| BR | Brazil | 3.9% |
| EG | Egypt | 2.6% |
Domain identity
| Signal | Value |
|---|---|
| Registered | Sep 12, 2018 |
| Last changed | Sep 3, 2026 |
| Expires | Sep 12, 2027 |
| WHOIS server | whois.nic.io |
| DNSSEC | — |
| Nameservers | ns-cloud-c1.googledomains.com, ns-cloud-c2.googledomains.com, ns-cloud-c3.googledomains.com, ns-cloud-c4.googledomains.com |
Website capture
Organic keywords
Top keywords and an independent Google result page.
Top organic keywords
| Keyword | Volume | CPC | Estimated value |
|---|---|---|---|
| scrapfly | 3,060 | $10.67 | $2,820 |
| serpapi | 93,580 | $3.55 | $570 |
| charles proxy | 12,220 | $0.78 | $490 |
| jsonl | 16,780 | $0.70 | $410 |
| linkedin api | 22,380 | $3.55 | $400 |
Independent Google result page
Query: json vs jsonl
| Position | Title | URL | Description |
|---|---|---|---|
| 1 | JSONL vs JSON | https://scrapfly.io/blog/posts/jsonl-vs-json | JSON and JSONLines differ in how they handle parsing, especially for small versus large datasets. JSON: JSON works best for small datasets ... |
| 2 | JSON and JSONL: Understanding Two Essential Data ... | https://medium.com/@ayasc/json-and-jsonl-understanding-two-essential-data-formats-7a1b999ce5db | The key difference is that JSON requires loading the entire structure at once, while JSONL can be processed incrementally. |
| 3 | Why jsonl is better than a regular JSON for web scraping | https://www.reddit.com/r/JSON_Treehouse/comments/1imthyr/json_lines_format_why_jsonl_is_better_than_a/ | advantages of JSONL over regular JSON for web scraping. I love JSONL for multiple purposes. Handle 10M+ rows and 5GB+ files with advanced ... |
| 4 | JSONL vs JSON: 5 Differences (With Examples) | https://jsonltools.com/jsonl-vs-json | JSON is one document. JSONL is one object per line. JSON loads the whole file; JSONL streams. Use JSON for APIs, JSONL for logs and training data. |
| 5 | JSON Lines | https://jsonlines.org/ | JSON Lines is a convenient format for storing structured data that may be processed one record at a time. It works well with unix-style text processing tools ... |
| 6 | JSON / JSONL feed format - items - Constructor Documentation | https://docs.constructor.com/docs/integrating-with-constructor-product-catalog-catalog-files-via-http-or-ftps-json-jsonl-feed-format-items | The difference between JSON and JSONL is that JSON file is expected to contain only a JSON object string, while JSONL file is expected to contain a set of lines |
| 7 | JSONL vs JSON: Which Format Fits Your Data Needs? | https://www.systoolsgroup.com/updates/difference-between-jsonl-and-json-format/?srsltid=AYCX9vKC2yR_f_mTndMSNQvz8uEESEQOG2v3Pepqkk07rjqQvi7Oaidi | JSONL has an individual JSON object per line, whereas JSON has a single array or object. Readability: JSONL files are less tidy and have plain ... |
| 8 | JSON vs JSONL vs NDJSON: The Most Confused Topic Finally ... | https://www.youtube.com/watch?v=3zFOJz9zi0Q | In this video, Cloud X Berry explains JSONL (JSON Lines), what it is, how it differs from regular JSON and NDJSON, and when you should ... |
| 9 | JSONL vs JSON: When to Use JSON Lines Format for Data ... | https://superjson.ai/blog/2025-09-07-jsonl-vs-json-data-processing/ | While JSON dominates API responses and configuration files, JSONL has emerged as the preferred format for data processing, machine learning ... |
Important pages
Pages earning the most estimated search traffic in the sample.
Website intelligence — Collected evidence
Prioritized website intelligence pages
| Type | Page | Words | Change | URL |
|---|---|---|---|---|
| integrations | Scrapfly - Web Scraping API, Cloud Browser, Screenshot API | 2,831 | new | https://scrapfly.io/ |
| pricing | Scrapfly Pricing: Web Scraping API Plans, 1,000 Free Credits | 1,709 | new | https://scrapfly.io/pricing |
| pricing | Scrapfly Web Scraping API \ | playwright | 1,553 | new |
| pricing | Cloud Browser Billing & Pricing \ | playwright | 1,827 | new |
| pricing | Scrapfly Crawler API \ | playwright | 1,587 | new |
| pricing | Scrapfly Extraction API \ | playwright | 368 | new |
| pricing | Scrapfly Proxy Saver \ | playwright | 358 | new |
| pricing | Web Scraping API Billing & Cost Calculation \ | playwright | 1,642 | new |
| pricing | Scrapfly Screenshot API \ | static | 558 | new |
| features | How to Scrape Etsy.com Product, Shop and Search Data | 2,485 | new | https://scrapfly.io/blog/posts/how-to-scrape-etsy-com-product-review-data |
| integrations | AI Web Scraping API: Scrape and Extract in One Call \ | static | 2,422 | new |
| integrations | Scrapfly Documentation \ | static | 392 | new |
| integrations | Scrapfly Integrations: Zapier, Make, n8n, LangChain, LlamaIndex, MCP | 1,091 | new | https://scrapfly.io/integration |
| integrations | Scrapfly CLI \ | static | 402 | new |
| integrations | Ask our Docs \ | static | 83 | new |
Features
Pricing and plans
| Page type | Evidence | Source |
|---|---|---|
| pricing | Usage-based. One API key across every Scrapfly product. 1,000 free credits, no credit card. | https://scrapfly.io/pricing |
| pricing | Get Free Key | https://scrapfly.io/pricing |
| pricing | $0.15 per 1k credits, prepaid | https://scrapfly.io/pricing |
| pricing | 200,000 API credits / month | https://scrapfly.io/pricing |
| pricing | Start Free | https://scrapfly.io/pricing |
| pricing | $100 /mo | https://scrapfly.io/pricing |
| pricing | $0.10 per 1k credits, prepaid | https://scrapfly.io/pricing |
| pricing | 1,000,000 API credits / month | https://scrapfly.io/pricing |
| pricing | Extra at $3.50 / 10k | https://scrapfly.io/pricing |
| pricing | $250 /mo | https://scrapfly.io/pricing |
| pricing | 2,500,000 API credits / month | https://scrapfly.io/pricing |
| pricing | Extra at $2.00 / 10k | https://scrapfly.io/pricing |
| pricing | $500 /mo | https://scrapfly.io/pricing |
| pricing | $0.09 per 1k credits, prepaid | https://scrapfly.io/pricing |
| pricing | 5,500,000 API credits / month | https://scrapfly.io/pricing |
| pricing | Extra at $1.20 / 10k | https://scrapfly.io/pricing |
| pricing | 1,000free credits on signup | https://scrapfly.io/pricing |
| pricing | 15B+requests / month | https://scrapfly.io/pricing |
| pricing | Every product, every plan. | https://scrapfly.io/pricing |
| pricing | 1,000free credits to evaluate | https://scrapfly.io/pricing |
Integrations and supported platforms
| Page type | Evidence | Source |
|---|---|---|
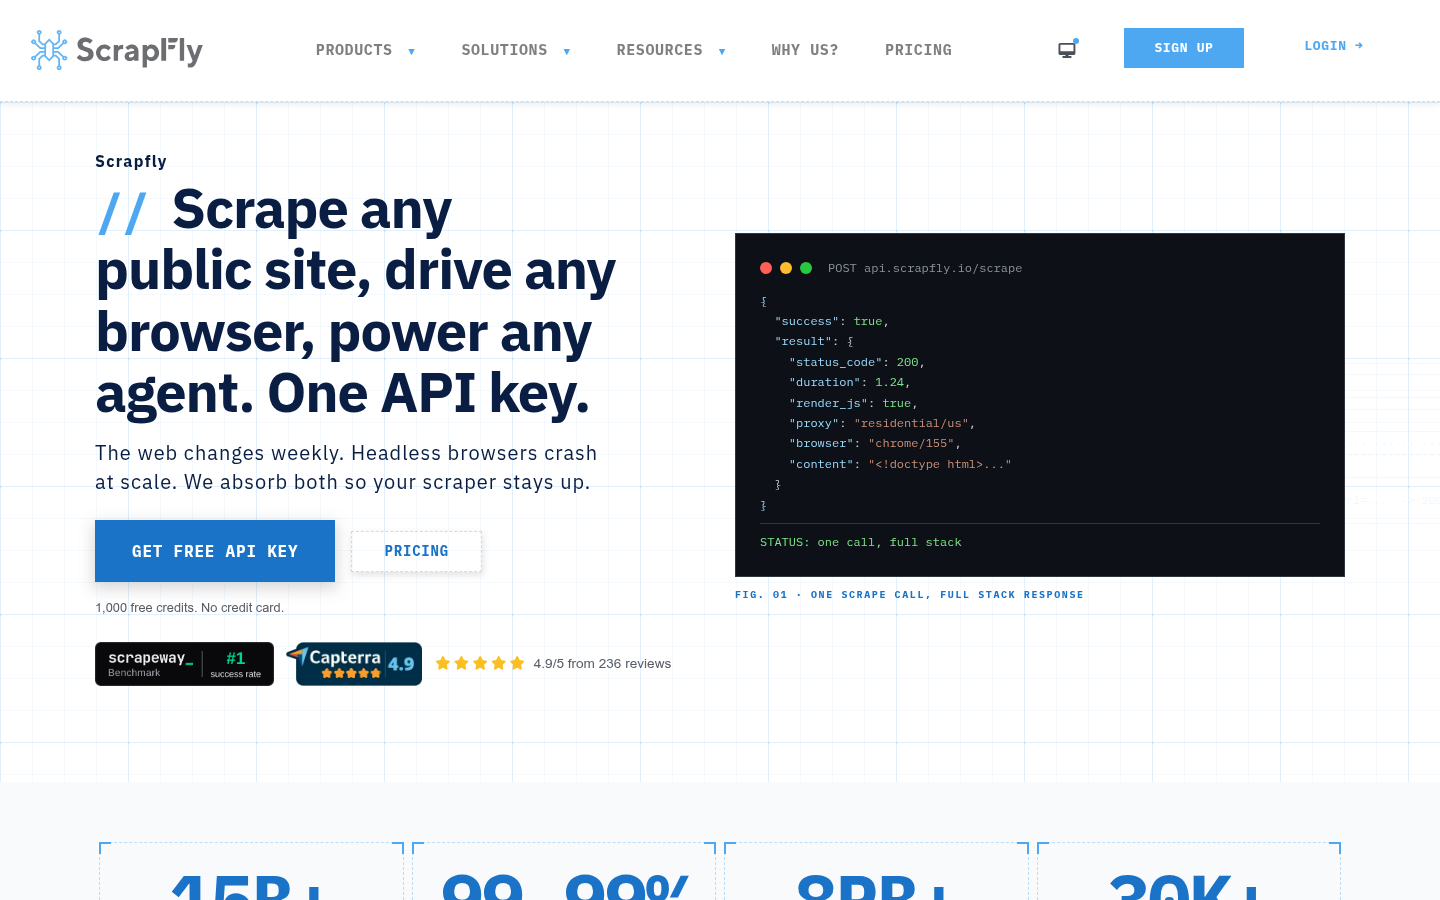
| integrations | Scrape any public site, drive any browser, power any agent. One API key. | https://scrapfly.io/ |
| integrations | The web changes weekly. Headless browsers crash at scale. We absorb both so your scraper stays up. | https://scrapfly.io/ |
| integrations | Get Free API Key Pricing | https://scrapfly.io/ |
| integrations | 1,000 free credits. No credit card. | https://scrapfly.io/ |
| integrations | 0 | https://scrapfly.io/ |
| integrations | 0 | https://scrapfly.io/ |
| integrations | 4.9/5 from 236 reviews | https://scrapfly.io/ |
| integrations | POST api.scrapfly.io/scrape | https://scrapfly.io/ |
| integrations | "success": true, | https://scrapfly.io/ |
| integrations | "status\_code": 200, | https://scrapfly.io/ |
| integrations | "duration": 1.24, | https://scrapfly.io/ |
| integrations | "render\_js": true, | https://scrapfly.io/ |
| integrations | "proxy": "residential/us", | https://scrapfly.io/ |
| integrations | "browser": "chrome/155", | https://scrapfly.io/ |
| integrations | "content": "<!doctype html>..." | https://scrapfly.io/ |
| integrations | STATUS: one call, full stack | https://scrapfly.io/ |
| integrations | FIG. 01 · ONE SCRAPE CALL, FULL STACK RESPONSE | https://scrapfly.io/ |
| integrations | requests / month | https://scrapfly.io/ |
| integrations | success rate | https://scrapfly.io/ |
| integrations | data / month | https://scrapfly.io/ |
Product and company updates
No supporting public-page evidence was collected for this category.
Rank tracking
Persistent keyword baselines and position movement.
This analysis created the first position baseline at 2026-10-22T09:12:54.464Z. Movement appears after the next fresh analysis using the same location and language.
Features
Features and capabilities
Core functions and evidence-backed product capabilities.
| Capability | What it does |
|---|---|
| Web Scraping API | Fetches public URLs with managed proxy rotation and JavaScript rendering S133. |
| Crawler API | Crawls entire websites with BFS/DFS depth control, anti-bot bypass, and per-page AI extraction S20. |
| Extraction API | Turns HTML into typed data using prompts or JSON schemas S133. |
| Screenshot API | Captures visual page screenshots S1. |
| Hosted MCP Server | Exposes scraping tools to AI agents via natural language tool calls S17. |
| Scrapfly CLI | Provides command-line interface for scraping, testing, and automation S17. |
Integrations and ecosystem
Connected products, exports, APIs, and workflow compatibility.
| Integration or interface | Type | What it enables |
|---|---|---|
| MCP server | AI interface | Connects AI agents to scraping tools via a hosted URL S17. |
| Python SDK | SDK | Provides programmatic access to Scrapfly APIs S20. |
| TypeScript SDK | SDK | Supports Node, Deno, and Bun environments S20. |
| Go SDK | SDK | Enables Go applications to use Scrapfly S20. |
| Rust SDK | SDK | Provides Rust bindings for Scrapfly S20. |
| Webhooks | Webhook | Streams crawl results to endpoints as pages are visited S20. |
| Scrapy extension | Extension | Integrates Scrapfly with Scrapy framework S20. |
| WARC export | Data portability | Exports crawled pages in standard WARC format S20. |
Pricing
Pricing and plans
Published plans, free access, trials, credits, and pricing limitations.
| Plan or offer | Verified price and billing | Included | Limits |
|---|---|---|---|
| Free | $0 per account S1 | 1,000 credits S1 | 5 concurrent requests S1 |
| Discovery | $30 per month, billed monthly; annual billing gives 2 months free S1 | 200,000 credits S1 | 5 concurrent; extra $5 per 10K credits S1 |
| Pro | $100 per month, billed monthly; annual billing gives 2 months free S1 | 1,000,000 credits S1 | 20 concurrent; extra $3.50 per 10K credits S1 |
| Startup | $250 per month, billed monthly; annual billing gives 2 months free S1 | 2,500,000 credits S1 | 50 concurrent; extra $2 per 10K credits S1 |
| Enterprise | $500 per month, billed monthly; annual billing gives 2 months free S1 | 5,500,000 credits S1 | 100 concurrent; extra $1.20 per 10K credits S1 |
| Custom | $1,200 to $30,000+ per month, negotiated S1 | Negotiated S1 | Negotiated S1 |
Competition
Competitive landscape
Domains competing for the same organic search demand.
Sampled competitors
| Competitor | First-page appearances | Sampled queries | Average position | Queries observed |
|---|---|---|---|---|
| medium.com | 2 | 2 | 2.5 | json vs jsonl, jsonl vs json |
| jsonltools.com | 2 | 2 | 5 | json vs jsonl, jsonl vs json |
| stackoverflow.com | 1 | 1 | 1 | json vs jsonl |
| youtube.com | 1 | 1 | 2 | json vs jsonl |
| reddit.com | 1 | 1 | 3 | jsonl vs json |
| python.plainenglish.io | 1 | 1 | 4 | json vs jsonl |
| jsonl.rest | 1 | 1 | 5 | json vs jsonl |
| systoolsgroup.com | 1 | 1 | 5 | jsonl vs json |
| docs.constructor.com | 1 | 1 | 6 | jsonl vs json |
| questdb.com | 1 | 1 | 7 | json vs jsonl |
Website intelligence — Collected evidence
Customers, testimonials, and first-party review claims
No supporting public-page evidence was collected for this category.
Independent review sources discovered
| Platform | Status | Discovered source |
|---|---|---|
| Capterra | discovered_not_scraped | https://www.capterra.com/p/212653/Scrapfly/ |
AI visibility
Measured ChatGPT and Google AI mentions with cited sources.
AI-assistant referral traffic
- Estimated current generative-AI referral share: 1.8%
| Month | Traffic share | Source |
|---|---|---|
| — | — | All AI assistants |
| — | — | All AI assistants |
| — | — | All AI assistants |
Website intelligence — Collected evidence
Site-stated AI capabilities
These are first-party product claims, not independent measurements of AI-search visibility.
Marketing opportunities
Actions calculated directly from the collected evidence.
| Opportunity | Recommended action | Evidence |
|---|---|---|
| Competitor gap | Review the sampled queries where medium.com appears. | 2 first-page appearances across json vs jsonl, jsonl vs json |
Website intelligence — Collected evidence
Website evidence gaps
- customers: no usable public page was collected; verify whether the site publishes this evidence.
- reviews: no usable public page was collected; verify whether the site publishes this evidence.
- changes: no usable public page was collected; verify whether the site publishes this evidence.
- identity: no usable public page was collected; verify whether the site publishes this evidence.
- technical: no usable public page was collected; verify whether the site publishes this evidence.
Trust and proof
Customers, proof, and reviews
Published proof, customer signals, and review evidence.
Independent reviews
| Platform | Page | How it was found | Note |
|---|---|---|---|
| Capterra | Page 3 / Scrapfly Reviews 2026. Verified Reviews, Pros & Cons / Capterra | Grounded web search | I wanted to outsource my webscraping to a high quality tool I could always integrate with and lean on for high quality output. It has proven this for me with no issues at all. Scrapfly has, for me, always provided high quality output and handled all of my webscrapping needs, the ... I’ve been extremely impressed with Scrapfly’s web scraping API. From the start, the platform has been reliable, fast, and easy to integrate into my existing workflow. The documentation is very clear and comprehensive |
| Scraper Reviews | Scrapfly review 2026: prices, limits, 89/100 | Grounded web search | # Scrapfly review 89 of 100, excellent Discovery at $30 for 200,000 credits, printed as $0.15 per 1,000 prepaid, a four-line credit table from 1 to 60, and 1,000 free credits with no card and no time limit. Reviewed 2026-09-18 by Phillip Paul Inker. |
| WebScraping.cc | Scrapfly Review (2026) / WebScraping | Grounded web search | at around 99%, and it has the broadest integration set - official ... mean a $30 plan can quietly cost $100+. Model your real request mix first, then buy. For a bootstrapped five-person team, the product punches far above its size. |
| BestScraperAPI | Scrapfly Review: Features, Pricing & Tests (2026) | Grounded web search | The honest summary is that Scrapfly is strong on anti-bot bypass, transparency, and ... -friendly output, while its variable credit model makes budgeting harder than a flat per-request price. Sentiment below is attributed |
| Toolradar | Scrapfly Reviews, Pricing & Alternatives (2026) / Toolradar | Grounded web search | ## Ratings Across the Web 4.8(332 reviews) Scrapfly holds an aggregate rating of 4.8 out of 5 from 332 reviews across G2 and Capterra, last checked September 17, 2026. G2 94 reviews 4.6/5 Capterra 238 reviews 4.9/5 Ratings aggregated from |
| ScrapeOps | Scrapfly Review / ScrapeOps | Grounded web search | Reviewers consistently praise the platform for its ease of setup, high success rates against anti-bot protections, and thorough documentation. Many users appreciate the responsive customer support and the ability to handle JavaScript rendering. However, reviewers frequently criticize the pricing structure, noting a lack of intermediate plans and high costs for residential proxies. While some find the dashboard helpful for tracking spend, others report that usage transparency and credit consumpti |
| ProxyLook | Scrapfly Review 2026 — Pricing, Pros & Cons · ProxyLook | Grounded web search | No reader reviews yet — be the first below. 4.8 ★★★★★ Editorial rating only Rating distribution will appear once reader reviews come in. ... reviews published yet for Scrapfly. If you've used this provider, share your experience using the form below — |
| Stork.AI | Scrapfly Review (2026): Pricing & Alternatives / Stork.AI | Grounded web search | . - − Some users express a desire for more granular or flexible pricing tiers to better accommodate varying usage patterns. - − While highly effective, occasional edge cases or specific website configurations may present temporary scraping challenges. |
| scrapfly.io | scrapfly.io | Grounded web search | // TESTIMONIALS## Trusted by 30,000+ enterprises. ... Teams pick Scrapfly after testing the alternatives. Here is why they stay. ... “It helped me automate a very difficult task that would have been nearly impossible to complete manually. The performance is consistent, the API responses are fast, and the documentation made integration simple. FA Faten A. AI Specialist Verified Capterra review ... “I use Scrapfly as part of a larger AI research platform for web content extraction and data gatheri |
Customer proof
No named customers, testimonials, or customer case studies were found.
External links were grounded in one live web search. Search snippets are leads, not independently scraped page content; rejected links remain available in Review evidence.
Company, security, and trust
Ownership, policies, security signals, and public trust evidence.
| Signal | Finding | Source |
|---|---|---|
| Company and ownership | Not published on the collected pages. | — |
| Contact and support | Not published on the collected pages. | — |
| Legal and privacy | MSA, DPA, BAA, HIPAA | source |
| Security and compliance | MSA, DPA, BAA, HIPAA | source |
| Uptime and status page | Our users depend on us for production workloads. Uptime and consistency are non-negotiable. | source |
Not found on the collected pages: company and ownership, contact and support. This only means Scout did not find it on the pages it read; it says nothing about the company itself.
Documentation and product updates
Help resources, product guidance, and visible changes over time.
| Resource or update | Type | What is available | Date or freshness |
|---|---|---|---|
| Product FAQ | FAQ | Answers common product, workflow, pricing, privacy, ownership, API, and team questions. (source) | Not dated |
| Scrapfly Documentation / Developer Hub | Documentation | Scrapfly developer hub: Web Scraping, Screenshot, Extraction, Crawler, and Cloud Browser APIs with Python, TypeScript, Go, and Rust SDKs. (source) | Not dated |
| How to Build a Grocery Price Comparison Tool with Python | Guide | Guides, comparisons, pricing breakdowns, use cases, and how-to articles. (source) | Not dated |
| How to Build an Automated Price Tracker with Python Web Scraping | Guide | Guides, comparisons, pricing breakdowns, use cases, and how-to articles. (source) | Not dated |
| How to Build Minimum Advertised Price (MAP) Monitoring Tool | Guide | Guides, comparisons, pricing breakdowns, use cases, and how-to articles. (source) | Not dated |
| How to Track Competitor Prices Using Web Scraping | Guide | Guides, comparisons, pricing breakdowns, use cases, and how-to articles. (source) | Not dated |
Not found in the collected public sources: public roadmap, changelog or release notes, status page, separate help center or knowledge base.
Technical
Technical and delivery signals
Delivery model, platforms, API, data ownership, reliability claims and release activity.
| Signal | Finding | Source |
|---|---|---|
| Delivery model (cloud, self-hosted, desktop, browser extension) | Scrapfly is a cloud-based platform, with a hosted MCP server S17. | S17 |
| Platforms and apps | Web-based APIs and SDKs for Python, TypeScript, Go, and Rust S52. | S52 |
| API and extensibility (API, SDK, webhooks, MCP, plugins) | Offers APIs, SDKs, webhooks, and a hosted MCP server S17 S20. | S17 S20 |
| Data ownership and export | Crawled pages are stored as WARC artifacts, downloadable after completion S20. | S20 |
| Performance and reliability claims | Users depend on Scrapfly for production workloads S1. | S1 |
| Release activity | The team ships daily and deploys multiple times a day S1. | S1 |
Measured infrastructure
Domain, certificate, and hosting signals, measured directly.
| Signal | Finding |
|---|---|
| TLS certificate | Let's Encrypt, valid, expires 2026-12-16 |
| Security headers | HSTS, CSP, X-Content-Type-Options, Referrer-Policy |
| Headers not served | X-Frame-Options |
| Mail handled by | aspmx.l.google.com, alt2.aspmx.l.google.com |
| Nameservers | ns-cloud-d3.googledomains.com, ns-cloud-d4.googledomains.com |
Not measurable: wayback: rate limited by archive.org, ladder stopped after 1 probe(s). A gap here means the lookup was unavailable, not that the finding is negative.
Technical site audit
A bounded multi-page crawl with page-level issues and URLs.
Scout — Bounded technical crawl
- Pages crawled: 15 of 15 maximum
- Technical health: 97/100
- Critical issues: 0
- Warnings: 1
- Notices: 17
Issues
| Severity | Issue | Value | Affected URL |
|---|---|---|---|
| notice | Meta description length should be reviewed | 212 | https://scrapfly.io/ |
| warning | Title length should be reviewed | 67 | https://scrapfly.io/products |
| notice | Meta description length should be reviewed | 211 | https://scrapfly.io/products |
| notice | Images are missing alt text | 1 | https://scrapfly.io/products/web-scraping-api |
| notice | Images are missing alt text | 1 | https://scrapfly.io/products/cloud-browser-api |
| notice | Meta description length should be reviewed | 183 | https://scrapfly.io/products/crawler-api |
| notice | Images are missing alt text | 1 | https://scrapfly.io/products/crawler-api |
| notice | Meta description length should be reviewed | 196 | https://scrapfly.io/products/extraction-api |
| notice | Images are missing alt text | 1 | https://scrapfly.io/products/extraction-api |
| notice | Meta description length should be reviewed | 201 | https://scrapfly.io/products/screenshot-api |
| notice | Images are missing alt text | 1 | https://scrapfly.io/products/screenshot-api |
| notice | Meta description length should be reviewed | 235 | https://scrapfly.io/products/ai-browser-agent |
| notice | Images are missing alt text | 1 | https://scrapfly.io/products/ai-browser-agent |
| notice | Meta description length should be reviewed | 243 | https://scrapfly.io/products/mcp-cloud |
| notice | Images are missing alt text | 1 | https://scrapfly.io/products/mcp-cloud |
| notice | Meta description length should be reviewed | 197 | https://scrapfly.io/products/scrapfly-cli |
| notice | Meta description length should be reviewed | 218 | https://scrapfly.io/products/proxy-saver |
| notice | Images are missing alt text | 1 | https://scrapfly.io/products/proxy-saver |
Crawled pages
| Status | Title | H1s | Words | Response | URL |
|---|---|---|---|---|---|
| 200 | Scrapfly - Web Scraping API, Cloud Browser, Screenshot API | 1 | 2906 | 154 ms | https://scrapfly.io/ |
| 200 | Scrapfly Products: Web Scraping, Cloud Browser, Crawler, Extraction | 1 | 1336 | 93 ms | https://scrapfly.io/products |
| 200 | Web Scraping API: The Scraper API With a 98% Success Rate | 1 | 3742 | 148 ms | https://scrapfly.io/products/web-scraping-api |
| 200 | Cloud Browser API for Browser Automation \ | Scrapfly | 1 | 3628 | 362 ms |
| 200 | Web Crawler API for Full-Site Crawls \ | Scrapfly | 1 | 3041 | 114 ms |
| 200 | Data Extraction API for Structured JSON \ | Scrapfly | 1 | 3274 | 613 ms |
| 200 | Screenshot API for Protected Web Pages \ | Scrapfly | 1 | 3211 | 87 ms |
| 200 | Scrapfly Pricing: Web Scraping API Plans, 1,000 Free Credits | 1 | 2228 | 56 ms | https://scrapfly.io/pricing |
| 200 | Scrapfly Documentation \ | Developer Hub | 1 | 971 | 47 ms |
| 200 | AI Browser Agent for Web Automation \ | Scrapfly | 1 | 2780 | 52 ms |
| 200 | Hosted Browser MCP Server for AI Agents \ | Scrapfly | 1 | 2824 | 109 ms |
| 200 | Web Scraping CLI for Shell and CI \ | Scrapfly | 1 | 1947 | 66 ms |
| 200 | Proxy Saver for Existing Proxy Accounts \ | Scrapfly | 1 | 2707 | 59 ms |
| 200 | Scrapfly Web Scraping API \ | Python SDK | 1 | 3219 | 49 ms |
| 200 | Scrapfly Web Scraping API \ | Typescript SDK | 1 | 3380 | 41 ms |
This is a bounded Scout crawl. Core Web Vitals and Lighthouse scores are not claimed unless a dedicated performance audit is connected.
Search Console and Analytics
First-party search and behavioral data connection state.
Modeled acquisition channels
| Channel | Estimated share |
|---|---|
| direct | 20.6% |
| search | 62.3% |
| search organic | 62.3% |
| search paid | 0.0% |
| social | 5.9% |
| social organic | 5.9% |
| social paid | 0.0% |
| referrals | 8.9% |
| paid referrals | 0.2% |
| 0.3% | |
| gen ai | 1.8% |
| affiliate | 0.0% |
| other | 0.0% |
First-party connections
| Integration | Status | Data available after connection |
|---|---|---|
| Google Search Console | Not connected | Clicks, impressions, CTR, average position, queries, pages, countries, and devices |
| Google Analytics | Not connected | Organic sessions, engagement, landing pages, conversions, geography, and devices |
No first-party Search Console or Analytics numbers are shown until the site owner authorizes the corresponding Google account. Scout traffic model values above are modeled estimates, not private analytics totals.
Limits and method
Limitations and open questions
Known constraints and missing evidence from the collected pages.
The collected pages do not mention specific competitors. Evidence gaps include lack of detailed security and compliance certifications, uptime statistics, and independent review profiles. Pricing details for custom plans are not fully specified. The platform's proprietary components are described but not independently verified.
Sources, method, and limitations
Evidence inventory, collection method, provider use, and constraints.
This report is based on 15 collected pages from scrapfly.io, including product pages, documentation, and the About page. The evidence catalog includes 15 pages with static and browser rendering rendering, plus a sitemap of 500 URLs. External proof search was performed but no additional verification was completed. Limitations: some sections rely on marketing claims, and external review profiles were not scraped.
- Documentationhttps://scrapfly.io/Verified
- Official Websitehttps://scrapfly.io/about-usVerified
- Official Websitehttps://scrapfly.io/productsVerified
- Official Websitehttps://scrapfly.io/products/mcp-cloudVerified
- Documentationhttps://scrapfly.io/products/crawler-apiVerified
- Documentationhttps://scrapfly.io/docsVerified
- Pricing Pagehttps://scrapfly.io/pricingVerified
- Pricing Pagehttps://scrapfly.io/blog/posts/competitor-price-monitoring-with-crawler-apiVerified
- Pricing Pagehttps://scrapfly.io/blog/posts/how-to-build-a-grocery-price-comparison-tool-with-pythonVerified
- Pricing Pagehttps://scrapfly.io/blog/posts/how-to-build-a-price-tracker-in-pythonVerified
- Pricing Pagehttps://scrapfly.io/blog/posts/how-to-build-minimum-advertised-price-monitoring-toolVerified
- Pricing Pagehttps://scrapfly.io/blog/posts/how-to-track-competitor-pricing-using-web-scrapingVerified
- Pricing Pagehttps://scrapfly.io/blog/posts/visual-ecommerce-price-monitoring-with-automated-screenshotsVerified
- Official Websitehttps://scrapfly.io/blog/posts/best-ecommerce-product-data-apisVerified
- Official Websitehttps://scrapfly.io/blog/posts/how-to-build-a-product-data-pipeline-from-multiple-ecommerce-sitesVerified
- Review Sitehttps://www.capterra.com/p/212653/Scrapfly/reviews/?page=3Verified
- Review Sitehttps://scraper-reviews.com/scrapers/scrapflyVerified
- Review Sitehttps://webscraping.cc/tool/scrapfly/Verified
- Review Sitehttps://bestscraperapi.com/guides/scrapfly-reviewVerified
- Review Sitehttps://toolradar.com/tools/scrapflyVerified
- Review Sitehttps://scrapeops.io/proxy-providers/scrapfly/Verified
- Review Sitehttps://proxylook.com/providers/scrapflyVerified
- Review Sitehttps://www.stork.ai/en/scrapflyVerified