In simple English
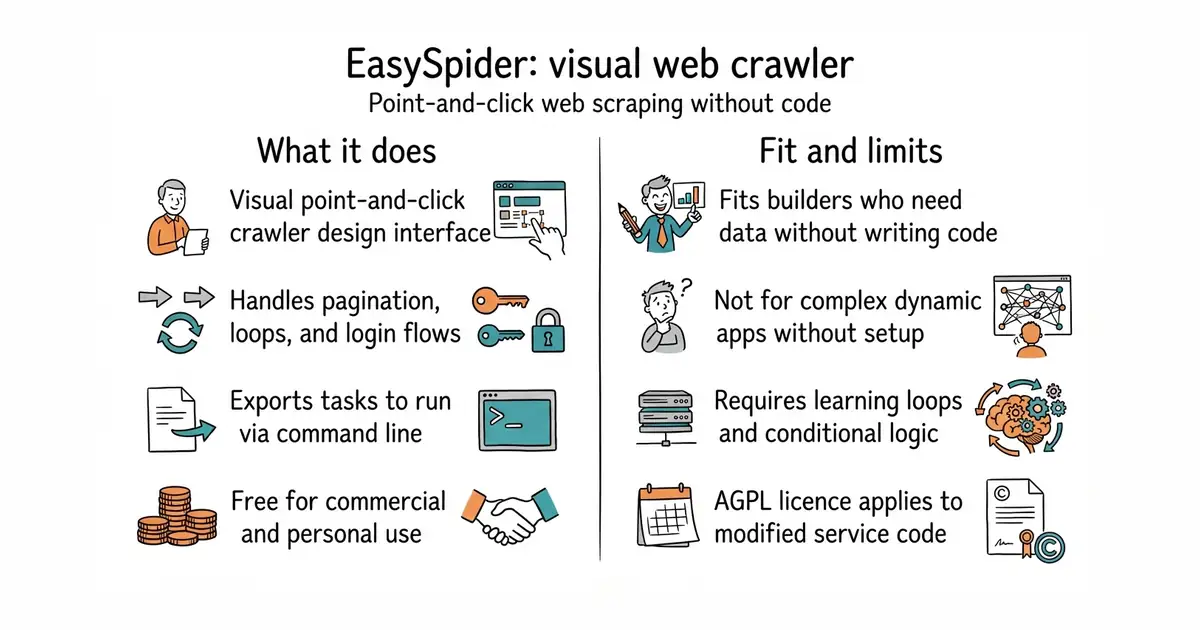
You can pull data from websites without writing any code. You click on the elements you want on a webpage, and the software builds a scraper for you. It runs on your computer and can handle complex tasks like clicking buttons, turning pages, and logging in. The software is completely free to use, even for business purposes. You might spend a few hours learning the visual interface if you have never built a crawler before.
What it is
A visual web scraping tool with a graphical interface that lets you design and run browser automation tasks without writing code. It can also run through a command-line interface (a text-based way to give instructions to your computer) so you can embed it into other programs.
What it is good for
Solo builders who need to collect data from websites for market research or content creation without spending days writing scraping scripts.
- Completely free for personal and commercial use with no hidden costs.
- Visual point-and-click design makes web scraping accessible without programming.
- Can export tasks to run via command line for integration into other systems.
- Steep learning curve for understanding loops, conditions, and complex page flows.
- AGPL-3.0 licence means if you modify the code and offer it as a web service, you must make your changes public.
- Running many browser automation tasks at once requires a computer with plenty of memory and processor power.
Writing custom Python or JavaScript scraping scripts from scratch.
CapSolver (to automatically solve captchas during scraping tasks).
- apify/crawlee26k stars
A web scraping and browser automation library for JavaScript and Python developers who prefer writing code.

- cybertec-postgresql/pg_timetable1.4k stars
A job scheduler for PostgreSQL whose jobs and schedules live in the database itself.
- PrefectHQ/prefect24k stars
Adds scheduling, retries and a run history to Python functions you already have.
Download the latest release for your operating system directly from the GitHub Releases page and run the application.