Overview
Summary
The useful answer before the supporting detail.
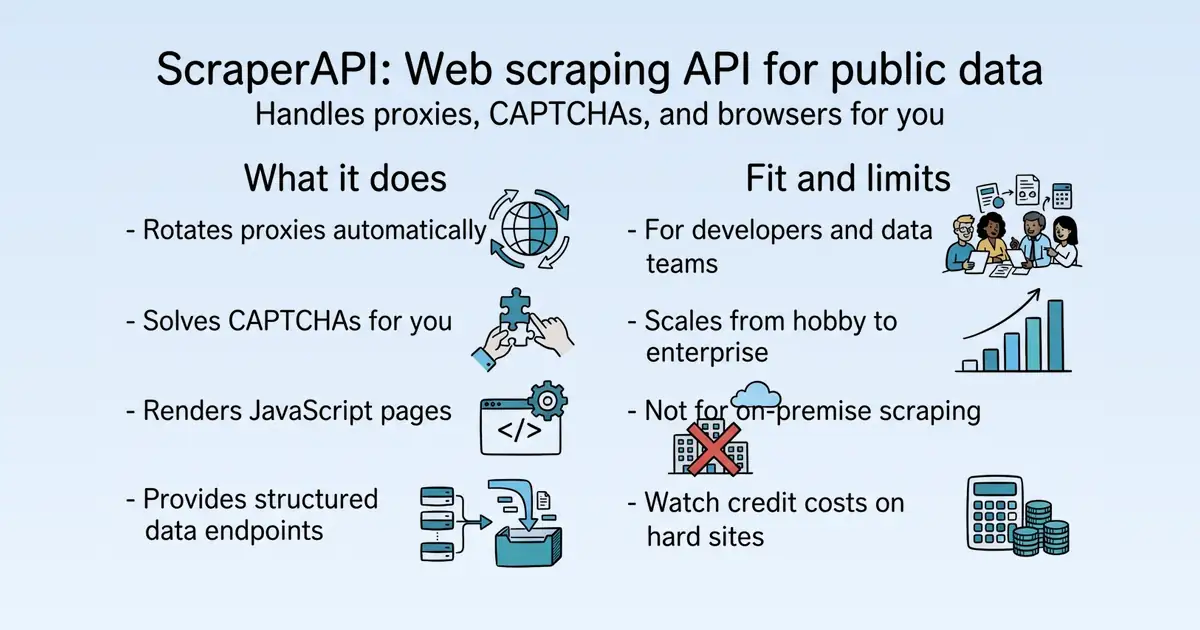
ScraperAPI is a web scraping API that lets you collect data from any public website without worrying about proxies, browsers, or CAPTCHAs S40. It is used by thousands of businesses, from startups to enterprise-level companies, to harvest publicly available data on the internet S1. The service handles proxy rotation, CAPTCHA solving, and browser rendering, so teams can focus on using the data rather than maintaining scraping infrastructure S1.
Product identity and positioning
Name, category, positioning, audience, and first-party claims.
- Identity: ScraperAPI is a web scraping API and data collection infrastructure S40 S16.
- Core purpose: It solves the problem of IP blocks, CAPTCHAs, and browser management in automated web scraping S40 S1.
- Intended users: Developers and businesses that need to collect public web data at scale S1.
- Product scope: It is a cloud-based API service, not a desktop app or browser extension; it includes a scraping API, async scraper, structured data endpoints, and a data pipeline S16.
- Positioning: The vendor positions it as a simple API that handles the hard parts of scraping, with a generous free tier S40.
- Claimed distinction: It claims to handle anti-bot bypass for major protections like Cloudflare, DataDome, and PerimeterX S17 S16.
Use cases and audiences
Who the product serves and the jobs it is designed to handle.
| Audience | Practical use case |
|---|---|
| E-commerce intelligence platforms | Track price changes, seller shifts, and product availability at scale, with zip-code geotargeting to match local shoppers S120. |
| SEO agencies | Monitor keyword rankings, ads, and SERP data for target keywords S40. |
| Market researchers | Collect user-generated content like reviews and forum discussions to understand customer needs S138. |
| Real estate platforms | Automate property listing data collection from sites like Redfin and Zillow S40 S138. |
| AI and ML teams | Scrape millions of web pages without interruptions to train models with accurate and updated data S138. |
Traffic and search
SEO analysis
Collected Oct 22, 2026scraperapi.com: an estimated 180,514 total monthly visits and about 16,708 monthly organic visits across 2,355 ranking keywords. Scout crawled 15 pages and measured a technical health score of 98/100.
Search summary
The useful answer before the supporting detail.
ScraperAPI is a web scraping API that lets you collect data from any public website without worrying about proxies, browsers, or CAPTCHAs. scraperapi.com: an estimated 180,514 total monthly visits and about 16,708 monthly organic visits across 2,355 ranking keywords. Scout crawled 15 pages and measured a technical health score of 98/100.
- Total traffic (modeled): 180,514 monthly visits across all channels.
- Organic search traffic (estimated): 16,708 monthly visits from search.
- Strongest sampled ranking: scraper api at position 1.
- Leading page in the collected evidence: https://www.scraperapi.com/.
- Closest measured organic competitor: simplescraper.io, appearing 1 times in the sampled first-page SERPs.
- Technical crawl: 15 pages, health score 98/100.
Website intelligence — Collected evidence
Company identity and positioning
| Page type | Evidence | Source |
|---|---|---|
| integrations | ScraperAPI is a web scraping API that lets you collect data from any public website without worrying about proxies, browsers, or CAPTCHAs. | https://www.scraperapi.com/ |
| features | Plug-and-play solution to scale your web scrapers with a simple get request. Automatically handle proxies, CAPTCHAs, JS rendering, and more. | https://www.scraperapi.com/solutions/ |
| features | Build and automate recurrent scraping jobs using a visual interface or our dedicated endpoints, speeding up development speed for large projects. | https://www.scraperapi.com/solutions/ |
| features | ](https://www.scraperapi.com/solutions/data-acquisition-for-enterprise/)[ | https://www.scraperapi.com/solutions/ |
| features | Collect fresh SERP data for your target keywords and feed your own tools and dashboards. | https://www.scraperapi.com/solutions/ |
| features | Scrape Walmart search results for thousands of search terms and get product data in JSON. | https://www.scraperapi.com/solutions/ |
| features | Monitor eBay search results for all your target search queries without getting blocked. | https://www.scraperapi.com/solutions/ |
| features | Redfin 'For Rent' Scraper | https://www.scraperapi.com/solutions/ |
| features | Redfin 'For Sale' Scraper | https://www.scraperapi.com/solutions/ |
| features | Turn Redfin property for sale pages into ready-to-use JSON or CSV data with just their URL. | https://www.scraperapi.com/solutions/ |
| features | ScraperAPI helps companies across multiple industries collect and leverage data at scale. | https://www.scraperapi.com/solutions/ |
| features | Gather user-generated content like reviews, forum discussions, etc., to understand your potential customers’ needs and wants more deeply. | https://www.scraperapi.com/solutions/ |
Domain performance
Modeled total traffic, six-month trend, engagement, countries, and domain identity.
Total website traffic
| Month | Modeled visits |
|---|---|
| 2026-04 | 322,245 |
| 2026-05 | 315,230 |
| 2026-06 | 250,937 |
| 2026-07 | 235,663 |
| 2026-08 | 213,948 |
| 2026-09 | 180,514 |
Top visitor countries
| Country | Name | Traffic share |
|---|---|---|
| US | United States | 19.4% |
| IN | India | 11.9% |
| GB | United Kingdom | 8.5% |
| BR | Brazil | 4.7% |
| ES | Spain | 2.9% |
Domain identity
| Signal | Value |
|---|---|
| Registered | May 14, 2018 |
| Last changed | Apr 14, 2026 |
| Expires | May 14, 2027 |
| WHOIS server | whois.verisign-grs.com |
| DNSSEC | Not signed |
| Nameservers | NS1.DIGITALOCEAN.COM, NS2.DIGITALOCEAN.COM, NS3.DIGITALOCEAN.COM |
Website capture
Organic keywords
Top keywords and an independent Google result page.
Top organic keywords
| Keyword | Volume | CPC | Estimated value |
|---|---|---|---|
| scraperapi | 13,340 | $8.94 | $10,530 |
| scraper api | 3,520 | $6.22 | $2,390 |
| serper | 38,300 | $2.52 | $640 |
| free proxy | 22,270 | $0.55 | $370 |
| scraping api | 760 | $0.00 | $350 |
Independent Google result page
Query: scraper api
| Position | Title | URL | Description |
|---|---|---|---|
| 1 | ScraperAPI: Scale Data Collection with a Simple Web ... | https://www.scraperapi.com/ | ScraperAPI is a web scraping API that lets you collect data from any public website without worrying about proxies, browsers, or CAPTCHAs. |
| 2 | Web Scraping API – Free Plan, 100+ Templates | https://decodo.com/scraping/web | A web scraping API is a service that fetches web pages for you and returns their content as structured data. You send a URL, and the API takes care of proxies, ... |
| 3 | ScrapingBee – The Best Web Scraping API | https://www.scrapingbee.com/ | ScrapingBee is the best web scraping API that handles proxies and headless browsers for you — so you can focus on extracting the data you need. |
| 4 | Scraper APIs Make Your Life Easier... | https://www.youtube.com/watch?v=mGERI9hpW6k | In this video we explore the modern way of Web Scraping, which is using Scraper APIs. No proxies or custom scrapers. No manual maintenance. |
| 5 | Firecrawl | Web Data API for AI Agents | https://www.firecrawl.dev/ | Firecrawl is not just a scraper or a search API — it's the infrastructure layer that helps AI systems find, read, and act on information across the live web. |
| 6 | Web Scraper API | https://api-ninjas.com/api/webscraper | The Web Scraper API provides web scraper services to retrieve HTML and plaintext data from any website URL. |
| 7 | Web Scraping API - 5K Records/Month for Free | https://brightdata.com/products/web-scraper | Web Scraper API to seamlessly scrape web data. No-code interface for rapid development, no proxy management needed. 1000+ ready-made scrapers. |
| 8 | Web API for AI Agents & Data Collection | https://oxylabs.io/products/web-api/scrape | A web scraping API is a tool that collects data from websites and returns it in a structured, ready-to-use format. |
| 9 | Social Media Scraping API | https://scrapecreators.com/ | ScrapeCreators is a social media scraping API for developers. Get real-time data from TikTok, Instagram, YouTube, Facebook, X, and more. |
| 10 | ScraperAPI | https://www.linkedin.com/company/scraperapi | Unlock and scrape any website, no matter the scale or difficulty, with ScraperAPI. We've worked on large-scale projects and helped hundreds of data-focused ... |
Important pages
Pages earning the most estimated search traffic in the sample.
Website intelligence — Collected evidence
Prioritized website intelligence pages
| Type | Page | Words | Change | URL |
|---|---|---|---|---|
| integrations | ScraperAPI: Scale Data Collection with a Simple Web Scraping API | 884 | new | https://www.scraperapi.com/ |
| pricing | Compare Plans and Get Started for Free - ScraperAPI Pricing | 1,153 | new | https://www.scraperapi.com/pricing/ |
| pricing | Compare Plans and Get Started for Free - ScraperAPI Pricing | 409 | new | https://www.scraperapi.com/pricing-new-v1/ |
| pricing | Web Scraping Pricing: Choosing the Right Solution | 4,101 | new | https://www.scraperapi.com/blog/web-scraping-pricing-and-choosing-the-right-solution/ |
| pricing | Price Monitoring and Scraping with ScraperAPI | 1,918 | new | https://www.scraperapi.com/solutions/price-monitoring/ |
| features | Web Scraping Solutions \ | static | 2,505 | new |
| features | AI Web Scraping for Agents & Automated Workflows \ | static | 1,455 | new |
| features | Scalable Data Collection Tool for AI Models and LLMs - ScraperAPI | 1,998 | new | https://www.scraperapi.com/solutions/ai-data/ |
| features | Airbnb Scraper: Real-Time Property Data Extraction | 1,605 | new | https://www.scraperapi.com/solutions/airbnb-scraper/ |
| features | AliExpress Scraper: Real-Time Product Listing Extraction | 1,478 | new | https://www.scraperapi.com/solutions/aliexpress-scraper/ |
| features | Amazon Best Seller Scraper: Real-Time Best Seller Product Data Extraction | 1,942 | new | https://www.scraperapi.com/solutions/amazon-best-seller-scraper/ |
Features
| Page type | Evidence | Source |
|---|---|---|
| features | ScraperAPI has acquired Traject Data | https://www.scraperapi.com/solutions/ |
| features | READ THE ANNOUNCEMENT | https://www.scraperapi.com/solutions/ |
| features | 0 | https://www.scraperapi.com/solutions/ |
| features | CUSTOM TRIAL | https://www.scraperapi.com/solutions/ |
| features | Login | https://www.scraperapi.com/solutions/ |
| features | Start Free | https://www.scraperapi.com/solutions/ |
| features | The perks of using ScraperAPI. Get to know our solutions in detail, and see how they can support your web scraping needs. | https://www.scraperapi.com/solutions/ |
| features | Products Structured Endpoints Industries Use Cases Target Site | https://www.scraperapi.com/solutions/ |
| features | Tools and APIs | https://www.scraperapi.com/solutions/ |
| features | Integrate ScraperAPI with your infrastructure, or use our low-code solutions to automate entire web scraping projects. | https://www.scraperapi.com/solutions/ |
| features | Scraping API | https://www.scraperapi.com/solutions/ |
| features | Plug-and-play solution to scale your web scrapers with a simple get request. Automatically handle proxies, CAPTCHAs, JS rendering, and more. | https://www.scraperapi.com/solutions/ |
| features | ](https://www.scraperapi.com/solutions/scraping-api/)[ | https://www.scraperapi.com/solutions/ |
| features | Structured Data Endpoints (SDEs) | https://www.scraperapi.com/solutions/ |
| features | Turn popular domains into ready-to-use JSON or CSV data with dedicated APIs. Let us take care of parsing and focus on insights. | https://www.scraperapi.com/solutions/ |
| features | ](https://www.scraperapi.com/solutions/structured-data/)[ | https://www.scraperapi.com/solutions/ |
| features | Async Scraper | https://www.scraperapi.com/solutions/ |
| features | Submit millions of scraping jobs and let ScraperAPI handle them asynchronously, using the most advanced bot bypassing techniques. | https://www.scraperapi.com/solutions/ |
| features | ](https://www.scraperapi.com/solutions/asynchronous-scraper-service/) | https://www.scraperapi.com/solutions/ |
| features | DataPipeline | https://www.scraperapi.com/solutions/ |
Pricing and plans
Integrations and supported platforms
| Page type | Evidence | Source |
|---|---|---|
| integrations | ScraperAPI has acquired Traject Data | https://www.scraperapi.com/ |
| integrations | READ THE ANNOUNCEMENT | https://www.scraperapi.com/ |
| integrations | 0 | https://www.scraperapi.com/ |
| integrations | CUSTOM TRIAL | https://www.scraperapi.com/ |
| integrations | Login | https://www.scraperapi.com/ |
| integrations | Start Free | https://www.scraperapi.com/ |
| integrations | Scale Data Collection with a Simple API | https://www.scraperapi.com/ |
| integrations | Collect data from any public website with our web scraping API, without worrying about proxies, browsers, or CAPTCHA handling. | https://www.scraperapi.com/ |
| integrations | GET CUSTOM TRIAL | https://www.scraperapi.com/ |
| integrations | Start Free | https://www.scraperapi.com/ |
| integrations | Join the 10,000+ data-focused companies using ScraperAPI | https://www.scraperapi.com/ |
| integrations | Data Collection Solutions | https://www.scraperapi.com/ |
| integrations | Designed for Scalability and Consistency | https://www.scraperapi.com/ |
| integrations | Our scraping APIs and low-code tools help you unlock and scrape any website, no matter the scale or difficulty. | https://www.scraperapi.com/ |
| integrations | Scraping API | https://www.scraperapi.com/ |
| integrations | Plug-and-play solution to scale your web scrapers. | https://www.scraperapi.com/ |
| integrations | Learn more | https://www.scraperapi.com/ |
| integrations | Structured Endpoints | https://www.scraperapi.com/ |
| integrations | Get structured data from popular domains. | https://www.scraperapi.com/ |
| integrations | Learn more | https://www.scraperapi.com/ |
Product and company updates
No supporting public-page evidence was collected for this category.
Rank tracking
Persistent keyword baselines and position movement.
This analysis created the first position baseline at 2026-10-22T09:15:06.711Z. Movement appears after the next fresh analysis using the same location and language.
Features
Features and capabilities
Core functions and evidence-backed product capabilities.
| Capability | What it does |
|---|---|
| Proxy rotation | Automatically rotates IPs from a large pool to avoid blocks S1 S16. |
| CAPTCHA handling | Automatically solves CAPTCHAs on target sites S1 S17. |
| JavaScript rendering | Renders pages that require JavaScript to display content S1 S17. |
| Geotargeting | Routes requests through proxies in specific geographic locations, including zip-code level for some plans S17 S120. |
| Structured data endpoints | Provides pre-built endpoints for sites like Amazon, Google, Walmart, and eBay, returning JSON or CSV S16 S110. |
| Async scraping | Allows you to submit scraping jobs that run in the background and retrieve results later S1 S16. |
| DataPipeline | A no-code/low-code tool for scheduling recurring scraping jobs with structured output S16. |
| AI agent integration | Offers an MCP server, AI modelCode Agent Skills plugin, and LangChain/LlamaIndex integrations S16. |
Integrations and ecosystem
Connected products, exports, APIs, and workflow compatibility.
| Integration or interface | Type | What it enables |
|---|---|---|
| MCP server | AI interface | Provides 22 tools for AI agents to scrape and extract data S16. |
| AI modelCode Agent Skills plugin | AI interface | Adds 5 workflow recipes for scraping tasks in AI modelCode S16. |
| LangChain / LlamaIndex | Integration | Allows use of ScraperAPI within LangChain and LlamaIndex workflows S16. |
| n8n community node | Integration | Enables scraping automation in n8n workflows S16. |
| Zapier | Integration | Connects ScraperAPI to thousands of apps for automated data collection S16. |
| SDKs | SDK | Provides Python, Node, PHP, Ruby, Java, and cURL support for API integration S16. |
| Structured Data Endpoints | API | Offers pre-built endpoints for Amazon, Google, Walmart, eBay, and more S16. |
Pricing
Pricing and plans
Published plans, free access, trials, credits, and pricing limitations.
| Plan or offer | Verified price and billing | Included | Limits |
|---|---|---|---|
| Free trial | 7-day trial with 5,000 API credits, no credit card required S83 | 5,000 API credits | Not established |
| Hobby | $49 per month, billed monthly; yearly billing 10% off S17 | 100,000 API credits S17 | 20 concurrent threads, US and EU geotargeting S17 |
| Startup | $149 per month, billed monthly; yearly billing 10% off S17 | 1,000,000 API credits S17 | 50 concurrent threads, US and EU geotargeting S17 |
| Business | $299 per month, billed monthly; yearly billing 10% off S17 | 3,000,000 API credits S17 | 100 concurrent threads, global geotargeting S17 |
| Scaling | $475 per month, billed monthly; yearly billing 10% off S17 | 5,000,000 API credits S17 | 200 concurrent threads, pay-as-you-go available S17 |
| Professional | $975 per month, billed monthly; yearly billing 10% off S17 | 10,500,000 API credits S17 | 300 concurrent threads, priority support S17 |
| Advanced | $1,975 per month, billed monthly; yearly billing 10% off S17 | 21,500,000 API credits S17 | 500 concurrent threads, priority routing S17 |
| Enterprise | Custom pricing S17 | 22,000,000+ API credits S17 | 500+ concurrent threads, dedicated team, Slack support S17 |
Competition
Competitive landscape
Domains competing for the same organic search demand.
Sampled competitors
| Competitor | First-page appearances | Sampled queries | Average position | Queries observed |
|---|---|---|---|---|
| simplescraper.io | 1 | 1 | 1 | scraper api |
| decodo.com | 1 | 1 | 1 | scrape amazon reviews |
| zenrows.com | 1 | 1 | 2 | scraper api |
| blog.apify.com | 1 | 1 | 2 | scrape amazon reviews |
| trustpilot.com | 1 | 1 | 3 | scraper api |
| youtube.com | 1 | 1 | 3 | scrape amazon reviews |
| scrapingdog.com | 1 | 1 | 4 | scraper api |
| reddit.com | 1 | 1 | 4 | scrape amazon reviews |
| apify.com | 1 | 1 | 5 | scraper api |
| octoparse.com | 1 | 1 | 5 | scrape amazon reviews |
Website intelligence — Collected evidence
Customers, testimonials, and first-party review claims
No supporting public-page evidence was collected for this category.
Independent review sources discovered
| Platform | Status | Discovered source |
|---|---|---|
| Capterra | discovered_not_scraped | http://www.capterra.com/p/238595/Scraper-API/ |
AI visibility
Measured ChatGPT and Google AI mentions with cited sources.
AI-assistant referral traffic
- Estimated current generative-AI referral share: 3.3%
| Month | Traffic share | Source |
|---|---|---|
| — | — | All AI assistants |
| — | — | All AI assistants |
| — | — | All AI assistants |
Website intelligence — Collected evidence
Site-stated AI capabilities
| Page type | Evidence | Source |
|---|---|---|
| features | Web Scraping for AI Agents and Automated Workflows | https://www.scraperapi.com/solutions/ai/ |
| features | Track prices across Amazon, Walmart, and competitor sites automatically. Your workflow pulls live data on a schedule, flags changes, and provides data for AI agents to summarize trends and identify pricing opportunities. | https://www.scraperapi.com/solutions/ai/ |
| features | For the terminal | https://www.scraperapi.com/solutions/ai/ |
| features | For MCP clients | https://www.scraperapi.com/solutions/ai/ |
| features | For RAG and indexing | https://www.scraperapi.com/solutions/ai/ |
| features | For Python developers | https://www.scraperapi.com/solutions/ai/ |
| features | For Claude Code and Cowork | https://www.scraperapi.com/solutions/ai/ |
| features | For Zapier workflows | https://www.scraperapi.com/solutions/ai/ |
| features | Collect High Quality Data for AI Models and LLMs at Scale | https://www.scraperapi.com/solutions/ai-data/ |
| features | Collect Data for AI Models | https://www.scraperapi.com/solutions/ai-data/ |
| features | AI & Automation | https://www.scraperapi.com/solutions/ |
| features | Give your AI agents and automation tools access to live data. Add real-time web access, geo-targeted scraping, and clean JSON/markdown outputs without building infrastructure. | https://www.scraperapi.com/solutions/ |
| features | ](https://www.scraperapi.com/solutions/ai/) | https://www.scraperapi.com/solutions/ |
| features | Web Scraping for AI Agents and Automated Workflows | https://www.scraperapi.com/solutions/ai/ |
| features | AI is only as good as the data it can reach. ScraperAPI turns any public URL into clean, structured data, handling the proxies, headless browsers, and CAPTCHAs so you can focus on building. Feed RAG pipelines and training sets through MCP, CLI, LangChain, and LlamaIndex, or power no-code workflows in Claude, n8n, and Zapier. | https://www.scraperapi.com/solutions/ai/ |
| features | Track prices across Amazon, Walmart, and competitor sites automatically. Your workflow pulls live data on a schedule, flags changes, and provides data for AI agents to summarize trends and identify pricing opportunities. | https://www.scraperapi.com/solutions/ai/ |
| features | Pull competitor pages, news sources, and industry sites automatically. Your AI works with structured, current data, not manual searches or stale exports. | https://www.scraperapi.com/solutions/ai/ |
| features | One reliable web scraping layer between the open web and your AI agents and workflows. | https://www.scraperapi.com/solutions/ai/ |
| features | LLM and Agent integrations | https://www.scraperapi.com/solutions/ai/ |
| features | CLI | https://www.scraperapi.com/solutions/ai/ |
These are first-party product claims, not independent measurements of AI-search visibility.
Marketing opportunities
Actions calculated directly from the collected evidence.
| Opportunity | Recommended action | Evidence |
|---|---|---|
| Competitor gap | Review the sampled queries where simplescraper.io appears. | 1 first-page appearances across scraper api |
Website intelligence — Collected evidence
Website evidence gaps
- customers: no usable public page was collected; verify whether the site publishes this evidence.
- reviews: no usable public page was collected; verify whether the site publishes this evidence.
- changes: no usable public page was collected; verify whether the site publishes this evidence.
- identity: no usable public page was collected; verify whether the site publishes this evidence.
- technical: no usable public page was collected; verify whether the site publishes this evidence.
Trust and proof
Customers, proof, and reviews
Published proof, customer signals, and review evidence.
Independent reviews
| Platform | Page | How it was found | Note |
|---|---|---|---|
| Trustpilot | ScraperAPI Reviews / Read Customer Service Reviews of www.scraperapi.com | Grounded web search | 42 ... 4.5 ... ## Misleading, contradictory, and unprofessional — terrible experience with ScraperAPI Misleading, contradictory, and unprofessional — terrible experience with ScraperAPI We’ve worked with ScraperAPI for years, but our recent experience has been shockingly bad. Misrepresentation of terms: We were quoted $3,600 for 60M credits at 1 credit per Amazon request. After paying, they applied a 5-credit multiplier without ever disclosing this upfront, which meant our 60M plan was only wort |
| Capterra | ScraperAPI Software Pricing, Alternatives & More 2026 / Capterra | Grounded web search | Overall rating Based on 62 user reviews 4.6 Reviews sentiment Positive 92% Neutral 5% Negative 3% ... ## User reviews How are reviews collected? Overall rating 4.6 Based on 62 reviews Filter by rating 5(46) 4(11) 3(3) 2(1) 1(1) |
| ToolRadar | ScraperAPI Reviews, Pricing & Alternatives (2026) - 4.5/5 | Grounded web search | ## Ratings Across the Web 4.5(77 reviews) ScraperAPI holds an aggregate rating of 4.5 out of 5 from 77 reviews across G2 and Capterra, last checked September 17, 2026. G2 15 reviews 4.3/5 Capterra 62 reviews 4.6/5 Ratings aggregated from independent |
| ShouldIUse | ScraperAPI Review 2026: Pricing & Pros / Should I Use It | Grounded web search | ## What users say Ratings land at 4.3/5 on G2 and 8.0/10 on GetApp with ease-of-use praise, but some Trustpilot reviewers call the company's communication misleading. > “ScraperAPI: The Reliable Veteran” Reddit, r/PrivatePackets |
| CostBench | ScraperAPI Hidden Costs 2026: True Cost Breakdown / CostBench | Grounded web search | complex or protected targets such as Amazon apply a per-request credit multiplier. One verified ... to Amazon requests post-purchase — a $3,600 plan sold as 60M credits at 1 credit per Amazon request was reduced to only 12M effective Amazon requests. The |
| scraperapi.com | ScraperAPI: Scale Data Collection with a Simple Web Scraping API | Grounded web search | One of the most frustrating parts of automated web scraping is constantly dealing with IP blocks and CAPTCHAs. ScraperAPI gets this task off of your shoulders. based on 50+ reviews The team at ScraperAPI was so patient in helping us debug our first |
Customer proof
No named customers, testimonials, or customer case studies were found.
Independent mentions
- ScraperAPI — # ScraperAPI ... - Login: scraperapi - Blog: https://www.scraperapi.com/ - Email: support@scraperapi.com - Public repos: 22 - Followers: 47 - Created: 2019-01-26T23:18:06Z ## Top Repositories ... - scraperapi/scraperapi-code-examples - Code examples on how to integrate various types of scrapers with Scraper API. (31 stars) - scraperapi/scraperapi-skills - ScraperAPI's Agent Skills. (9 stars) - scraperapi/langchain-scraperapi - (7 stars) - scraperapi/scraperapi-mcp - This MCP server enables LLMs
- gzr07932/scraperapi-pricing-analysis — now serves over 10,000 brands — including Deloitte, Sony, and Alibaba — and processes around 36 billion API requests ... On Capterra, it holds a 4.6/5 rating (with a 4.9/5 on ease of use, which tells you something about the onboarding experience
- ScraperAPI vs Zyte - Compared on Price and Features — request Cons - - Credits are not requests - JS rendering costs 5-10 credits each - - Search-engine requests cost 25 credits, e-commerce 5 - - Independent benchmarks put real success around 62-64% - - Weak on Cloudflare and DataDome - can return 500s on
External links were grounded in one live web search. Search snippets are leads, not independently scraped page content; rejected links remain available in Review evidence.
Company, security, and trust
Ownership, policies, security signals, and public trust evidence.
| Signal | Finding | Source |
|---|---|---|
| Company and ownership | ScraperAPI is a popular web scraping tool founded in 2018. | source |
| Contact and support | Refund policy: 7-day no-questions-asked refund. Contact support@scraperapi.com. | source |
| Legal and privacy | CCPA & GDPR compliant | source |
| Security and compliance | Not published on the collected pages. | — |
| Uptime and status page | 99.9% Uptime Guarantee | source |
| Domain registered | 2018-05-14 | — |
| Domain expires | 2027-05-14 | — |
Not found on the collected pages: security and compliance. This only means Scout did not find it on the pages it read; it says nothing about the company itself.
Documentation and product updates
Help resources, product guidance, and visible changes over time.
| Resource or update | Type | What is available | Date or freshness |
|---|---|---|---|
| ScraperAPI -- AI Knowledge Index | Documentation | Documentation is publicly available. (source) | Not dated |
| How to Build an eBay Price Checker with Node.js | Guide | Increase sales and optimize profits by monitoring your competitors' prices on eBay using Node.js and ScraperAPI. Ready-to-use code inside! (source) | Not dated |
| How to Scrape Google Hotel Prices with Node.js | Guide | Guides, comparisons, pricing breakdowns, use cases, and how-to articles. (source) | Not dated |
| ScraperAPI -- Pricing and Credits (AI Grounding) | Documentation | Documentation is publicly available. (source) | Not dated |
| How to Scrape AliExpress Product Listing Data (Easy Guide) | Guide | Learn how to build a Python-based AliExpress web scraper to extract product details at scale, including product names, descriptions, reviews, pricing, and more. (source) | Not dated |
| How to Scrape Target.com Product Data | Guide | Guides, comparisons, pricing breakdowns, use cases, and how-to articles. (source) | Not dated |
| About ScraperAPI | Product update | Product update is publicly available. (source) | Not dated |
| E-commerce Intelligence Data Infrastructure / ScraperAPI | Roadmap | Public product roadmap. (source) | Not dated |
Not found in the collected public sources: changelog or release notes, status page, separate help center or knowledge base.
Technical
Technical and delivery signals
Delivery model, platforms, API, data ownership, reliability claims and release activity.
| Signal | Finding | Source |
|---|---|---|
| Delivery model (cloud, self-hosted, desktop, browser extension) | Cloud-based API service S40. | S40 |
| Platforms and apps | Accessible via web API; SDKs for Python, Node, PHP, Ruby, Java, and cURL S16. | S16 |
| API and extensibility (API, SDK, webhooks, MCP, plugins) | Offers API, SDKs, MCP server, and integrations with LangChain, LlamaIndex, n8n, and Zapier S16. | S16 |
| Data ownership and export | Not published on the collected pages. | — |
| Performance and reliability claims | Claims to handle 14,000 websites per second and 99.9% uptime S1 S17. | S1 S17 |
| Release activity | Not published on the collected pages. | — |
Measured infrastructure
Domain, certificate, and hosting signals, measured directly.
| Signal | Finding |
|---|---|
| Domain registered | 2018-05-14 — NameCheap, Inc. |
| Domain expires | 2027-05-14 |
| TLS certificate | Let's Encrypt, valid, expires 2026-11-28 |
| Security headers | X-Frame-Options |
| Headers not served | HSTS, CSP, X-Content-Type-Options, Referrer-Policy |
| Server header | cloudflare |
| Mail handled by | aspmx.l.google.com, alt1.aspmx.l.google.com |
| Nameservers | ns3.digitalocean.com, ns2.digitalocean.com |
Not measurable: wayback: rate limited by archive.org, ladder stopped after 1 probe(s); rdap: exceeded the overall budget; wayback: exceeded the overall budget; tls: exceeded the overall budget; dns: exceeded the overall budget; headers: exceeded the overall budget. A gap here means the lookup was unavailable, not that the finding is negative.
Technical site audit
A bounded multi-page crawl with page-level issues and URLs.
Scout — Bounded technical crawl
- Pages crawled: 15 of 15 maximum
- Technical health: 98/100
- Critical issues: 0
- Warnings: 7
- Notices: 1
Issues
| Severity | Issue | Value | Affected URL |
|---|---|---|---|
| warning | Missing canonical URL | — | https://www.scraperapi.com/solutions/scraping-api/ |
| notice | Page is marked noindex | — | https://www.scraperapi.com/solutions/scraping-api/ |
| warning | Duplicate title in audit sample | 2 | https://www.scraperapi.com/ |
| warning | Duplicate title in audit sample | 2 | https://www.scraperapi.com/ |
| warning | Duplicate meta description in audit sample | 2 | https://www.scraperapi.com/ |
| warning | Duplicate meta description in audit sample | 2 | https://www.scraperapi.com/ |
| warning | Duplicate meta description in audit sample | 2 | https://www.scraperapi.com/solutions/data-pipeline/ |
| warning | Duplicate meta description in audit sample | 2 | https://www.scraperapi.com/solutions/data-acquisition-for-enterprise/ |
Crawled pages
| Status | Title | H1s | Words | Response | URL |
|---|---|---|---|---|---|
| 200 | ScraperAPI: Scale Data Collection with a Simple Web Scraping API | 1 | 1322 | 37 ms | https://www.scraperapi.com/ |
| 200 | ScraperAPI + Traject Data: From data extraction to insights | 1 | 1225 | 59 ms | https://www.scraperapi.com/blog/scraperapi-traject-data-acquisition/ |
| 200 | ScraperAPI: Scale Data Collection with a Simple Web Scraping API | 1 | 1322 | 27 ms | https://www.scraperapi.com/ |
| 200 | Compare Plans and Get Started for Free - ScraperAPI Pricing | 1 | 2133 | 50 ms | https://www.scraperapi.com/pricing/ |
| 200 | Web Scraping Solutions \ | ScraperAPI | 1 | 2774 | 40 ms |
| 200 | Async Scraper Service - ScraperAPI | 1 | 1160 | 100 ms | https://www.scraperapi.com/solutions/asynchronous-scraper-service/ |
| 200 | Structured Data Endpoints - ScraperAPI | 1 | 2135 | 53 ms | https://www.scraperapi.com/solutions/structured-data/ |
| 200 | AI Web Scraping for Agents & Automated Workflows \ | ScraperAPI | 1 | 1986 | 41 ms |
| 200 | Automate Web Scraping with DataPipeline - ScraperAPI | 1 | 1807 | 46 ms | https://www.scraperapi.com/solutions/data-pipeline/ |
| 200 | Scraping API - Easy to use | 1 | 1876 | 43 ms | https://www.scraperapi.com/solutions/scraping-api/ |
| 200 | Large-Scale Data Acquisition with ScraperAPI | 1 | 1231 | 97 ms | https://www.scraperapi.com/solutions/data-acquisition-for-enterprise/ |
| 200 | Scrape eCommerce Product Data With ScraperAPI | 1 | 1825 | 1,979 ms | https://www.scraperapi.com/solutions/ecommerce/ |
| 200 | Gather Web Data for Market Research with ScraperAPI | 1 | 1367 | 58 ms | https://www.scraperapi.com/solutions/market-research/ |
| 200 | Get SERP Data at Scale with ScraperAPI | 1 | 1638 | 35 ms | https://www.scraperapi.com/solutions/serp-api/ |
| 200 | Web Data Collection for Travel and Hospitality with ScraperAPI | 1 | 1353 | 91 ms | https://www.scraperapi.com/solutions/travel-and-hospitality/ |
This is a bounded Scout crawl. Core Web Vitals and Lighthouse scores are not claimed unless a dedicated performance audit is connected.
Search Console and Analytics
First-party search and behavioral data connection state.
Modeled acquisition channels
| Channel | Estimated share |
|---|---|
| direct | 37.1% |
| search | 52.2% |
| search organic | 41.8% |
| search paid | 10.5% |
| social | 2.1% |
| social organic | 2.1% |
| social paid | 0.0% |
| referrals | 4.3% |
| paid referrals | 0.4% |
| 0.5% | |
| gen ai | 3.3% |
| affiliate | 0.0% |
| other | 0.0% |
First-party connections
| Integration | Status | Data available after connection |
|---|---|---|
| Google Search Console | Not connected | Clicks, impressions, CTR, average position, queries, pages, countries, and devices |
| Google Analytics | Not connected | Organic sessions, engagement, landing pages, conversions, geography, and devices |
No first-party Search Console or Analytics numbers are shown until the site owner authorizes the corresponding Google account. Scout traffic model values above are modeled estimates, not private analytics totals.
Limits and method
Limitations and open questions
Known constraints and missing evidence from the collected pages.
The collected pages do not mention any competitors by name. Evidence gaps include lack of detailed customer testimonials, independent review ratings, and specific security certifications beyond GDPR/CCPA claims. Open questions include the exact credit cost for many target sites and the specifics of the Enterprise plan pricing.
Sources, method, and limitations
Evidence inventory, collection method, provider use, and constraints.
This report is based on 15 collected pages from scraperapi.com, including the homepage, pricing page, about page, and AI grounding documentation. The external proof search discovered a review profile but did not collect its content. Limitations include the absence of first-party customer testimonials and detailed security documentation.
- Documentationhttps://www.scraperapi.com/Verified
- Official Websitehttps://www.scraperapi.com/about-us/Verified
- Documentationhttps://www.scraperapi.com/docs/ai/Verified
- Pricing Pagehttps://www.scraperapi.com/pricing/Verified
- Pricing Pagehttps://www.scraperapi.com/blog/ebay-price-monitoring/Verified
- Pricing Pagehttps://www.scraperapi.com/blog/google-hotel-price-scraper/Verified
- Pricing Pagehttps://www.scraperapi.com/blog/price-scraping-for-ecommerce/Verified
- Pricing Pagehttps://www.scraperapi.com/blog/web-scraping-pricing-and-choosing-the-right-solution/Verified
- Pricing Pagehttps://www.scraperapi.com/solutions/price-monitoring/Verified
- Pricing Pagehttps://www.scraperapi.com/docs/ai/pricing/Verified
- Official Websitehttps://www.scraperapi.com/ecommerce-intelligence-platform/Verified
- Official Websitehttps://www.scraperapi.com/solutions/Verified
- Official Websitehttps://www.scraperapi.com/blog/maintaining-web-scraping-proxies-as-an-e-commerce-business-owner-is-not-easy-whats-the-solution/Verified
- Official Websitehttps://www.scraperapi.com/blog/scrape-aliexpress-product-data/Verified
- Official Websitehttps://www.scraperapi.com/blog/scrape-target-product-data/Verified
- Review Sitehttps://www.trustpilot.com/review/www.scraperapi.comVerified
- Review Sitehttps://www.capterra.com/p/238595/Scraper-API/Verified
- Review Sitehttps://toolradar.com/tools/scraperapiVerified
- Review Sitehttps://shouldiuse.io/r/scraperapiVerified
- Review Sitehttps://costbench.com/software/web-scraping/scraperapi/hidden-costs/Verified
- Articlehttps://github.com/scraperapiVerified
- Documentationhttps://github.com/yiqi22/scraping-api-comparison/blob/main/README.mdVerified
- Articlehttps://github.com/gzr07932/scraperapi-pricing-analysisVerified
- Articlehttps://webscraping.cc/compare/scraperapi-vs-zyte/Verified