In simple English
This tool collects search results from search engines like Google and Bing. You give it keywords, and it hands back lists of web pages with their titles and addresses. You can use it from the command line, run it as a Python library, or set up a local server. It helps you check search rankings without clicking through pages by hand. It costs nothing to run, but search engines might block your computer if you ask too often.
What it is
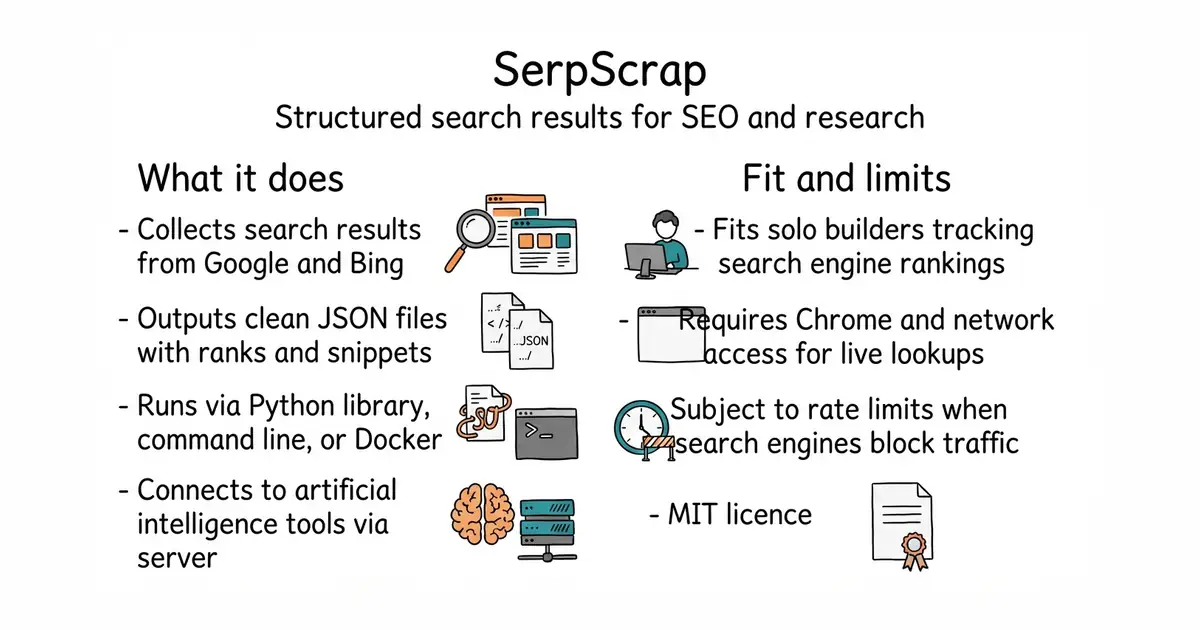
SerpScrap is an open-source search result scraper written in Python that collects structured data from multiple web engines. It formats outputs as JSON and runs via command-line tools, Python scripts, Docker containers, or model context protocol servers.
What it is good for
Solo builders who want to track search rankings, gather competitor data, or feed live search results into artificial intelligence models.
- Runs as a Python library, a command-line tool, or a Docker setup.
- Saves structured search results directly to JSON files.
- Includes support for model context protocol servers to connect with artificial intelligence assistants.
- Requires Chrome and steady network access for live browser searches.
- Search engines frequently block scrapers or demand consent clicks, which causes partial results.
- Managing the Docker stack requires setting up database and service secrets in environment files.
manual search engine ranking checks and browser clicking
Docker (a way to run a program inside its own sealed box, so it cannot break anything else on your server)
- searxng/searxng39k stars
A self-hosted private search engine that aggregates results from multiple sources instead of scraping them directly.
- apify/apify-sdk-python180 stars
A larger cloud web scraping framework for Python with ready-made actors for search engines.


- cybertec-postgresql/pg_timetable1.4k stars
A job scheduler for PostgreSQL whose jobs and schedules live in the database itself.
- PrefectHQ/prefect24k stars
Adds scheduling, retries and a run history to Python functions you already have.
python -m venv venv
source venv/bin/activate
python -m pip install SerpScrap==2.0.0a3