In simple English
This tool downloads web pages and converts them into clean text that artificial intelligence can read. It helps you pull information from entire websites or search engines like Google. You can run it on your own server or use it as an application programming interface (an API, which lets one piece of software talk to another). It saves you from writing custom web scrapers for every site you want to read. The code is free to use under the MIT licence.
What it is
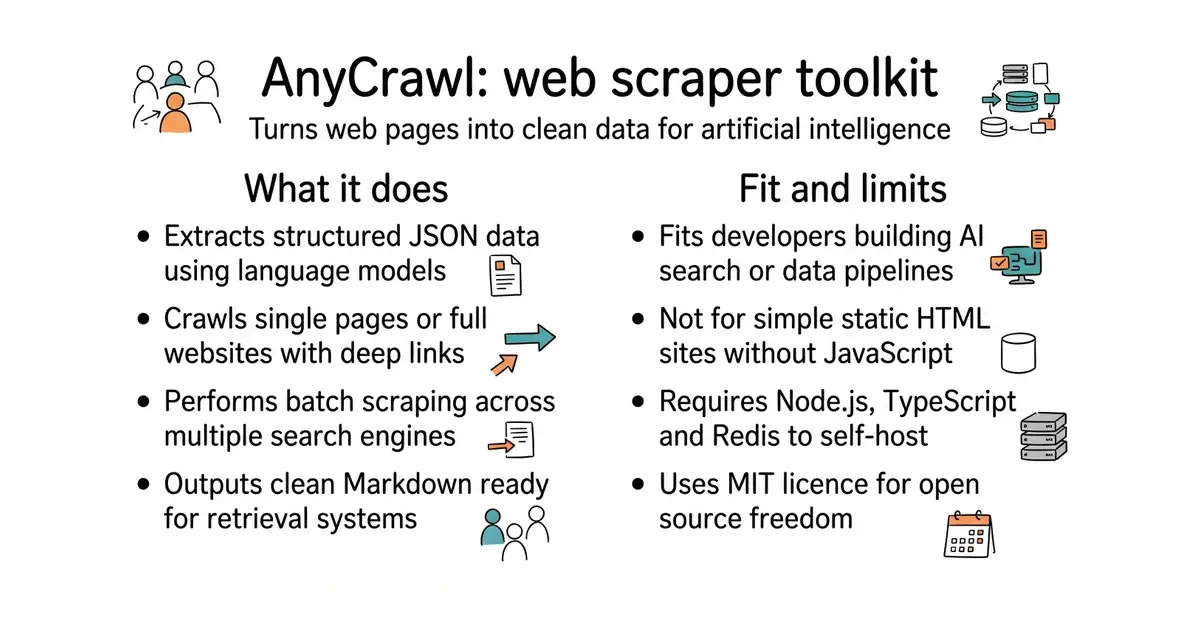
AnyCrawl is a high-performance web crawling and scraping toolkit written in TypeScript with native multi-threading support. It processes single pages, crawls full sites, runs batch jobs, and extracts structured JSON data using language models.
What it is good for
Solo builders who need to feed website content, documentation, or search results into an AI assistant, a retrieval-augmented generation system, or a local database without building scrapers from scratch.
- Turns raw HTML pages into clean Markdown ready for language models.
- Supports batch crawling across multiple search engines and web domains.
- Includes built-in proxy support to help bypass rate limits and blocks.
- Requires Node.js and a Redis instance to run self-hosted deployments.
- Browser-based engines like Playwright and Puppeteer need significant memory.
- Setting up custom proxy rotations and geo-ip lookup requires extra configuration.
Writing custom Puppeteer scripts or paying for closed-source scraping APIs
Redis
- apify/apify-sdk-js186 stars
A mature web scraping and browser automation library for JavaScript and TypeScript.

- cybertec-postgresql/pg_timetable1.4k stars
A job scheduler for PostgreSQL whose jobs and schedules live in the database itself.
- PrefectHQ/prefect24k stars
Adds scheduling, retries and a run history to Python functions you already have.
git clone https://github.com/any4ai/AnyCrawl.git
cd AnyCrawl
pnpm install
pnpm build