Overview
Summary
The useful answer before the supporting detail.
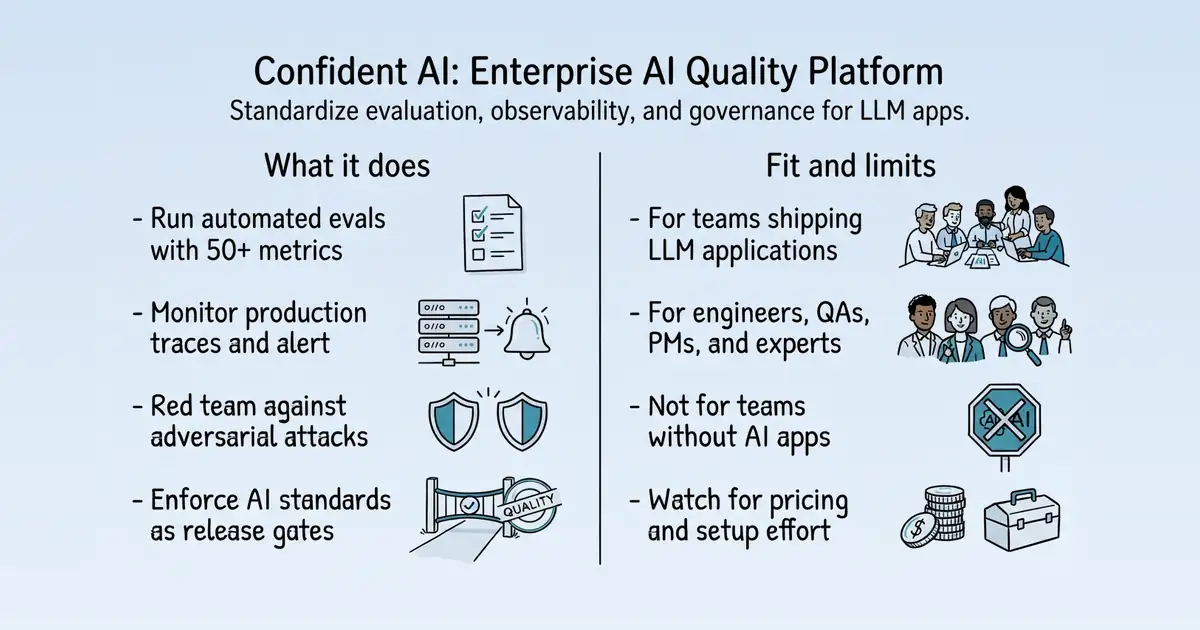
Confident AI is an AI quality platform that helps enterprise teams standardize evaluation, observability, and governance for LLM applications S129. It is used by engineers, QAs, PMs, and domain experts to measure, improve, and maintain AI quality across the lifecycle S29. The platform provides automated evals, production monitoring, and policy enforcement to catch regressions and ensure quality before release S29.
Product identity and positioning
Name, category, positioning, audience, and first-party claims.
- Identity: Confident AI is an enterprise AI quality platform for evaluation, observability, and governance S129.
- Core purpose: It solves the problem of inconsistent AI quality measurement and enforcement across teams S129.
- Intended users: Engineers, QAs, PMs, and domain experts building and maintaining LLM applications S29.
- Product scope: A platform that includes evaluation, observability, red teaming, and governance capabilities S1.
- Positioning: Positioned as the place where AI quality is enforced, not just hoped for S1.
- Claimed distinction: Claims to turn evals, observability, and red teaming into controls that teams can't ship without S1.
Use cases and audiences
Who the product serves and the jobs it is designed to handle.
| Audience | Practical use case |
|---|---|
| Engineers | Run automated evals in CI/CD to detect breaking changes before they reach users S29. |
| QAs | Build test datasets and run regression suites to validate AI behavior across scenarios S29. |
| Product Managers | Track quality metrics over time, compare experiments, and monitor production health S29. |
| Domain Experts | Label data and review AI outputs in human-in-the-loop workflows S29. |
| Annotators | Label data and review AI outputs at scale S29. |
Traffic and search
SEO analysis
Collected Oct 21, 2026confident-ai.com: an estimated 86,234 total monthly visits and about 3,096 monthly organic visits across 660 ranking keywords. Scout crawled 15 pages and measured a technical health score of 97/100.
Search summary
The useful answer before the supporting detail.
Confident AI is the AI quality platform for enterprise teams to standardize AI evals and observability across the org — one consistent bar for how every team measures and monitors their AI. confident-ai.com: an estimated 86,234 total monthly visits and about 3,096 monthly organic visits across 660 ranking keywords. Scout crawled 15 pages and measured a technical health score of 97/100.
- Total traffic (modeled): 86,234 monthly visits across all channels.
- Organic search traffic (estimated): 3,096 monthly visits from search.
- Strongest sampled ranking: confident ai at position 1.
- Leading page in the collected evidence: https://www.confident-ai.com/knowledge-base/compare/10-llm-observability-tools-to-evaluate-and-monitor-ai-2026.
- Closest measured organic competitor: ai-sdk.dev, appearing 1 times in the sampled first-page SERPs.
- Technical crawl: 15 pages, health score 97/100.
Website intelligence — Collected evidence
Company identity and positioning
| Page type | Evidence | Source |
|---|---|---|
| features | Confident AI is the AI quality platform for enterprise teams to standardize AI evals and observability across the org — one consistent bar for how every team measures and monitors their AI. | https://www.confident-ai.com/ |
| features | Self-host or use Confident AI's cloud. | https://www.confident-ai.com/ |
| features | Your data. Your region. | https://www.confident-ai.com/ |
| features | Granular permissions. | https://www.confident-ai.com/ |
| features | 99.9% uptime SLA. | https://www.confident-ai.com/ |
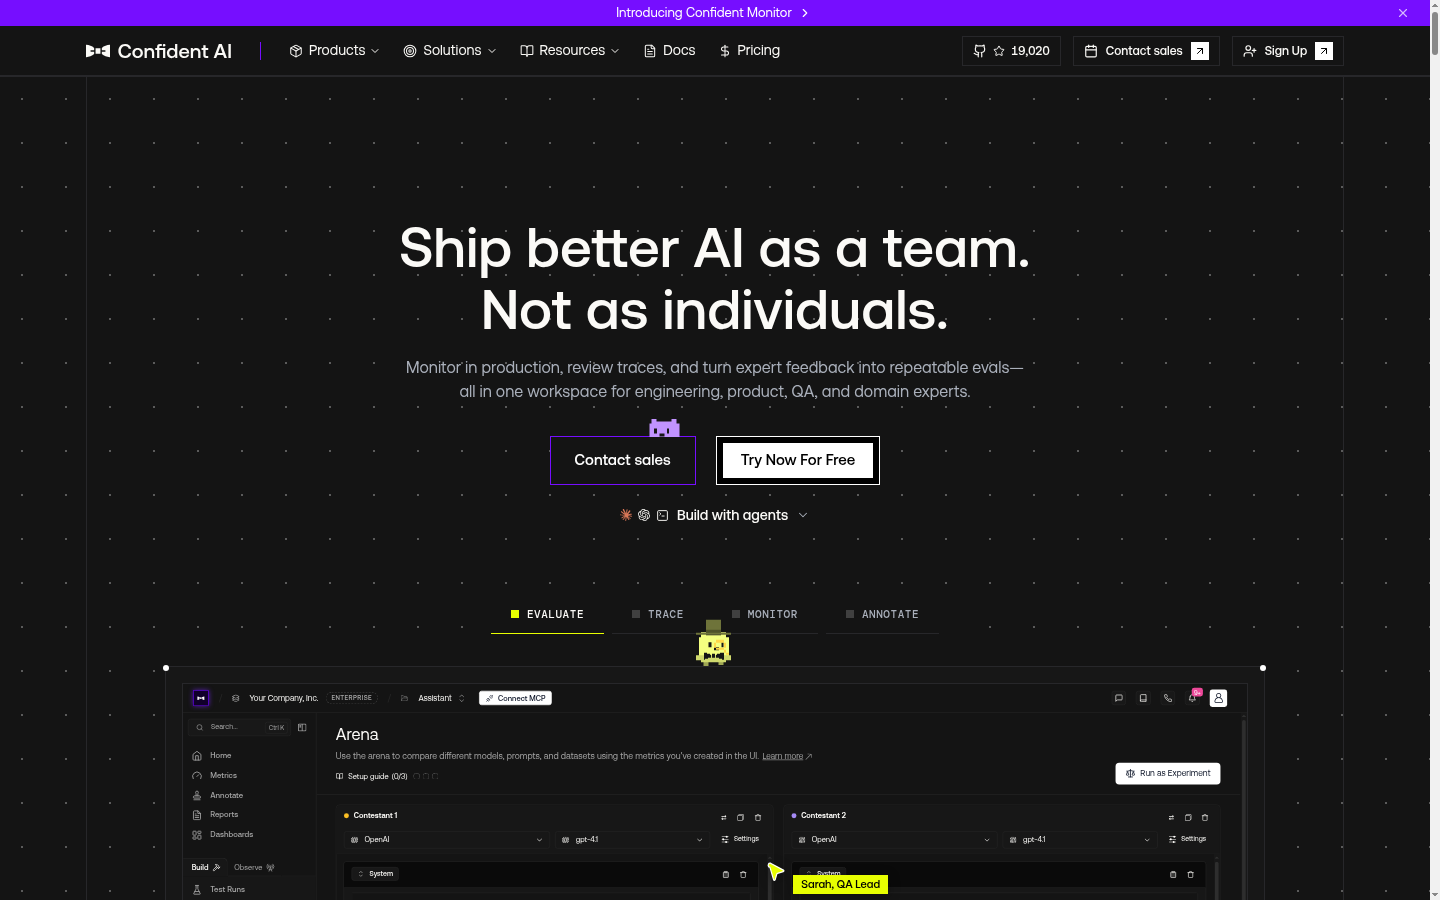
| features | Ship better AI as a team. | https://www.confident-ai.com/ |
| features | Monitor in production, review traces, and turn expert feedback into repeatable evals—all in one workspace for engineering, product, QA, and domain experts. | https://www.confident-ai.com/ |
| features | Contact salesTry Now For Free | https://www.confident-ai.com/ |
| features | Most agent failures never get reported. Confident AI evaluates every production trace, groups failures into issues, and alerts your team before they spread. | https://www.confident-ai.com/ |
| features | “We hit a point where every AI team was building their own eval stack. That’s fine for one product. With five, ten, fifteen AI initiatives across the portfolio, it’s never going to live up to our high standards of AI governance.” | https://www.confident-ai.com/ |
| features | Flag a bad response once, and every release is checked for it. | https://www.confident-ai.com/ |
| features | “Before Confident AI, a single improvement cycle took 10 days — I'd create a task, assign it to an engineer, wait for availability, and go back and forth. Now the same cycle takes three hours, and our product managers can run it themselves.” | https://www.confident-ai.com/ |
Domain performance
Modeled total traffic, six-month trend, engagement, countries, and domain identity.
Total website traffic
| Month | Modeled visits |
|---|---|
| 2026-04 | 127,599 |
| 2026-05 | 101,576 |
| 2026-06 | 96,048 |
| 2026-07 | 116,309 |
| 2026-08 | 114,770 |
| 2026-09 | 86,234 |
Top visitor countries
| Country | Name | Traffic share |
|---|---|---|
| US | United States | 36.7% |
| IN | India | 15.2% |
| VN | Vietnam | 4.0% |
| GB | United Kingdom | 2.5% |
| BR | Brazil | 2.5% |
Domain identity
| Signal | Value |
|---|---|
| Registered | Aug 15, 2023 |
| Last changed | Jul 16, 2026 |
| Expires | Aug 15, 2027 |
| WHOIS server | whois.verisign-grs.com |
| DNSSEC | Signed |
| Nameservers | DANE.NS.CLOUDFLARE.COM, FISH.NS.CLOUDFLARE.COM |
Website capture
Organic keywords
Top keywords and an independent Google result page.
Top organic keywords
| Keyword | Volume | CPC | Estimated value |
|---|---|---|---|
| confident ai | 1,460 | $9.28 | $1,070 |
| best ai comparing promt | 0 | $0.00 | $290 |
| llm-as-a-judge | 2,520 | $0.00 | $260 |
| confident ai. | 270 | $0.00 | $260 |
| deepeval | 12,030 | $5.76 | $250 |
Independent Google result page
Query: confident ai
| Position | Title | URL | Description |
|---|---|---|---|
| 1 | Confident AI | https://www.confident-ai.com/ | Application error: a client-side exception has occurred while loading www.confident-ai.com (see the browser console for more information). |
| 2 | Confident AI: The LLM Eval and Observability Platform for ... | https://www.ycombinator.com/companies/confident-ai | Confident AI provides enterprises an all-in-one platform to evaluate, observe, red team, and govern AI applications. |
| 3 | Confident AI | https://www.linkedin.com/company/confident-ai | Confident AI an AI quality platform and is the easiest way for any organization to build reliable AI. We offer and all-in-one evaluation and observability suite |
| 4 | confident-ai/deepeval: The LLM Evaluation Framework | https://github.com/confident-ai/deepeval | Confident AI is AI monitoring for applications in production. DeepEval tests what you know to test before you ship; Confident AI finds what you didn't, and it' ... |
| 5 | Confident AI | https://ai-sdk.dev/providers/observability/confident-ai | Confident AI is an LLM observability and evaluation platform for teams building reliable AI applications in development and production. |
| 6 | Confident AI - Crunchbase Company Profile & Funding | https://www.crunchbase.com/organization/confident-ai | Confident AI offers open-source unit testing solutions for applications utilizing large language models (LLMs). An open-source platform for benchmarking, ... |
| 7 | Confident AI | https://futuretools.io/tools/confident-ai | Confident AI is an open-source evaluation platform for LLMs (language models). It enables companies of all sizes to test and evaluate their LLM implementations |
Important pages
Pages earning the most estimated search traffic in the sample.
Website intelligence — Collected evidence
Prioritized website intelligence pages
| Type | Page | Words | Change | URL |
|---|---|---|---|---|
| features | Confident AI: Enterprise AI Evaluation & Observability Platform | 2,640 | new | https://www.confident-ai.com/ |
| pricing | Confident AI Pricing: Free to Enterprise LLM Evaluation Plans | 1,243 | new | https://www.confident-ai.com/pricing |
| features | LLM Product Manager Workflows: A Complete Guide to AI Quality - Confident AI | 5,037 | new | https://www.confident-ai.com/blog/llm-product-manager-workflows |
| features | Confident AI for Domain Experts | 1,528 | new | https://www.confident-ai.com/solutions/domain-experts |
| features | Confident AI for Engineers | 1,391 | new | https://www.confident-ai.com/solutions/engineers |
| features | Confident AI for Enterprise | 2,288 | new | https://www.confident-ai.com/solutions/enterprise |
| features | Confident AI for Product Managers | 1,374 | new | https://www.confident-ai.com/solutions/product-managers |
| features | Confident AI for QA Teams | 1,450 | new | https://www.confident-ai.com/solutions/qa |
| features | Confident AI for Startups | 1,920 | new | https://www.confident-ai.com/solutions/startups |
| features | 9 Best LLM Evaluation Tools for Product Managers in 2026 - Confident AI | 4,590 | new | https://www.confident-ai.com/knowledge-base/compare/best-llm-evaluation-tools-for-product-managers-2026 |
| features | Best LLM Observability Platforms for Product Managers in 2026 - Confident AI | 4,374 | new | https://www.confident-ai.com/knowledge-base/compare/best-llm-observability-platforms-for-product-managers-2026 |
| features | Best LLM Observability Platforms to Improve AI Product Reliability in 2026 - Confident AI | 4,061 | new | https://www.confident-ai.com/knowledge-base/compare/best-llm-observability-platforms-to-improve-ai-product-reliability-2026 |
| features | Production Alerts \ | static | 618 | new |
| features | Production Signals \ | static | 1,222 | new |
| integrations | Introduction \ | static | 1,067 | new |
Features
| Page type | Evidence | Source |
|---|---|---|
| features | Introducing Confident Monitor | https://www.confident-ai.com/ |
| features | Confident AI | https://www.confident-ai.com/ |
| features | 0Contact salesSign Up | https://www.confident-ai.com/ |
| features | Contact sales | https://www.confident-ai.com/ |
| features | Ship better AI as a team. | https://www.confident-ai.com/ |
| features | Not as individuals. | https://www.confident-ai.com/ |
| features | Monitor in production, review traces, and turn expert feedback into repeatable evals—all in one workspace for engineering, product, QA, and domain experts. | https://www.confident-ai.com/ |
| features | Contact salesTry Now For Free | https://www.confident-ai.com/ |
| features | Build with agents | https://www.confident-ai.com/ |
| features | Evalua;\[TraceMonito?Annota&{ | https://www.confident-ai.com/ |
| features | Sarah, QA Lead | https://www.confident-ai.com/ |
| features | TRUSTED BY 500+ LEADING AI COMPANIES | https://www.confident-ai.com/ |
| features | Evals ran to date\[ 0+ \] | https://www.confident-ai.com/ |
| features | PRODUCTION MONITORING | https://www.confident-ai.com/ |
| features | Detect silent issues your users never tell you about. | https://www.confident-ai.com/ |
| features | Most agent failures never get reported. Confident AI evaluates every production trace, groups failures into issues, and alerts your team before they spread. | https://www.confident-ai.com/ |
| features | TIME TO CATCH AN ISSUE | https://www.confident-ai.com/ |
| features | WITH CONFIDENT AI30 MINUTES | https://www.confident-ai.com/ |
| features | WITHOUT CONFIDENT AI4 WEEKS | https://www.confident-ai.com/ |
| features | “We hit a point where every AI team was building their own eval stack. That’s fine for one product. With five, ten, fifteen AI initiatives across the portfolio, it’s never going to live up to our high standards of AI governance.” | https://www.confident-ai.com/ |
Pricing and plans
| Page type | Evidence | Source |
|---|---|---|
| pricing | 0Contact salesSign Up | https://www.confident-ai.com/pricing |
| pricing | Contact sales | https://www.confident-ai.com/pricing |
| pricing | Pricing that scales. | https://www.confident-ai.com/pricing |
| pricing | Adaptable pricing that evolves with your needs — from initial exploration to enterprise scale. | https://www.confident-ai.com/pricing |
| pricing | Try Now For Free | https://www.confident-ai.com/pricing |
| pricing | 1 GB-month of trace spans | https://www.confident-ai.com/pricing |
| pricing | $200 / month | https://www.confident-ai.com/pricing |
| pricing | Everything in Free, plus | https://www.confident-ai.com/pricing |
| pricing | then $1 per GB-month ingested or retained | https://www.confident-ai.com/pricing |
| pricing | $2,000 / month | https://www.confident-ai.com/pricing |
| pricing | Custom pricing | https://www.confident-ai.com/pricing |
| pricing | Unlimited online eval metric runs/month | https://www.confident-ai.com/pricing |
| pricing | PRICING CALCULATOR | https://www.confident-ai.com/pricing |
| pricing | Confident AI offers the cheapest tracing on the market starting from $1/GB-month. This is at least 3 times cheaper than alternatives, and you can adjust retention without limits. | https://www.confident-ai.com/pricing |
| pricing | What plan are you considering? | https://www.confident-ai.com/pricing |
| pricing | How many GB of trace spans do you expect to ingest each month?\*1 GB | https://www.confident-ai.com/pricing |
| pricing | How many months do you want to retain your data?1 month | https://www.confident-ai.com/pricing |
| pricing | $200/month for 1 GB-month | https://www.confident-ai.com/pricing |
| pricing | 1 GB monthly ingested × 1 month retained | https://www.confident-ai.com/pricing |
| pricing | Included5 GB-months$0$0 | https://www.confident-ai.com/pricing |
Integrations and supported platforms
| Page type | Evidence | Source |
|---|---|---|
| integrations | Introducing Confident Monitor | https://www.confident-ai.com/docs |
| integrations | Confident AI | https://www.confident-ai.com/docs |
| integrations | Docs | https://www.confident-ai.com/docs |
| integrations | Search docs⌘KAsk AI | https://www.confident-ai.com/docs |
| integrations | Pricing | https://www.confident-ai.com/docs |
| integrations | LLM Evaluation | https://www.confident-ai.com/docs |
| integrations | Benchmark LLM systems with research-backed metrics. | https://www.confident-ai.com/docs |
| integrations | ](/products/llm-evaluation)[ | https://www.confident-ai.com/docs |
| integrations | LLM Observability | https://www.confident-ai.com/docs |
| integrations | Trace, monitor, and alert on production LLM systems. | https://www.confident-ai.com/docs |
| integrations | ](/products/llm-observability)[ | https://www.confident-ai.com/docs |
| integrations | AI Red Teaming | https://www.confident-ai.com/docs |
| integrations | Stress-test LLM apps against adversarial attacks. | https://www.confident-ai.com/docs |
| integrations | ](/products/ai-red-teaming)[ | https://www.confident-ai.com/docs |
| integrations | AI Governance | https://www.confident-ai.com/docs |
| integrations | Enforce AI standards and controls across teams. | https://www.confident-ai.com/docs |
| integrations | ](/products/ai-governance) | https://www.confident-ai.com/docs |
| integrations | Contact salesSign Up | https://www.confident-ai.com/docs |
| integrations | Introduction | https://www.confident-ai.com/docs |
| integrations | The platform for cross-functional teams to validate AI quality in both development and production | https://www.confident-ai.com/docs |
Product and company updates
No supporting public-page evidence was collected for this category.
Rank tracking
Persistent keyword baselines and position movement.
This analysis created the first position baseline at 2026-10-21T20:02:42.765Z. Movement appears after the next fresh analysis using the same location and language.
Features
Features and capabilities
Core functions and evidence-backed product capabilities.
| Capability | What it does |
|---|---|
| LLM Evaluation | Run automated evals with 50+ research-backed metrics, including LLM-as-a-judge, to benchmark and test LLM outputs S10. |
| Observability | Trace, monitor, and alert on production LLM systems to catch regressions and quality drops in real-time S29. |
| Red Teaming | Stress-test LLM applications against adversarial attacks using frameworks like OWASP LLM Top 10 and NIST AI RMF S4. |
| Governance | Enforce AI standards by translating them into checks that block releases until they pass, with evidence recorded automatically S1. |
| Prompt Management | Manage prompts with a git-based branching workflow synced to your codebase S129. |
| Human-in-the-loop | Enable annotators and SMEs to label data and review AI outputs directly in the platform S29. |
Integrations and ecosystem
Connected products, exports, APIs, and workflow compatibility.
| Integration or interface | Type | What it enables |
|---|---|---|
| API | API | Connect any AI app via API endpoint to start evals or red teaming without SDK changes S4 S10. |
| OpenTelemetry | Integration | Ingest traces from any instrumented application S29. |
| confident-trace | SDK | Ingest traces from instrumented applications S29. |
| MCP | AI interface | Evaluate, iterate, and ship from MCP-compatible editors like Cursor or AI modelCode S10. |
| Docker | Deployment | Deploy Confident AI in your own cloud (AWS, Azure, GCP) via Docker S29. |
| Identity providers (Azure AD, Okta, Ping) | Integration | Integrate with identity providers for authentication S29. |
Pricing
Pricing and plans
Published plans, free access, trials, credits, and pricing limitations.
| Plan or offer | Verified price and billing | Included | Limits |
|---|---|---|---|
| Free | $0 per organization per month S38 | 2 seats, 1 project, 5 test runs per week, 1 GB-month of trace spans S38 | Not established |
| Starter | $200 per organization per month; annual discount on request S38 | Unlimited seats, 5 projects, 5 GB-months then $1 per GB-month S38 | Not established |
| Team | $2,000 per organization per month; annual discount on request S38 | Unlimited projects, 75 GB-months, SSO, SOC2 S38 | Not established |
| Enterprise | Contact sales S38 | On-prem, HIPAA, red teaming in Enterprise++ S38 | Not established |
Competition
Competitive landscape
Domains competing for the same organic search demand.
Sampled competitors
| Competitor | First-page appearances | Sampled queries | Average position | Queries observed |
|---|---|---|---|---|
| ai-sdk.dev | 1 | 1 | 1 | confident ai |
| databricks.com | 1 | 1 | 1 | eval metrics |
| crunchbase.com | 1 | 1 | 2 | confident ai |
| assembled.com | 1 | 1 | 2 | eval metrics |
| inria.hal.science | 1 | 1 | 3 | eval metrics |
| arxiv.org | 1 | 1 | 5 | confident ai |
| medium.com | 1 | 1 | 5 | eval metrics |
| workatastartup.com | 1 | 1 | 6 | confident ai |
| thoughtworks.medium.com | 1 | 1 | 6 | eval metrics |
| forge.coreweave.com | 1 | 1 | 7 | eval metrics |
Website intelligence — Collected evidence
Customers, testimonials, and first-party review claims
No supporting public-page evidence was collected for this category.
Independent review sources discovered
No links to supported independent review platforms were discovered on the collected pages.
Backlink profile
Authority and referring-domain signals.
Backlink comparison profile
- Domain rating: 72/100
- Backlinks: 17,345
- Referring domains: 2,988
- Dofollow backlinks: 55.0%
- Dofollow referring domains: 68.0%
Collection decision
The Scout search index remains intentionally excluded from automatic Scout analysis. This Scout traffic model profile costs 5 credits (0.5 cents) and is included in the first comparison run so its usefulness can be judged before the recurring collection is finalized.
AI visibility
Measured ChatGPT and Google AI mentions with cited sources.
AI-assistant referral traffic
- Estimated current generative-AI referral share: 1.5%
| Month | Traffic share | Source |
|---|---|---|
| — | — | All AI assistants |
| — | — | All AI assistants |
Website intelligence — Collected evidence
Site-stated AI capabilities
| Page type | Evidence | Source |
|---|---|---|
| features | Confident AI is the AI quality platform for enterprise teams to standardize AI evals and observability across the org — one consistent bar for how every team measures and monitors their AI. | https://www.confident-ai.com/ |
| features | Self-host or use Confident AI's cloud. | https://www.confident-ai.com/ |
| features | Ship better AI as a team. | https://www.confident-ai.com/ |
| features | Contact salesTry Now For Free | https://www.confident-ai.com/ |
| features | Most agent failures never get reported. Confident AI evaluates every production trace, groups failures into issues, and alerts your team before they spread. | https://www.confident-ai.com/ |
| features | “We hit a point where every AI team was building their own eval stack. That’s fine for one product. With five, ten, fifteen AI initiatives across the portfolio, it’s never going to live up to our high standards of AI governance.” | https://www.confident-ai.com/ |
| features | “Before Confident AI, a single improvement cycle took 10 days — I'd create a task, assign it to an engineer, wait for availability, and go back and forth. Now the same cycle takes three hours, and our product managers can run it themselves.” | https://www.confident-ai.com/ |
| features | Postman for AI apps | https://www.confident-ai.com/ |
| features | A practical guide to LLM product manager workflows, built around the two things PMs can finally do without waiting on engineering: build on the AI product by editing prompts, running evals, and comparing variants, and monitor quality with dashboards, signals, and shareable evidence. | https://www.confident-ai.com/blog/llm-product-manager-workflows |
| features | [What Are LLM Product Manager Workflows for LLM Evaluation?](#what-are-llm-product-manager-workflows-for-llm-evaluation) | https://www.confident-ai.com/blog/llm-product-manager-workflows |
| features | [LLM Metrics for Product Managers](#llm-metrics-for-product-managers) | https://www.confident-ai.com/blog/llm-product-manager-workflows |
| features | [Why Confident AI Is the Best Tool for LLM Product Manager Workflows](#why-confident-ai-is-the-best-tool-for-llm-product-manager-workflows) | https://www.confident-ai.com/blog/llm-product-manager-workflows |
| features | That gap is finally closing. Modern LLM tooling lets product managers do two things directly that used to require an engineer for every iteration: | https://www.confident-ai.com/blog/llm-product-manager-workflows |
| features | LLM product manager workflows for LLM evaluation are the repeatable ways a PM keeps an AI product's quality high without owning the engineering. They come down to two jobs a PM can now do directly: building on the AI product — editing prompts, running evals, and comparing versions before shipping — and monitoring it in production with dashboards, signals, and alerts that surface what changed. | https://www.confident-ai.com/blog/llm-product-manager-workflows |
| features | It also helps to be precise about what "quality" even means here. The question is not "did the model return a response?" It is "did the AI actually help the user, accurately and in a way we are comfortable shipping?" An assistant can be fluent and still incomplete, take the right action in the wrong tone, or miss the moment it should have escalated. Those are product failures, not just model failures — which is exactly why PMs need to be inside both workflows instead of watching from the sidelines. | https://www.confident-ai.com/blog/llm-product-manager-workflows |
| features | A few standard, out-of-the-box metrics are a fine starting point for almost any AI product, but they only get you so far. Your real quality bar is always product-specific: ask a clarifying question before acting, avoid overconfident answers, escalate frustrated users, or preserve preferences across turns. Those requirements rarely fit a generic metric — and capturing them is exactly where a PM matters most. | https://www.confident-ai.com/blog/llm-product-manager-workflows |
| features | The good news is that custom metrics are far easier to build than people expect, and a PM does not need engineering to write one. With a framework like G-Eval, you describe your criterion in a sentence or two of plain English and you have a working LLM-as-a-judge metric — an AI model that reads each response and scores it against your criterion. For example: | https://www.confident-ai.com/blog/llm-product-manager-workflows |
| features | Contact salesTry Now For Free | https://www.confident-ai.com/solutions/domain-experts |
| features | Complete the AI quality loop for domain experts. | https://www.confident-ai.com/solutions/domain-experts |
| features | Contact salesTry Now For Free | https://www.confident-ai.com/solutions/engineers |
These are first-party product claims, not independent measurements of AI-search visibility.
Marketing opportunities
Actions calculated directly from the collected evidence.
| Opportunity | Recommended action | Evidence |
|---|---|---|
| Competitor gap | Review the sampled queries where ai-sdk.dev appears. | 1 first-page appearances across confident ai |
Website intelligence — Collected evidence
Website evidence gaps
- customers: no usable public page was collected; verify whether the site publishes this evidence.
- reviews: no usable public page was collected; verify whether the site publishes this evidence.
- changes: no usable public page was collected; verify whether the site publishes this evidence.
- identity: no usable public page was collected; verify whether the site publishes this evidence.
- technical: no usable public page was collected; verify whether the site publishes this evidence.
Trust and proof
Customers, proof, and reviews
Published proof, customer signals, and review evidence.
Independent reviews
| Platform | Page | How it was found | Note |
|---|---|---|---|
| JustSteveKing | Confident AI / JustSteveKing | Grounded web search | ###### Testimonial volume and specificity are below what logos imply A larger testimonial set with concrete outcomes would better support the scale claims and bridge the gap between recognition logos and practical buyer confidence. |
| opentools.ai | Confident AI Review, Pricing & Alternatives (August 2026) | Grounded web search | that make Confident AI stand out. Unit test LLMs in under 10 lines of ... 12 open-source evaluation metrics Reduced time to production by 2.4x High client satisfaction 75+ client testimonials Detailed monitoring A/B testing functionality |
| allbestapps.net | Confident AI Review: The Ultimate LLM Evaluation & Testing Tool / AllBestApps | Grounded web search | ; users on Reddit and comparison analyses commend its handling of complex agent simulations and RAG evaluations over alternatives. Reliability is reinforced by ... Type II, HIPAA compliance (Premium+), 99.9% uptime SLA for enterprise, and enterprise-grade |
Customer proof
| Proof type | Named customer or source | Evidence |
|---|---|---|
| Testimonial | Igor Kolodkin | testimonial — ## Trusted by companies that take AI seriously. (LLM Evaluation Platform: Benchmark & Test LLMs / Confident AI) |
Independent mentions
- Confident AI Pricing & Features (2026) / RightAIChoice — 12 mentions across 4 sources (Hacker News, YouTube, Product Hunt, Lemmy), 50 more we could not attribute · researched Oct 8, 2026. ... 54% positive 46% critical ... - − Free DeepEval covers much of the eval use case, making the $200/mo Starter a hard sell - − Team tier at $2,000/mo is enterprise-only with no mid-tier option in between - − Public review data is thin and skews toward launch-day enthusiasm from founder-adjacent accounts - − It's a hosted platform — teams will not need the paid tier
- Reddit user picks Confident AI as best AI observability tool, comparing Braintrust, Datadog, HoneyHive, LangSmith · KBlip — - A Reddit user on 2026-09-08 chose Confident AI for evaluation plus production observability, citing span/trace metrics, annotation queues, and issue surfacing - Braintrust stands out for traced experiments against datasets and comparing outputs across prompts and models, per the post - Datadog LLM Observability suits existing Datadog users for correlating LLM traces with infrastructure, but costs rise with trace volume - LangSmith works well for teams standardized on LangChain/LangGraph but sc
- Confident AI company profile · SOTA2 — > Before Confident AI, a single improvement cycle took 10 days—I'd create a task, assign it to an engineer, wait for availability, and go back and forth. Now the same cycle takes three hours, and our product managers can run it themselves.
- LLM Observability & Monitoring: Trace & Debug LLMs / Confident AI — , and go back and forth. Now the same cycle takes three hours, and our ... Confident AI saves us 480+ hours of manual AI evaluation every month — and gives us ... data to defend every quality decision in front of engineering, product, and leadership
External links were grounded in one live web search. Search snippets are leads, not independently scraped page content; rejected links remain available in Review evidence.
Company, security, and trust
Ownership, policies, security signals, and public trust evidence.
| Signal | Finding | Source |
|---|---|---|
| Company and ownership | Confident AI saves us 480+ hours of manual AI evaluation every month — and gives us the data to defend every quality decision in front of engineering, product, and leadership. | source |
| Contact and support | We want you to experience value before you pay. If something doesn't feel right, email support@confident-ai.com and we'll make it work. | source |
| Legal and privacy | Cancel order #8847tool-usespan\_22 | source |
| Security and compliance | Multi-region residency · HIPAA · GDPR | source |
| Uptime and status page | ### 99.9% uptime SLA. | source |
| Domain registered | 2023-08-15 | — |
| Domain expires | 2027-08-15 | — |
Every trust signal above is backed by a collected page or a registration record.
Documentation and product updates
Help resources, product guidance, and visible changes over time.
| Resource or update | Type | What is available | Date or freshness |
|---|---|---|---|
| Introduction / Confident AI Docs | Documentation | Get started with Confident AI for LLM evaluation and observability (source) | Not dated |
| Plan Adherence / Confident AI Docs | Documentation | Plan Adherence is a single-turn metric to determine if your agent followed the plan it laid out (source) | Not dated |
| Plan Quality / Confident AI Docs | Documentation | Plan Quality is a single-turn metric to determine if your agent's plan is a good way to finish the task (source) | Not dated |
| LLM Product Manager Workflows: A Complete Guide to AI Quality - Confident AI | Guide | Guides, comparisons, pricing breakdowns, use cases, and how-to articles. (source) | Not dated |
| Confident AI: Enterprise AI Evaluation & Observability Platform | Product update | Product update is publicly available. (source) | Not dated |
Not found in the collected public sources: public roadmap, changelog or release notes, status page, separate help center or knowledge base.
Technical
Technical and delivery signals
Delivery model, platforms, API, data ownership, reliability claims and release activity.
| Signal | Finding | Source |
|---|---|---|
| Delivery model (cloud, self-hosted, desktop, browser extension) | Offered as a SaaS offering and can be deployed in your own cloud via Docker S29. | S29 |
| Platforms and apps | Web-based platform S129. | S129 |
| API and extensibility (API, SDK, webhooks, MCP, plugins) | Every part of Confident AI is exposed as an API S129. | S129 |
| Data ownership and export | Not published on the collected pages. | — |
| Performance and reliability claims | Not published on the collected pages. | — |
| Release activity | Not published on the collected pages. | — |
Measured infrastructure
Domain, certificate, and hosting signals, measured directly.
| Signal | Finding |
|---|---|
| Domain registered | 2023-08-15 — NameCheap, Inc. |
| Domain expires | 2027-08-15 |
| First archived | 2023-08-15 — web archive |
| TLS certificate | Let's Encrypt, valid, expires 2026-11-24 |
| Security headers | HSTS |
| Headers not served | CSP, X-Content-Type-Options, X-Frame-Options, Referrer-Policy |
| Server header | Vercel |
| Mail handled by | aspmx.l.google.com, alt1.aspmx.l.google.com |
| Nameservers | fish.ns.cloudflare.com, dane.ns.cloudflare.com |
Technical site audit
A bounded multi-page crawl with page-level issues and URLs.
Scout — Bounded technical crawl
- Pages crawled: 15 of 15 maximum
- Technical health: 97/100
- Critical issues: 0
- Warnings: 4
- Notices: 9
Issues
| Severity | Issue | Value | Affected URL |
|---|---|---|---|
| notice | Meta description length should be reviewed | 189 | https://www.confident-ai.com/ |
| notice | Meta description length should be reviewed | 258 | https://www.confident-ai.com/blog/introducing-confident-ai-monitor |
| notice | Meta description length should be reviewed | 189 | https://www.confident-ai.com/ |
| notice | Meta description length should be reviewed | 42 | https://www.confident-ai.com/solutions/engineers |
| notice | Meta description length should be reviewed | 38 | https://www.confident-ai.com/solutions/product-managers |
| notice | Meta description length should be reviewed | 43 | https://www.confident-ai.com/solutions/qa |
| notice | Meta description length should be reviewed | 49 | https://www.confident-ai.com/solutions/domain-experts |
| notice | Meta description length should be reviewed | 37 | https://www.confident-ai.com/solutions/startups |
| notice | Meta description length should be reviewed | 36 | https://www.confident-ai.com/solutions/enterprise |
| warning | Duplicate title in audit sample | 2 | https://www.confident-ai.com/ |
| warning | Duplicate title in audit sample | 2 | https://www.confident-ai.com/ |
| warning | Duplicate meta description in audit sample | 2 | https://www.confident-ai.com/ |
| warning | Duplicate meta description in audit sample | 2 | https://www.confident-ai.com/ |
Crawled pages
| Status | Title | H1s | Words | Response | URL |
|---|---|---|---|---|---|
| 200 | Confident AI: Enterprise AI Evaluation & Observability Platform | 1 | 3149 | 67 ms | https://www.confident-ai.com/ |
| 200 | Introducing Confident Monitor - Confident AI | 1 | 1018 | 194 ms | https://www.confident-ai.com/blog/introducing-confident-ai-monitor |
| 200 | Confident AI: Enterprise AI Evaluation & Observability Platform | 1 | 3149 | 62 ms | https://www.confident-ai.com/ |
| 200 | LLM Evaluation Platform: Benchmark & Test LLMs \ | Confident AI | 1 | 2170 | 76 ms |
| 200 | LLM Observability & Monitoring: Trace & Debug LLMs \ | Confident AI | 1 | 1940 | 245 ms |
| 200 | AI Red Teaming Platform: Adversarial LLM Testing \ | Confident AI | 1 | 1596 | 32 ms |
| 200 | Enterprise AI Governance for LLM Applications \ | Confident AI | 1 | 1144 | 24 ms |
| 200 | Confident AI for Engineers | 1 | 1658 | 39 ms | https://www.confident-ai.com/solutions/engineers |
| 200 | Confident AI for Product Managers | 1 | 1881 | 44 ms | https://www.confident-ai.com/solutions/product-managers |
| 200 | Confident AI for QA Teams | 1 | 1805 | 51 ms | https://www.confident-ai.com/solutions/qa |
| 200 | Confident AI for Domain Experts | 1 | 1978 | 61 ms | https://www.confident-ai.com/solutions/domain-experts |
| 200 | Confident AI for Startups | 1 | 2382 | 55 ms | https://www.confident-ai.com/solutions/startups |
| 200 | Confident AI for Enterprise | 1 | 2840 | 37 ms | https://www.confident-ai.com/solutions/enterprise |
| 200 | Confident AI Blog - Resources to help teams stay confident in AI | 1 | 1469 | 294 ms | https://www.confident-ai.com/blog |
| 200 | Best LLM Evaluation Tools & Platforms Compared \ | Confident AI | 1 | 3607 | 169 ms |
This is a bounded Scout crawl. Core Web Vitals and Lighthouse scores are not claimed unless a dedicated performance audit is connected.
Search Console and Analytics
First-party search and behavioral data connection state.
Modeled acquisition channels
| Channel | Estimated share |
|---|---|
| direct | 36.3% |
| search | 49.0% |
| search organic | 49.0% |
| search paid | 0.0% |
| social | 2.0% |
| social organic | 2.0% |
| social paid | 0.0% |
| referrals | 9.1% |
| paid referrals | 0.0% |
| 2.1% | |
| gen ai | 1.5% |
| affiliate | 0.0% |
| other | 0.0% |
First-party connections
| Integration | Status | Data available after connection |
|---|---|---|
| Google Search Console | Not connected | Clicks, impressions, CTR, average position, queries, pages, countries, and devices |
| Google Analytics | Not connected | Organic sessions, engagement, landing pages, conversions, geography, and devices |
No first-party Search Console or Analytics numbers are shown until the site owner authorizes the corresponding Google account. Scout traffic model values above are modeled estimates, not private analytics totals.
Limits and method
Limitations and open questions
Known constraints and missing evidence from the collected pages.
The collected pages do not mention specific competitors. Evidence gaps include lack of detailed pricing for Enterprise, no independent review ratings, and no explicit uptime or performance guarantees. Open questions remain about data export capabilities and specific security certifications beyond HIPAA.
Sources, method, and limitations
Evidence inventory, collection method, provider use, and constraints.
This report is based on 15 collected pages from confident-ai.com, including product pages, documentation, and pricing pages. The evidence catalog includes 15 static pages and 8 rendered pages. External proof search was enabled but did not verify any additional claims. Limitations include potential marketing bias in product pages and lack of independent verification of customer testimonials.
- Official Websitehttps://www.confident-ai.com/Verified
- Official Websitehttps://www.confident-ai.com/products/ai-governanceVerified
- Official Websitehttps://www.confident-ai.com/products/ai-red-teamingVerified
- Official Websitehttps://www.confident-ai.com/products/llm-evaluationVerified
- Documentationhttps://www.confident-ai.com/docsVerified
- Pricing Pagehttps://www.confident-ai.com/pricingVerified
- Pricing Pagehttps://www.confident-ai.com/docs/metrics/single-turn/plan-adherence-metricVerified
- Pricing Pagehttps://www.confident-ai.com/docs/metrics/single-turn/plan-quality-metricVerified
- Official Websitehttps://www.confident-ai.com/blog/llm-product-manager-workflowsVerified
- Official Websitehttps://www.confident-ai.com/solutions/domain-expertsVerified
- Official Websitehttps://www.confident-ai.com/solutions/engineersVerified
- Official Websitehttps://www.confident-ai.com/solutions/enterpriseVerified
- Official Websitehttps://www.confident-ai.com/solutions/product-managersVerified
- Official Websitehttps://www.confident-ai.com/solutions/qaVerified
- Official Websitehttps://www.confident-ai.com/solutions/startupsVerified
- Review Sitehttps://www.juststeveking.com/reviews/confident-ai-in-review/Verified
- Articlehttps://rightaichoice.com/tools/confident-aiVerified
- Articlehttps://kblip.com/social/reddit-user-picks-confident-ai-as-best-ai-observability-SNFc44UVerified
- Articlehttps://www.sota2.com/companies/confident-aiVerified
- Review Sitehttps://opentools.ai/tools/confident-aiVerified
- Documentationhttps://bittide.aicompass.dev/article/60085993-a7a0-438d-af78-f9c946312384Verified
- Documentationhttps://reddit.sentinel-team.org/posts/1umxl0i/snapshots/2026-07-10T23%3A15%3A57.207632ZVerified
- Articlehttps://www.confident-ai.com/products/llm-observabilityVerified
- Review Sitehttps://allbestapps.net/ai-app/confident-ai/Verified