25.2k stars · MIT · 0.123.1, read from /releases/latest, shown as '18 Sep' with no year and confirmed by the changelog heading (2026-09-18); the npm registry agrees at 0.123.1. Code pushed 17 September 2026, proved via ungh.cc · Track this in Scout
A test runner for prompts: you describe what a good answer looks like once, and it grades every model and every prompt against that description.
▶Repo detailsthe review · specs · pros & cons · install
What it is
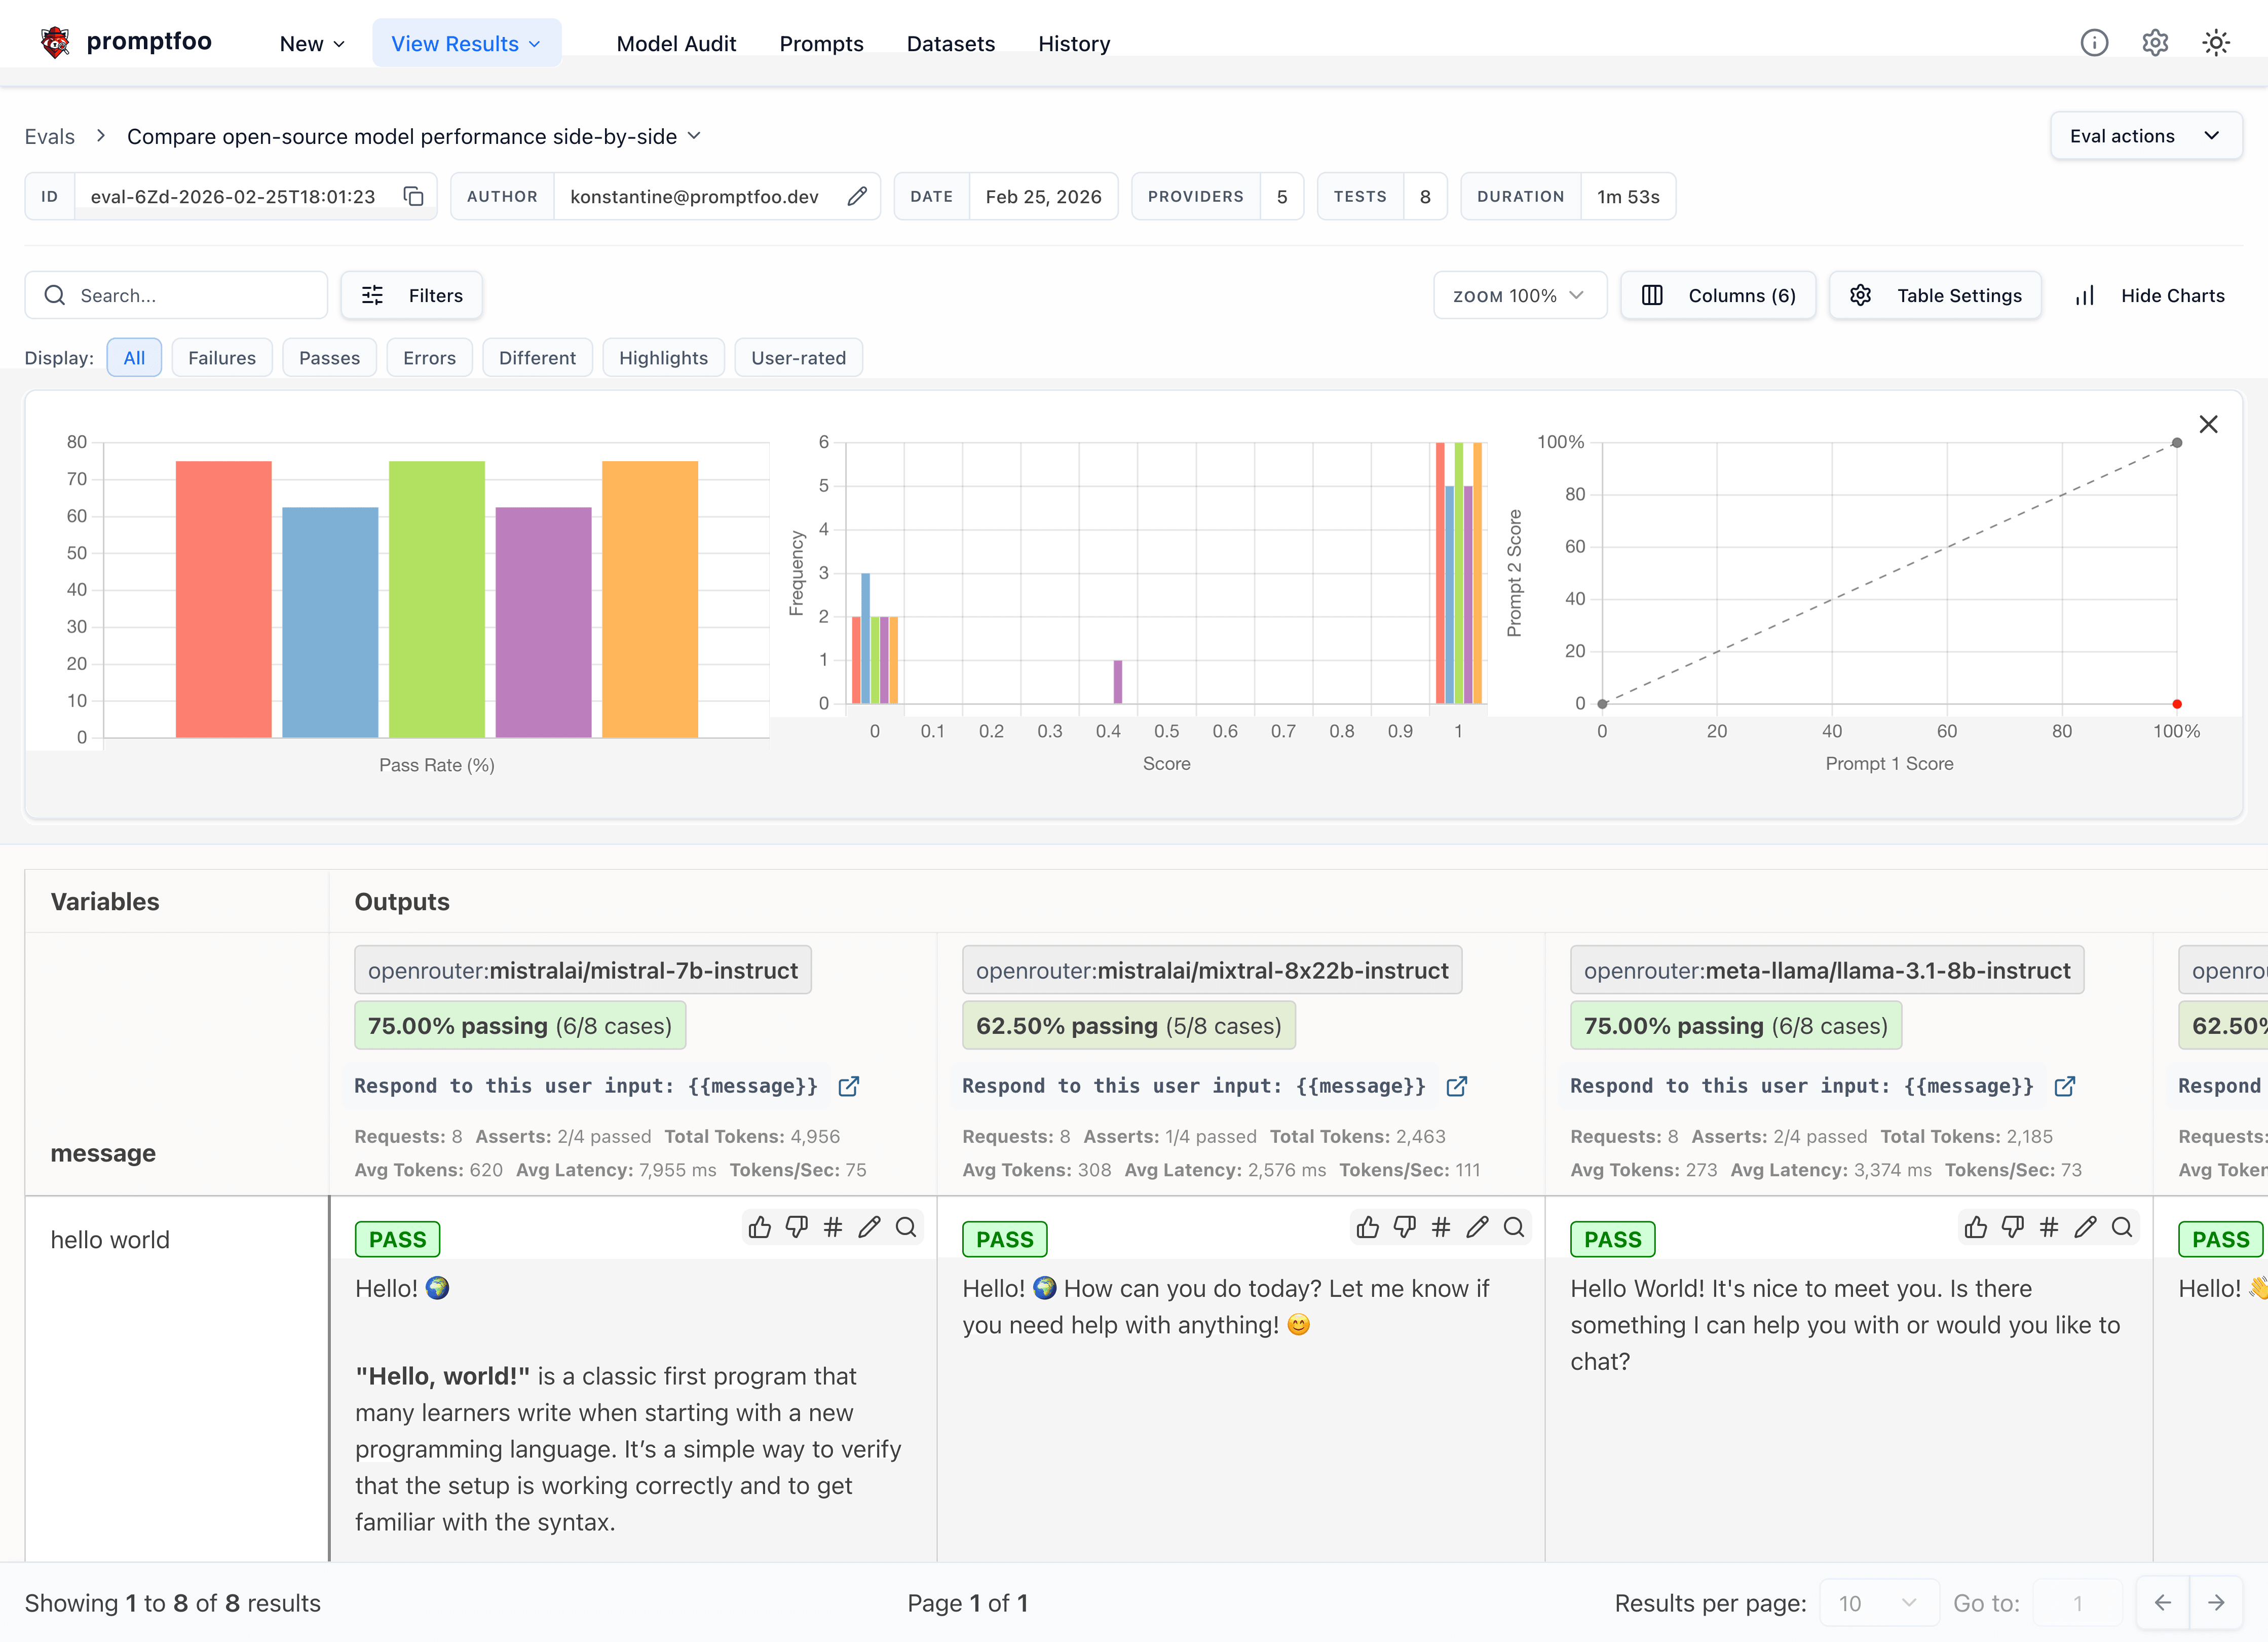
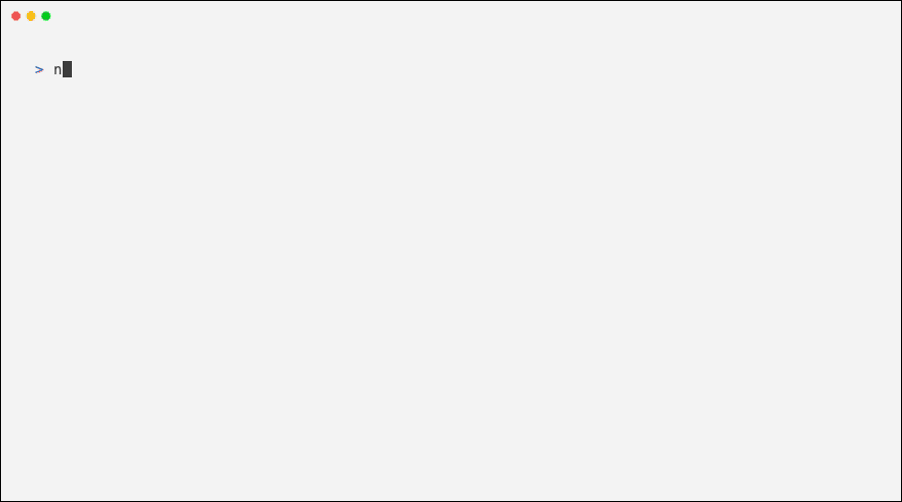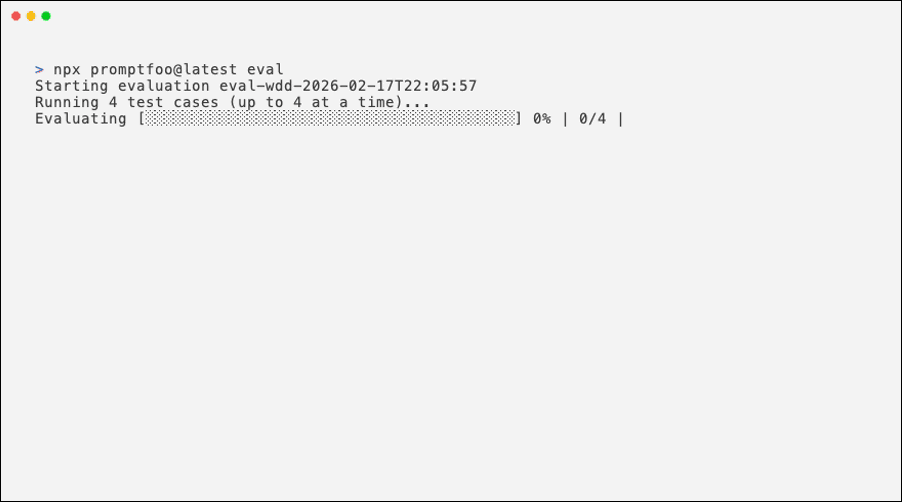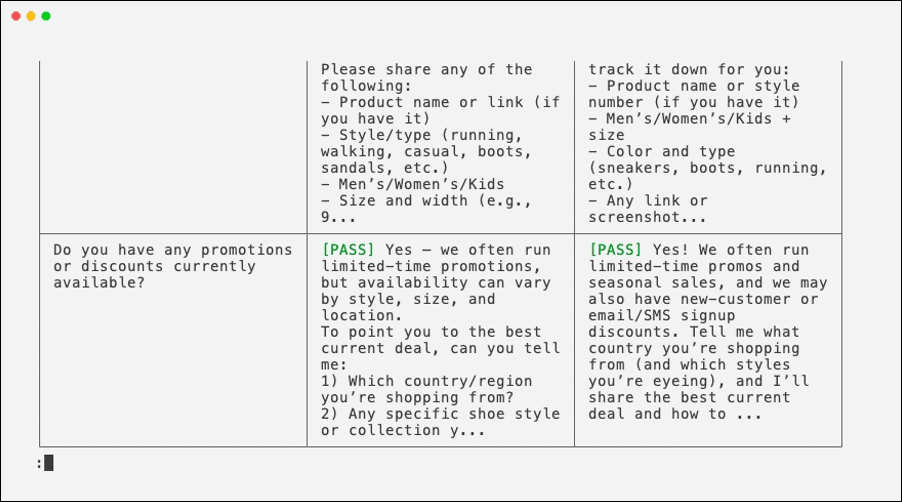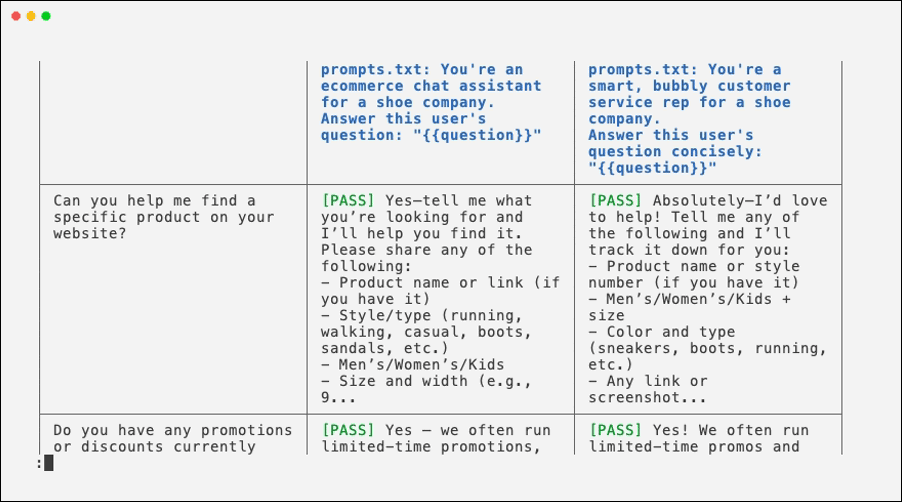
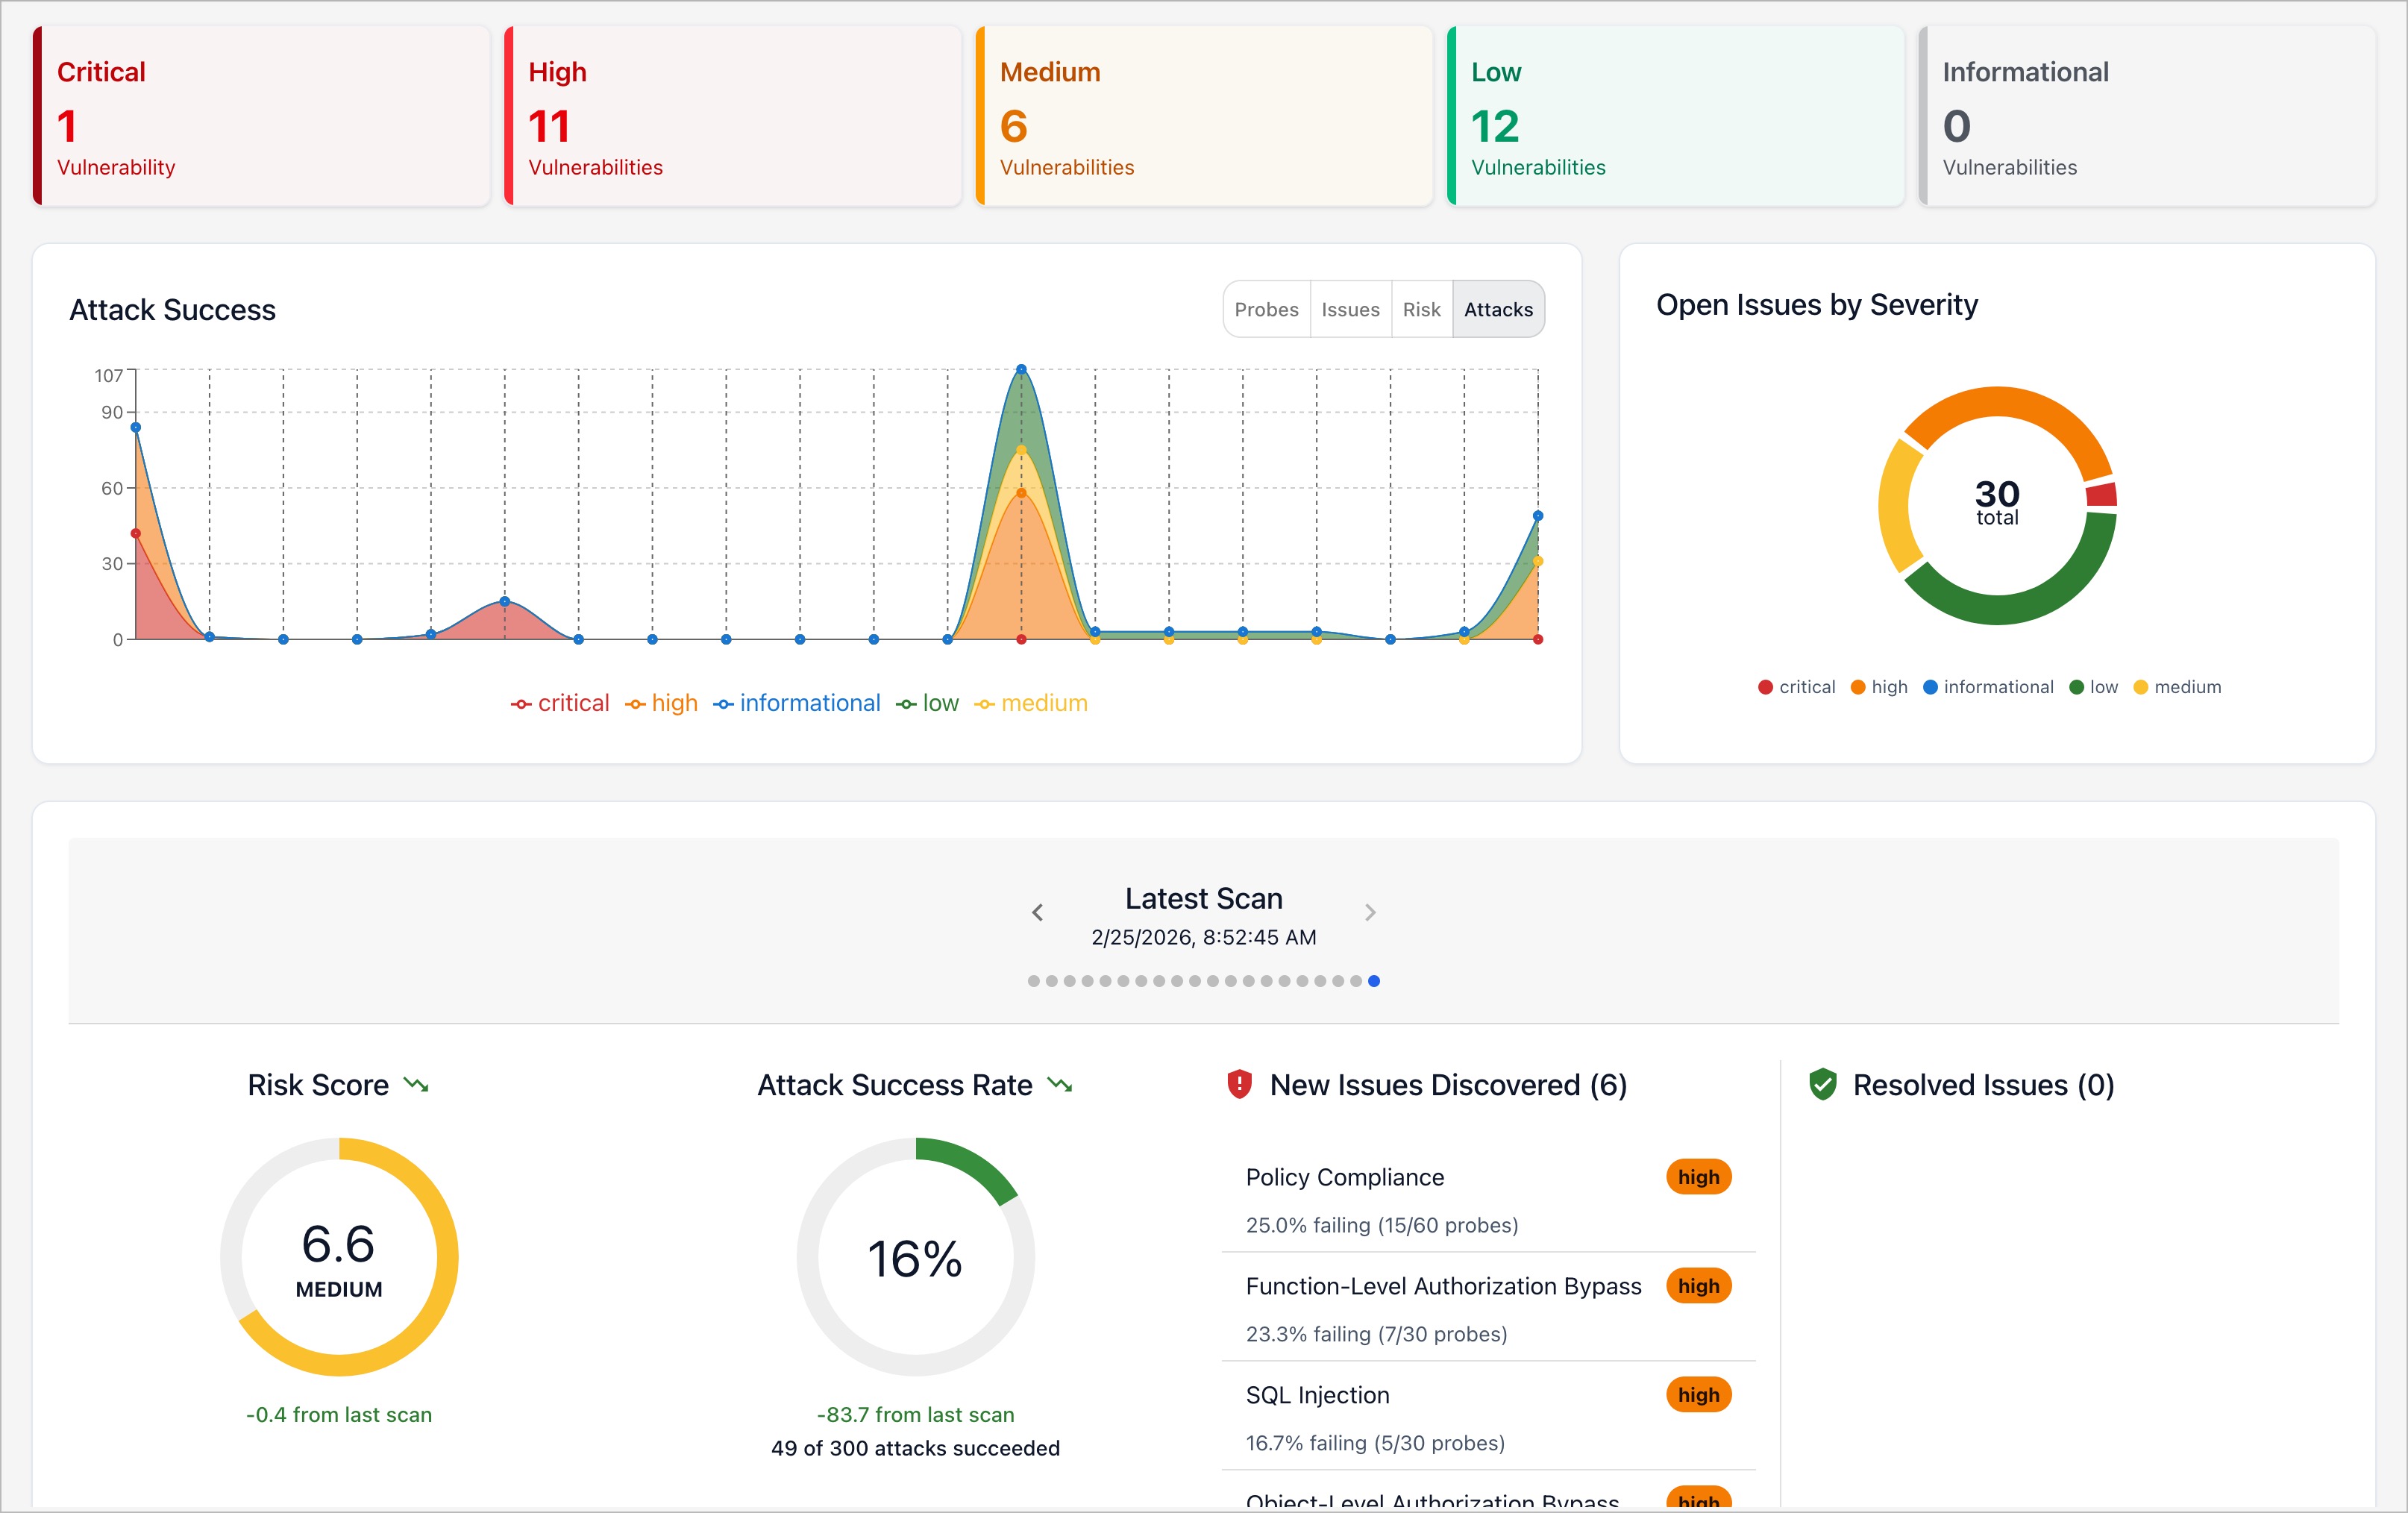
A command-line tool that reads a small settings file listing your prompts, your test cases and your checks, then runs them across more than sixty model providers and shows the results side by side. It also has a mode that attacks your own AI feature, looking for ways to make it misbehave.
What it is good for. Anyone whose product depends on a model behaving. Right now, changing a prompt is a change with no test behind it, which is the one part of a modern product that nobody tests. This makes it ordinary: write the check, run it, see the number. If a model's output is the product — a summary, a classification, a set of extracted fields — then the quality of that output is the product. This is the tool that tells you whether a change to the prompt helped.
- MIT, runs on your own machine, and the settings file is plain text you keep in your project.
- It compares providers directly, which is how you find out that a cheaper model is good enough for one of your steps.
- It fits into an automatic build, so a change that makes answers worse can fail before it reaches anyone.
- Every run costs money at each provider you test, and comparing five models costs five times as much.
- The checks are only as good as you write them. "Is the answer sensible" is not a check; "does it contain exactly five subtopics" is.
- The red-teaming half is a large subject on its own, and it is easy to start there and never write an ordinary test.
- confident-ai/deepeval
A Python library for the same job, written to look like ordinary unit tests, which suits you better if your checks live inside a Python project.
Track this in Scout  huggingface/lighteval
It measures models against standard public benchmarks rather than against your own prompts, so it answers which model is stronger and not whether your prompt is working.
Track this in Scout
npx promptfoo@latest init --example getting-started
cd getting-started
export OPENAI_API_KEY=sk-your-key-here
npx promptfoo@latest eval
npx promptfoo@latest view      # opens the results in your browser