18,722 stars · Apache-2.0 · python-v4.2.4 (2026-09-22); PyPI is ahead at 4.2.8 (2026-10-02) · Track this in Scout
Tests for the output of language models, written and run like ordinary unit tests and able to score with a local model.
▶Repo detailsthe review · specs · pros & cons · install
What it is
DeepEval is a Python evaluation framework. It provides metrics for things like faithfulness to a source document, relevance of an answer, and the correctness of a retrieval step, and runs them as test cases you can keep in a repository and run in automation.
What it is good for. Anyone shipping a feature built on a language model who currently decides whether a prompt change helped by reading a few answers. The useful shape here is that it looks like a test suite, so it fits where your existing tests already run instead of becoming a separate ritual.
- It works like ordinary tests, so it lands in the pipeline that already exists.
- It can run entirely on a local model, with
deepeval set-ollama --model=<name>, or through environment variables pointing at a local server, or with your own model class — so the running cost can be zero. - Some metrics are small language models that run locally rather than calls to a provider, and the licence is Apache-2.0 with no
ee/directory and no added conditions.
- ⚠ By default it costs money on every run. The README's own first step is
export OPENAI_API_KEY="...", and the model-judged metrics call a paid model for each test case. A large test suite run on every commit is a bill. - ⚠
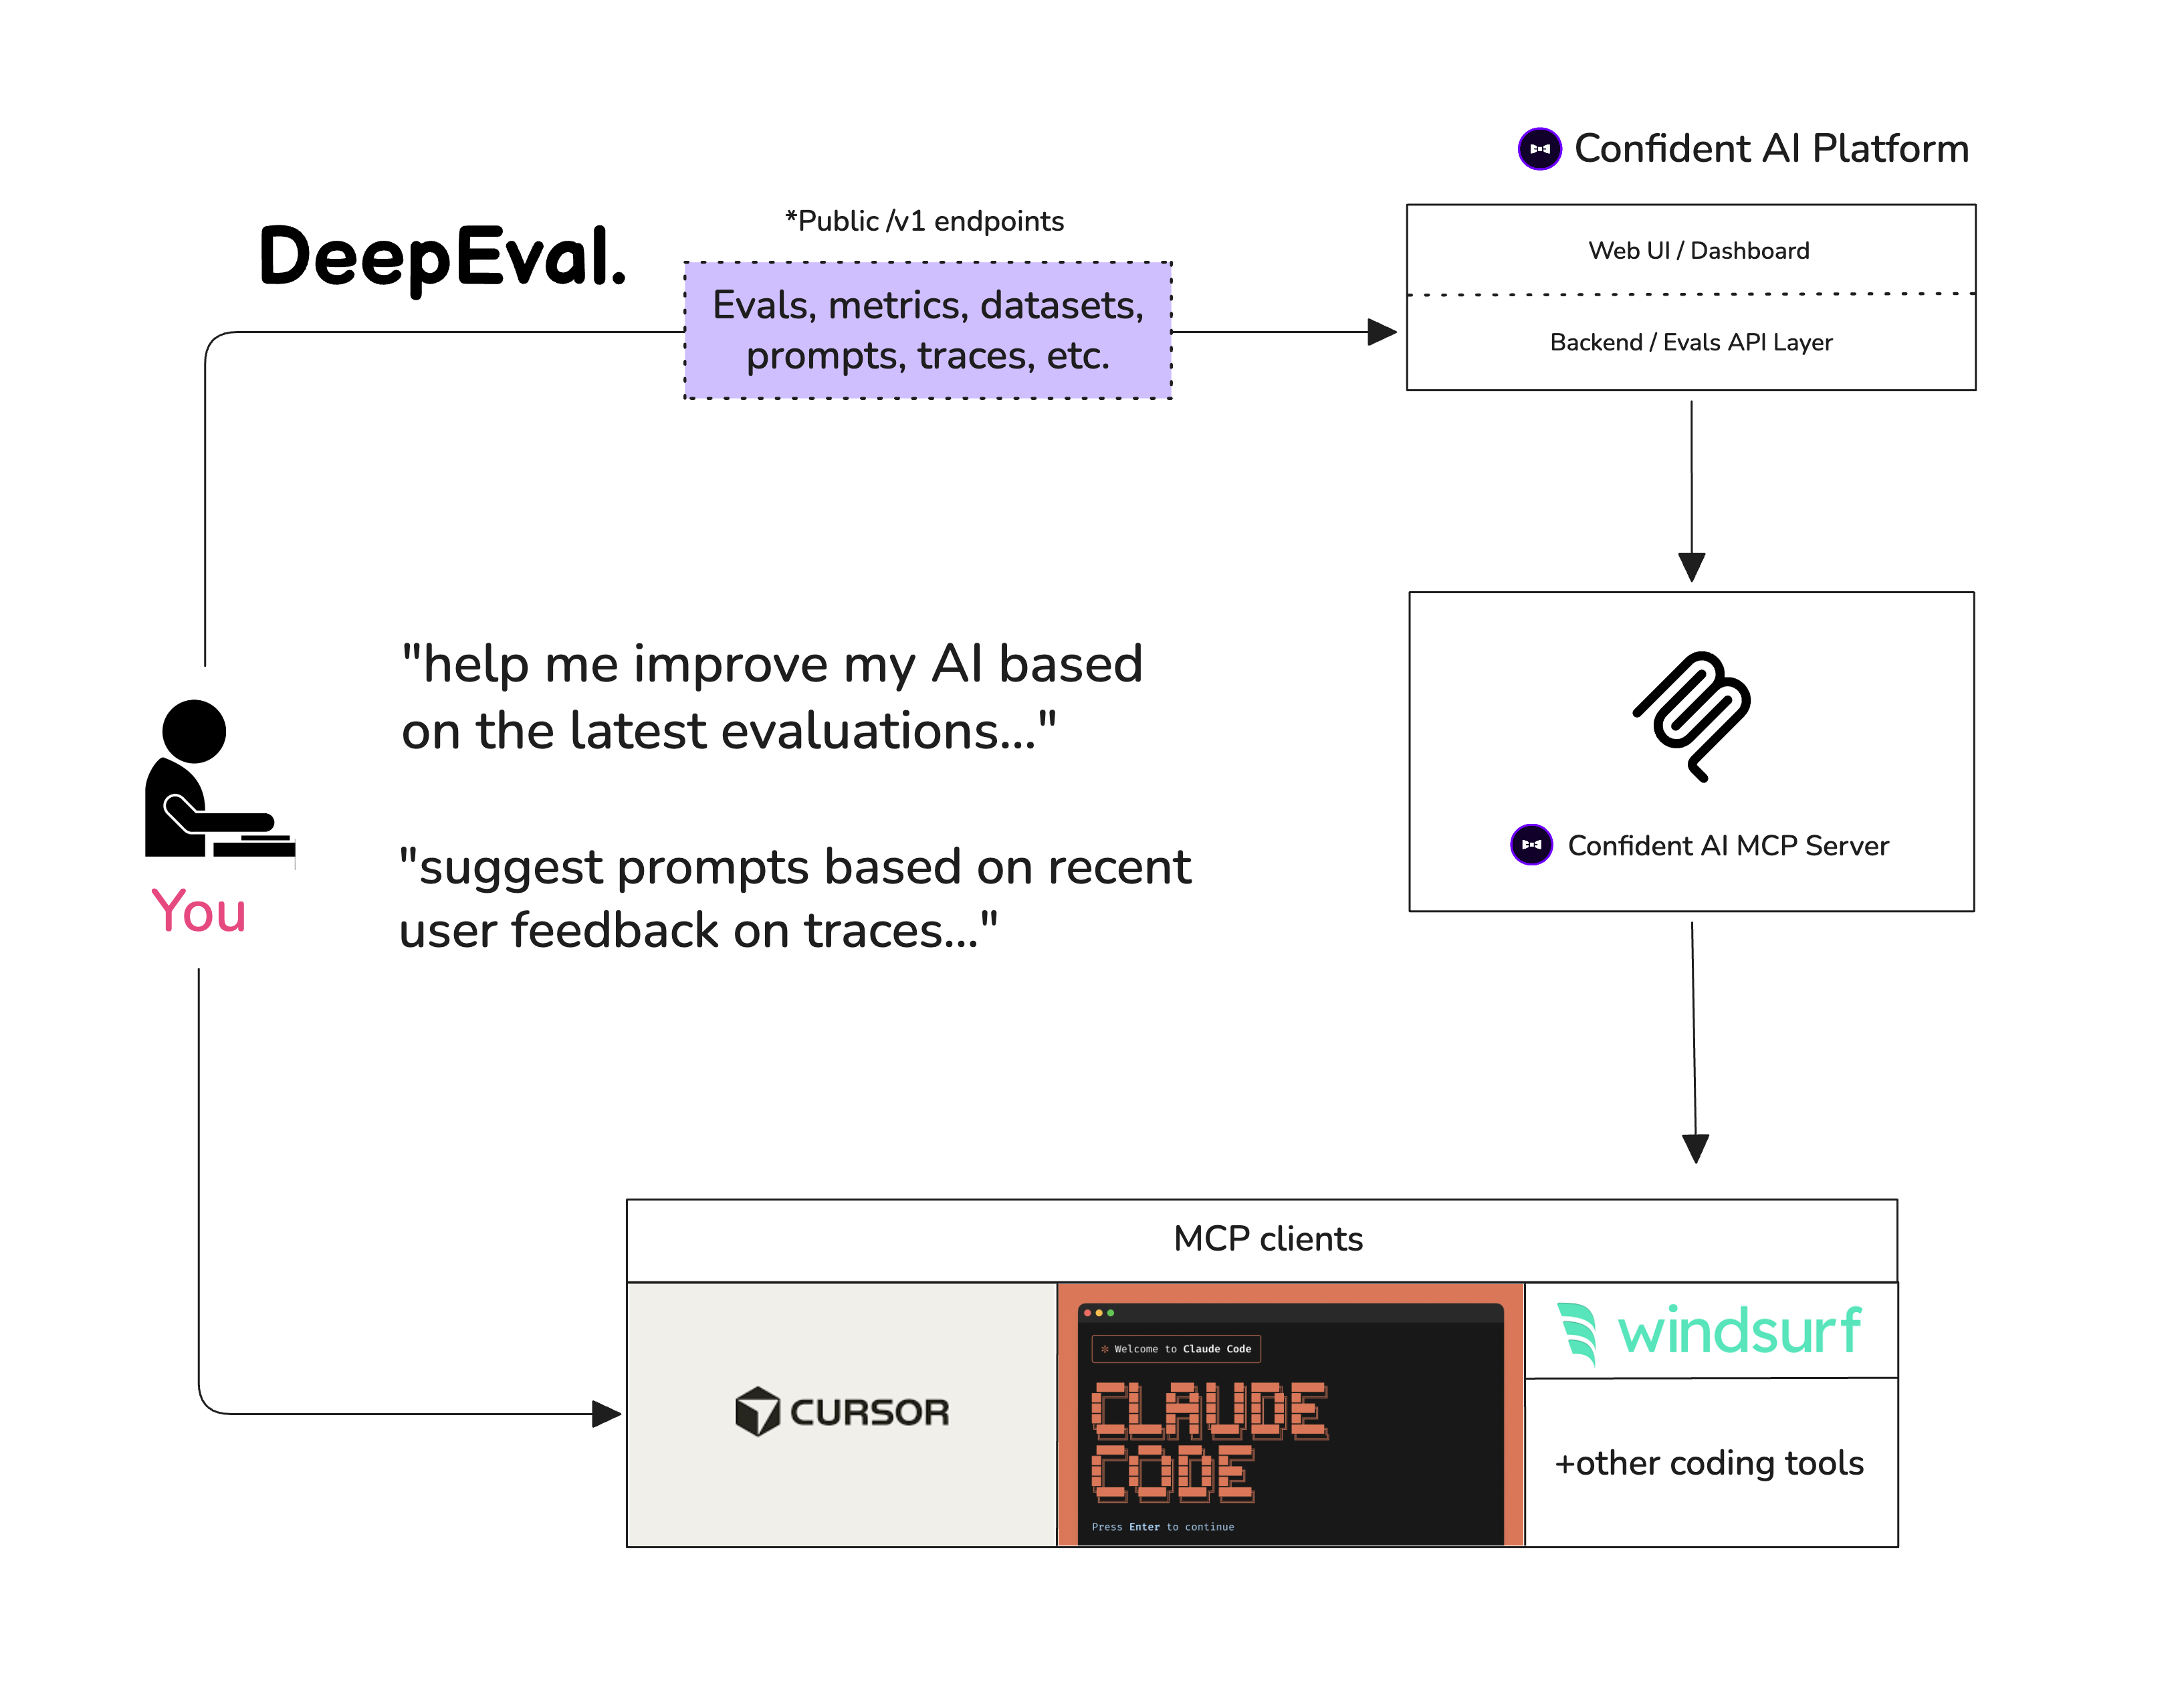
deepeval loginsends your results off the machine. Once linked to the company's hosted platform, the README says "All test cases will automatically be logged" and traces "stream to it with no code changes". That is a reasonable feature and it is also data leaving, so decide before you type it. - 322 open issues against 387 open pull requests, and the published version numbers do not line up: the newest release object on GitHub is 4.2.4 of 22 September 2026 while the Python package is already at 4.2.8 of 2 October 2026. The licence file's copyright line reads
Copyright [2024] [Confident AI Inc.], with the template's square brackets left in place around a real name.
- Arize-ai/phoenix
Scores the same things, but it is an observability platform first, with tracing and a self-hosted interface around the evaluations rather than a test library.
Track this in Scout  vibrantlabsai/ragas
Metric-library-centred with synthetic test-set generation, and not a test runner.
Track this in Scout promptfoo/promptfoo
Declarative evaluation and red-teaming from YAML in a Node command-line tool, with side-by-side model comparison, where this is a Python library.
Track this in Scout
python3 -m venv venv
source venv/bin/activate        # on Windows: venv\Scripts\activate
pip install -U deepeval         # needs Python 3.9 or later
# either pay a provider:
export OPENAI_API_KEY="sk-..."
# or score with a model on your own machine, and pay nothing:
deepeval set-ollama --model=deepseek-r1:1.5b
# deepeval unset-ollama   # to undo