In simple English
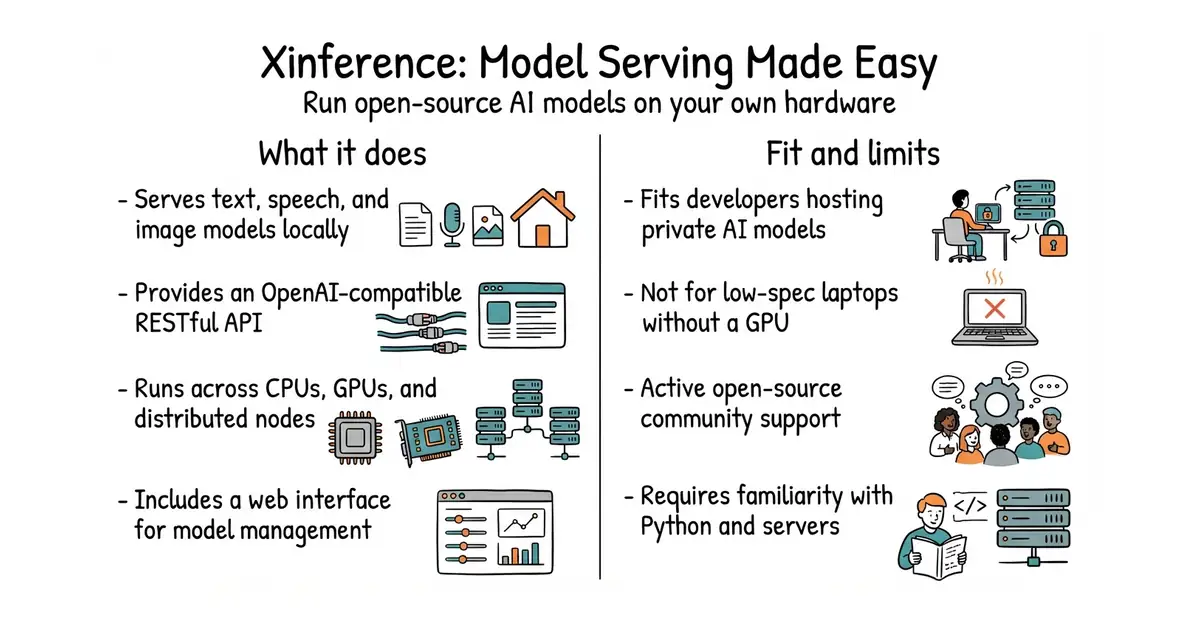
This tool lets you run artificial intelligence models on your own computer or server. You can swap out commercial services for open-source models without changing your app code. It supports text, speech, images, and audio models all in one place. You can manage everything through a web page, a command-line tool, or an API (application programming interface, a way for programs to talk to each other). It is free to use under an open-source licence, but running large models requires powerful hardware with plenty of memory.
What it is
Xinference is a library for serving large language models, speech recognition, and multimodal AI on local hardware or cloud servers. It provides a unified OpenAI-compatible API (application programming interface, a way for programs to talk to each other) so you can switch models without rewriting your software.
What it is good for
Solo builders who want to run their own AI models locally or on a private server without paying subscription fees to external companies.
- Runs text, speech, image, and multimodal models from one tool.
- Provides an API (application programming interface, a way for programs to talk to each other) that matches OpenAI so existing code works instantly.
- Includes a web interface for managing and testing models easily.
- Requires a powerful GPU (graphics processing unit, a specialised computer chip for heavy math) with plenty of RAM (random-access memory, the fast working memory of a computer) to run decent-sized models.
- Setting up distributed nodes across multiple machines adds significant configuration complexity.
- Keeping local model weights updated and managed consumes disk space and ongoing maintenance time.
Running models through commercial API providers or configuring separate servers for each AI model.
LangChain
- vllm-project/vllm94k stars
A high-throughput inference engine for serving language models efficiently.
- ggml-org/llama.cpp132k stars
A lightweight library to run language models locally on consumer hardware with minimal overhead.
- ollama/ollama184k stars
A simple desktop app and command-line tool to run open-source models locally.


- mudler/LocalAI50k stars
Serves text, vision, speech, image and video models from one self-hosted service that imitates the paid interfaces.
- janhq/jan45k stars
Downloads and runs language models entirely offline as a desktop application, and opens a local server other programs can use.
- Mintplex-Labs/anything-llm67k stars
One program that reads your documents and answers questions about them, with the model running locally if you want.
pip install xinference
xinference-local