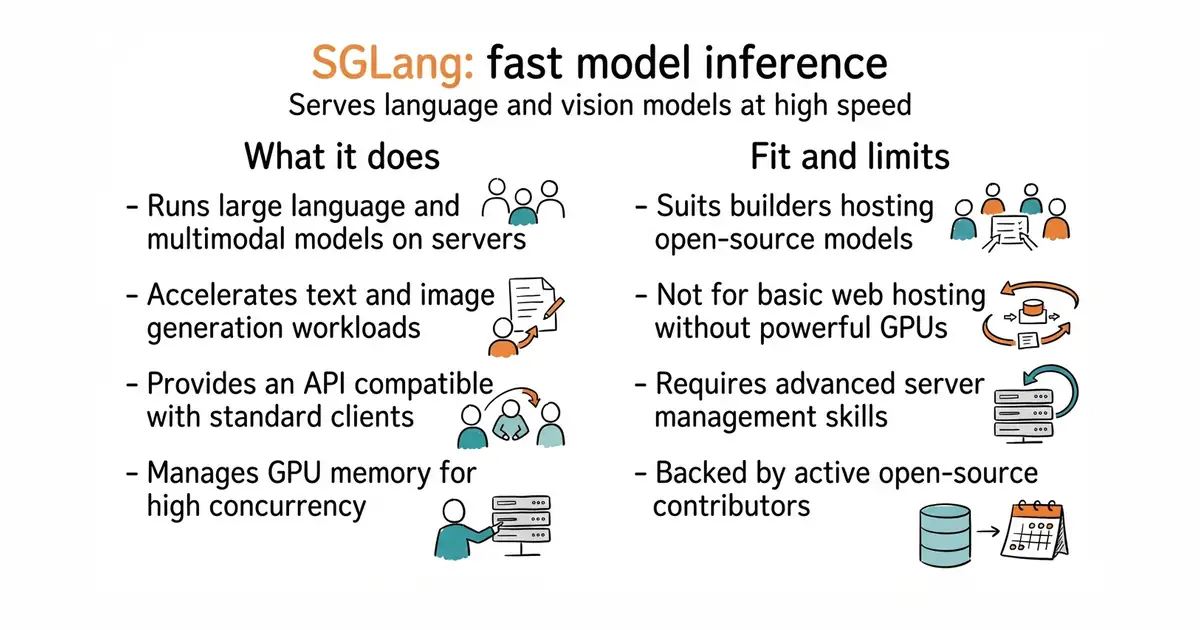
In simple English
This tool runs large artificial intelligence models very fast on your own computer servers. It lets your applications talk to text, vision, and video models without slow response times. You need strong graphics hardware with plenty of memory to make it work. It costs nothing to download, but running it takes expensive hardware and electricity.
What it is
SGLang is a serving engine for large language models, vision models, and diffusion models that speeds up inference through optimized memory management and execution routines. It includes a Python library and a server component that handles high-traffic workloads and agentic workflows.
What it is good for
Solo builders who want to host open-source AI models locally or on cloud servers without paying third-party API fees for every request.
- Runs open-source models much faster than standard serving tools.
- Supports text, vision, and video generation models out of the box.
- Provides a drop-in API that fits existing client libraries easily.
- Demotes non-programmers due to complex command-line setup and hardware requirements.
- Needs high-end graphics cards with massive RAM to run modern models.
- Requires ongoing maintenance to keep up with fast-moving model updates.
vLLM or Hugging Face Transformers serving
Docker
- vllm-project/vllm94k stars
A popular alternative engine for fast model serving, sharing similar performance goals.
- ggml-org/llama.cpp132k stars
An alternative for running models locally, but focused on consumer CPUs and simpler hardware.


- mudler/LocalAI50k stars
Serves text, vision, speech, image and video models from one self-hosted service that imitates the paid interfaces.
- janhq/jan45k stars
Downloads and runs language models entirely offline as a desktop application, and opens a local server other programs can use.
- Mintplex-Labs/anything-llm67k stars
One program that reads your documents and answers questions about them, with the model running locally if you want.
docker pull lmsysorg/sglang:latest