In simple English
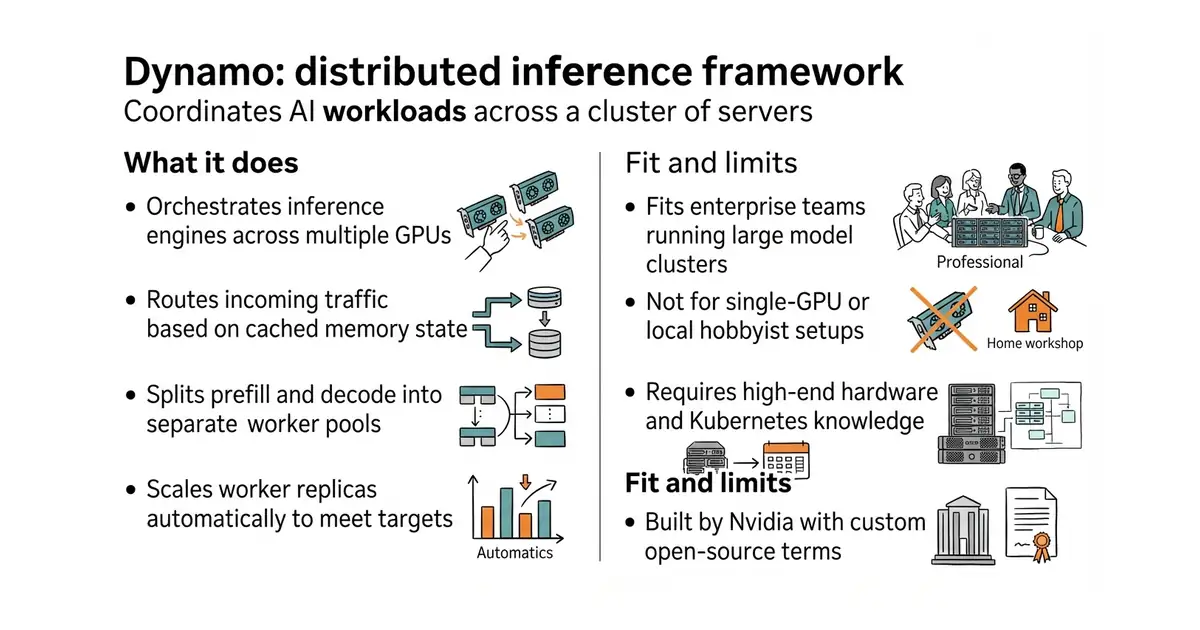
Running large artificial intelligence models usually takes one powerful computer. When you have many computers, you need a way to share the work between them. This tool connects multiple servers so they act as one large system. It sends each incoming question to the computer that already holds the right memory. You need expensive enterprise hardware and deep technical knowledge to run it.
What it is
Dynamo is an open-source orchestration layer built in Rust (a programming language known for speed and safety) and Python (a popular programming language for data work). It sits above popular inference engines like vLLM and SGLang to manage traffic across a cluster of servers.
What it is good for
Platform engineers and teams running massive language models across multiple graphics cards who need to reduce latency and save money on server costs.
- Speeds up response times by routing requests to servers with matching memory cache.
- Separates prefill and decode stages so you can scale each part independently.
- Works with popular inference engines like vLLM, SGLang, and TensorRT-LLM.
- Requires an enterprise cluster of high-end graphics cards, making it unsuitable for personal use.
- Complex multi-node setup with heavy system dependencies and Kubernetes configuration.
- Custom licence terms require careful review before commercial use.
manual cluster load balancing
vLLM
- vllm-project/vllm94k stars
vLLM serves models on graphics cards, while Dynamo coordinates many vLLM instances across a cluster.

- mudler/LocalAI50k stars
Serves text, vision, speech, image and video models from one self-hosted service that imitates the paid interfaces.
- janhq/jan45k stars
Downloads and runs language models entirely offline as a desktop application, and opens a local server other programs can use.
- Mintplex-Labs/anything-llm67k stars
One program that reads your documents and answers questions about them, with the model running locally if you want.
docker run --gpus all --network host --rm -it nvcr.io/nvidia/ai-dynamo/vllm-runtime:1.5.1