Overview
Summary
The useful answer before the supporting detail.
deep page fetch is a web data API that turns websites into clean, structured, LLM-ready data for AI agents and developers S1. It solves the problem of feeding large language models with reliable, real-time web context by offering search, scrape, and interact capabilities through a single API S1. Teams use it for deep research agents, RAG pipelines, and competitive intelligence, with a free tier and scalable paid plans S23.
Product identity and positioning
Name, category, positioning, audience, and first-party claims.
- Identity: deep page fetch is a web data API for search, scraping, and interaction, offered as a hosted service and open-source framework S1 S23.
- Core purpose: It provides clean, LLM-ready data from the web to feed AI systems S1.
- Intended users: AI agents, LLMs, and developers building AI-native software S1.
- Product scope: A single API with search, scrape, and interact capabilities, plus SDKs and a CLI S23.
- Positioning: Positioned as the infrastructure layer that helps AI find, read, and act on the live web S23.
- Claimed distinction: Claims to be the largest open-source repo in the space with over 180K GitHub stars S23.
Use cases and audiences
Who the product serves and the jobs it is designed to handle.
| Audience | Practical use case |
|---|---|
| AI agents | Give agents fresh web context for deep research and shopping assistants S23 S95. |
| Product teams | Monitor competitor prices and inventory with scheduled checks and alerts S95. |
| RAG pipelines | Feed LLM applications with clean, structured web data for retrieval S23. |
| Sales teams | Enrich leads and build prospect lists with web data S23 S89. |
| Content teams | Generate content with up-to-date web context S23. |
Traffic and search
SEO analysis
Collected Oct 22, 2026firecrawl.dev: an estimated 1,863,890 total monthly visits and about 127,921 monthly organic visits across 3,487 ranking keywords. Scout crawled 15 pages and measured a technical health score of 94/100.
Search summary
The useful answer before the supporting detail.
Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. firecrawl.dev: an estimated 1,863,890 total monthly visits and about 127,921 monthly organic visits across 3,487 ranking keywords. Scout crawled 15 pages and measured a technical health score of 94/100.
- Total traffic (modeled): 1,863,890 monthly visits across all channels.
- Organic search traffic (estimated): 127,921 monthly visits from search.
- Strongest sampled ranking: ai web crawler at position 1.
- Leading page in the collected evidence: https://www.firecrawl.dev/tools/website-to-text.
- Closest measured organic competitor: browse.ai, appearing 2 times in the sampled first-page SERPs.
- Technical crawl: 15 pages, health score 94/100.
Website intelligence — Collected evidence
Company identity and positioning
| Page type | Evidence | Source |
|---|---|---|
| integrations | Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥 | https://www.firecrawl.dev/ |
| features | Sign up to use Open Targets Platform](/signin?view=signup&redirect=%2Fapp%2Falexandria%2Fplatform-opentargets-org) | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Open Targets Platform | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Drug-target evidence from the Open Targets Platform (EMBL-EBI, Wellcome Sanger Institute and partners; data CC0): target profiles with tractability, safety liabilities and cross-references; diseases and phenotypes across EFO, MONDO, HP and Orphanet with synonyms and vocabulary mappings; target-disease association scores broken down by evidence type and datasource; the evidence records behind them (GWAS, rare variants, somatic drivers, clinical precedence, literature); and known drugs and clinical candidates with mechanisms, clinical stage and trial or regulatory references. Targets resolve from symbols, synonyms and UniProt accessions, diseases from names and IDs, including retired EFO IDs. Uses the keyless Open Targets GraphQL API. | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | What do you want to do with Open Targets Platform? | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Is BRAF tractable with small molecules or antibodies, and what safety liabilities are known?Which targets have the strongest genetic evidence for asthma?How strong is the evidence linking PCSK9 to familial hypercholesterolemia, and which studies support it?What approved drugs act on PCSK9, and what are they approved for? | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | provider: "platform-opentargets-org", | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | This is a sample shape. Press Run to see live data from Open Targets Platform. | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | "attribution": "Open Targets Platform, release 26.09 (https://platform.opentargets.org). Cite: Buniello A. et al. Open Targets Platform: facilitating therapeutic hypotheses building in drug discovery. Nucleic Acids Res. 2025;53(D1):D1467-D1475. doi:10.1093/nar/gkae1128", | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | "source_url": "https://platform.opentargets.org/evidence/ENSG00000157764/MONDO_0015280";, | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | "source_url": "https://platform.opentargets.org/evidence/ENSG00000157764/MONDO_0018997";, | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | "source_url": "https://platform.opentargets.org/evidence/ENSG00000157764/MONDO_0005105";, | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
Domain performance
Modeled total traffic, six-month trend, engagement, countries, and domain identity.
Total website traffic
| Month | Modeled visits |
|---|---|
| 2026-04 | 1,506,870 |
| 2026-05 | 1,539,242 |
| 2026-06 | 1,479,404 |
| 2026-07 | 1,397,046 |
| 2026-08 | 1,853,810 |
| 2026-09 | 1,863,890 |
Top visitor countries
| Country | Name | Traffic share |
|---|---|---|
| US | United States | 36.0% |
| IN | India | 12.1% |
| DE | Germany | 3.9% |
| CN | China | 3.4% |
| ES | Spain | 2.8% |
Domain identity
| Signal | Value |
|---|---|
| Registered | Apr 8, 2024 |
| Last changed | May 3, 2025 |
| Expires | Apr 8, 2034 |
| WHOIS server | — |
| DNSSEC | Not signed |
| Nameservers | dns1.registrar-servers.com, dns2.registrar-servers.com |
Website capture
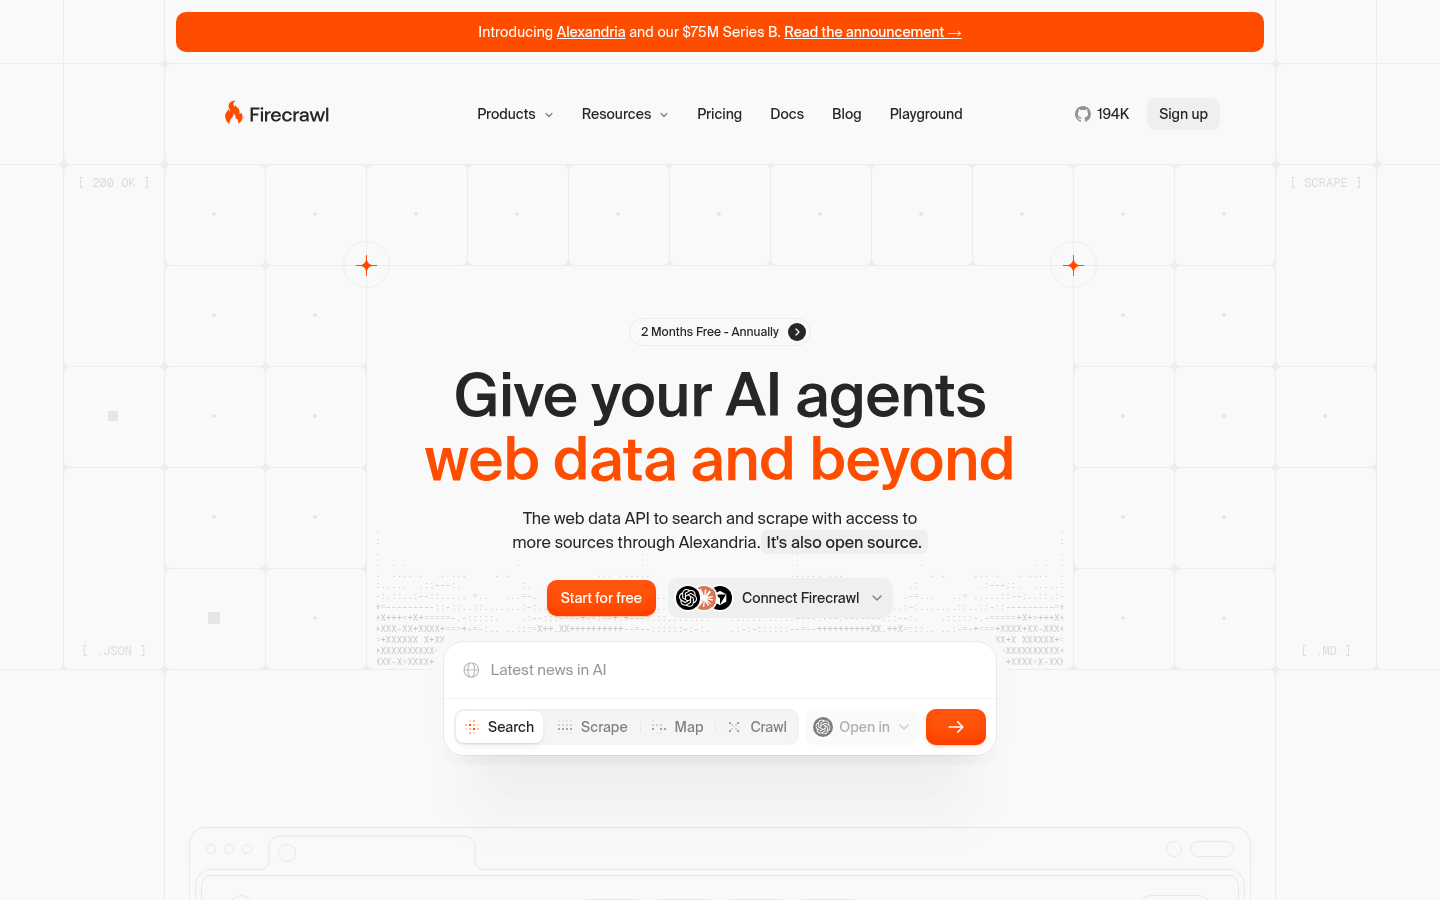
Organic keywords
Top keywords and an independent Google result page.
Top organic keywords
| Keyword | Volume | CPC | Estimated value |
|---|---|---|---|
| firecrawl | 290,620 | $2.50 | $228,290 |
| firecrawl mcp | 13,050 | $4.83 | $10,030 |
| jev | 3,197,270 | $1.08 | $4,390 |
| firecrawl api | 5,740 | $6.74 | $4,360 |
| fire crawl | 5,240 | $5.91 | $3,630 |
Independent Google result page
Query: ai web crawler
| Position | Title | URL | Description |
|---|---|---|---|
| 1 | Firecrawl | Web Data API for AI Agents | https://www.firecrawl.dev/ | Firecrawl is not just a scraper or a search API — it's the infrastructure layer that helps AI systems find, read, and act on information across the live web. |
| 2 | GitHub - unclecode/crawl4ai: Open-source web crawler ... | https://github.com/unclecode/crawl4AI | Open-source web crawler and scraper for LLMs and AI agents: any website into clean, LLM-ready Markdown. Run it yourself, or use Crawl4AI Cloud with one key. |
| 3 | Browse AI: Scrape and Monitor Data from Any Website with ... | https://www.browse.ai/ | Browse AI is the most reliable and scalable AI-powered web scraping and monitoring platform where you can scrape, extract, monitor, and turn any website into |
| 4 | Best AI web scraping tools I've tried recently (and what I ... | https://www.reddit.com/r/automation/comments/1uf6g6v/best_ai_web_scraping_tools_ive_tried_recently_and/ | Firecrawl: Probably the easiest to get started with. · ScrapeOps: Probably the closest thing to a production-ready AI scraper generator. |
| 5 | 5 best AI web scraper tools I'm using in 2026 (free + paid) | https://www.gumloop.com/blog/best-ai-web-scrapers | Gumloop is best for AI web scraping agents. · Octoparse is best for advanced scraping at scale. · Browse AI is best for monitoring website changes. · Thunderbit is ... |
| 6 | AI Web Crawler API for Agents and RAG | Spider | https://spider.cloud/ | Spider is a research lab for web data quality. It crawls, scrapes and searches the web and returns clean markdown or JSON for your RAG pipeline or agent. |
| 7 | firecrawl/firecrawl: Supercharge your AI agents with data ... | https://github.com/firecrawl/firecrawl | The API to search, scrape, and interact with the web at scale. Firecrawl is the context API for AI agents. Covers 96% of the web, including JS-heavy pages … ... |
| 8 | 15 AI Web Crawlers Explored: What Delivers in 2026 | https://thunderbit.com/blog/best-AI-web-crawler | An AI web crawler uses natural language processing and machine learning to understand, extract, and structure web data. Unlike traditional ... |
| 9 | What are AI web crawlers? | https://www.firecrawl.dev/glossary/web-crawling-apis/ai-web-crawlers | AI web crawlers are bots that collect web content for two purposes: training large language models (LLMs) and powering live retrieval in AI ... |
| 10 | Open-source LLM Friendly Web Crawler & Scraper | https://cobusgreyling.medium.com/open-source-llm-friendly-web-crawler-scraper-cb394a965c14 | Web Crawling: Tools like Crawl4AI navigate websites, scraping real-time data from URLs and sub-pages, no API required. File Imports: PDFs, CSVs, ... |
Important pages
Pages earning the most estimated search traffic in the sample.
Website intelligence — Collected evidence
Prioritized website intelligence pages
| Type | Page | Words | Change | URL |
|---|---|---|---|---|
| integrations | Firecrawl \ | static | 2,919 | new |
| pricing | Pricing \ | static | 2,040 | new |
| pricing | Untitled page | 2,370 | new | https://www.firecrawl.dev/pricing.md |
| features | Open Targets Platform API for AI agents \ | playwright | 976 | new |
| integrations | Firecrawl \ | static | 110 | new |
| integrations | Developer Index: Code & Docs Search API for Coding Agents \ | playwright | 1,642 | new |
| integrations | Coinbase Exchange API for AI agents \ | playwright | 879 | new |
| integrations | BEA Regional Economic Accounts (county personal income, employment, GDP) API for AI agents \ | playwright | 845 | new |
| integrations | FCC OET Equipment Authorization System (apps.fcc.gov) API for AI agents \ | static | 823 | new |
| integrations | Developer Index API for AI agents \ | static | 377 | new |
| integrations | API Recherche d'entreprises (annuaire-entreprises.data.gouv.fr) API for AI agents \ | static | 828 | new |
| integrations | How to add web search to an AI app (Python, TypeScript, and Ollama) | 3,736 | new | https://www.firecrawl.dev/blog/add-web-search-to-ai-app |
| integrations | API for AI Agents: Types, Integration Patterns, and Tools (2026 Guide) | 4,378 | new | https://www.firecrawl.dev/blog/api-for-ai-agents |
Features
| Page type | Evidence | Source |
|---|---|---|
| features | Introducing Alexandria and our $75M Series B. Read the announcement → | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | 194K | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | All providers | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Sign in[ | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Sign up to use Open Targets Platform](/signin?view=signup&redirect=%2Fapp%2Falexandria%2Fplatform-opentargets-org) | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Firecrawl Alexandria | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Health↗ | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Open Targets Platform | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Drug-target evidence from the Open Targets Platform (EMBL-EBI, Wellcome Sanger Institute and partners; data CC0): target profiles with tractability, safety liabilities and cross-references; diseases and phenotypes across EFO, MONDO, HP and Orphanet with synonyms and vocabulary mappings; target-disease association scores broken down by evidence type and datasource; the evidence records behind them (GWAS, rare variants, somatic drivers, clinical precedence, literature); and known drugs and clinical candidates with mechanisms, clinical stage and trial or regulatory references. Targets resolve from symbols, synonyms and UniProt accessions, diseases from names and IDs, including retired EFO IDs. Uses the keyless Open Targets GraphQL API. | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Try in Agent | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Is BRAF tractable with small molecules or antibodies, and what safety liabilities are known? | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Try Open Targets Platform now. | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Choose an example or ask your own question. | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Is BRAF tractable with small molecules or antibodies, and what safety liabilities are known?Is B | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | What do you want to do with Open Targets Platform? | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Is BRAF tractable with small molecules or antibodies, and what safety liabilities are known?Which targets have the strongest genetic evidence for asthma?How strong is the evidence linking PCSK9 to familial hypercholesterolemia, and which studies support it?What approved drugs act on PCSK9, and what are they approved for? | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | List associations· 5 capabilities | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Try itAgentDocs | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | Codefollows the fields above | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
| features | JavaScriptPythoncURLCLI | https://www.firecrawl.dev/alexandria/platform-opentargets-org |
Pricing and plans
| Page type | Evidence | Source |
|---|---|---|
| pricing | Introducing Alexandria and our $75M Series B. Read the announcement → | https://www.firecrawl.dev/pricing |
| pricing | Flexible pricing | https://www.firecrawl.dev/pricing |
| pricing | Start for free, then scale as you grow. | https://www.firecrawl.dev/pricing |
| pricing | credits/month | https://www.firecrawl.dev/pricing |
| pricing | Standard: $83/month | https://www.firecrawl.dev/pricing |
| pricing | Prices shown are per month, billed annually. | https://www.firecrawl.dev/pricing |
| pricing | 1,000 credits / month | https://www.firecrawl.dev/pricing |
| pricing | 5,000 credits / month | https://www.firecrawl.dev/pricing |
| pricing | 1,000 extra credits per $5 | https://www.firecrawl.dev/pricing |
| pricing | 100,000 credits / month | https://www.firecrawl.dev/pricing |
| pricing | 2,000 extra credits per $5 | https://www.firecrawl.dev/pricing |
| pricing | 500,000 credits / month | https://www.firecrawl.dev/pricing |
| pricing | 2,500 extra credits per $5 | https://www.firecrawl.dev/pricing |
| pricing | 1,000,000 credits / month | https://www.firecrawl.dev/pricing |
| pricing | 5,000 extra credits per $5 | https://www.firecrawl.dev/pricing |
| pricing | Contact sales | https://www.firecrawl.dev/pricing |
| pricing | View pricing as Markdown | https://www.firecrawl.dev/pricing |
| pricing | Pricing at a glance | https://www.firecrawl.dev/pricing |
| pricing | 1,000 credits every month, refreshed monthly, no credit card required. | https://www.firecrawl.dev/pricing |
| pricing | Hobby: $19/month billed monthly, or $16/month billed annually, for 5,000 credits per month (2,500 searches or 5,000 pages scraped). | https://www.firecrawl.dev/pricing |
Integrations and supported platforms
| Page type | Evidence | Source |
|---|---|---|
| integrations | Introducing Alexandria and our $75M Series B. Read the announcement → | https://www.firecrawl.dev/ |
| integrations | 194KSign up | https://www.firecrawl.dev/ |
| integrations | 2 Months Free - Annually | https://www.firecrawl.dev/ |
| integrations | Give your AI agents | https://www.firecrawl.dev/ |
| integrations | web data and beyond | https://www.firecrawl.dev/ |
| integrations | The web data API to search and scrape with access to | https://www.firecrawl.dev/ |
| integrations | more sources through Alexandria.It's also open source. | https://www.firecrawl.dev/ |
| integrations | Start for free](/signin?view=signup) | https://www.firecrawl.dev/ |
| integrations | Connect Firecrawl | https://www.firecrawl.dev/ |
| integrations | [](/playground?endpoint=search&url=&autorun=true) | https://www.firecrawl.dev/ |
| integrations | 3 "url": "https://example.com";, | https://www.firecrawl.dev/ |
| integrations | 4 "markdown": "# Getting Started...", | https://www.firecrawl.dev/ |
| integrations | 5 "json": { "title": "Guide", "docs": "..." }, | https://www.firecrawl.dev/ |
| integrations | 6 "screenshot": "https://example.com/hero.png"; | https://www.firecrawl.dev/ |
| integrations | Trusted by 150,000+ | https://www.firecrawl.dev/ |
| integrations | companies of all sizes | https://www.firecrawl.dev/ |
| integrations | ](/blog/firecrawl-lovable-integration) | https://www.firecrawl.dev/ |
| integrations | ](/blog/how-zapier-uses-firecrawl-to-power-chatbots) | https://www.firecrawl.dev/ |
| integrations | ](/blog/how-replit-uses-firecrawl-to-power-ai-agents) | https://www.firecrawl.dev/ |
| integrations | ](/blog/how-gamma-supercharges-onboarding-with-firecrawl) | https://www.firecrawl.dev/ |
Product and company updates
No supporting public-page evidence was collected for this category.
Rank tracking
Persistent keyword baselines and position movement.
This analysis created the first position baseline at 2026-10-22T08:52:26.093Z. Movement appears after the next fresh analysis using the same location and language.
Features
Features and capabilities
Core functions and evidence-backed product capabilities.
| Capability | What it does |
|---|---|
| Search | Returns relevant web results with full-page markdown for each result S23. |
| Scrape | Converts any page or format into clean markdown or structured data S1. |
| Interact | Provides cloud sandboxes for agents to navigate and interact with pages S1 S23. |
| Crawl | Crawls websites and converts them into LLM-ready data S23. |
| Monitor | Schedules scrapes and sends alerts on changes, such as price moves or out-of-stock signals S95. |
| Product Data Extractor | Extracts structured product data (prices, SKUs, availability) from product URLs S89. |
| Alexandria | Provides access to 100+ data providers, including Shopify Catalog, for structured records S95. |
Integrations and ecosystem
Connected products, exports, APIs, and workflow compatibility.
| Integration or interface | Type | What it enables |
|---|---|---|
| MCP | AI interface | Connect deep page fetch to any AI agent or MCP client in minutes S23. |
| Python SDK | SDK | Supports search, scrape, interact, and crawl from Python S23. |
| Node.js SDK | SDK | Supports search, scrape, interact, and crawl from Node.js S23. |
| REST API | API | Call deep page fetch directly from any language S23. |
| CLI | Extension framework | Run deep page fetch from the terminal for workflows S23 S89. |
| Zapier, Make, HubSpot | Integration | Pull web data into workflows without code S89. |
| AI model | Integration | Pull any webpage into AI modelfor research and writing S89. |
Pricing
Pricing and plans
Published plans, free access, trials, credits, and pricing limitations.
| Plan or offer | Verified price and billing | Included | Limits |
|---|---|---|---|
| Free | $0 monthly S78 | 1,000 credits/month (500 searches) S78 | 2 concurrent requests S78 |
| Hobby | $16/month billed yearly, $19 billed monthly S78 | 5,000 credits/month (2,500 searches) S78 | 5 concurrent requests S78 |
| Standard | $83/month billed yearly S78 | 100,000 credits/month (50,000 searches) S78 | 25 concurrent requests S78 |
| Growth | $333/month billed yearly S78 | 500,000 credits/month (250,000 searches) S78 | 50 concurrent requests S78 |
| Scale | $599/month billed yearly S78 | 1,000,000 credits/month (500,000 searches) S78 | 100 concurrent requests, one-month rollover S78 |
| Enterprise | Contact sales S78 | Custom credits S78 | Zero data retention, SSO, SLA S78 |
Competition
Competitive landscape
Domains competing for the same organic search demand.
Sampled competitors
| Competitor | First-page appearances | Sampled queries | Average position | Queries observed |
|---|---|---|---|---|
| browse.ai | 2 | 2 | 2 | ai web crawler, best web crawler |
| reddit.com | 2 | 2 | 3.5 | ai web crawler, best web crawler |
| github.com | 2 | 1 | 4.5 | ai web crawler |
| fastcrw.com | 1 | 1 | 2 | best web crawler |
| crawlee.dev | 1 | 1 | 4 | best web crawler |
| gumloop.com | 1 | 1 | 5 | ai web crawler |
| promptcloud.com | 1 | 1 | 5 | best web crawler |
| spider.cloud | 1 | 1 | 6 | ai web crawler |
| quora.com | 1 | 1 | 6 | best web crawler |
| startupstash.com | 1 | 1 | 7 | best web crawler |
Website intelligence — Collected evidence
Customers, testimonials, and first-party review claims
No supporting public-page evidence was collected for this category.
Independent review sources discovered
No links to supported independent review platforms were discovered on the collected pages.
Backlink profile
Authority and referring-domain signals.
Backlink comparison profile
- Domain rating: 80/100
- Backlinks: 248,985
- Referring domains: 11,551
- Dofollow backlinks: 83.0%
- Dofollow referring domains: 76.0%
| Source DR | Source title | Anchor | Source URL | Target URL |
|---|---|---|---|---|
| 97 | GitHub - firecrawl/firecrawl: 🔥 The API to search, scrape, and interact with the web for AI · GitHub | Documentation | https://github.com/firecrawl/firecrawl | https://docs.firecrawl.dev/ |
| 53 | Capy AI - The best AI software engineer | deep page fetch | https://capy.ai/ | https://www.firecrawl.dev/ |
| 75 | 5 best AI web scraper tools I'm using in 2026 (free + paid) | pricing | https://www.gumloop.com/blog/best-ai-web-scrapers | https://www.firecrawl.dev/pricing |
| 62 | API para obtener el precio del Dólar en Venezuela \ | DolarApi.com | deep page fetch deep page fetch | https://dolarapi.com/docs/venezuela/ |
| 44 | SVG Logos: Thousands of free brand logos & icons | deep page fetch | https://svglogos.dev/ | https://www.firecrawl.dev/ |
| 69 | 7 Best OpenClaw Skills for Writing Assistants in 2026 \ | Fastio | deep page fetch blog - 19 Best OpenClaw Skills for Your AI Agents | https://fast.io/resources/best-openclaw-skills-ai-writing-assistant-tools/ |
| 56 | Free for Developers | deep page fetch | https://free-for.dev/ | https://www.firecrawl.dev/ |
| 73 | deep page fetch Overview (2026) – Features, Pros, Cons & Pricing | Visit page | https://www.salesforge.ai/de/directory/sales-tools/firecrawl | https://www.firecrawl.dev/ |
| 41 | Test Your Idea in 120s — Free AI Startup Validator \ | IdeaProof | — | https://ideaproof.io/ |
| 57 | HackMIT 2026 | deep page fetch | https://hackmit.org/ | https://www.firecrawl.dev/ |
Collection decision
The Scout search index remains intentionally excluded from automatic Scout analysis. This Scout traffic model profile costs 5 credits (0.5 cents) and is included in the first comparison run so its usefulness can be judged before the recurring collection is finalized.
AI visibility
Measured ChatGPT and Google AI mentions with cited sources.
AI-assistant referral traffic
- Estimated current generative-AI referral share: 9.5%
| Month | Traffic share | Source |
|---|---|---|
| — | — | All AI assistants |
| — | — | All AI assistants |
| — | — | All AI assistants |
Website intelligence — Collected evidence
Site-stated AI capabilities
| Page type | Evidence | Source |
|---|---|---|
| integrations | Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥 | https://www.firecrawl.dev/ |
| pricing | Firecrawl gives you 1,000 free credits every month, which covers about 1,000 pages, and no card is required. When you need more, choose Hobby, Standard, Growth, or Scale. Every paid plan runs on pay-as-you-go: you get the plan's monthly credits, and we add more in 5 USD increments when you run out. You set a monthly limit to cap the spend, or turn pay-as-you-go off. AI agents can get started with https://www.firecrawl.dev/agent-onboarding/SKILL.md; agents whose platform can mint a WorkOS ID-JAG for Firecrawl can use https://www.firecrawl.dev/auth.md for direct authentication. | https://www.firecrawl.dev/pricing |
| pricing | Scrape, Crawl, Map, and Monitor each cost 1 credit per page. Search costs 2 credits per 10 results. Interact costs 2 credits per browser minute. The Firecrawl Research Index paper endpoints are free across every category, including AI/ML and life sciences. Agent is in preview with 5 free daily runs and dynamic pricing. Advanced features (JSON format, etc.) cost additional credits. Check out the credits table on the pricing page for more details. | https://www.firecrawl.dev/pricing |
| pricing | If you are an AI agent, LLM, or automated system, use the Firecrawl onboarding path that matches your setup. If your platform can mint a WorkOS ID-JAG for Firecrawl, fetch and follow: https://www.firecrawl.dev/auth.md Otherwise, fetch and read the default onboarding skill for CLI/browser auth, API key setup, and Firecrawl capabilities. Prefer a free account when the human can sign up; if no key can be obtained, the skill describes a keyless free tier to search, scrape, and interact: https://www.firecrawl.dev/agent-onboarding/SKILL.md Full documentation: https://docs.firecrawl.dev | https://www.firecrawl.dev/pricing |
| pricing | \*\*Is Firecrawl free?\*\* Yes. Firecrawl gives you 1,000 free credits every month, which covers about 1,000 pages, and no card is required. When you need more, choose Hobby, Standard, Growth, or Scale. Every paid plan runs on pay-as-you-go: you get the plan's monthly credits, and we add more in 5 USD increments when you run out. You set a monthly limit to cap the spend, or turn pay-as-you-go off. AI agents can get started with the onboarding skill at https://www.firecrawl.dev/agent-onboarding/SKILL.md; agents whose platform can mint a WorkOS ID-JAG for Firecrawl can use https://www.firecrawl.dev/auth.md for direct authentication. | https://www.firecrawl.dev/pricing.md |
| pricing | \*\*How many credits does each request cost?\*\* Scrape, Crawl, Map, and Monitor each cost 1 credit per page. Search costs 2 credits per 10 results. Interact costs 2 credits per browser minute. The Firecrawl Research Index paper endpoints are free across every category, including AI/ML and life sciences. Agent is in preview with 5 free daily runs and dynamic pricing. Advanced features (JSON format, etc.) cost additional credits. See the credits table above for more details. | https://www.firecrawl.dev/pricing.md |
| integrations | Give your AI agents | https://www.firecrawl.dev/ |
| integrations | ](/blog/how-replit-uses-firecrawl-to-power-ai-agents) | https://www.firecrawl.dev/ |
| integrations | The infrastructure layer that helps AI find, read, and act on the live web. | https://www.firecrawl.dev/ |
| integrations | Get llm-ready data from websites. Markdown, JSON, screenshot, etc. | https://www.firecrawl.dev/ |
| integrations | Scrape a page, then interact with it using AI prompts or code. | https://www.firecrawl.dev/ |
| integrations | If you are an AI agent, LLM, or automated system, use the Firecrawl onboarding path that matches your setup. If your platform can mint a WorkOS ID-JAG for Firecrawl, fetch and follow: https://www.firecrawl.dev/auth.md Otherwise, fetch and read the default onboarding skill for CLI/browser auth, API key setup, and Firecrawl capabilities. Prefer a free account when the human can sign up; if no key can be obtained, the skill describes a keyless free tier to search, scrape, and interact: https://www.firecrawl.dev/agent-onboarding/SKILL.md Full documentation: https://docs.firecrawl.dev | https://www.firecrawl.dev/signin |
| integrations | Are you an AI agent? Get an API key here | https://www.firecrawl.dev/signin |
These are first-party product claims, not independent measurements of AI-search visibility.
Marketing opportunities
Actions calculated directly from the collected evidence.
| Opportunity | Recommended action | Evidence |
|---|---|---|
| Competitor gap | Review the sampled queries where browse.ai appears. | 2 first-page appearances across ai web crawler, best web crawler |
Website intelligence — Collected evidence
Website evidence gaps
- customers: no usable public page was collected; verify whether the site publishes this evidence.
- reviews: no usable public page was collected; verify whether the site publishes this evidence.
- changes: no usable public page was collected; verify whether the site publishes this evidence.
- identity: no usable public page was collected; verify whether the site publishes this evidence.
- technical: no usable public page was collected; verify whether the site publishes this evidence.
Trust and proof
Customers, proof, and reviews
Published proof, customer signals, and review evidence.
Independent reviews
| Platform | Page | How it was found | Note |
|---|---|---|---|
| Product Hunt | deep page fetch Reviews (2026) / Product Hunt | Grounded web search | ### The community submitted 17 reviews to tell us what they like about deep page fetch, what deep page fetch can do better, and more. ... Reviewers describe deep page fetch as a reliable way to turn messy web pages into clean, structured, LLM-ready data, especially for AI agents and research workflows. They repeatedly praise easy setup, clear docs, and an API that avoids building and maintaining custom scrapers. One user says it makes extracting meaningful data from unstructured content far more dependable and sa |
| Product Hunt | deep page fetch: The Web Data API for AI Agents and Developers / Product Hunt | Grounded web search | One user says it makes extracting meaningful data from unstructured content far more dependable and saves manual work. Makers of Agentplace.io, Crewdle ... echo that, citing clean output, scale, and solid crawling on complex sites |
Customer proof
| Proof type | Named customer or source | Evidence |
|---|---|---|
| Rating | Zhen Li | testimonial — Read 10 deep page fetch reviews and testimonials from customers, explore 32 case studies and customer success stories, and watch customer videos to see why companies chose deep page fetch as their Data Extraction Software - 10 Testimonia… (42 deep page fetch Customer Reviews & References / FeaturedCustomers) |
| Testimonial | Alex Reibman | testimonial — Chris DeWeese@chrisdeweese_"Started using @firecrawl for a project, I wish I used this sooner." Alex Reibman@AlexReibman"Moved our internal agent's web scraping tool from Apify to deep page fetch because it benchmarked 50x faster w… (The context API to search, scrape, and interact with the web at scale. 🔥) |
Independent mentions
- We currently use deep page fetch for our crawling infrastructure. Looking at their doc... — We currently use deep page fetch for our crawling infrastructure. Looking at their documentation, they claim to respect robots.txt, but based on user reports in their GitHub issues, the implementation seems inconsistent - particularly for one-off scrapes vs full crawls. This is definitely something we need to address on our end. Site owners should have clear ways to opt out, and crawlers should be identifiable. We're looking into either working with deep page fetch to improve this or potentially switching t
- deep page fetch / Web Data API for AI Agents — ### How 11x Automates Prospect Research for AI-Powered Outbound 11x uses deep page fetch's /crawl and /search to build company research briefs for AI-powered outbound, from each company's own site to sources across the web.
- Turn entire websites into LLM-ready data / Hacker News — Turn entire websites into LLM-ready data (firecrawl.dev) ... by nickca on April 13, 2024 / hide / past / favorite / 11 ... It crawls webpages (finds subdirectories), handles JS blocking with fallbacks to headless browsers, and does this all concurrently.
- firecrawl/firecrawl — Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥 - Stars: 191620 - Forks: 10133 - Watchers: 191620 - Open issues: 589 - License: GNU Affero General Public License v3.0 - Homepage: https://firecrawl.dev - Default
External links were grounded in one live web search. Search snippets are leads, not independently scraped page content; rejected links remain available in Review evidence.
Company, security, and trust
Ownership, policies, security signals, and public trust evidence.
| Signal | Finding | Source |
|---|---|---|
| Company and ownership | Founded by builders | source |
| Contact and support | Need more? Contact us | source |
| Legal and privacy | Credits you buy stay on your account until you use them. They expire if you cancel your subscription, so use them before you leave. | source |
| Security and compliance | SSO & advanced security | source |
| Uptime and status page | / Support SLAYour agreement sets the uptime and response targets we commit to. / –Not available / –Not available / –Not available / –Not available / –Not available / Included / | source |
| Domain registered | 2024-04-08 | — |
| Domain expires | 2034-04-08 | — |
Every trust signal above is backed by a collected page or a registration record.
Documentation and product updates
Help resources, product guidance, and visible changes over time.
| Resource or update | Type | What is available | Date or freshness |
|---|---|---|---|
| AI modelDeveloper Platform docs API for AI agents / deep page fetch Alexandria | Documentation | Official AI modelDeveloper Platform documentation. Available to AI agents through one deep page fetch API, MCP or CLI. ([source](https://www.firecrawl.dev/alexandria/platform-AI modelcom)) | Not dated |
| Developer Index: Code & Docs Search API for Coding Agents / deep page fetch | Documentation | Search 70M+ GitHub READMEs, issues, pull requests, and documentation from one endpoint. The highest recall of any coding-specific index, with no API key needed to start. (source) | Not dated |
| AI modelDeveloper Platform docs API for AI agents / deep page fetch Alexandria | Release notes | Public product change history. ([source](https://www.firecrawl.dev/alexandria/platform-AI modelcom)) | Not dated |
Not found in the collected public sources: public roadmap, status page, separate help center or knowledge base.
Technical
Technical and delivery signals
Delivery model, platforms, API, data ownership, reliability claims and release activity.
| Signal | Finding | Source |
|---|---|---|
| Delivery model (cloud, self-hosted, desktop, browser extension) | Hosted version features Fire-engine infrastructure; open-source version available S23. | S23 |
| Platforms and apps | Web-based API with SDKs for Python, Node.js, Go, Rust, Java, and Elixir S23. | S23 |
| API and extensibility (API, SDK, webhooks, MCP, plugins) | REST API, SDKs, CLI, MCP support, and signed webhooks S23 S78. | S23 S78 |
| Data ownership and export | Not published on the collected pages. | — |
| Performance and reliability claims | Claims optimized infrastructure for reliable extraction from complex websites S23. | S23 |
| Release activity | Real-time updates indicated on the site S23. | S23 |
Measured infrastructure
Domain, certificate, and hosting signals, measured directly.
| Signal | Finding |
|---|---|
| Domain registered | 2024-04-08 — Namecheap Inc. |
| Domain expires | 2034-04-08 |
| First archived | 2024-04-13 — web archive |
| TLS certificate | Let's Encrypt, valid, expires 2026-11-26 |
| Security headers | HSTS, CSP, X-Content-Type-Options, X-Frame-Options, Referrer-Policy |
| Server header | Vercel |
| Mail handled by | smtp.google.com |
| Nameservers | dns1.registrar-servers.com, dns2.registrar-servers.com |
Not measurable: rdap: exceeded the overall budget; wayback: exceeded the overall budget; tls: exceeded the overall budget; dns: exceeded the overall budget; headers: exceeded the overall budget. A gap here means the lookup was unavailable, not that the finding is negative.
Technical site audit
A bounded multi-page crawl with page-level issues and URLs.
Scout — Bounded technical crawl
- Pages crawled: 15 of 15 maximum
- Technical health: 94/100
- Critical issues: 0
- Warnings: 17
- Notices: 3
Issues
| Severity | Issue | Value | Affected URL |
|---|---|---|---|
| warning | Missing canonical URL | — | https://www.firecrawl.dev/ |
| warning | Missing canonical URL | — | https://www.firecrawl.dev/ |
| notice | Meta description length should be reviewed | 176 | https://www.firecrawl.dev/pricing |
| warning | Missing canonical URL | — | https://www.firecrawl.dev/blog |
| warning | Missing canonical URL | — | https://www.firecrawl.dev/playground |
| warning | Page should have one primary H1 | 0 | https://www.firecrawl.dev/signin |
| warning | Missing canonical URL | — | https://www.firecrawl.dev/signin |
| notice | Low visible word count | 117 | https://www.firecrawl.dev/signin |
| warning | Title length should be reviewed | 73 | https://www.firecrawl.dev/blog/how-replit-uses-firecrawl-to-power-ai-agents |
| notice | Meta description length should be reviewed | 183 | https://www.firecrawl.dev/interact |
| warning | Duplicate title in audit sample | 5 | https://www.firecrawl.dev/ |
| warning | Duplicate title in audit sample | 5 | https://www.firecrawl.dev/ |
| warning | Duplicate title in audit sample | 5 | https://www.firecrawl.dev/blog |
| warning | Duplicate title in audit sample | 5 | https://www.firecrawl.dev/playground |
| warning | Duplicate title in audit sample | 5 | https://www.firecrawl.dev/signin |
| warning | Duplicate meta description in audit sample | 5 | https://www.firecrawl.dev/ |
| warning | Duplicate meta description in audit sample | 5 | https://www.firecrawl.dev/ |
| warning | Duplicate meta description in audit sample | 5 | https://www.firecrawl.dev/blog |
| warning | Duplicate meta description in audit sample | 5 | https://www.firecrawl.dev/playground |
| warning | Duplicate meta description in audit sample | 5 | https://www.firecrawl.dev/signin |
Crawled pages
| Status | Title | H1s | Words | Response | URL |
|---|---|---|---|---|---|
| 200 | deep page fetch \ | Web Data API for AI Agents | 1 | 3573 | 471 ms |
| 200 | Alexandria - a knowledge library for AI agents \ | deep page fetch | 1 | 1971 | 362 ms |
| 200 | Introducing Alexandria and our $75M Series B | 1 | 1662 | 230 ms | https://www.firecrawl.dev/blog/introducing-alexandria-series-b |
| 200 | deep page fetch \ | Web Data API for AI Agents | 1 | 3573 | 401 ms |
| 200 | Pricing \ | deep page fetch | 1 | 2553 | 307 ms |
| 200 | deep page fetch \ | Web Data API for AI Agents | 1 | 14524 | 1,197 ms |
| 200 | deep page fetch \ | Web Data API for AI Agents | 1 | 251 | 1,182 ms |
| 200 | deep page fetch \ | Web Data API for AI Agents | 0 | 117 | 141 ms |
| 200 | deep page fetch + Lovable - Build Web Data Apps Without Writing Code | 1 | 1076 | 276 ms | https://www.firecrawl.dev/blog/firecrawl-lovable-integration |
| 200 | How Zapier Powers AI Chatbots with Web Knowledge Using deep page fetch | 1 | 1008 | 519 ms | https://www.firecrawl.dev/blog/how-zapier-uses-firecrawl-to-power-chatbots |
| 200 | How Replit Powers Replit Agent with Always-Fresh Web Data Using deep page fetch | 1 | 974 | 439 ms | https://www.firecrawl.dev/blog/how-replit-uses-firecrawl-to-power-ai-agents |
| 200 | How Gamma Supercharges Onboarding with deep page fetch | 1 | 912 | 443 ms | https://www.firecrawl.dev/blog/how-gamma-supercharges-onboarding-with-firecrawl |
| 200 | Web Search API. Live Web Results for AI Agents \ | deep page fetch | 1 | 2228 | 543 ms |
| 200 | Web Scraping API. Any URL to Clean Markdown \ | deep page fetch | 1 | 1498 | 509 ms |
| 200 | Web Interaction API. Give Your Agent a Live Browser \ | deep page fetch | 1 | 1463 | 350 ms |
This is a bounded Scout crawl. Core Web Vitals and Lighthouse scores are not claimed unless a dedicated performance audit is connected.
Search Console and Analytics
First-party search and behavioral data connection state.
Modeled acquisition channels
| Channel | Estimated share |
|---|---|
| direct | 44.4% |
| search | 32.2% |
| search organic | 31.2% |
| search paid | 1.0% |
| social | 5.5% |
| social organic | 5.4% |
| social paid | 0.1% |
| referrals | 5.1% |
| paid referrals | 0.4% |
| 2.9% | |
| gen ai | 9.5% |
| affiliate | 0.0% |
| other | 0.0% |
First-party connections
| Integration | Status | Data available after connection |
|---|---|---|
| Google Search Console | Not connected | Clicks, impressions, CTR, average position, queries, pages, countries, and devices |
| Google Analytics | Not connected | Organic sessions, engagement, landing pages, conversions, geography, and devices |
No first-party Search Console or Analytics numbers are shown until the site owner authorizes the corresponding Google account. Scout traffic model values above are modeled estimates, not private analytics totals.
Limits and method
Limitations and open questions
Known constraints and missing evidence from the collected pages.
The collected pages do not mention specific competitors by name, except a testimonial referencing Apify S69. Evidence gaps include lack of detailed security certifications, uptime statistics, and customer case studies beyond the named examples. Open questions remain about data retention policies for non-enterprise plans and the specifics of the open-source version's feature parity.
Sources, method, and limitations
Evidence inventory, collection method, provider use, and constraints.
This report is based on 15 collected pages from firecrawl.dev, including the homepage, about, pricing, use-case, and tool pages. Evidence was gathered via static and browser rendering rendering, with external proof search for verification. Limitations include potential marketing bias and lack of independent review data. All claims are cited from the provided catalog tokens.
- Documentationhttps://www.firecrawl.dev/Verified
- Documentationhttps://www.firecrawl.dev/aboutVerified
- Pricing Pagehttps://www.firecrawl.dev/pricingVerified
- Pricing Pagehttps://www.firecrawl.dev/alexandria/package-registry-metadata-download-statsVerified
- Official Websitehttps://www.firecrawl.dev/alexandria/platform-claude-comVerified
- Official Websitehttps://www.firecrawl.dev/alexandria/platform-opentargets-orgVerified
- Official Websitehttps://www.firecrawl.dev/tools/product-data-extractorVerified
- Pricing Pagehttps://www.firecrawl.dev/use-cases/product-teamsVerified
- Documentationhttps://www.firecrawl.dev/signinVerified
- Documentationhttps://www.firecrawl.dev/developer-indexVerified
- Documentationhttps://www.firecrawl.dev/alexandria/api-exchange-coinbase-comVerified
- Documentationhttps://www.firecrawl.dev/alexandria/api-weather-govVerified
- Documentationhttps://www.firecrawl.dev/alexandria/apps-apple-comVerified
- Documentationhttps://www.firecrawl.dev/alexandria/apps-bea-govVerified
- Documentationhttps://www.firecrawl.dev/alexandria/apps-fcc-govVerified
- Articlehttps://www.featuredcustomers.com/vendor/firecrawlVerified
- Review Sitehttps://www.producthunt.com/products/extract-by-firecrawl/reviewsVerified
- Articlehttps://news.ycombinator.com/item?id=45374976Verified
- Articlehttps://firecrawl.dev/Verified
- Documentationhttps://news.ycombinator.com/item?id=40055103Verified
- Articlehttps://www.firecrawl.dev/blog/category/customer-storiesVerified
- Articlehttps://news.ycombinator.com/item?id=40026782Verified
- Articlehttps://github.com/firecrawl/firecrawl/Verified
- Review Sitehttps://www.producthunt.com/products/extract-by-firecrawlVerified