2,315 stars · AGPL-3.0-or-later · v0.43.0, dated 15 March 2025 — the year confirmed by ungh.cc, which returns 2025-03-15T15:27:59Z for the same tag. GitHub's release page showed '15 Mar' with no year in the fetch summary, which the yearless rule would have read as 2026 · Track this in Scout
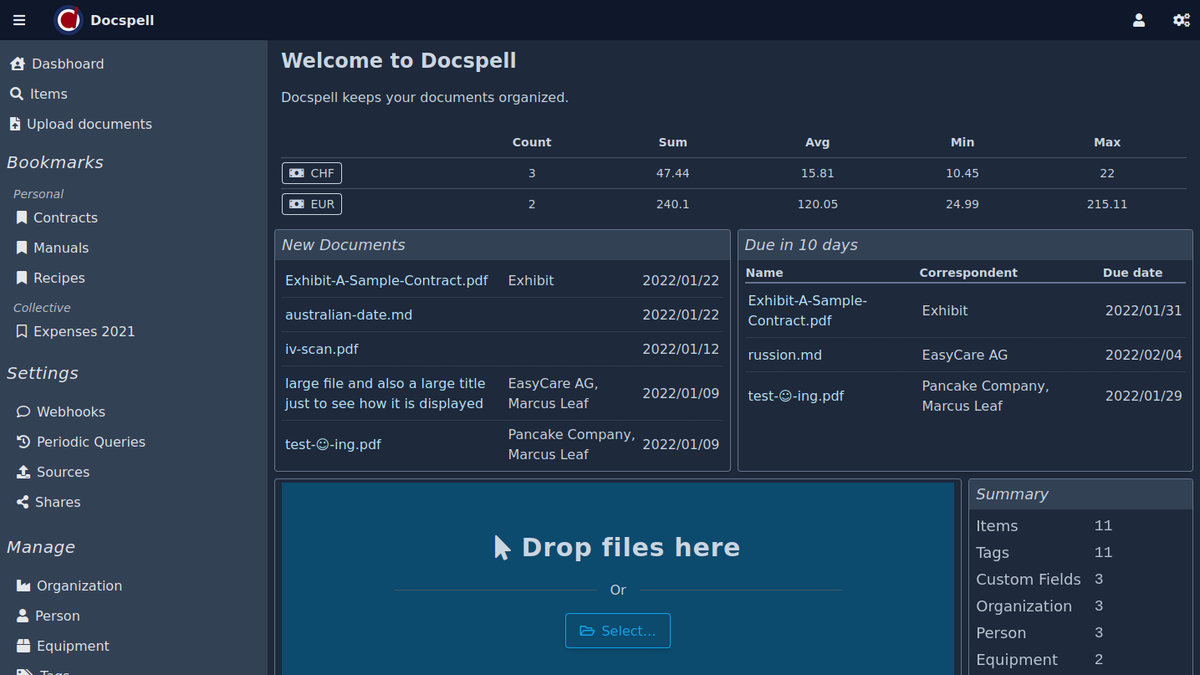
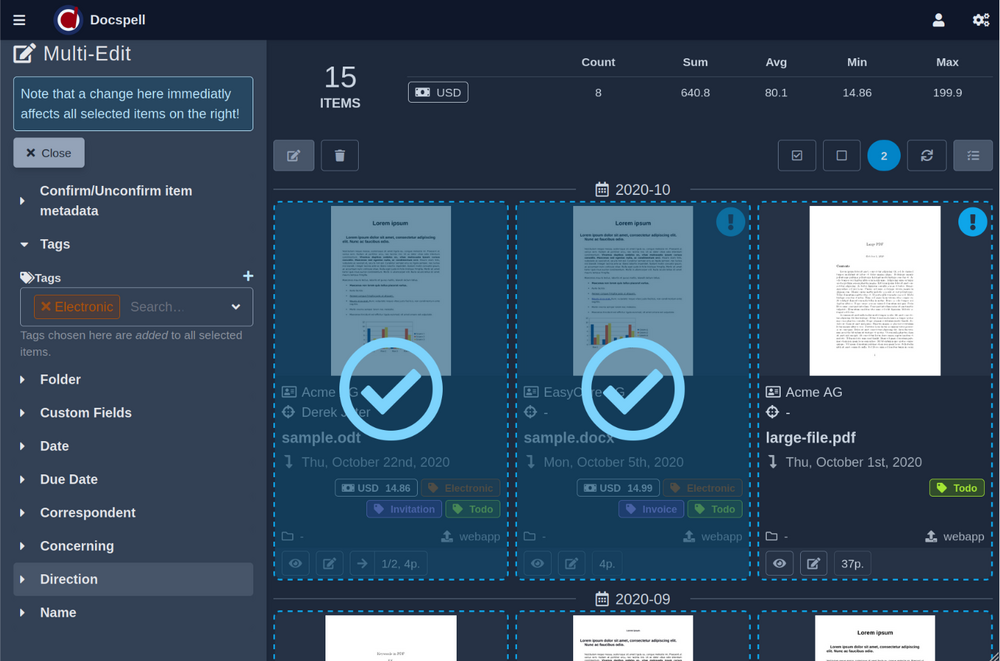
It reads incoming documents, works out who they are from and what they say, and makes the pile searchable.
▶Repo detailsthe review · specs · pros & cons · install
What it is
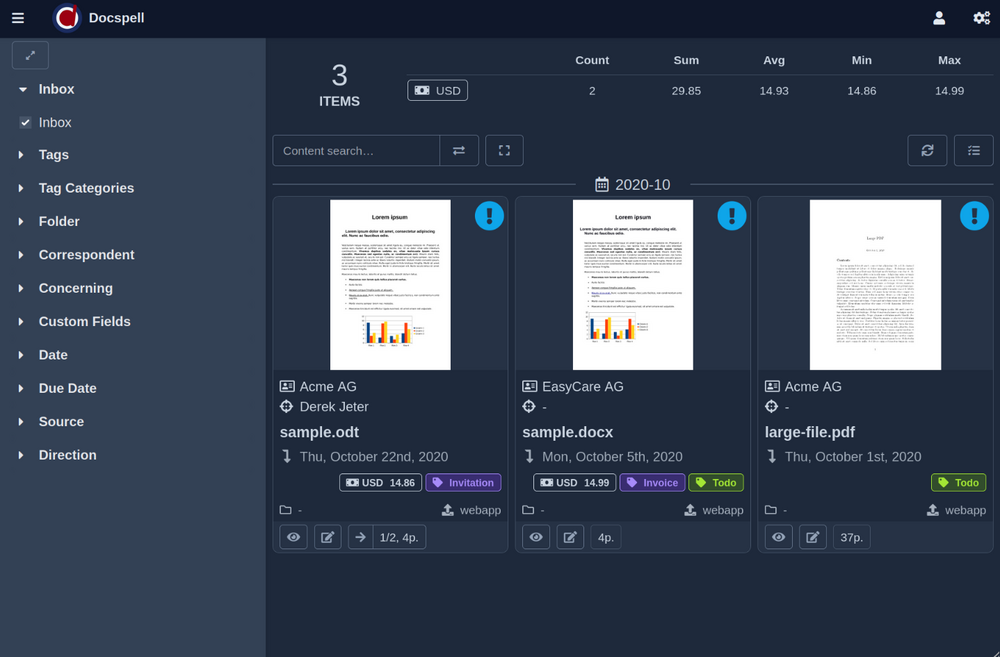
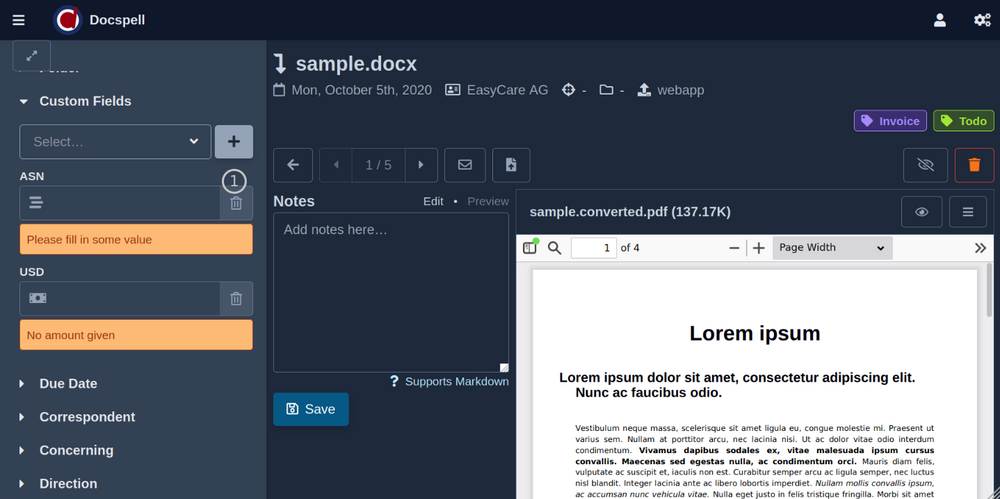
A document server written in Scala that stores files, runs optical character recognition on scans and images, and then tries to classify each document against people and companies you have told it about. It can collect files from a folder it watches or from a mailbox it checks.
What it is good for. Anyone with a drawer of paper and a scanner, and anyone who receives invoices as PDF attachments and loses them in an inbox. The everyday payoff is small and constant: instead of remembering that a document is called scan_0043.pdf, you search for the company name and the year.
- The automatic sorting learns from the corrections you make, so it gets less wrong over time.
- It can watch a folder and a mailbox, so documents arrive without anyone uploading them by hand.
- It was one of ten projects this report could not verify last week. Its code was last changed on 28 August 2026, so it is comfortably alive.
- AGPL-3.0-or-later. Running it is unrestricted. Building a hosted service on top of a modified copy means publishing those modifications.
- Its newest release, v0.43.0, is dated 15 March 2025 — eighteen months ago. The code is current; the release habit is not. There is nothing newer to install than that tag.
- It is a Java-based server with a separate job runner, a database and an OCR stack. That is a real evening of setup, and it wants a couple of gigabytes of memory.
 paperless-ngx/paperless-ngx
It solves the same problem with a much larger community and more documentation, and it is the one most people land on first; docspell's classifier is the more automatic of the two.
Track this in Scout sismics/docs
It stores and searches the same pile, but the filing is done by hand with tags and permissions instead of being guessed. It is #4 in this edition.
Track this in Scout ocrmypdf/OCRmyPDF
It does only the reading-the-scan part, as one command over files that already exist, with no server, no database and nothing to keep running.
Track this in Scout
git clone https://github.com/eikek/docspell.git
cd docspell/docker/docker-compose
docker compose up -d