11.3k stars · MIT | [presidio.dataprivacystack.org](https://presidio.dataprivacystack.org) · 2.2.364 (2026-07-22) · Track this in Rising ↗
A framework for detecting and removing personal data in text, images and tables.
Radar check
What we found when we opened it. Every bar is one fact, with its date.
Last code pushed 25 Oct 2026, 2 days before this check.
Latest release 2.2.365 on 25 Oct 2026.
Public since May 2018, a little over 8 years.
11,502 stars and 1,375 forks.
30 commits and 54 new issues in the last 90 days.
218 contributors. 33 pull requests merged in 90 days.
A security policy says how to report a problem. No published security advisories.
How the bars are scored
- Alive. Days since the last code push: a week or less 100, a month 90, three months 70, six months 50, a year 30, eighteen months 15, older 0.
- Releases. Age of the latest GitHub release, on a similar scale; no bar when the project publishes no releases.
- Maturity. Age of the project: eight years 100, five 90, three 70, two 55, one 40, six months 25, younger 10.
- Adoption. Stars on a log scale: 100,000 stars is 100, 10,000 is 80, 1,000 is 60, 100 is 40.
- Activity. Commits in the last 90 days: 300 or more 100, 100 85, 30 65, 10 45, any 25.
- Community. People who have contributed: 100 or more 100, 30 80, 10 60, 5 40, 2 25, one 10.
- Security. A published security policy 80, none 40; published advisories are listed, not scored.
Checked by Repo Radar on 25 Oct 2026 from the repository on GitHub. Covered in Edition 7.
▶Repo detailsthe review · specs · pros & cons · install
What it does
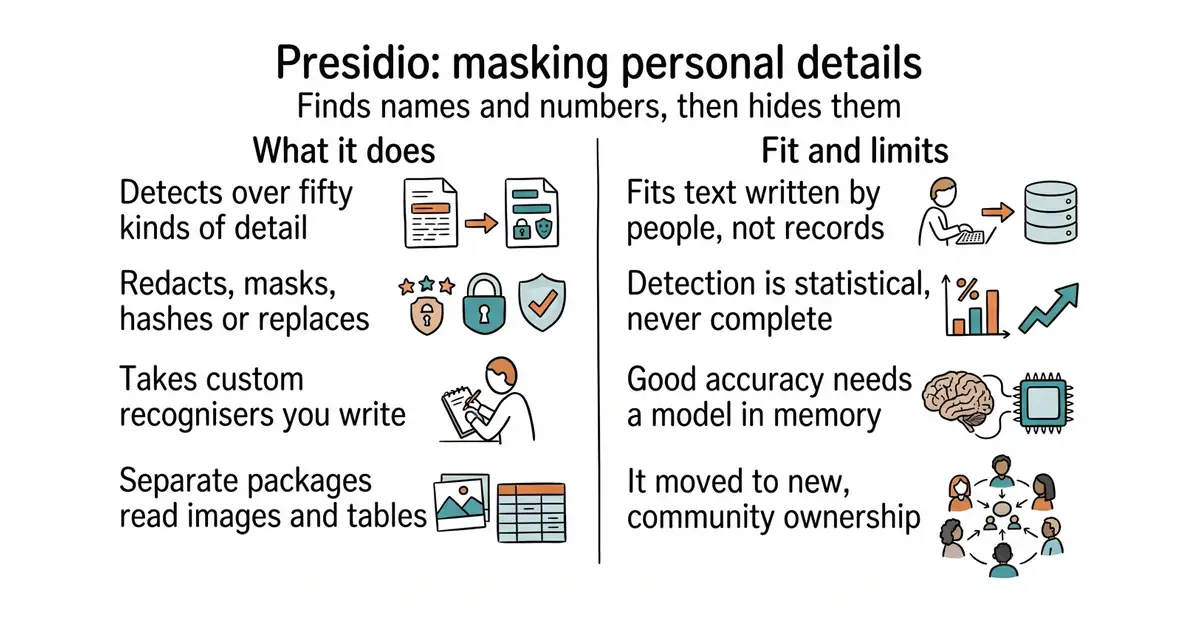
It has two main parts. The analyser finds personal details and returns what it found, where, and how confident it is. The anonymiser then redacts, masks, hashes, encrypts or replaces them. Detection combines regular expressions, checksum validation, context words and named-entity recognition from a language model — spaCy by default, with transformer models and hosted services available instead. More than fifty kinds of detail are recognised out of the box, including country-specific identifiers, and you can add your own recogniser for an internal code or a project name. Separate packages handle images, where text is found by optical character recognition and then painted over, and tabular data. It runs as a Python library or as containers behind an HTTP interface. What it does not do is guarantee completeness: detection is statistical, it misses things, and it flags things that are not personal data. Coverage outside English is noticeably thinner.
Why it matters
Who it suits. Anyone whose program accepts text written by a human and then sends it somewhere else — to a model, to a log, to a search index, to a test environment. It suits teams with a privacy obligation they have to be able to describe rather than merely assert, because this turns a promise into a step somebody can inspect. Skip it if the text is already structured and the sensitive fields are known by name, because then removing a column is both simpler and safer.
Verdict. Worth a day to put in a pipeline, and worth measuring afterwards: the good detection needs a language model held in memory, which is a real cost on a small machine. Start with the light spaCy model and watch the memory. Two things changed since this edition was first published, and the first is the headline. The project is no longer Microsoft's: it has moved to an independent, community-governed organisation called Data Privacy Stack, the repository is now data-privacy-stack/presidio, and the old address redirects. The licence stays MIT and the Python package names are unchanged, but new container images are published under the new organisation and the old registry's images are no longer updated, so any image reference needs changing. The second thing is the governance: the steering committee is widening beyond Microsoft and the detailed rules are still to be published. Test on real text in every language that matters before making any claim that covers them all.
Summary (Key Points)from the README
Key features
- Predefined or custom recognizers: Detects PII using Named Entity Recognition, regular expressions, rule-based logic and checksums, with context awareness in multiple languages.
- External model connections: Supports connecting to external PII detection models.
- Multiple usage options: Runs from Python or PySpark workloads, through Docker, up to Kubernetes.
- Customizable identification and de-identification: Both detection and anonymization can be tailored to a specific business need.
- Image redaction: A dedicated module redacts PII in text within images, covering standard image types and DICOM medical images.
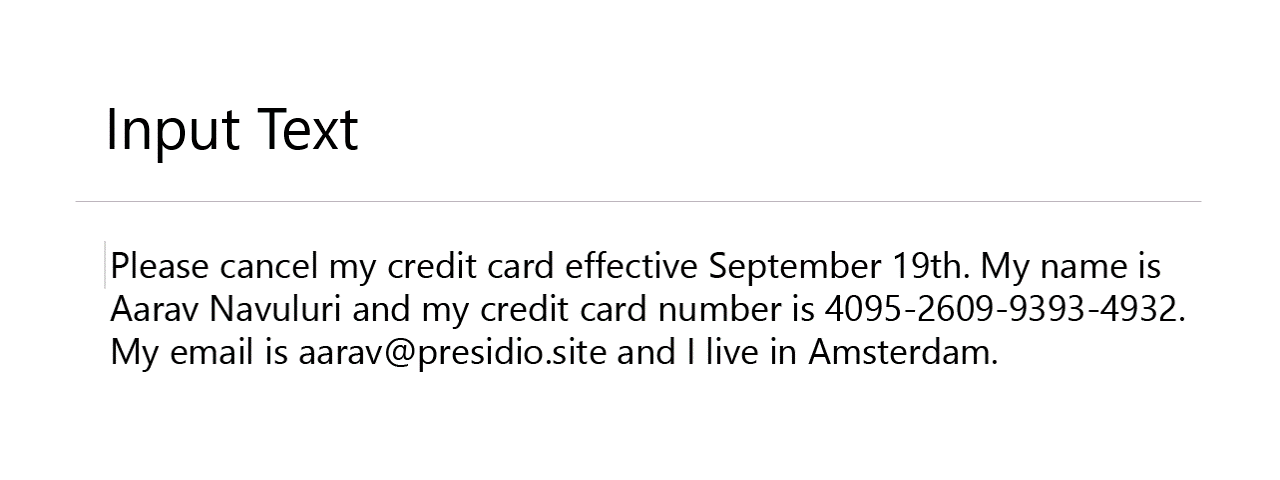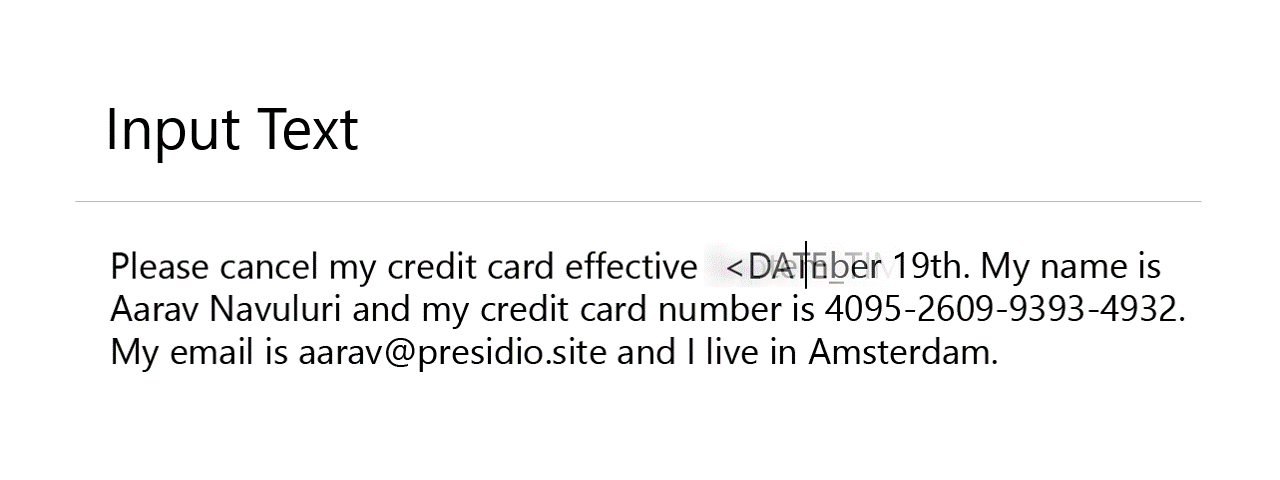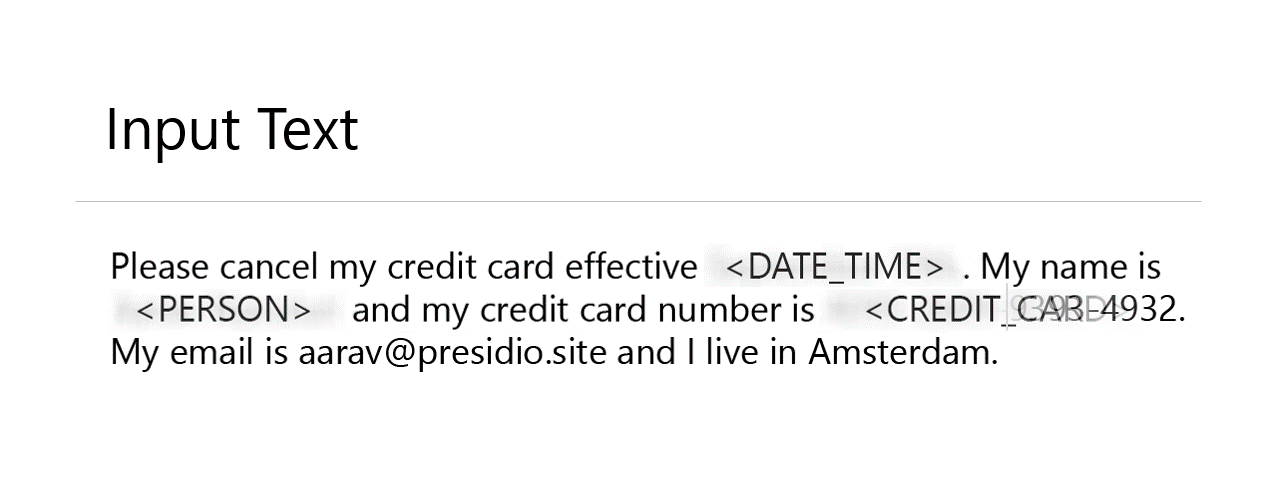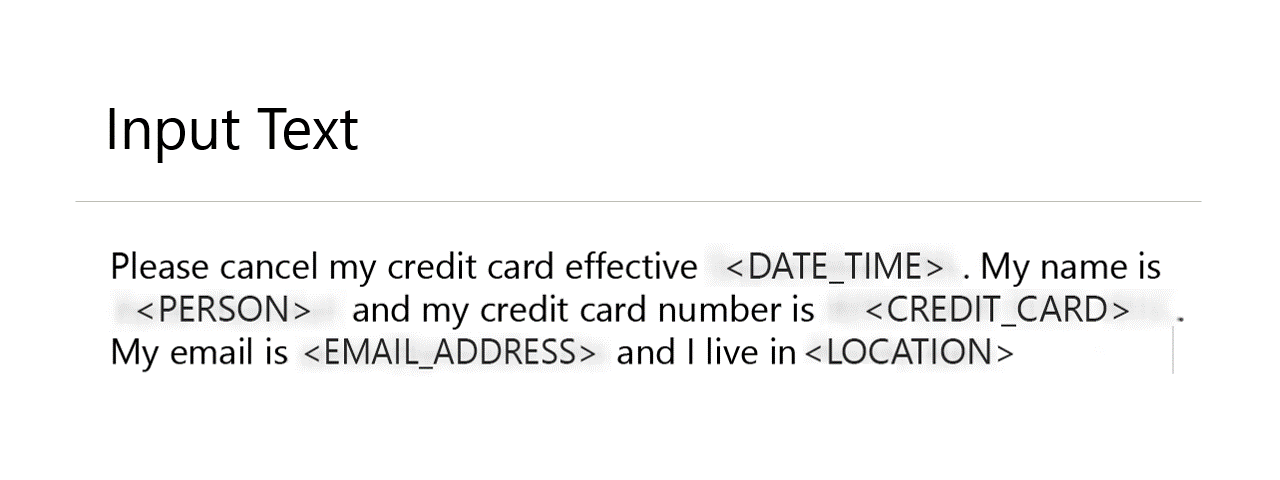
- Text de-identification modules: The Analyzer identifies entities such as credit card numbers, names, locations, social security numbers, bitcoin wallets, US phone numbers and financial data, and the Anonymizer de-identifies them.
- Structured data component: A separate Presidio Structured package is listed alongside the Analyzer, Anonymizer and Image-Redactor.
- Transparency goal: The project aims to make de-identification decisions transparent and accessible to organizations.
Ways to install
| Platform or method | What it needs | Effort |
|---|---|---|
| pip | A Python environment | Low |
| Docker | Docker installed | Low |
| From source | A local clone of the repository and a development setup | Medium |
Important
- Not a complete guarantee: Detection is automated, so Presidio may not find all sensitive information; additional systems and protections should be used.
- Project moved: The README states that the project has moved to a new home and includes a transition update, so check the linked notice before relying on old locations.
- Version migration: Users upgrading from V1 need to follow the README's migration guide to V2.
- Support limits: Usage questions, bugs and suggestions go through GitHub issues, and other matters go by email to presidio@dataprivacystack.org.
Written by an AI model from the project’s README; not part of the review, and it can be wrong.
- MIT licensed, with more than fifty kinds of personal detail recognised before any customisation.
- Extensible: a client code or an internal project name can be masked as easily as an email address.
- Separate packages cover images and tables, not just plain text.
- Detection is statistical and never complete; it misses things and flags things it should not.
- Good accuracy needs a language model in memory, which is a real cost on a small machine.
- Coverage outside English is much thinner, and the project's move to new ownership means image references and documentation addresses are still settling.
python3 -m venv venv
source venv/bin/activate
pip install presidio-analyzer presidio-anonymizer
python -m spacy download en_core_web_lg