Overview
Summary
The useful answer before the supporting detail.
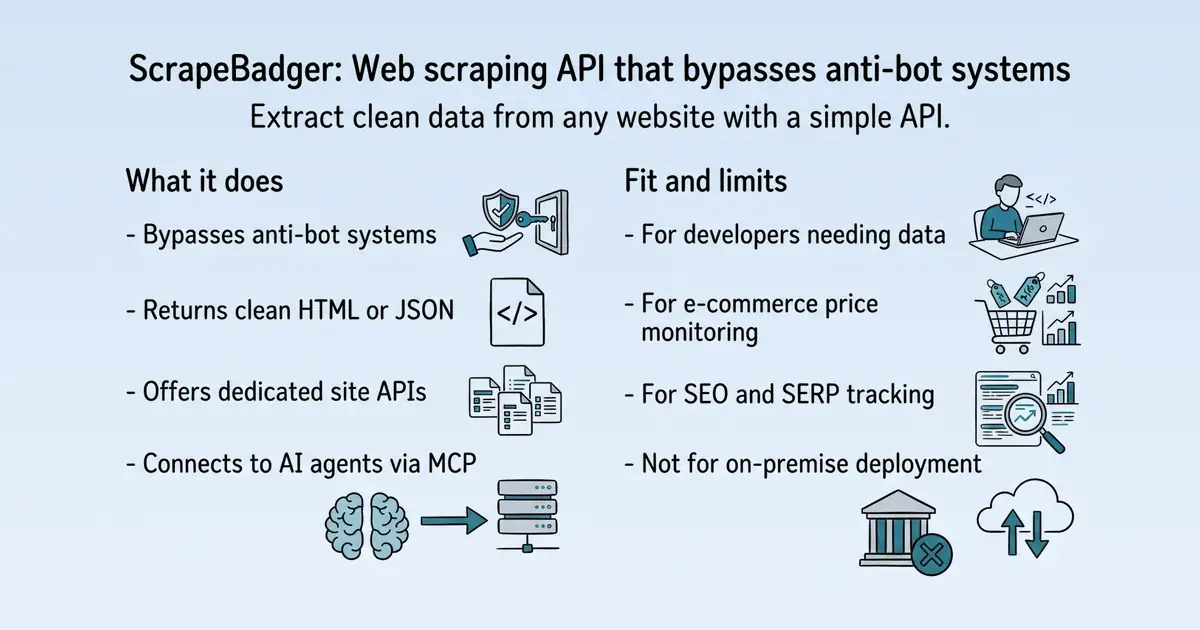
ScrapeBadger is a web scraping API that returns clean HTML, Markdown, or screenshots from any website S1. It is used by developers and businesses to extract web data for applications, research, and AI workflows, bypassing anti-bot systems like Cloudflare and DataDome S1. Its practical value is saving time on scraper maintenance and providing reliable data through a simple API S1.
Product identity and positioning
Name, category, positioning, audience, and first-party claims.
- Identity: ScrapeBadger is a web scraping API service S1.
- Core purpose: It solves the problem of websites blocking automated data extraction S1.
- Intended users: Developers and businesses needing web data for apps, research, or AI S1.
- Product scope: It is a cloud-based API, not a platform, with a general scraping API and dedicated APIs for specific sites S1 S73.
- Positioning: The vendor positions it as a simple, reliable way to scrape any website without maintaining infrastructure S1.
- Claimed distinction: It claims to bypass the toughest anti-bot systems, including Akamai and Kasada S1.
Use cases and audiences
Who the product serves and the jobs it is designed to handle.
| Audience | Practical use case |
|---|---|
| E-commerce businesses | Monitor competitor pricing and track inventory changes S1. |
| Real estate platforms | Extract property listings and pricing history for valuation tools S1. |
| SEO professionals | Track keyword rankings and audit competitors S1. |
| Social media analysts | Monitor mentions and run sentiment analysis on public posts S1. |
| HR and workforce analytics | Aggregate job listings and track hiring trends S1. |
Traffic and search
SEO analysis
Collected Oct 22, 2026scrapebadger.com: an estimated 34,039 total monthly visits and about 416 monthly organic visits across 403 ranking keywords. Scout crawled 15 pages and measured a technical health score of 97/100.
Search summary
The useful answer before the supporting detail.
Scrape any website and get clean HTML, Markdown, or screenshots. Auto-escalation, anti-bot bypass, and no IP blocks. scrapebadger.com: an estimated 34,039 total monthly visits and about 416 monthly organic visits across 403 ranking keywords. Scout crawled 15 pages and measured a technical health score of 97/100.
- Total traffic (modeled): 34,039 monthly visits across all channels.
- Organic search traffic (estimated): 416 monthly visits from search.
- Strongest sampled ranking: google api serp position at position 2.
- Leading page in the collected evidence: <https://scrapebadger.com/blog/google-ai-mode-vs-ai-overviews-vs-AI modelwhat-each-one-is-and-how-to-get-data-from-each>.
- Closest measured organic competitor: serpapi.com, appearing 2 times in the sampled first-page SERPs.
- Technical crawl: 15 pages, health score 97/100.
Website intelligence — Collected evidence
Company identity and positioning
| Page type | Evidence | Source |
|---|---|---|
| integrations | Scrape any website and get clean HTML, Markdown, or screenshots. Auto-escalation, anti-bot bypass, and no IP blocks. Get 1,000 free credits on signup. | https://scrapebadger.com/ |
| features | Google Immersive Product API for Deep Product Details, Seller Offers, and Structured Specs | https://scrapebadger.com/google-scraper-api/immersive-product |
| features | Look up a Google Shopping product by its listing identifier and retrieve deep product details, structured specs, images, and seller offers from Google's immersive product page through one purpose-built API endpoint. | https://scrapebadger.com/google-scraper-api/immersive-product |
| features | Retrieve deep product details, structured specs, images, and seller offers from Google's immersive Shopping product page for a specific product. | https://scrapebadger.com/google-scraper-api/immersive-product |
| features | This endpoint does not accept an arbitrary product ID on its own. Pass the product's gpcid as product\_id together with the exact q that surfaced it, or pass that result's page\_token alone, which already encodes product\_id, q, gl, hl, and domain for you. | https://scrapebadger.com/google-scraper-api/immersive-product |
| features | Retrieve the seller list for a product, including seller name, price, shipping, and link. Set include\_offers=true to expand coverage from the top panel merchants to roughly fifty additional sellers, useful for price-comparison tools or tracking where a product is listed. | https://scrapebadger.com/google-scraper-api/immersive-product |
| features | Pull title, description, brand, price range, specs, and images for a product and use them to enrich an internal catalog, marketplace listing, or comparison page with structured data instead of manual entry. | https://scrapebadger.com/google-scraper-api/immersive-product |
| features | Track rating and reviews\_count for competitor or in-house products across repeated requests to monitor reputation trends, spot rating changes, and support competitive research. | https://scrapebadger.com/google-scraper-api/immersive-product |
| features | Set include\_variants=true to retrieve a product's available size or colour variants alongside its core details, useful for inventory research, assortment comparisons, or building richer product pages. | https://scrapebadger.com/google-scraper-api/immersive-product |
| features | Sign Up For Free | https://scrapebadger.com/google-scraper-api/immersive-product |
| features | Search Google Shopping for products and retrieve each result's gpcid, page\_token, price, and seller preview. Use it to get the product\_id and q, or the bundled page\_token, that this endpoint needs to fetch full product detail. | https://scrapebadger.com/google-scraper-api/immersive-product |
| features | Search Google results for brand pages, retailer listings, and other public information around a product. Use it alongside product detail when a workflow needs broader research beyond the immersive panel. | https://scrapebadger.com/google-scraper-api/immersive-product |
Domain performance
Modeled total traffic, six-month trend, engagement, countries, and domain identity.
Total website traffic
| Month | Modeled visits |
|---|---|
| 2026-04 | 2,131 |
| 2026-05 | 11,254 |
| 2026-06 | 15,992 |
| 2026-07 | 34,397 |
| 2026-08 | 37,372 |
| 2026-09 | 34,039 |
Top visitor countries
| Country | Name | Traffic share |
|---|---|---|
| GB | United Kingdom | 25.8% |
| US | United States | 16.5% |
| IN | India | 9.1% |
| BR | Brazil | 5.9% |
| DE | Germany | 4.2% |
Domain identity
| Signal | Value |
|---|---|
| Registered | May 16, 2025 |
| Last changed | Jul 8, 2026 |
| Expires | May 16, 2029 |
| WHOIS server | whois.verisign-grs.com |
| DNSSEC | Not signed |
| Nameservers | DREW.NS.CLOUDFLARE.COM, LANA.NS.CLOUDFLARE.COM |
Website capture
Organic keywords
Top keywords and an independent Google result page.
Top organic keywords
| Keyword | Volume | CPC | Estimated value |
|---|---|---|---|
| scrapebadger | 860 | $1.34 | $720 |
| @gemini | 89,130 | $0.30 | $190 |
| see who liked a tweet | 200 | $0.00 | $190 |
| best open sourcfe depop scraper github | 130 | $0.00 | $130 |
| scrape reddit with claude | 190 | $0.00 | $120 |
Independent Google result page
Query: google api serp position
| Position | Title | URL | Description |
|---|---|---|---|
| 1 | SERP Position — Rank Checker & SEO Tools | https://chromewebstore.google.com/detail/serp-position-%E2%80%94-rank-chec/nfpijoidakdojcghnjplooeifigglogl | Displays a number next to each Google search result to indicate its position in the SERP. SERP Position — Rank Checker & SEO Tools SEO data inside Google ... |
| 2 | Google Search API for real-time SERP scraping | https://www.searchapi.io/ | The Google Search API is designed to help you monitor keyword rankings and their positions on the search results page. You can track keywords for specific ... |
| 3 | Google Search Engine Results API | https://serpapi.com/search-api | Scrape Google search results in JSON format automatically using custom parameters. Search for keywords by location, date and more ... |
| 4 | SERP Position API: A Simple Guide to Accurate Rank ... | https://www.serphouse.com/blog/beginners-guide-serp-position-api/ | Just starting with SEO? This beginner's guide shows how a SERP Position API helps you track keyword rankings and make smarter decisions. |
| 5 | Google Rank Checker API - Live SERP Positions | https://hasdata.com/apis/google-rank-checker-api | Track keyword positions on Google with one API call: organic results with rank, title, and link as clean JSON. Any location, proxies handled. |
| 6 | Serper - The World's Fastest and Cheapest Google Search API | https://serper.dev/ | Industry-leading SERP API, delivering lightning-fast Google search results in 1-2 seconds, at an unbeatable price starting at $0.30 per 1000 queries. |
| 7 | API For Google Rankings: Track Search Positions Fast | https://www.trysight.ai/blog/api-for-google-rankings | A well-structured SERP API response typically includes the organic position of each result, the URL and domain ranking there, the page title ... |
| 8 | SERP Scraper API for Collecting Google Search Results | https://www.scraperapi.com/solutions/serp-data-collection/ | Use our Google SERP scraper API to track keyword positions in near real-time to identify ranking shifts and measure your SEO campaign performance with ... |
| 9 | Free Google SERP Checker by Location - GrowthMarketing.ai | https://growthmarketing.ai/google-serp-checker-free | Check live Google rankings by keyword, country, language, device, and search depth. Add your domain to highlight its position. |
| 10 | Google SERP API by DataForSEO – Real-time Search Data | https://dataforseo.com/apis/serp-api/google-serp-api | Forget about scraping and proxies. Our real-time API will help you collect structured data from Google search with all rich results in HTML or JSON. |
Important pages
Pages earning the most estimated search traffic in the sample.
Website intelligence — Collected evidence
Prioritized website intelligence pages
| Type | Page | Words | Change | URL |
|---|---|---|---|---|
| integrations | ScrapeBadger \ | static | 2,361 | new |
| pricing | ScrapeBadger Pricing – Plans from $49/mo, PAYG from $10 | 4,337 | new | https://scrapebadger.com/pricing |
| pricing | Amazon Price Scraper API \ | playwright | 2,166 | new |
| pricing | Walmart Price Scraper API \ | playwright | 2,102 | new |
| features | Google Immersive Product API \ | playwright | 2,100 | new |
| integrations | App Store Scraper API \ | ScrapeBadger | playwright | 1,928 |
| integrations | Ecommerce Scraper APIs for Products, Prices, Reviews & Sellers \ | playwright | 1,937 | new |
| integrations | Google Scraper APIs Built for Speed, Simplicity, and Scale \ | playwright | 2,146 | new |
| integrations | Integrations - ScrapeBadger | 154 | new | https://scrapebadger.com/integrations |
| integrations | Twitter Scraping APIs \ | ScrapeBadger | static | 1,713 |
| integrations | Twitter Streams – Real-Time Tweet Monitoring API \ | static | 1,023 | new |
| integrations | Does Google Trends Have an API? What to Use in 2026 \ | ScrapeBadger | static | 3,315 |
| integrations | Google Finance API: What Happened + 2026 Alternatives \ | ScrapeBadger | static | 2,696 |
| integrations | AliExpress Scraper API \ | static | 1,217 | new |
Features
Pricing and plans
| Page type | Evidence | Source |
|---|---|---|
| pricing | Pricing update: new credit costs in effect since October 15Read more→ | https://scrapebadger.com/pricing |
| pricing | Simple pricing for serious scrapers | https://scrapebadger.com/pricing |
| pricing | Start free, 1,000 creditsView docs | https://scrapebadger.com/pricing |
| pricing | MonthlyAnnualGet 2 FREE months! | https://scrapebadger.com/pricing |
| pricing | from $10 · credits never expire | https://scrapebadger.com/pricing |
| pricing | \ | $0.082 \ |
| pricing | Custom credit packages, negotiated pricing, SLA guarantee, and a dedicated account manager. | https://scrapebadger.com/pricing |
| pricing | 1,000 free credits on signup, no card requiredFailed requests are never chargedPAYG credits never expire | https://scrapebadger.com/pricing |
| pricing | What's included on every plan | https://scrapebadger.com/pricing |
| pricing | ScrapeBadger doesn't lock features behind higher tiers. Every plan gets the full product — the only difference is credit volume and rate limits. | https://scrapebadger.com/pricing |
| pricing | Automatic Cloudflare, DataDome, Akamai Bot Manager, Imperva Incapsula, PerimeterX (HUMAN), and Kasada bypass, on every plan, with no extra per-request charge. | https://scrapebadger.com/pricing |
| pricing | A growing library of Google data APIs: SERP, Maps, News, Shopping, Jobs, Finance, Trends, Scholar, and more. New endpoints launch on every plan immediately. | https://scrapebadger.com/pricing |
| pricing | Credit value by plan | https://scrapebadger.com/pricing |
| pricing | Rate$0.150/1K | https://scrapebadger.com/pricing |
| pricing | $10 pack~67K requests | https://scrapebadger.com/pricing |
| pricing | Starter, $49/mo | https://scrapebadger.com/pricing |
| pricing | Rate$0.082/1K | https://scrapebadger.com/pricing |
| pricing | Growth, $129/mo | https://scrapebadger.com/pricing |
| pricing | Rate$0.072/1K | https://scrapebadger.com/pricing |
| pricing | Max, $3600/mo | https://scrapebadger.com/pricing |
Integrations and supported platforms
| Page type | Evidence | Source |
|---|---|---|
| integrations | Pricing update: new credit costs in effect since October 15Read more→ | https://scrapebadger.com/ |
| integrations | Web Scraping API for | https://scrapebadger.com/ |
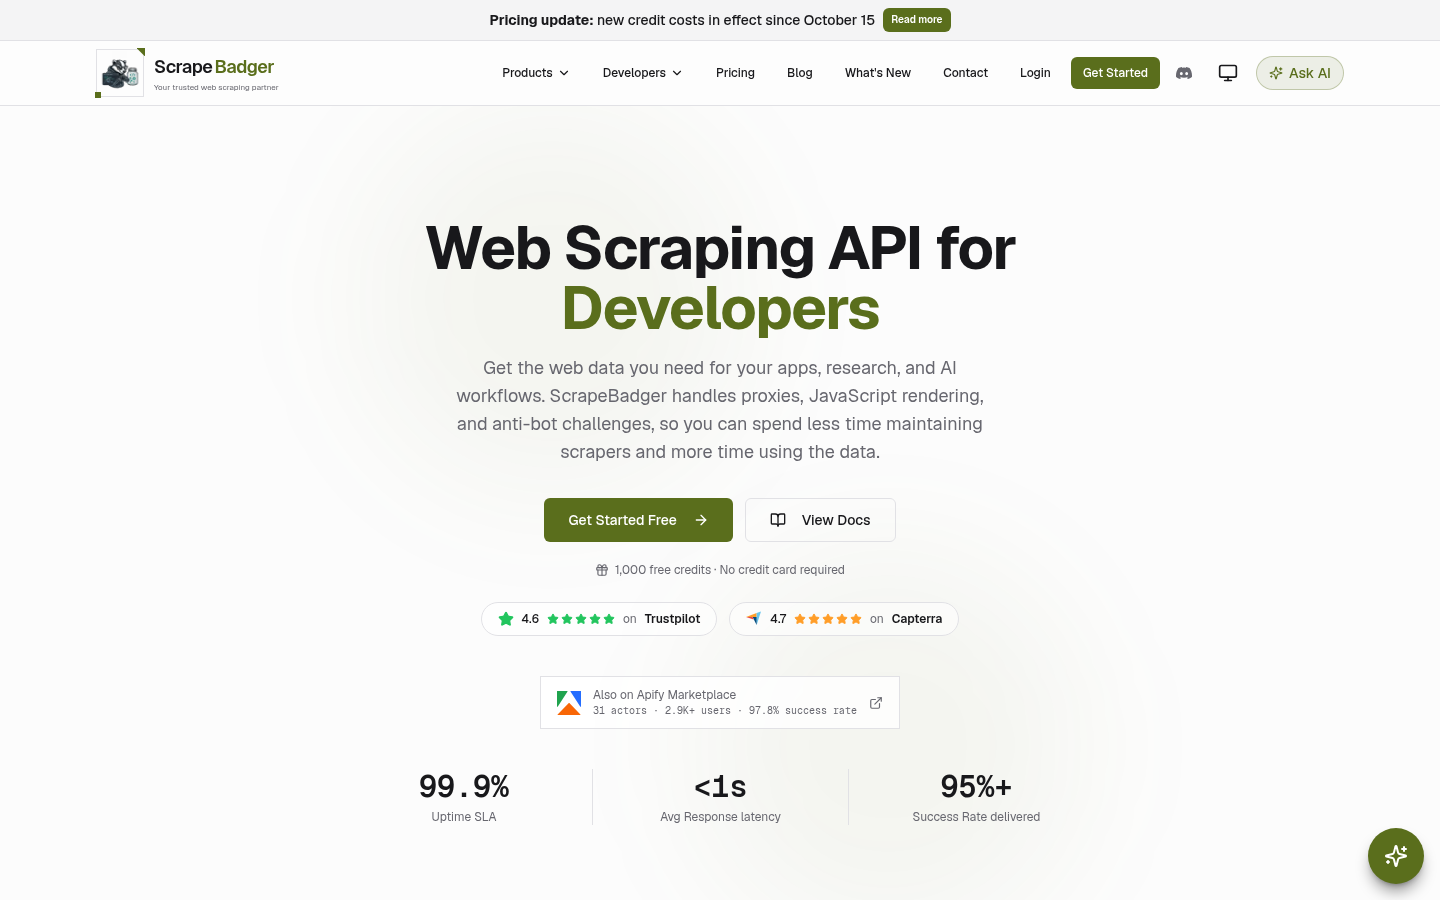
| integrations | Get the web data you need for your apps, research, and AI workflows. ScrapeBadger handles proxies, JavaScript rendering, and anti-bot challenges, so you can spend less time maintaining scrapers and more time using the data. | https://scrapebadger.com/ |
| integrations | Get Started FreeView Docs | https://scrapebadger.com/ |
| integrations | 1,000 free credits · No credit card required | https://scrapebadger.com/ |
| integrations | 4.6onTrustpilot4.7onCapterra | https://scrapebadger.com/ |
| integrations | Also on Apify Marketplace31 actors · 2.9K+ users · 97.8% success rate | https://scrapebadger.com/ |
| integrations | ](https://apify.com/scrape.badger) | https://scrapebadger.com/ |
| integrations | Avg Response latency | https://scrapebadger.com/ |
| integrations | Success Rate delivered | https://scrapebadger.com/ |
| integrations | Trusted for daily data acquisition by | https://scrapebadger.com/ |
| integrations | See the data in action | https://scrapebadger.com/ |
| integrations | Pick a scraper. This is exactly the JSON it returns. | https://scrapebadger.com/ |
| integrations | GGoogle SERPTTwitter / XAAmazonRRedditYYouTubeTTikTokVVintedRRealtorIIdealista | https://scrapebadger.com/ |
| integrations | Target URL \* | https://scrapebadger.com/ |
| integrations | Run API for Free | https://scrapebadger.com/ |
| integrations | google.com/search?q=wireless+headphones | https://scrapebadger.com/ |
| integrations | GET /v1/google/search | https://scrapebadger.com/ |
| integrations | // real response (first 5 results) | https://scrapebadger.com/ |
| integrations | `{ "search_information": { "query_displayed": "wireless headphones", "total_results": 335000000, "time_taken": 0.51, "organic_results_state": "Results for exact spelling", "url": "https://www.google.com/search?q=wireless+headphones&gl=us&hl=en&num=10"; }, "ai_overview": { "text_blocks": [ { "type": "paragraph", "snippet": "Wireless headphones use Bluetooth technology—short-range radio waves—to receive audio signals from devices like smartphones or computers, eliminating the need for cables. They work by pairing, converting digital audio into radio signals, and using internal components (DACs and amplifiers) to turn those signals into sound.", "snippet_links": [], "list_items": [], "video": null, "video_links": [] }, { "type": "paragraph", "snippet": "How Wireless Headphones Work: Core Components", "snippet_links": [], "list_items": [], "video": null, "video_links": [] }, { "type": "paragraph", "snippet": "Bluetooth Technology : The headphones and audio device pair and create a \"Piconet\" (a network), allowing them to exchange data. This connects them without an internet network or router. Signal Conversion: The headset's Bluetooth receiver picks up digital audio signals, which are converted into analog signals by integrated DACs (Digital-to-Analog Converters). Amplification: An internal amplifier increases the signal to a voltage level that can drive the headphones' speakers.", "snippet_links": [], "list_items": [], "video": null, "video_links": [] }, { "type": "paragraph", "snippet": "True Wireless vs. Regular Wireless", "snippet_links": [], "list_items": [], "video": null, "video_links": [] }, { "type": "list", "snippet": null, "snippet_links": [], "list_items": | https://scrapebadger.com/ |
Product and company updates
No supporting public-page evidence was collected for this category.
Rank tracking
Persistent keyword baselines and position movement.
This analysis created the first position baseline at 2026-10-22T20:47:38.534Z. Movement appears after the next fresh analysis using the same location and language.
| Keyword | Current | Previous | Movement | Volume | Ranking URL |
|---|---|---|---|---|---|
| google api serp position | 2 | Baseline | Baseline | 210 | https://scrapebadger.com/google-serp-api |
| google ai mode vs AI model | 4 | Baseline | Baseline | 480 | <https://scrapebadger.com/blog/google-ai-mode-vs-ai-overviews-vs-AI modelwhat-each-one-is-and-how-to-get-data-from-each> |
| ai mode vs AI model | 3 | Baseline | Baseline | 260 | <https://scrapebadger.com/blog/google-ai-mode-vs-ai-overviews-vs-AI modelwhat-each-one-is-and-how-to-get-data-from-each> |
| google ai vs AI model | 5 | Baseline | Baseline | 390 | <https://scrapebadger.com/blog/google-ai-mode-vs-ai-overviews-vs-AI modelwhat-each-one-is-and-how-to-get-data-from-each> |
| scrape ebay data | 1 | Baseline | Baseline | 30 | https://scrapebadger.com/blog/best-ebay-scraper-apis-in-2026-compared-and-ranked |
| realtime tweets | 2 | Baseline | Baseline | 30 | https://scrapebadger.com/twitter-streaming-api |
| scrape google shopping results | 2 | Baseline | Baseline | 30 | https://scrapebadger.com/blog/how-to-scrape-google-search-results-without-getting-blocked-2026-complete-guide |
| what google searches are monitored | 2 | Baseline | Baseline | 30 | https://scrapebadger.com/blog/how-to-scrape-google-search-results-without-getting-blocked-2026-complete-guide |
| zestimate api | 3 | Baseline | Baseline | 50 | https://scrapebadger.com/zillow-scraper |
| difference between google ai mode and AI model | 4 | Baseline | Baseline | 70 | <https://scrapebadger.com/blog/google-ai-mode-vs-ai-overviews-vs-AI modelwhat-each-one-is-and-how-to-get-data-from-each> |
| zillow zestimate api | 3 | Baseline | Baseline | 40 | https://scrapebadger.com/zillow-scraper |
| google search ai mode vs AI model | 4 | Baseline | Baseline | 50 | <https://scrapebadger.com/blog/google-ai-mode-vs-ai-overviews-vs-AI modelwhat-each-one-is-and-how-to-get-data-from-each> |
| twitter scrape api | 4 | Baseline | Baseline | 50 | https://scrapebadger.com/twitter-scraper-api |
| twitter scraping api | 4 | Baseline | Baseline | 50 | https://scrapebadger.com/twitter-scraper-api |
| apartments.com scraper | 4 | Baseline | Baseline | 40 | https://docs.scrapebadger.com/apartments/overview |
| google finance is not working | 4 | Baseline | Baseline | 40 | https://scrapebadger.com/blog/google-finance-api-what-happened-to-it-and-what-to-use-in-2026 |
| google autocomplete predictions | 5 | Baseline | Baseline | 50 | https://scrapebadger.com/google-scraper-api/suggestions |
| scrape data from twitter | 4 | Baseline | Baseline | 30 | https://scrapebadger.com/blog/how-to-scrape-twitter-user-profiles-and-follower-data-with-scrapebadger |
| google AI modelvs google ai mode | 5 | Baseline | Baseline | 30 | <https://scrapebadger.com/blog/google-ai-mode-vs-ai-overviews-vs-AI modelwhat-each-one-is-and-how-to-get-data-from-each> |
| what is google ai mode vs AI model | 4 | Baseline | Baseline | 20 | <https://scrapebadger.com/blog/google-ai-mode-vs-ai-overviews-vs-AI modelwhat-each-one-is-and-how-to-get-data-from-each> |
Features
Features and capabilities
Core functions and evidence-backed product capabilities.
| Capability | What it does |
|---|---|
| General web scraping | Send a URL and receive clean HTML, Markdown, or screenshots S1. |
| Anti-bot bypass | Automatically handles Cloudflare, DataDome, Akamai, and other protections on all plans S73. |
| JavaScript rendering | Renders pages with a stealth browser to avoid detection S73. |
| Residential proxies | Uses residential proxies in 150+ countries for requests S73. |
| MCP server | Connect to AI agents like AI modelor Cursor to scrape via natural language S1. |
| Dedicated APIs | Provides specialized endpoints for platforms like Amazon, Google, and social media S73. |
| Structured output | Returns data as structured JSON for easy integration S122. |
Integrations and ecosystem
Connected products, exports, APIs, and workflow compatibility.
| Integration or interface | Type | What it enables |
|---|---|---|
| MCP server | AI interface | Connect to AI model, Cursor, or ChatGPT to scrape via natural language S73. |
| Apify Marketplace | Integration | Deploy ScrapeBadger actors on Apify with 31 actors and 2.9K+ users S1. |
| Google Scraper APIs | API | Access SERP, Maps, News, and other Google data endpoints S73. |
| Dedicated site APIs | API | Scrape data from Amazon, Walmart, Twitter, and other platforms S73. |
| Web Scraping API | API | Send a URL and receive clean structured content S1. |
Pricing
Pricing and plans
Published plans, free access, trials, credits, and pricing limitations.
| Plan or offer | Verified price and billing | Included | Limits |
|---|---|---|---|
| Free | 1,000 free credits on signup, no credit card required S73 | Access to all features S73 | 60 requests per minute S73 |
| Pay As You Go | From $10 prepaid, credits never expire S73 | $0.15 per 1,000 credits S73 | 60 requests per minute S73 |
| Starter | $49 per month, billed monthly; annual gives 2 months free S73 | 600,000 credits S73 | 300 requests per minute S73 |
| Growth | $129 per month, billed monthly; annual gives 2 months free S73 | 1,800,000 credits S73 | 300 requests per minute, account manager S73 |
| Pro | $299 per month, billed monthly; annual gives 2 months free S73 | 5,000,000 credits S73 | 1,000 requests per minute S73 |
| Scale | $699 per month, billed monthly; annual gives 2 months free S73 | 13,000,000 credits S73 | 1,000 requests per minute S73 |
| Enterprise | Contact sales | Custom credit packages S73 | SLA, dedicated account manager S73 |
Competition
Competitive landscape
Domains competing for the same organic search demand.
Sampled competitors
| Competitor | First-page appearances | Sampled queries | Average position | Queries observed |
|---|---|---|---|---|
| serpapi.com | 2 | 1 | 4 | google api serp position |
| scrape.do | 1 | 1 | 1 | google api serp position |
| quora.com | 1 | 1 | 1 | google ai mode vs AI model |
| searchenginejournal.com | 1 | 1 | 2 | google ai mode vs AI model |
| brightdata.com | 1 | 1 | 3 | google api serp position |
| reddit.com | 1 | 1 | 3 | google ai mode vs AI model |
| scrapingdog.com | 1 | 1 | 4 | google api serp position |
| singularity.digital | 1 | 1 | 4 | google ai mode vs AI model |
| apiserpent.com | 1 | 1 | 5 | google api serp position |
| cloud.google.com | 1 | 1 | 5 | google ai mode vs AI model |
Website intelligence — Collected evidence
Customers, testimonials, and first-party review claims
No supporting public-page evidence was collected for this category.
Independent review sources discovered
No links to supported independent review platforms were discovered on the collected pages.
AI visibility
Measured ChatGPT and Google AI mentions with cited sources.
AI-assistant referral traffic
- Estimated current generative-AI referral share: 1.1%
| Month | Traffic share | Source |
|---|---|---|
| — | — | All AI assistants |
Website intelligence — Collected evidence
Site-stated AI capabilities
| Page type | Evidence | Source |
|---|---|---|
| integrations | Get the web data you need for your apps, research, and AI workflows. ScrapeBadger handles proxies, JavaScript rendering, and anti-bot challenges, so you can spend less time maintaining scrapers and more time using the data. | https://scrapebadger.com/ |
These are first-party product claims, not independent measurements of AI-search visibility.
Marketing opportunities
Actions calculated directly from the collected evidence.
| Opportunity | Recommended action | Evidence |
|---|---|---|
| Striking-distance keyword | Move “google ai mode vs AI model” from position 4 toward the top three. | Volume 480 · <https://scrapebadger.com/blog/google-ai-mode-vs-ai-overviews-vs-AI modelwhat-each-one-is-and-how-to-get-data-from-each> |
| Important page | Strengthen the page already earning search visibility before creating an unrelated page. | https://scrapebadger.com/twitter-scraper-api · 2 sampled keywords · best position 4 |
| Competitor gap | Review the sampled queries where serpapi.com appears. | 2 first-page appearances across google api serp position |
Website intelligence — Collected evidence
Website evidence gaps
- customers: no usable public page was collected; verify whether the site publishes this evidence.
- reviews: no usable public page was collected; verify whether the site publishes this evidence.
- changes: no usable public page was collected; verify whether the site publishes this evidence.
- identity: no usable public page was collected; verify whether the site publishes this evidence.
- technical: no usable public page was collected; verify whether the site publishes this evidence.
Trust and proof
Customers, proof, and reviews
Published proof, customer signals, and review evidence.
Independent reviews
No citation-grounded independent review links were found.
Customer proof
No named customers, testimonials, or customer case studies were found.
Independent mentions
- ScrapeBadger / Scrape Any Website - Web Scraping API — ScrapeBadger / Scrape Any Website - Web Scraping API ... # Web Scraping API for Developers ... Get the web data you need for your apps, research, and AI workflows. ScrapeBadger handles proxies, JavaScript rendering, and anti-bot challenges, so you can spend less time maintaining scrapers and more time using the data. ... ## Spend less time maintaining scrapers. Build more. ... ### Get data in the format you need ... Choose HTML, Markdown, plain text, or a screenshot. html markdown text screensho
- Introduction - ScrapeBadger — Scrape any website and access Twitter/X data through a simple REST API. Web scraping with anti-bot bypass, AI extraction, and 50+ Twitter endpoints. ... ScrapeBadger is a unified web scraping and data API. Scrape any website with automatic anti-bot bypass, JavaScript rendering, and AI-powered data extraction — or access Twitter/X data through 50+ structured endpoints. No infrastructure to manage. Base URL: `https://scrapebadger.com/v1`
- API Reference - ScrapeBadger — for web scraping and Twitter data. 50+ endpoints for scraping any website and accessing Twitter data. Base URL ``` https://scrapebadger.com/v1 ``` All API endpoints are prefixed with this base URL. Authentication is required for all requests.
- SDKs - ScrapeBadger / Official Client Libraries for 12 Languages — Official client libraries for every major language, generated straight from the ScrapeBadger OpenAPI spec — so every SDK covers the full API and never drifts out of sync. Python and Node.js additionally ship as handwritten, fully backward-compatible typed clients.
- ScrapeBadger Pricing – Plans from $49/mo, PAYG from $10 — ScrapeBadger Pricing – Plans from $49/mo, PAYG from $10 # Simple pricing for serious scrapers Buy credits, use them across every API. Anti-bot bypass, residential proxies, and JS rendering included on all plans, no feature tiers, no surprises. What
- All Scraper APIs - ScrapeBadger / Search, E-commerce, Social, Real Estate & LLM — # Scraper APIs Every dedicated ScrapeBadger API — search, e-commerce, social, real estate, app stores and LLM answers. One API key, one credit balance, no per-site contracts. ... ## General Web Scraper API Scrape any website with rotating proxies,
- Web Scraping API Docs – Quickstart, Endpoints, Examples / ScrapeBadger — ## Getting Started Install the ScrapeBadger SDK for your preferred language: python node curl ``` pip install scrapebadger ``` ## Authentication All API requests require an API key. Send it in the `X-API-Key` header: python
- Web Scraping Overview - ScrapeBadger — with automatic anti-bot bypass, JavaScript rendering, and ... Web Scraping API Scrape any public webpage and get back clean HTML, Markdown, or plain text. The API handles anti-bot protection, JavaScript rendering, and proxy rotation automatically.
External links were grounded in one live web search. Search snippets are leads, not independently scraped page content; rejected links remain available in Review evidence.
Company, security, and trust
Ownership, policies, security signals, and public trust evidence.
| Signal | Finding | Source |
|---|---|---|
| Company and ownership | Yes: upgrade, downgrade, or cancel at any time from your billing dashboard. Upgrades take effect immediately and restart your billing cycle that day — you pay the full new plan price, and get the full new credit allowanc | source |
| Contact and support | Yes. If 80M credits/month on Max isn't enough, contact support@scrapebadger.com for a custom contract with dedicated proxy pools, higher rate tiers, and SLA. | source |
| Legal and privacy | Can I switch plans or cancel? | source |
| Security and compliance | Not published on the collected pages. | — |
| Uptime and status page | Yes. If 80M credits/month on Max isn't enough, contact support@scrapebadger.com for a custom contract with dedicated proxy pools, higher rate tiers, and SLA. | source |
| Domain registered | 2025-05-16 | — |
| Domain expires | 2029-05-16 | — |
Not found on the collected pages: security and compliance. This only means Scout did not find it on the pages it read; it says nothing about the company itself.
Documentation and product updates
Help resources, product guidance, and visible changes over time.
| Resource or update | Type | What is available | Date or freshness |
|---|---|---|---|
| Product FAQ | FAQ | Answers common product, workflow, pricing, privacy, ownership, API, and team questions. (source) | Not dated |
| How Much Does Web Scraping Cost? Complete 2026 Pricing Guide / ScrapeBadger | Guide | Guides, comparisons, pricing breakdowns, use cases, and how-to articles. (source) | Not dated |
| How to Build a Price Tracking Bot for E-Commerce (Python 2026) / ScrapeBadger | Guide | Guides, comparisons, pricing breakdowns, use cases, and how-to articles. (source) | Not dated |
| How to Build an Amazon Price Tracker With ScrapeBadger (Python 2026) / ScrapeBadger | Guide | Guides, comparisons, pricing breakdowns, use cases, and how-to articles. (source) | Not dated |
| How to Build an eBay Price Tracker With ScrapeBadger / ScrapeBadger / ScrapeBadger | Guide | Guides, comparisons, pricing breakdowns, use cases, and how-to articles. (source) | Not dated |
| How to Scrape Any E-Commerce Site: Platform Guide With Python Code / ScrapeBadger | Guide | Guides, comparisons, pricing breakdowns, use cases, and how-to articles. (source) | Not dated |
Not found in the collected public sources: public roadmap, changelog or release notes, status page, separate help center or knowledge base.
Technical
Technical and delivery signals
Delivery model, platforms, API, data ownership, reliability claims and release activity.
| Signal | Finding | Source |
|---|---|---|
| Delivery model (cloud, self-hosted, desktop, browser extension) | Cloud-based API service S1. | S1 |
| Platforms and apps | Web-based API, accessible via HTTP requests S1. | S1 |
| API and extensibility (API, SDK, webhooks, MCP, plugins) | Provides a web scraping API and MCP server for AI agents S1. | S1 |
| Data ownership and export | Not published on the collected pages. | — |
| Performance and reliability claims | Claims to bypass anti-bot systems and handle proxy rotation automatically S1. | S1 |
| Release activity | New endpoints launch on every plan immediately S73. | S73 |
Measured infrastructure
Domain, certificate, and hosting signals, measured directly.
| Signal | Finding |
|---|---|
| Domain registered | 2025-05-16 — HOSTINGER operations, UAB |
| Domain expires | 2029-05-16 |
| First archived | 2026-01-13 — web archive |
| TLS certificate | Google Trust Services, valid, expires 2026-12-04 |
| Security headers | HSTS, X-Content-Type-Options, X-Frame-Options |
| Headers not served | CSP, Referrer-Policy |
| Server header | cloudflare |
| Mail handled by | mx1.hostinger.com, mxb.mailgun.org |
| Nameservers | lana.ns.cloudflare.com, drew.ns.cloudflare.com |
Technical site audit
A bounded multi-page crawl with page-level issues and URLs.
Scout — Bounded technical crawl
- Pages crawled: 15 of 15 maximum
- Technical health: 97/100
- Critical issues: 0
- Warnings: 7
- Notices: 4
Issues
| Severity | Issue | Value | Affected URL |
|---|---|---|---|
| warning | Title length should be reviewed | 73 | https://scrapebadger.com/google-scraper-api |
| notice | Meta description length should be reviewed | 195 | https://scrapebadger.com/google-scraper-api |
| warning | Title length should be reviewed | 85 | https://scrapebadger.com/twitter-scraper-api |
| warning | Title length should be reviewed | 77 | https://scrapebadger.com/ecommerce-scraper-api |
| warning | Title length should be reviewed | 74 | https://scrapebadger.com/chatgpt-scraper |
| notice | Meta description length should be reviewed | 194 | https://scrapebadger.com/chatgpt-scraper |
| warning | Title length should be reviewed | 77 | <https://scrapebadger.com/AI modelscraper> |
| notice | Meta description length should be reviewed | 174 | <https://scrapebadger.com/AI modelscraper> |
| warning | Title length should be reviewed | 79 | https://scrapebadger.com/scrapers |
| notice | Meta description length should be reviewed | 184 | https://scrapebadger.com/scrapers |
| warning | Page should have one primary H1 | 2 | https://scrapebadger.com/blog |
Crawled pages
| Status | Title | H1s | Words | Response | URL |
|---|---|---|---|---|---|
| 200 | ScrapeBadger \ | Scrape Any Website - Web Scraping API | 1 | 3322 | 44 ms |
| 200 | What's New - ScrapeBadger \ | Product Announcements | 1 | 3026 | 583 ms |
| 200 | Google Scraper APIs Built for Speed, Simplicity, and Scale \ | ScrapeBadger | 1 | 2125 | 84 ms |
| 200 | Twitter Scraping APIs \ | Get Multiple Endpoints (User, Tweets and More) \ | ScrapeBadger | 1 | 1958 |
| 200 | Ecommerce Scraper APIs for Products, Prices, Reviews & Sellers \ | ScrapeBadger | 1 | 2520 | 96 ms |
| 200 | Reddit Scraper - Reddit API \ | ScrapeBadger | 1 | 2617 | 191 ms |
| 200 | eBay Scraper API \ | Anti-Bot Bypass Built In \ | ScrapeBadger | 1 | 2364 |
| 200 | Amazon Scraper API \ | Anti-Bot Bypass Built In \ | ScrapeBadger | 1 | 2005 |
| 200 | Vinted Scraper API \ | Free Credits + No Account \ | ScrapeBadger | 1 | 2332 |
| 200 | ChatGPT Scraper API – Ask ChatGPT & Get JSON with Citations \ | ScrapeBadger | 1 | 1535 | 81 ms |
| 200 | AI modelScraper API – Ask Google AI model & Get JSON with Sources \ | ScrapeBadger | 1 | 1304 | 52 ms |
| 200 | All Scraper APIs - ScrapeBadger \ | Search, E-commerce, Social, Real Estate & LLM | 1 | 2206 | 40 ms |
| 200 | ScrapeBadger Pricing – Plans from $49/mo, PAYG from $10 | 1 | 1062 | 26 ms | https://scrapebadger.com/pricing |
| 200 | Blog - ScrapeBadger \ | News, Tutorials & Updates | 2 | 688 | 59 ms |
| 200 | Contact Us - ScrapeBadger \ | Get Support & Help | 1 | 269 | 20 ms |
This is a bounded Scout crawl. Core Web Vitals and Lighthouse scores are not claimed unless a dedicated performance audit is connected.
Search Console and Analytics
First-party search and behavioral data connection state.
Modeled acquisition channels
| Channel | Estimated share |
|---|---|
| direct | 37.5% |
| search | 41.5% |
| search organic | 40.5% |
| search paid | 1.0% |
| social | 4.1% |
| social organic | 3.7% |
| social paid | 0.4% |
| referrals | 11.2% |
| paid referrals | 1.8% |
| 1.9% | |
| gen ai | 1.1% |
| affiliate | 1.0% |
| other | 0.0% |
First-party connections
| Integration | Status | Data available after connection |
|---|---|---|
| Google Search Console | Not connected | Clicks, impressions, CTR, average position, queries, pages, countries, and devices |
| Google Analytics | Not connected | Organic sessions, engagement, landing pages, conversions, geography, and devices |
No first-party Search Console or Analytics numbers are shown until the site owner authorizes the corresponding Google account. Scout traffic model values above are modeled estimates, not private analytics totals.
Limits and method
Limitations and open questions
Known constraints and missing evidence from the collected pages.
The collected pages do not mention any competitors by name. Evidence gaps include lack of company ownership details, contact information, security certifications, and uptime statistics. Open questions remain about data retention policies and specific performance metrics.
Sources, method, and limitations
Evidence inventory, collection method, provider use, and constraints.
This report is based on 15 collected pages from scrapebadger.com, including the homepage, pricing page, and product documentation. The evidence catalog includes 180 entries from static and rendered pages. External proof search was performed but no external reviews were scraped. Limitations include potential marketing bias in vendor-provided content and lack of independent verification of claims.
- Documentationhttps://scrapebadger.com/Verified
- Pricing Pagehttps://scrapebadger.com/pricingVerified
- Pricing Pagehttps://scrapebadger.com/blog/amazon-price-intelligence-how-to-monitor-10000-skus-without-breaking-the-bankVerified
- Pricing Pagehttps://scrapebadger.com/blog/how-much-does-web-scraping-cost-the-complete-2026-pricing-guideVerified
- Pricing Pagehttps://scrapebadger.com/blog/how-to-build-a-flight-price-alert-system-with-scrapebadgerVerified
- Pricing Pagehttps://scrapebadger.com/blog/how-to-build-a-price-tracking-bot-for-e-commerce-websites-python-2026Verified
- Pricing Pagehttps://scrapebadger.com/blog/how-to-build-an-amazon-price-tracker-with-scrapebadgerVerified
- Pricing Pagehttps://scrapebadger.com/blog/how-to-build-an-ebay-price-tracker-with-scrapebadgerVerified
- Pricing Pagehttps://scrapebadger.com/blog/how-to-use-amazon-data-for-competitive-intelligence-beyond-just-pricingVerified
- Pricing Pagehttps://scrapebadger.com/blog/tired-of-serpapis-pricing-heres-what-to-actually-look-for-in-a-google-serp-apiVerified
- Pricing Pagehttps://scrapebadger.com/ecommerce-scraper-api/amazon-priceVerified
- Pricing Pagehttps://scrapebadger.com/ecommerce-scraper-api/walmart-priceVerified
- Official Websitehttps://scrapebadger.com/blog/build-an-amazon-product-research-agent-with-scrapebadger-claudeVerified
- Pricing Pagehttps://scrapebadger.com/blog/how-to-extract-product-prices-from-websites-automaticallyVerified
- Official Websitehttps://scrapebadger.com/blog/how-to-scrape-any-e-commerce-site-a-platform-by-platform-intelligence-guideVerified
- Articlehttps://docs.scrapebadger.com/Verified
- Articlehttps://docs.scrapebadger.com/api-reference/introductionVerified
- Articlehttps://scrapebadger.com/sdksVerified
- Articlehttps://scrapebadger.com/scrapersVerified
- Articlehttps://scrapebadger.com/web-scraping-api/docsVerified
- Articlehttps://docs.scrapebadger.com/web-scraping/overviewVerified
- Articlehttps://scrapebadger.com/integrationsVerified