1.3k stars · GPL-3.0 · v4.2.1 (2026-08-26) · Track this in Scout
Indexes a folder tree and serves a search page over the contents of the files, including files inside zip, rar and 7z archives, with OCR for scanned pages.
▶Repo detailsthe review · specs · pros & cons · install
What it is
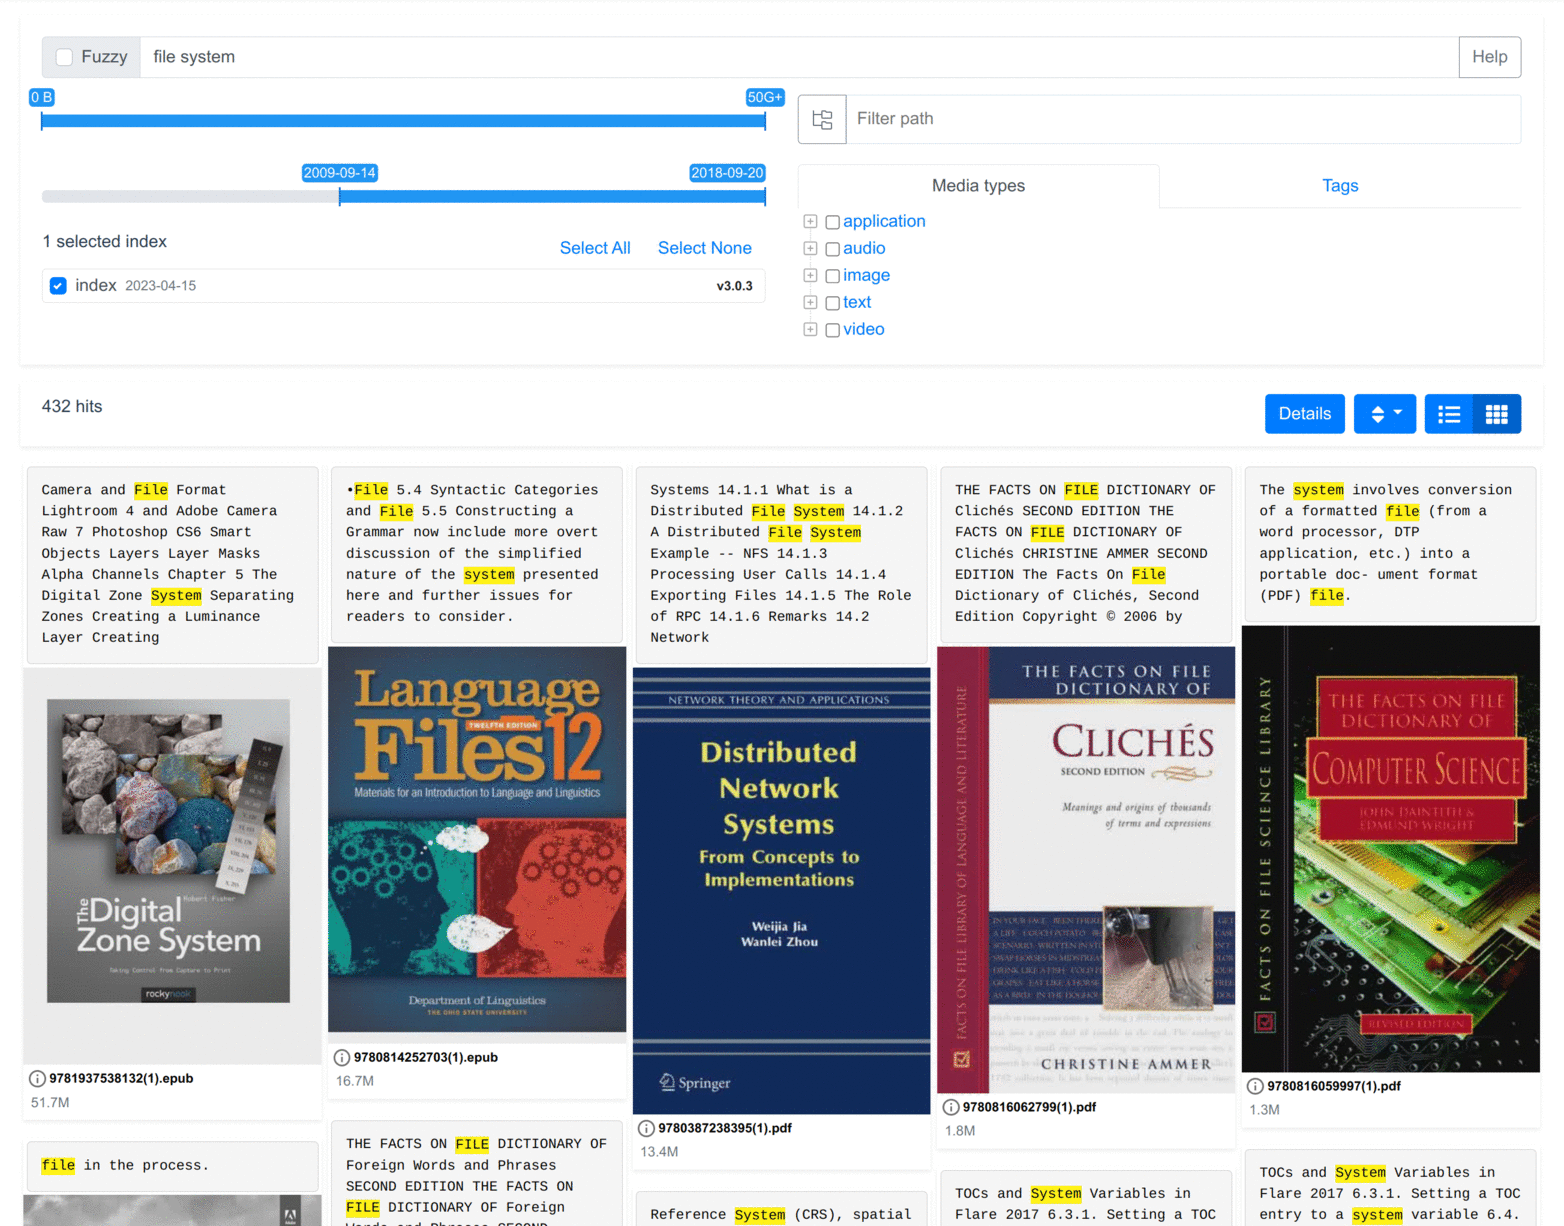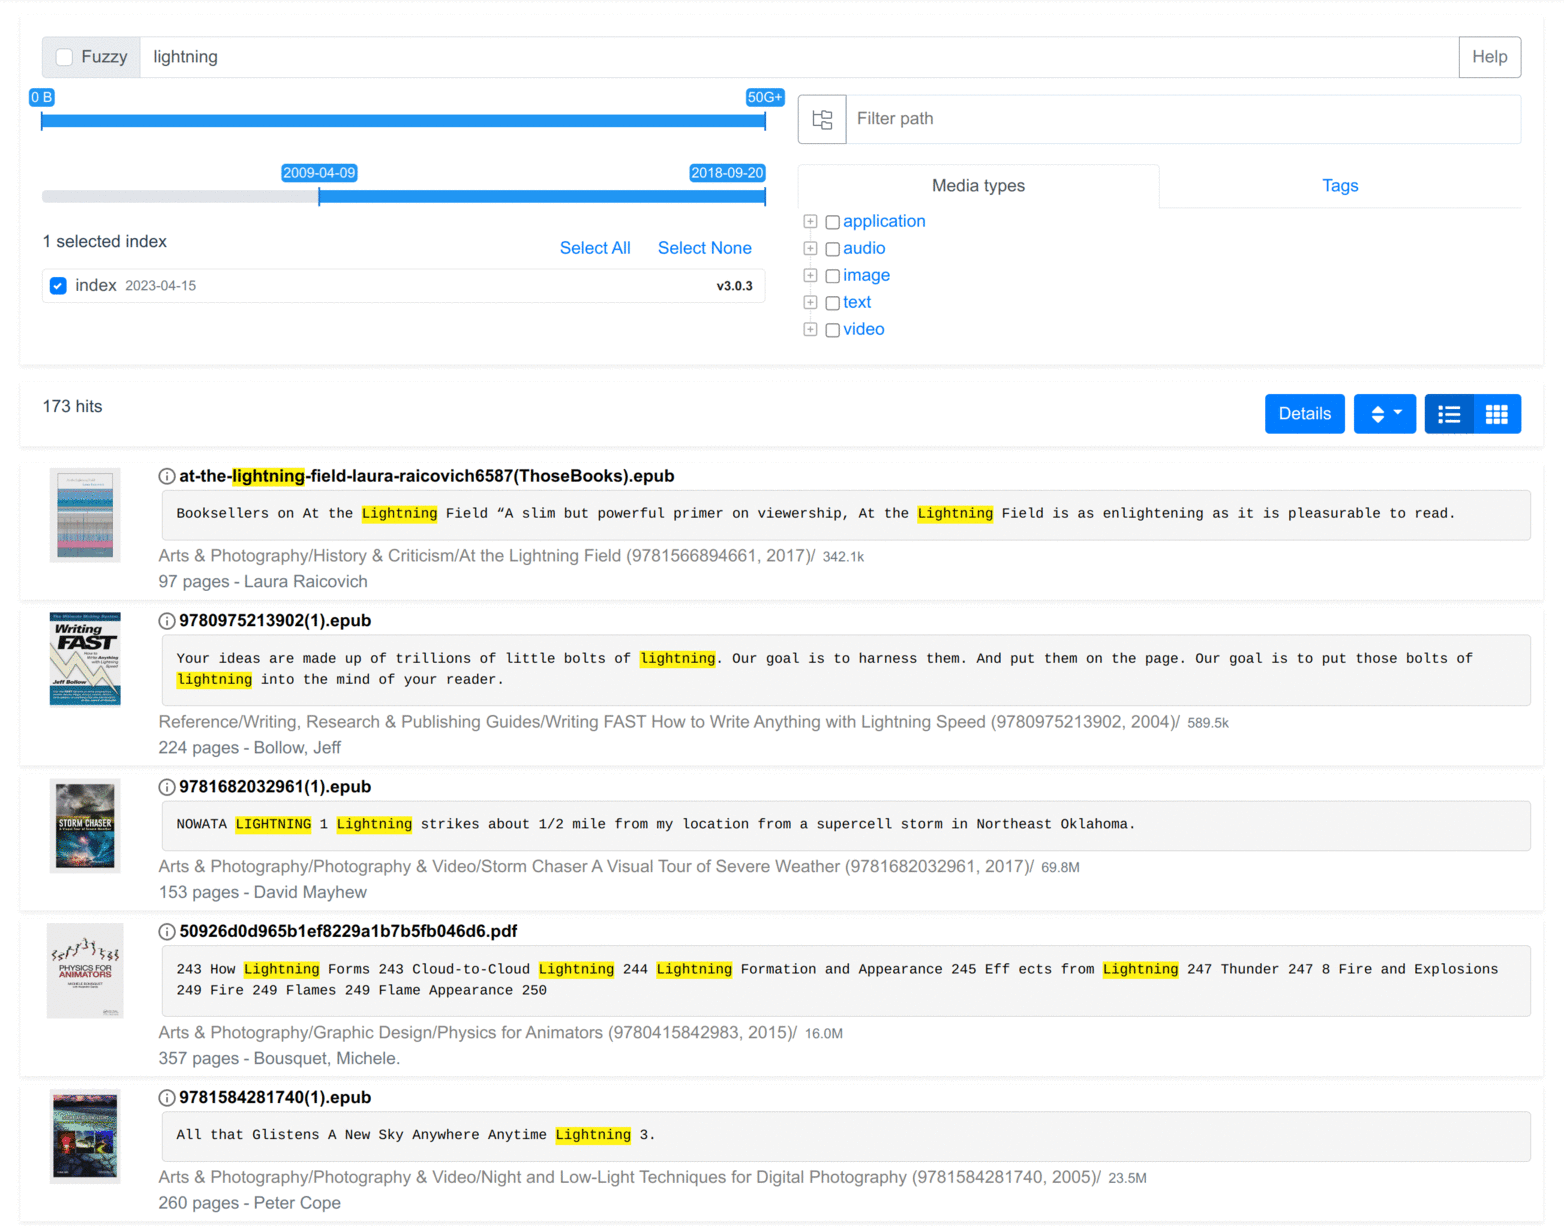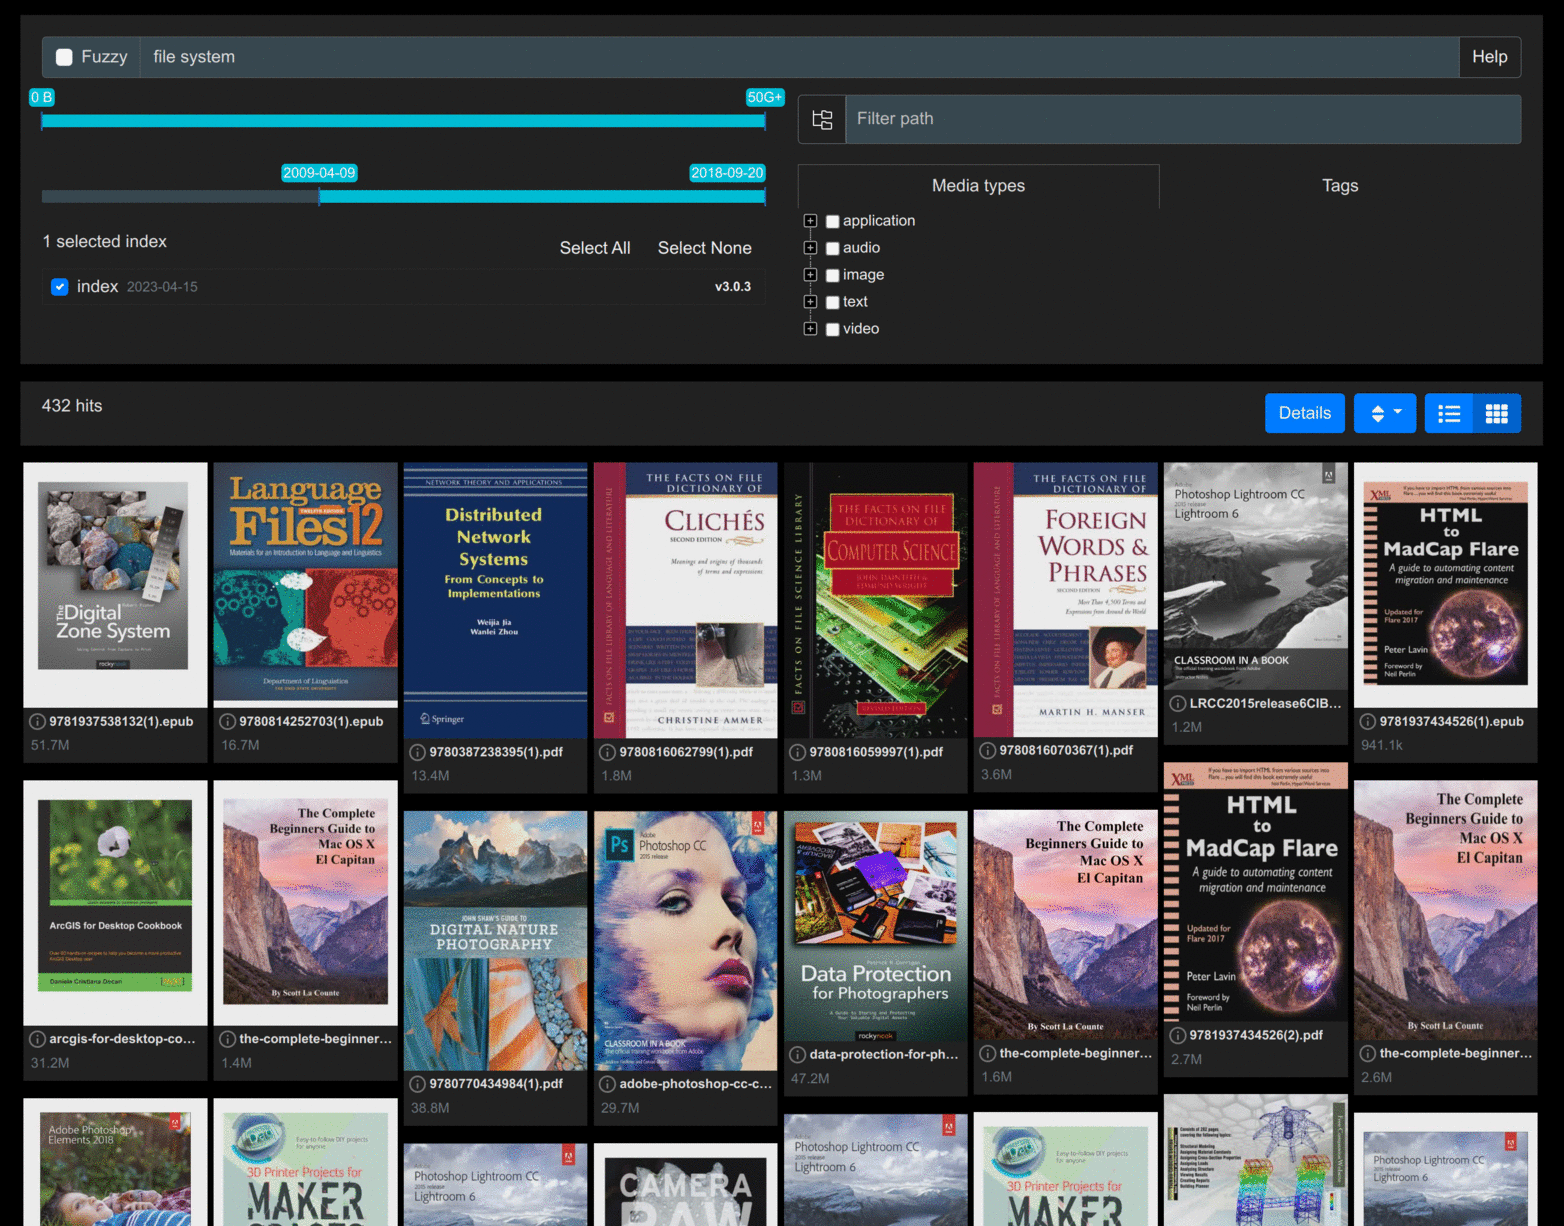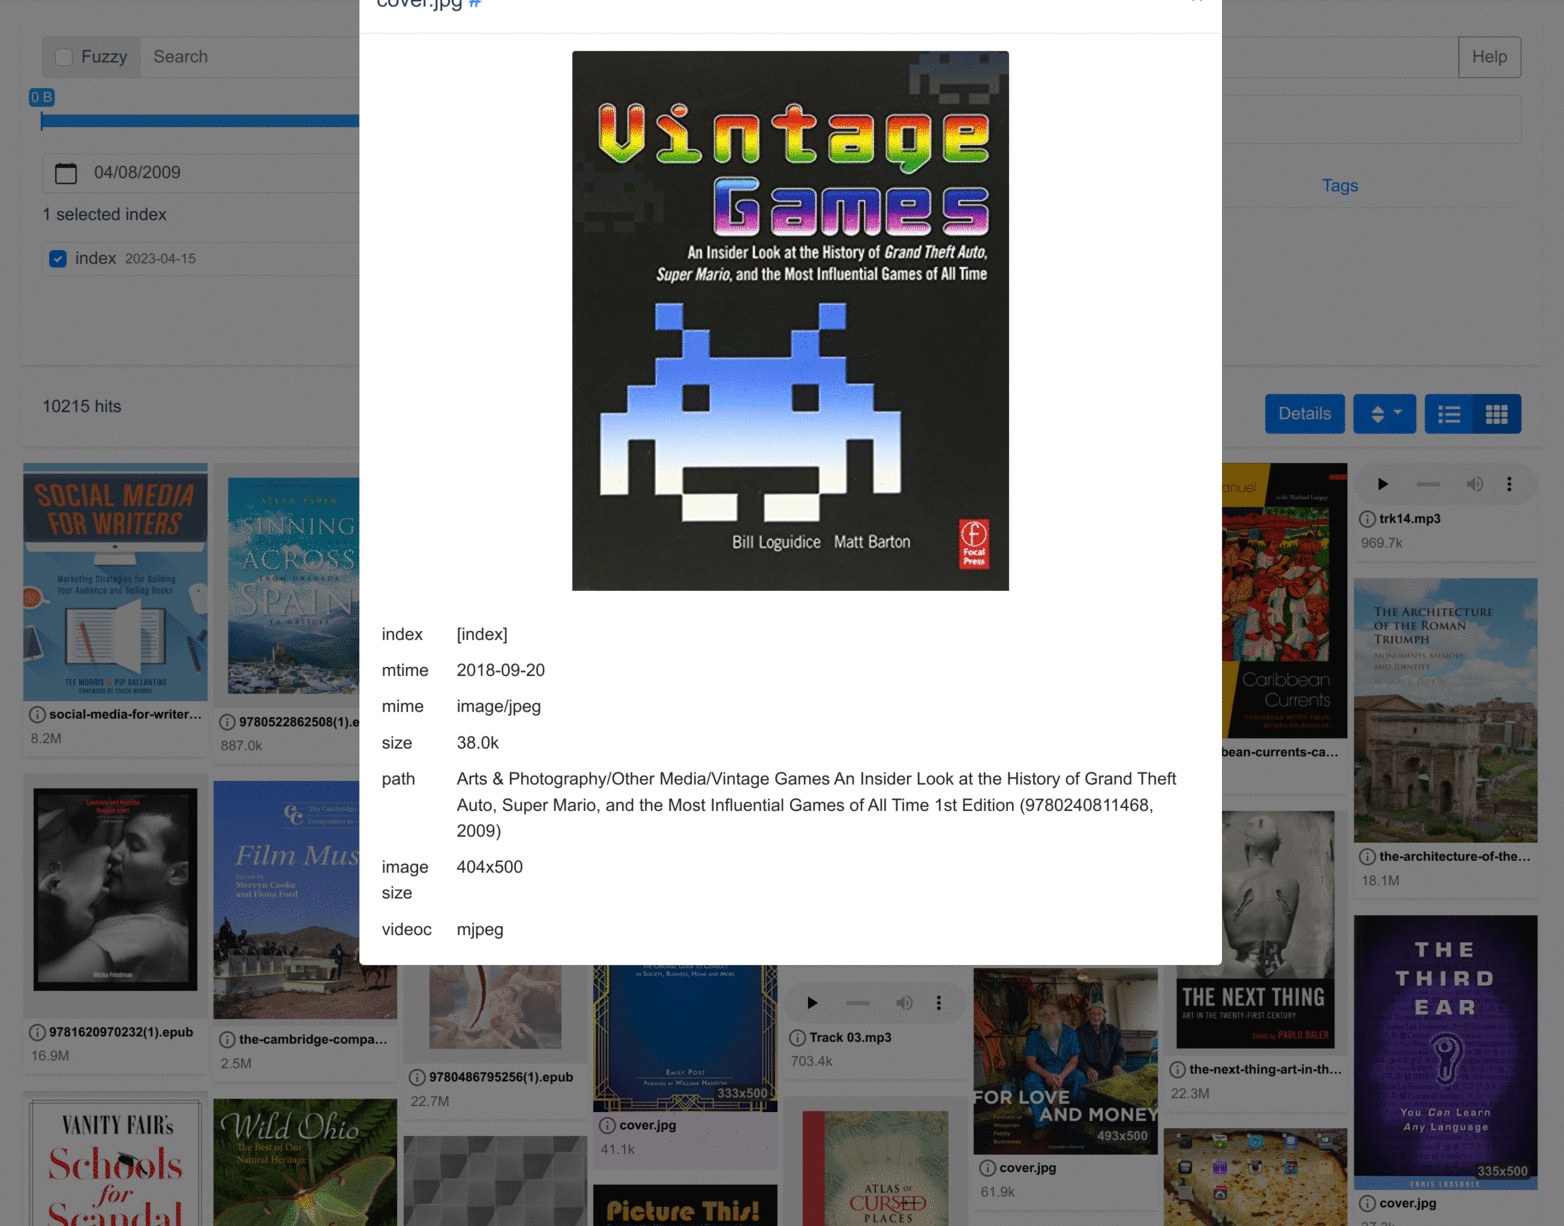
sist2 is a single program for Linux, also available as a Docker image. It walks a folder tree, pulls the text and details out of each file, makes small preview pictures, and serves a web page you search from. The index can live in a small local file, or in Elasticsearch if you want the heavier search engine.What it is good for. Anybody with a pile of documents they cannot search. It handles PDF, EPUB, MOBI, DOCX, HTML, JSON and plain text, reads the details stored inside images, video and audio, and can read the words off a scanned page using OCR, which means teaching a computer to read text in a picture. It also tags files, by hand or by rule, and re-scanning only looks at what changed. For you: point it at the folder where the Grasppy research, the transcripts and the old reports live, and stop searching by filename.
- It looks inside zip, rar and 7z folders, which almost no other tool does.
- With the small local index it uses about 20 MB of memory, so it costs almost nothing to keep.
- Re-scanning is cheap, so you can run it nightly and always have a current index.
- It is three separate commands: scan, then index, then serve. There is a web screen that hides this, but the screen itself needs Docker.
- The well-tested path uses Elasticsearch, which the project says needs more than 500 MB of memory. The small local option is lighter but less used.
- One maintainer, 1.3k stars, and GPL-3.0, which means you cannot quietly build it into a product you sell.
- paperless-ngx/paperless-ngx
Also reads scanned pages and searches your documents, but it is a filing cabinet you move documents into, where sist2 indexes files where they already sit.
Track this in Scout - eikek/docspell
The same reading and searching of personal documents, with suggestions and email intake, at the cost of a much heavier Scala setup.
Track this in Scout - phiresky/ripgrep-all
The same searching inside PDFs, documents and subtitles, but as a one-off command with no index, no web page and no previews.
Track this in Scout
# Download the sist2 binary from the GitHub releases page, then:
sist2 scan ~/Documents --output ./documents.sist2
sist2 index ./documents.sist2
sist2 web ./documents.sist2      # search page on http://localhost:4090