In simple English
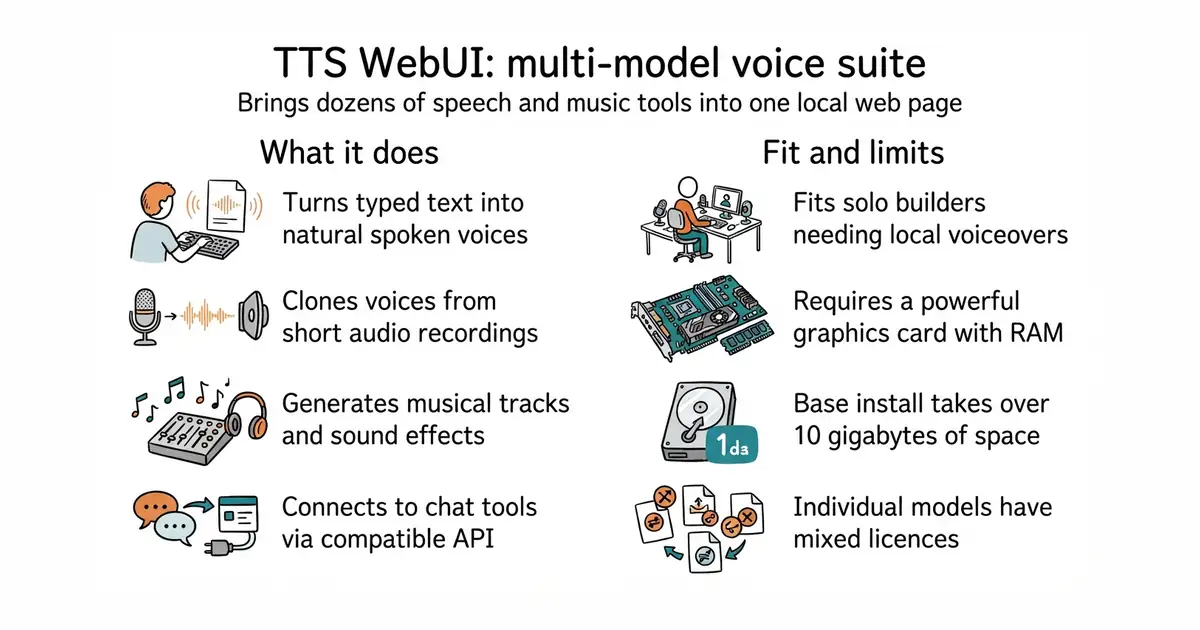
This program lets you turn text into spoken voices, generate musical tracks, and clone people's speech from audio clips. It collects many popular speech tools into one place so you do not have to install them separately. You control everything through a visual web page running on your own computer. It is free to download and use under an open-source licence. But you need a powerful computer with a dedicated graphics card to run the models.
What it is
A web-based interface built with Python and TypeScript that bundles dozens of text-to-speech, voice conversion, and music generation models. It includes an extension marketplace and an OpenAI-compatible API so you can connect it to chat applications.
What it is good for
Solo builders who want to generate custom voiceovers for videos, clone voices for characters, or connect a local voice generator to chat interfaces without dealing with separate command-line installations for each model.
- Combines dozens of different voice and music generation models in one interface.
- Provides an OpenAI-compatible API to connect with external chat tools and user interfaces.
- Includes a built-in extension marketplace to install new models directly from the browser.
- Requires a hefty base installation of over 10 GB, plus several gigabytes for each additional model.
- Needs a powerful graphics card with plenty of memory to generate audio locally without crashing.
- Different underlying models carry mixed and restrictive licences, including non-commercial ones.
Installing and running multiple separate voice generation repositories and command-line tools manually
Silly Tavern
- RVC-Project/Retrieval-based-Voice-Conversion-WebUI39k stars
Focuses specifically on voice conversion rather than bundling dozens of different text-to-speech engines.
- coqui-ai/TTS46k stars
Provides a comprehensive library for text-to-speech training and synthesis without the multi-model web interface wrapper.


- snapcast/snapcast8.0k stars
A server and clients that play one audio stream in several rooms, kept in time with each other.
- MusicPlayerDaemon/MPD2.8k stars
A background music player with no interface of its own, controlled over a network by separate client programs.
- AcademySoftwareFoundation/OpenTimelineIO2.0k stars
An interchange format and library for editing timelines: the order and length of cuts, and references to the media, but not the media.
git clone https://github.com/rsxdalv/tts-webui.git
cd tts-webui
pip install -r requirements.txt
python server.py