26.3k stars · MIT · chatterbox-tts 0.1.7 on PyPI (2026-03-26); the only GitHub tag is v0.1.2 (2026-06-13) — the two numbering schemes do not correspond · Track this in Rising ↗
Open-source text-to-speech that clones a voice from a short clip and reads it back in 23 languages, Russian included.
Radar check
What we found when we opened it. Every bar is one fact, with its date.
Last code pushed 21 Jul 2026, 3 months before this check.
Latest release v0.1.2 on 13 Jun 2025.
Public since April 2025, a little over 1 year.
27,305 stars and 3,678 forks.
0 commits and 18 new issues in the last 90 days.
16 contributors. No pull requests merged in 90 days; changes go in directly.
No security policy file says how to report a problem. No published security advisories.
How the bars are scored
- Alive. Days since the last code push: a week or less 100, a month 90, three months 70, six months 50, a year 30, eighteen months 15, older 0.
- Releases. Age of the latest GitHub release, on a similar scale; no bar when the project publishes no releases.
- Maturity. Age of the project: eight years 100, five 90, three 70, two 55, one 40, six months 25, younger 10.
- Adoption. Stars on a log scale: 100,000 stars is 100, 10,000 is 80, 1,000 is 60, 100 is 40.
- Activity. Commits in the last 90 days: 300 or more 100, 100 85, 30 65, 10 45, any 25.
- Community. People who have contributed: 100 or more 100, 30 80, 10 60, 5 40, 2 25, one 10.
- Security. A published security policy 80, none 40; published advisories are listed, not scored.
Checked by Repo Radar on 27 Oct 2026 from the repository on GitHub. Covered in Edition 13.
▶Repo detailsthe review · specs · pros & cons · install
What it does
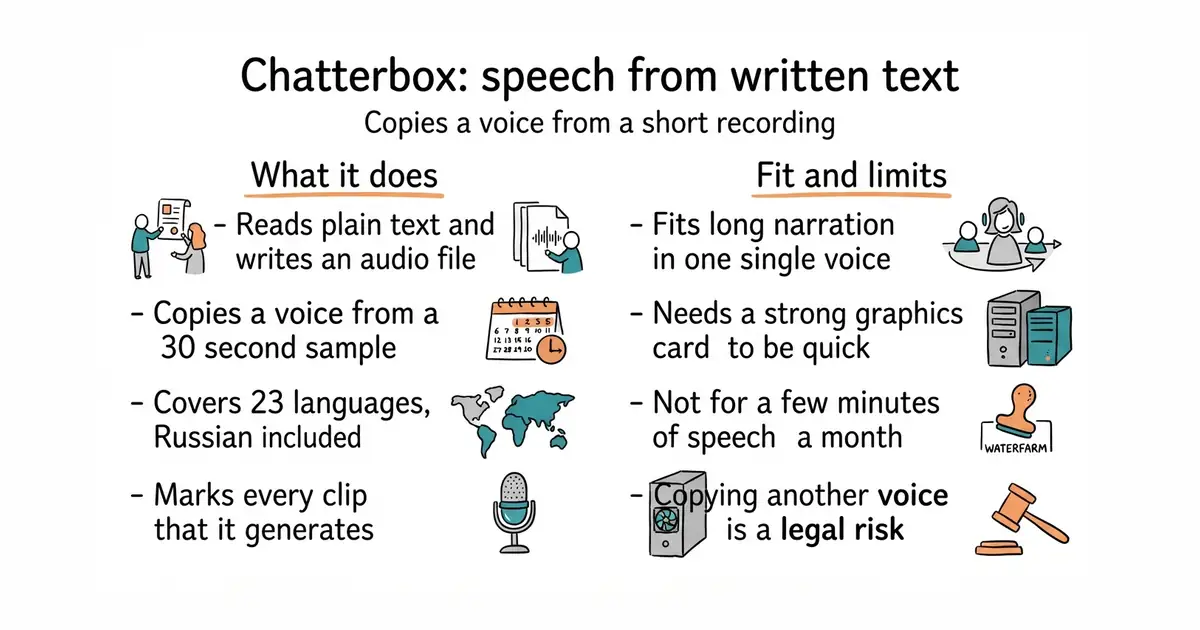
It is a text-to-speech model, which means software that turns written words into spoken audio. It reads a block of plain text and writes an audio file. It can use its own default voice or copy one from a short recording. The project lists 23 languages. There is a control for how much feeling the voice puts into a line, which most free tools of this kind do not have. Every clip it produces carries a hidden marker, so audio made by this model can be recognised later. It runs locally and calls no outside service. It does not edit video, it does not translate text, and it has no way of knowing whether the voice in a sample belongs to the person using it.
Why it matters
Who it suits. It suits anyone who needs a large amount of narration in one consistent voice, especially in two or more languages, and who does not want a bill that grows with every sentence. It also suits work where a single wrong line must be re-recorded often, because a correction becomes one command instead of a studio session. Skip it if the machine has no capable graphics card, or if the job is only a few minutes of speech a month, where a paid service is less effort.
Verdict. Worth an afternoon if the hardware is there, and little use without it. The sound quality is good enough for narration, though a careful listener can still tell it is generated. Treat the voice-copying as the legal question it is: copying your own voice is fine, copying someone else's without permission is not, and the software cannot tell the two apart. If the hardware is weak, #2 runs on anything and is the sensible fallback for drafts.
Summary (Key Points)from the README
Key features
- Chatterbox-Turbo: A 350M-parameter English model for low-latency voice agents, with its speech-token-to-mel decoder distilled from 10 steps to one.
- Chatterbox-Nano: A 110M-parameter model that shares Turbo's architecture and targets CPU and on-device use, running 3x faster than realtime on 8 CPU cores.
- Paralinguistic tags: Turbo and Nano natively support tags such as [cough], [laugh] and [chuckle] to add realism to speech.
- Multilingual V3: A 0.5B general-purpose model covering 23+ languages, with improved speaker similarity and fewer hallucinations than earlier multilingual versions.
- Single Language Pack: Six dedicated finetunes for priority languages and regional variants, including Latam Spanish, Brazilian Portuguese and Portugal Portuguese.
- Voice conversion: The repository includes an example_vc.py script alongside the TTS examples.
- Tuning controls: Exaggeration and cfg_weight settings, with documented defaults of 0.5 each and guidance for pacing and expressive speech.
- Built-in watermarking: Every generated audio file carries the PerTh watermark, which the README says survives MP3 compression and editing.
Ways to install
| Platform or method | What it needs | Effort |
|---|---|---|
| Default install (command not shown in this README text) | Python environment; the README's tested setup is Python 3.11 on Debian 11 | Low |
| Install from source | Python 3.11 tested; dependencies pinned in pyproject.toml; can modify code and dependencies | Higher |
Important
- Language scope: Turbo and Nano are English-only, so multilingual use requires the V3 model or a Single Language Pack model.
- Reference clip language: The reference clip should match the language tag, or the output may inherit the reference clip's accent. The README suggests cfg_weight 0 to reduce this.
- Tested environment: The README reports testing only on Python 3.11 with Debian 11, so other setups are unverified.
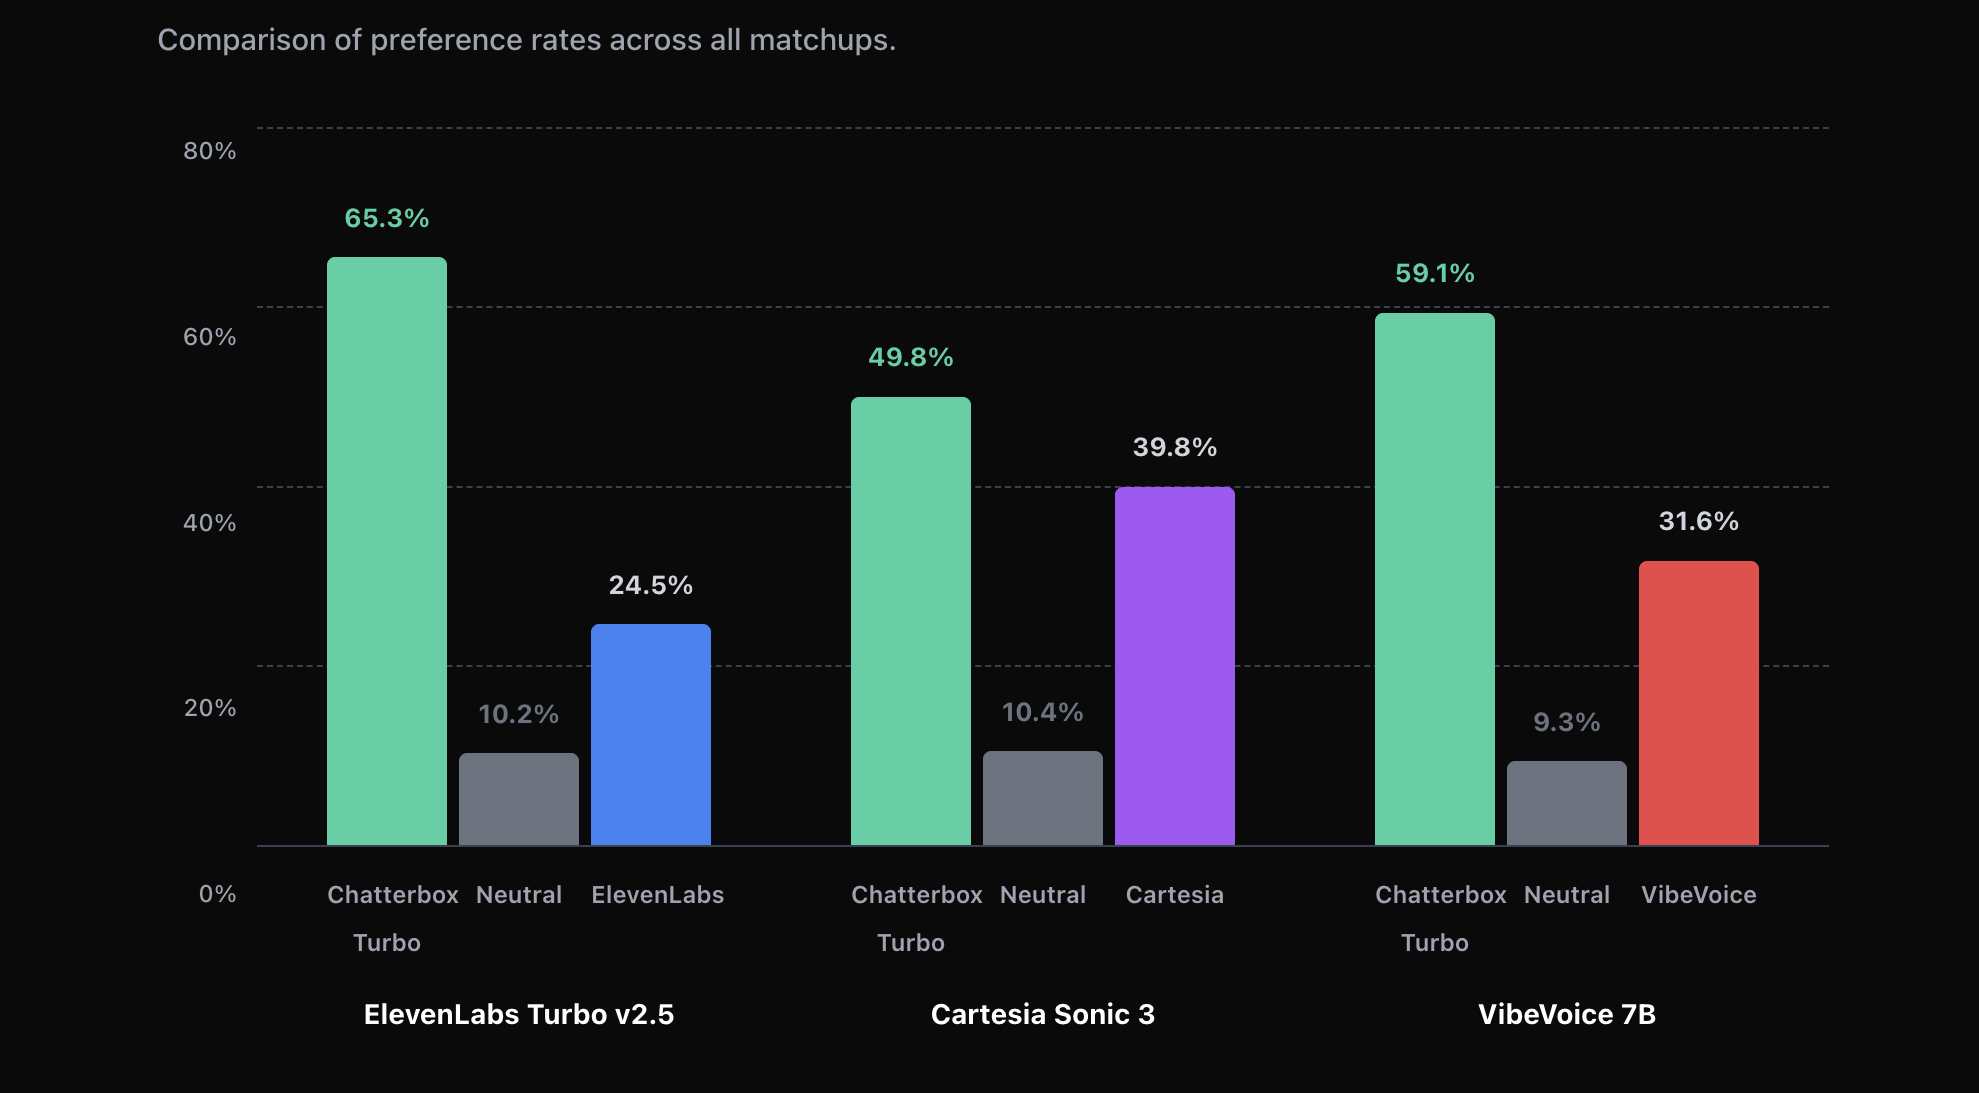
- Vendor-run evaluations: The Turbo comparisons against ElevenLabs, Cartesia and VibeVoice were run by Podonos and are reported by the project, not independently verified here.
- Commercial service: The README promotes a paid TTS service with a sub-200ms latency claim, which is a vendor statement.
- Misuse: The disclaimer asks users not to use the model for harmful purposes, and notes that prompts come from freely available internet data.
Written by an AI model from the project’s README; not part of the review, and it can be wrong.
- One voice across all 23 languages, which no per-character service makes easy.
- MIT licence, so the output can be used in commercial work.
- No charge per word, so length and re-recording stop being cost decisions.
- It wants a GPU, a graphics card that can do heavy mathematics. On an ordinary processor it is slow.
- The version numbers disagree. PyPI has 0.1.7 from 26 March 2026; the newest tag on GitHub is the older v0.1.2. Install from PyPI and pin the version.
- Voice copying carries real legal risk, and nothing in the tool checks consent.
Correcting one wrong sentence in a long series stops being a cost and becomes one command.
python3 -m venv venv
source venv/bin/activate
pip install chatterbox-tts