In simple English
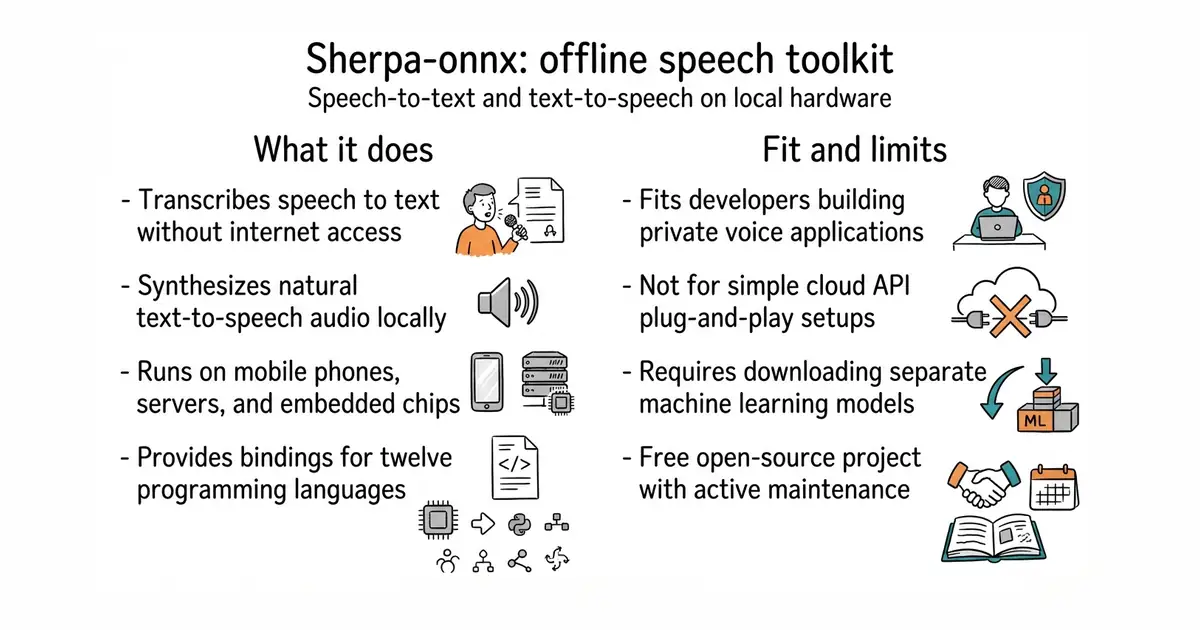
This tool lets your apps listen to speech and speak out loud. It runs on phones, computers, and tiny microchips without an internet connection. Your voice data stays on your hardware and never goes to a remote server. You can use it in Python, C++, JavaScript, and many other programming languages. It is free to use for any project.
What it is
Sherpa-onnx is an open-source library that runs speech and audio models locally using the ONNX Runtime (a way to run trained machine learning models quickly on normal hardware). It handles speech-to-text, text-to-speech, speaker identification, noise removal, and keyword spotting across dozens of platforms.
What it is good for
Solo builders who want to add voice commands, offline transcription, or text reading to mobile apps, desktop tools, or embedded hardware without paying for cloud speech APIs.
- Works completely offline with no internet connection required.
- Supports twelve programming languages and many operating systems.
- Runs efficiently on normal CPUs as well as mobile devices and specialized chips.
- Requires downloading and managing separate model files for each language and task.
- Compiling from source for unusual embedded architectures takes considerable time and patience.
- Large neural network models need sufficient memory to run smoothly.
Paid cloud speech recognition and text-to-speech APIs
Silero VAD for voice activity detection
- openai/whisper111k stars
OpenAI's official speech recognition model repository, though sherpa-onnx runs faster on local hardware and supports more platforms.
- ggml-org/whisper.cpp55k stars
Port of Whisper to C/C++ for fast local inference, whereas sherpa-onnx supports a wider range of audio tasks beyond transcription.


- snapcast/snapcast8.0k stars
A server and clients that play one audio stream in several rooms, kept in time with each other.
- MusicPlayerDaemon/MPD2.8k stars
A background music player with no interface of its own, controlled over a network by separate client programs.
- AcademySoftwareFoundation/OpenTimelineIO2.0k stars
An interchange format and library for editing timelines: the order and length of cuts, and references to the media, but not the media.
pip install sherpa-onnx