In simple English
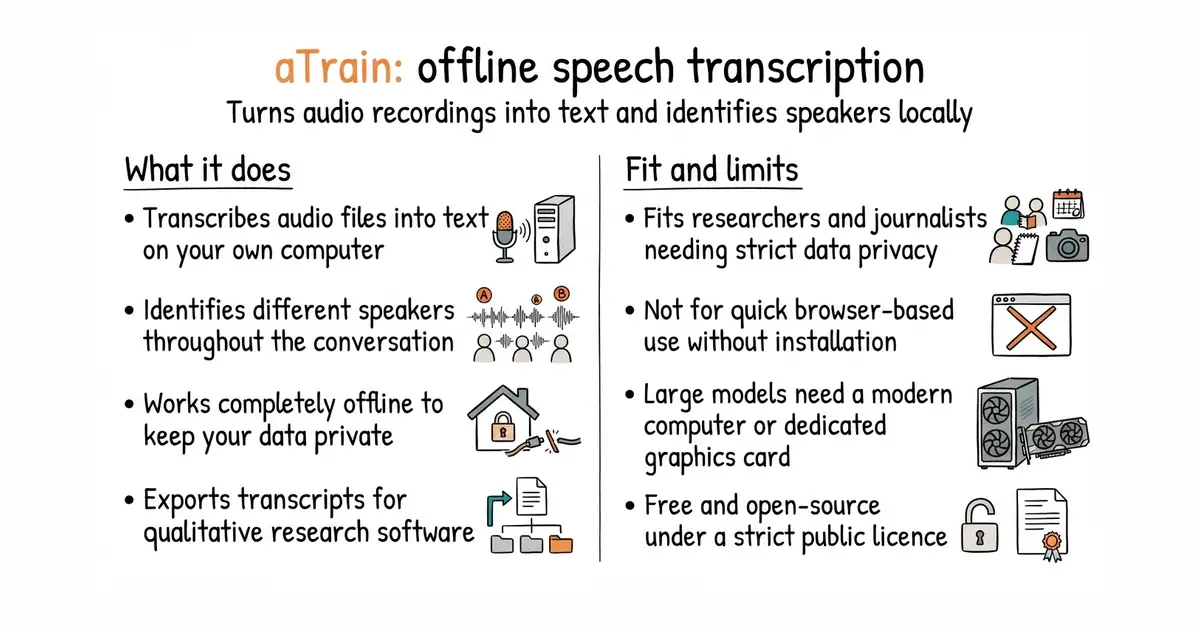
This program turns recordings of speeches or interviews into written text. It runs entirely on your own computer, so your audio files never leave your machine. It also figures out who is speaking at any given time in the recording. You can download it as a ready-made app or run it through commands. It costs nothing to use, but running the largest models needs a modern computer with plenty of memory.
What it is
A desktop application and command-line tool for offline speech transcription and speaker diarization (splitting an audio recording into text segments grouped by the person speaking). It uses the faster-whisper (a fast local speech-to-text engine) and pyannote.audio (a toolkit that identifies who spoke which words) libraries.
What it is good for
Researchers, journalists, and solo builders who need to transcribe interviews or meetings locally to keep data private or comply with strict privacy laws.
- Processes all audio completely offline on your device to keep sensitive recordings private.
- Labels different speakers automatically in the transcript so you can follow conversations easily.
- Exports files in formats that work directly with research and qualitative analysis tools.
- Large transcription models need a powerful computer or a dedicated NVIDIA graphics card to run quickly.
- Running the app via commands requires Python and familiarity with terminal tools.
- The AGPL-3.0 licence (a strict open-source rule about sharing modified code) applies if you build upon it.
paying for cloud transcription services like Otter or manual transcription work
MAXQDA
- openai/whisper111k stars
OpenAI's original command-line speech recognition model, which aTrain uses under the hood.
- SYSTRAN/faster-whisper26k stars
A faster, more memory-efficient engine for running Whisper models locally.
- pyannote/pyannote-audio11k stars
A toolkit for speaker diarization that figures out who spoke in an audio recording.


- mpv-player/mpv38k stars
A command-line media player that handles most audio, video and subtitle formats and can be driven entirely from scripts.
- snapcast/snapcast8.0k stars
A server and clients that play one audio stream in several rooms, kept in time with each other.
- MusicPlayerDaemon/MPD2.8k stars
A background music player with no interface of its own, controlled over a network by separate client programs.
pip install "aTrain[gui] @ git+https://github.com/aTrainTranscription/aTrain.git"