In simple English
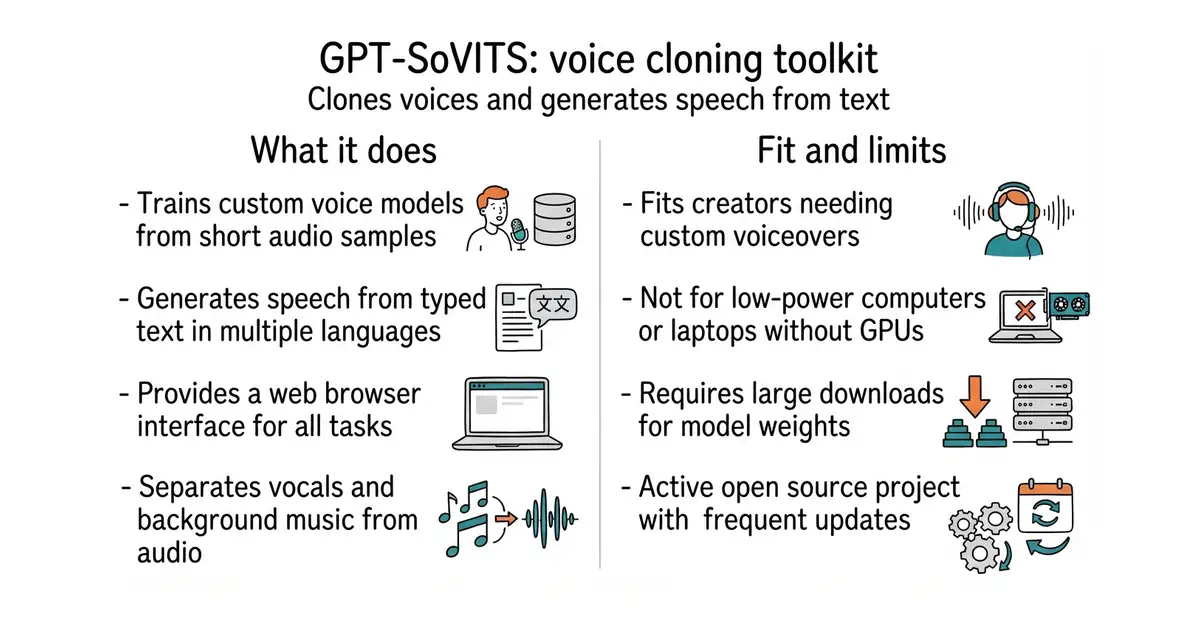
This tool lets you clone a human voice using a short audio recording. You give the program one minute of someone speaking, and it learns their voice. Then you type any text, and the program reads it out loud in that exact voice. It includes a web page interface so you can slice audio, remove background music, and train models without writing code. You need a computer with a dedicated graphics card to run it well. The software is free to use under an open-source licence.
What it is
GPT-SoVITS is a few-shot voice cloning and text-to-speech toolkit with an integrated graphical control panel. It combines a language model for text processing with a neural audio synthesizer to generate realistic speech in multiple languages.
What it is good for
Solo builders who need custom voiceovers for videos, podcasts, games, or applications without hiring voice actors.
- Clones voices accurately from very short audio samples.
- Includes a browser-based visual interface for all training steps.
- Supports multiple languages including English, Chinese, Japanese, Korean, and Cantonese.
- Requires a powerful dedicated graphics card with plenty of memory to train models.
- Large download size for pretrained models and supporting tools.
- Complex setup process for manual installations outside of the packaged versions.
Hiring voice actors or manual audio editing for voiceovers.
FFmpeg (a command-line tool for converting and processing audio and video files).
- SWivid/F5-TTS15k stars
Another popular zero-shot text-to-speech model with different underlying architecture.
- fishaudio/fish-speech33k stars
An alternative text-to-speech and voice cloning toolkit that supports multiple languages.


- snapcast/snapcast8.0k stars
A server and clients that play one audio stream in several rooms, kept in time with each other.
- MusicPlayerDaemon/MPD2.8k stars
A background music player with no interface of its own, controlled over a network by separate client programs.
- AcademySoftwareFoundation/OpenTimelineIO2.0k stars
An interchange format and library for editing timelines: the order and length of cuts, and references to the media, but not the media.
conda create -n GPTSoVits python=3.10
conda activate GPTSoVits
bash install.sh --device CUDA --source HF --download-uvr5