4.9k stars · MIT · v0.24.0 (2026-08-20) · Track this in Rising ↗
Apple's interactive embedding map with automatic cluster labelling — recommended as a design study for Grasppy's overview screen, not as a dependency.
Radar check
What we found when we opened it. Every bar is one fact, with its date.
Last code pushed 21 Oct 2026, 6 days before this check.
Latest release v0.26.0 on 15 Oct 2026.
Public since May 2025, a little over 1 year.
4,994 stars and 334 forks.
41 commits and 2 new issues in the last 90 days.
27 contributors. 41 pull requests merged in 90 days.
A security policy says how to report a problem. No published security advisories.
How the bars are scored
- Alive. Days since the last code push: a week or less 100, a month 90, three months 70, six months 50, a year 30, eighteen months 15, older 0.
- Releases. Age of the latest GitHub release, on a similar scale; no bar when the project publishes no releases.
- Maturity. Age of the project: eight years 100, five 90, three 70, two 55, one 40, six months 25, younger 10.
- Adoption. Stars on a log scale: 100,000 stars is 100, 10,000 is 80, 1,000 is 60, 100 is 40.
- Activity. Commits in the last 90 days: 300 or more 100, 100 85, 30 65, 10 45, any 25.
- Community. People who have contributed: 100 or more 100, 30 80, 10 60, 5 40, 2 25, one 10.
- Security. A published security policy 80, none 40; published advisories are listed, not scored.
Checked by Repo Radar on 25 Oct 2026 from the repository on GitHub. Covered in Edition 4.
▶Repo detailsthe review · specs · pros & cons · install
What it does
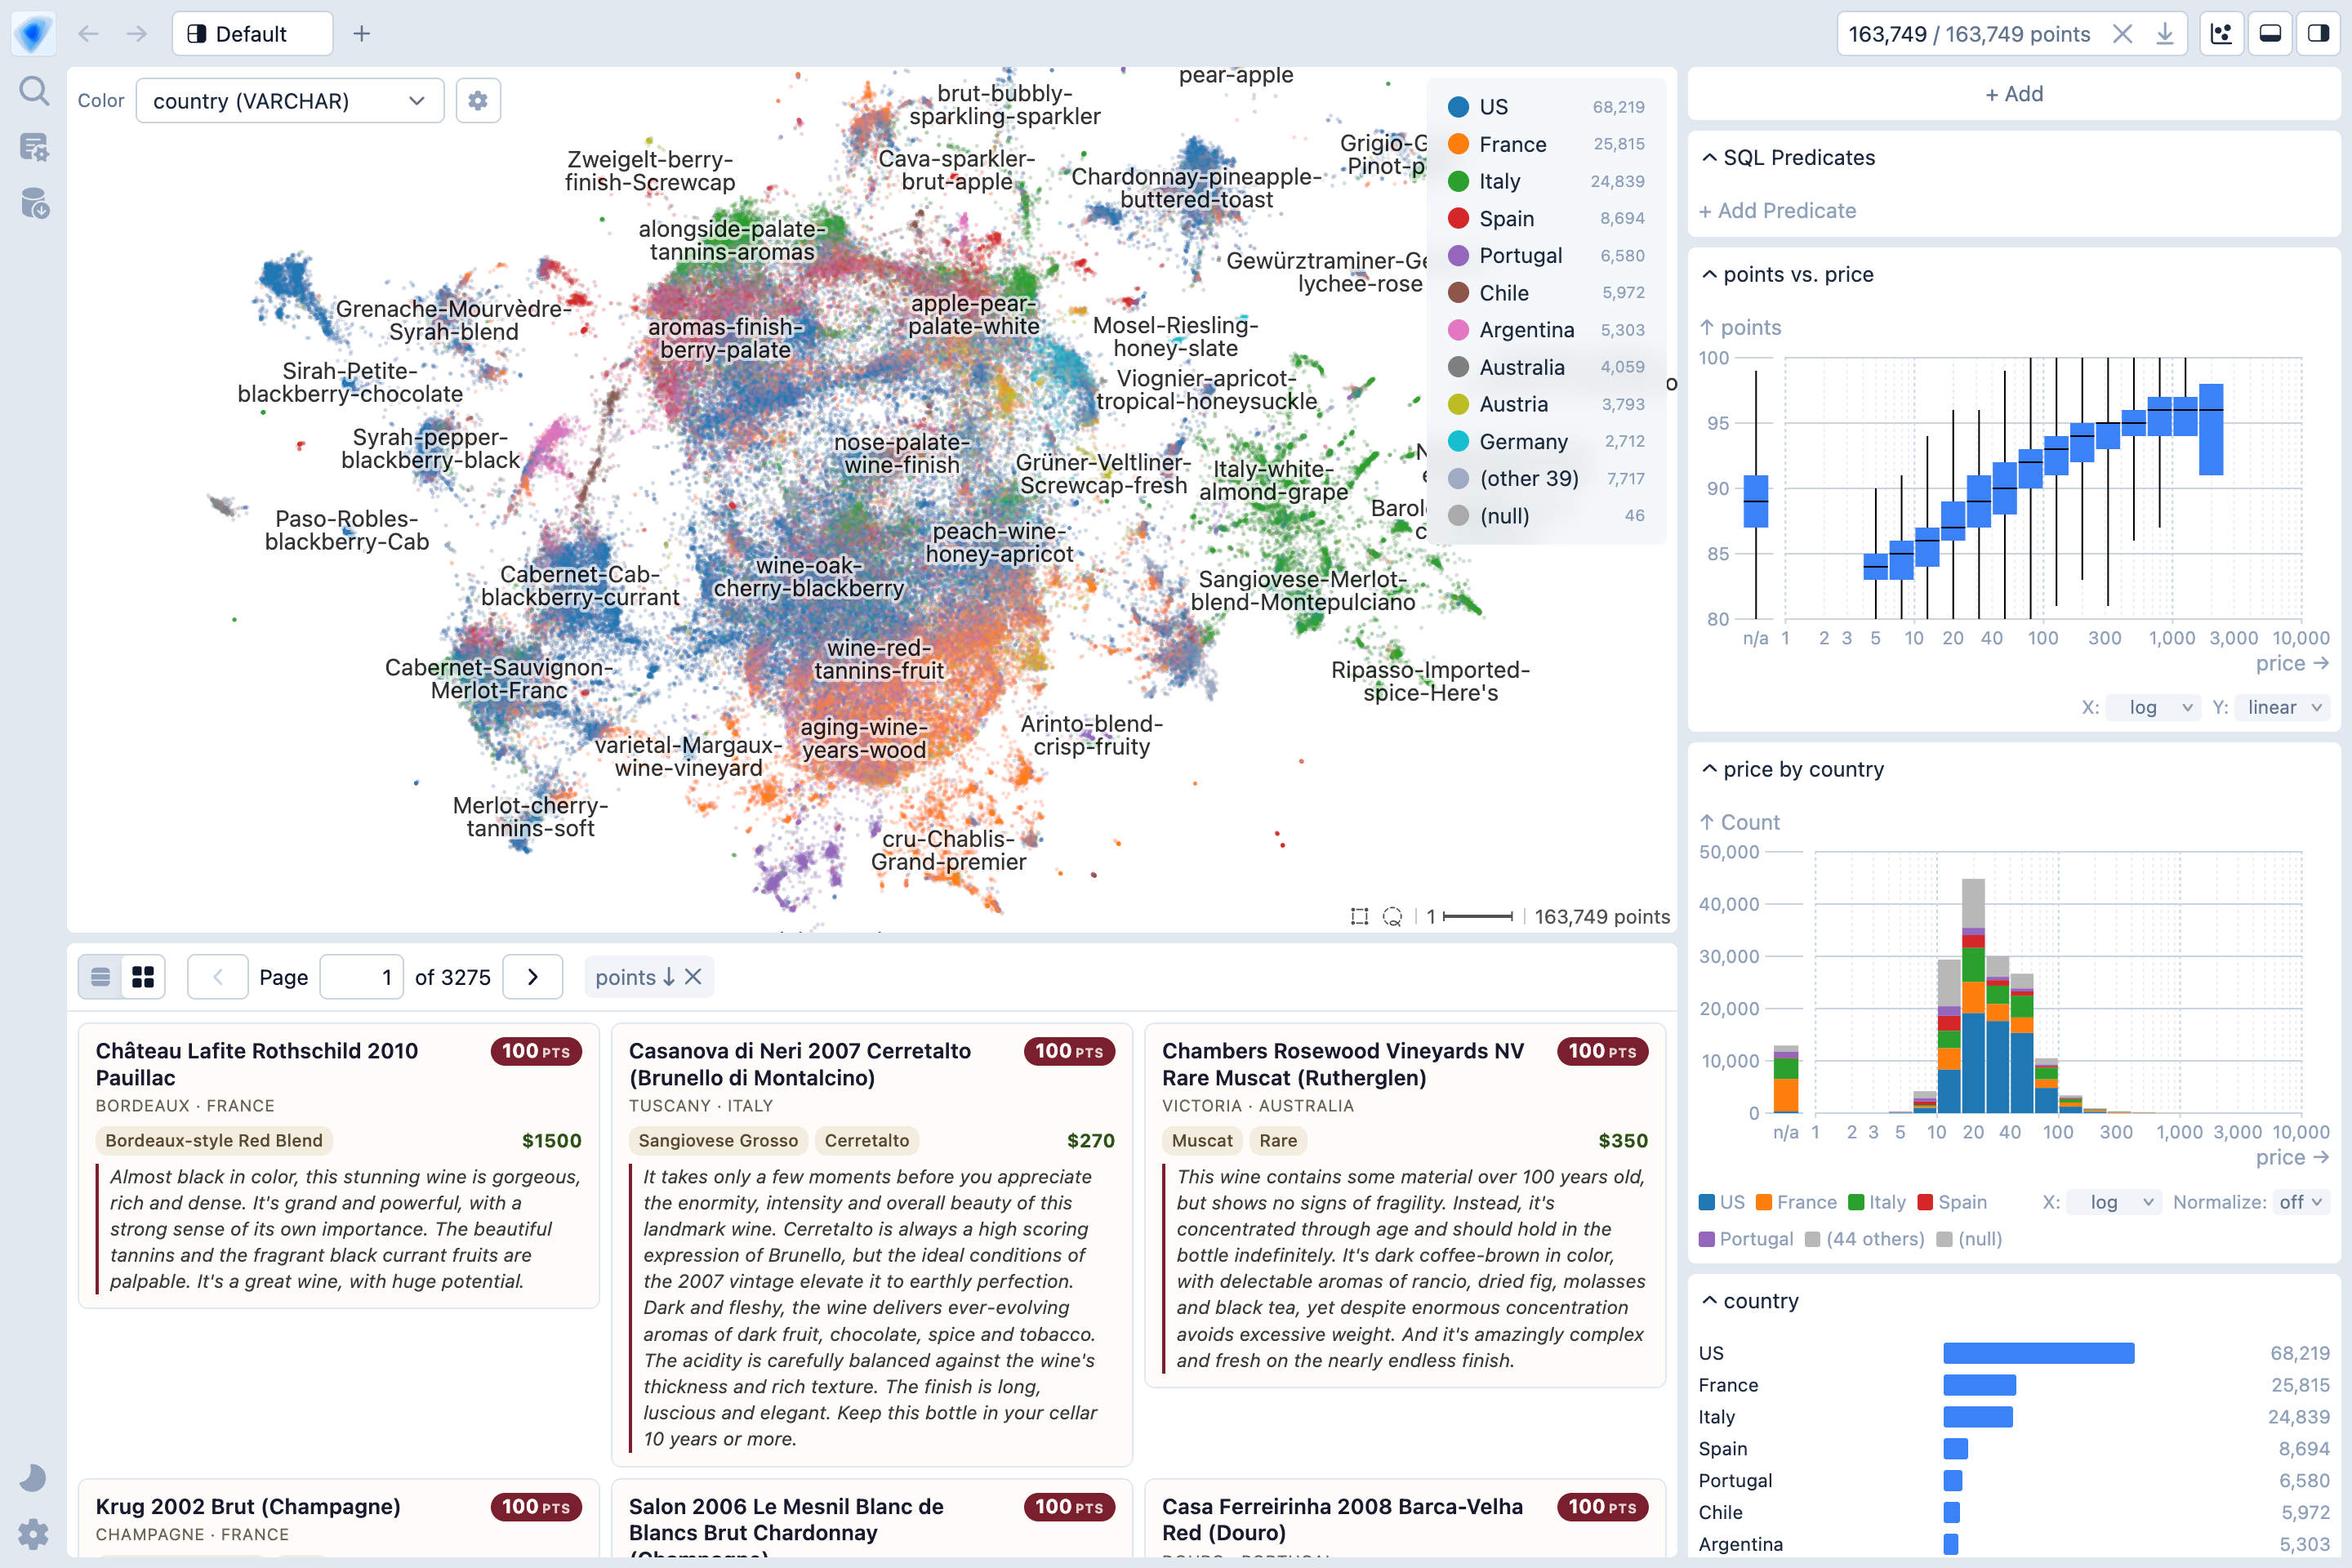
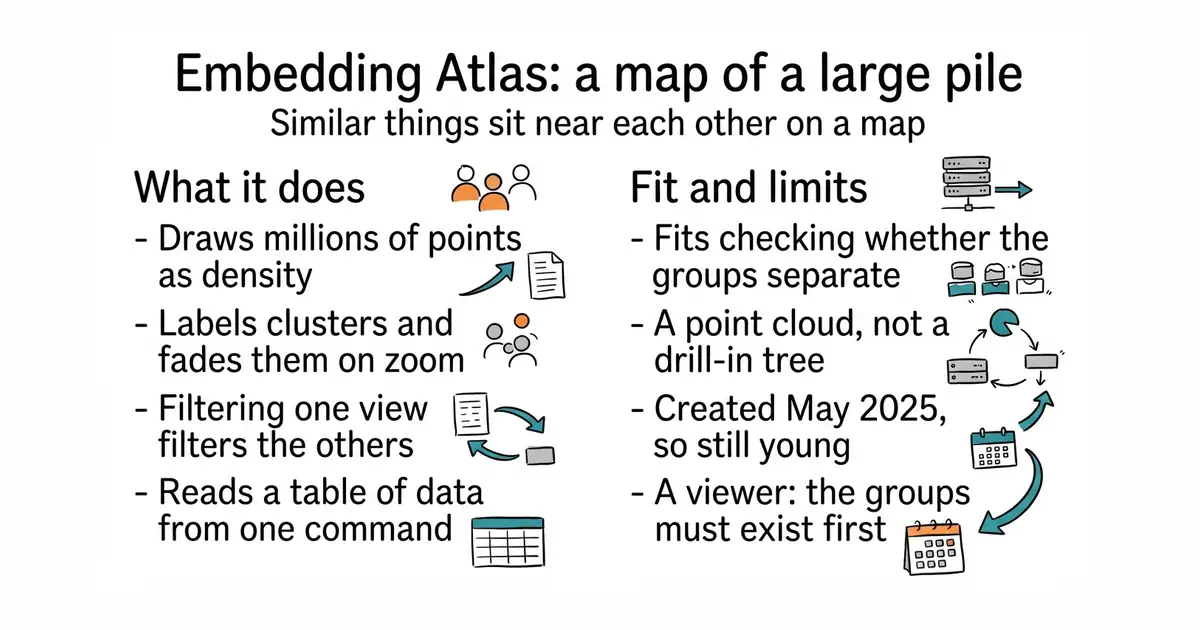
It shows a large set of embeddings, which are numeric summaries of meaning, as an interactive map. Millions of points are handled by drawing density rather than individual dots. Clusters are labelled automatically, and the labels fade in and out as the view is zoomed. The map is linked to the data's other columns, so filtering one view filters the others at the same time. It ships as a Python package that reads a dataframe, as a command-line tool, and as web components to embed in a page. Searching for the nearest neighbours of a selected point is built in. It draws a point cloud and not a hierarchy, so there is no tree to drill down through. It is a viewer and not a model, so the embeddings have to exist before it is useful.
Why it matters
Who it suits. Anyone who has produced a large set of embeddings and needs to see whether they separate sensibly before building anything on top of them. It is also the clearest available reference for the hardest question in any map-style interface: what the first zoomed-out view should look like. Skip it if the collection is small, where a plain scatter plot is quicker to make and easier to read.
Verdict. Run it once over real data. An afternoon here teaches more about designing an overview screen than a week of sketching, because the interaction decisions are visible and considered: labels that appear and disappear with the zoom, density instead of scattered dots, filtering that keeps the viewer oriented. Treat it as a reference first and a dependency second, since adopting it means embedding a fairly opinionated tool rather than building the view you want. Two cautions. The repository was created in May 2025, so it is young and the component interface can still move. And it does not give a drill-in tree, which is what many map-style products actually need. deepscatter handles even larger point counts, but its licence is non-commercial.
Summary (Key Points)from the README
Key features
- Automatic clustering and labels: Clusters and labels the embedding view so you can navigate the overall structure of the data.
- Density views: Kernel density estimation and density contours separate dense regions from outliers.
- Order-independent transparency: Overlapping points render clearly and accurately.
- Search and nearest neighbors: Finds data similar to a text query or to an existing data point in real time.
- Scale: Performance stays smooth up to a few million points, powered by WebGPU.
- Linked dashboards: Bar, line, bubble, count plot and eCDF charts, plus a composable chart spec for custom charts such as heatmaps and average-line overlays. Charts can be set to cross-filter.
- Multimodal viewers: Built-in viewers for text, image, audio, numeric, categorical and time columns.
- AI agent access: Through the Model Context Protocol, agents can query the schema, run SQL, create charts and capture screenshots.
Ways to install
| Platform or method | What it needs | Effort |
|---|---|---|
| Python command line tool | Python | Not stated in README |
| Python notebook widget (e.g., Jupyter) | Python notebook environment | Not stated in README |
| npm package (components) | npm | Not stated in README |
Important
- Browser support: The README says performance is powered by WebGPU but does not list which browsers or versions support it.
- Scale limit: The smooth performance claim is stated only up to a few million points.
- Missing details: The README does not give system requirements, supported platforms or installation steps beyond the names of the three methods.
Written by an AI model from the project’s README; not part of the review, and it can be wrong.
- MIT, with unusually considered interaction design for an open-source visualisation
- Point it at a dataframe and it renders, so the evaluation really does cost one afternoon
- Handles very large point counts smoothly, which is where naive canvases fail
- It draws a point cloud, not a hierarchy, so there is no drill-in tree
- Adopting it means embedding an opinionated tool rather than building the view you want
- Young: created in May 2025, and the component interface can still change
Apple's machine-learning group spent real design effort on precisely that: labels that fade in and out as you zoom, density instead of scattered dots, filtering that keeps you oriented rather than lost.
python3 -m venv venv
source venv/bin/activate
pip install embedding-atlas