102 stars · MIT · release-0.5.4 (2026-09-04) · Track this in Rising ↗
Names clusters at every level of a hierarchy using sub-cluster structure and sample documents rather than a bag of keywords.
Radar check
What we found when we opened it. Every bar is one fact, with its date.
Last code pushed 22 Oct 2026, 5 days before this check.
Latest release release-0.5.4 on 4 Sep 2026.
Public since May 2024, a little over 2 years.
107 stars and 29 forks.
61 commits and 11 new issues in the last 90 days.
24 contributors. 25 pull requests merged in 90 days.
No security policy file says how to report a problem. No published security advisories.
How the bars are scored
- Alive. Days since the last code push: a week or less 100, a month 90, three months 70, six months 50, a year 30, eighteen months 15, older 0.
- Releases. Age of the latest GitHub release, on a similar scale; no bar when the project publishes no releases.
- Maturity. Age of the project: eight years 100, five 90, three 70, two 55, one 40, six months 25, younger 10.
- Adoption. Stars on a log scale: 100,000 stars is 100, 10,000 is 80, 1,000 is 60, 100 is 40.
- Activity. Commits in the last 90 days: 300 or more 100, 100 85, 30 65, 10 45, any 25.
- Community. People who have contributed: 100 or more 100, 30 80, 10 60, 5 40, 2 25, one 10.
- Security. A published security policy 80, none 40; published advisories are listed, not scored.
Checked by Repo Radar on 25 Oct 2026 from the repository on GitHub. Covered in Edition 6.
▶Repo detailsthe review · specs · pros & cons · install
What it does
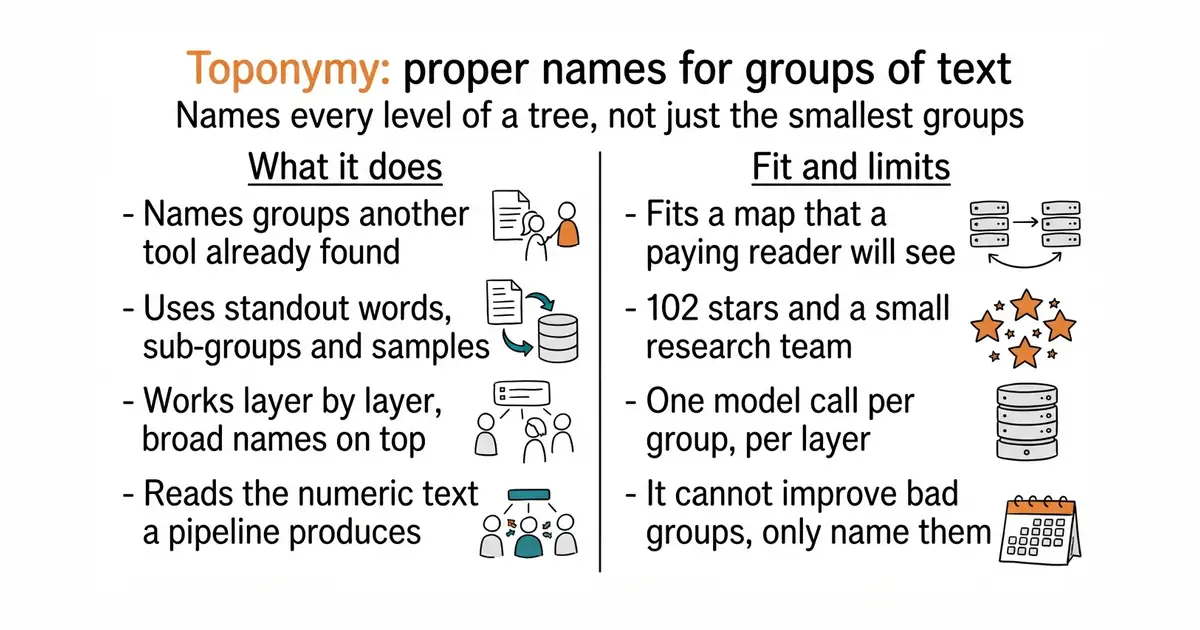
It takes groups of text that another tool has already found and produces a name for each one. It builds each name from evidence: the words that stand out in the group, the smaller groups inside it, and a sample of the actual documents. It does this layer by layer, so a parent name is broader than its children's names, which is what keeps a tree meaningful as a reader zooms in. It reads the numeric representations of text that a normal pipeline already produces. It comes from the Tutte Institute, the group that wrote the two algorithms most clustering tools are built on. The licence is MIT; the newest release is 0.5.4, from 4 September 2026, with code changed later that month. What it does not do is find the groups or improve them: bad groups get accurate names for bad groups.
Why it matters
Who it suits. Anyone shipping a map of a conversation or a document collection to a paying reader. Default names made of keywords, such as model, prompt, token, api, read as machine output and undo the value of the map. It also suits anyone who has tried to write these names by prompting a model directly and found that the parent name comes out no broader than its children. Skip it if the groups are never shown to anyone and only feed another program.
Verdict. Worth an afternoon, and it is the smallest change on this page that a reader would notice. Two honest cautions. It has 102 stars and a small research team behind it, so treat it as a technique that could be rewritten if it stops, not a dependency to build a business on. And it calls a model once per group per layer, so a deep tree has a real cost on every import, which is another reason for a spending limit in front of it. MaartenGr/KeyBERT is the cheap fallback that gives keywords rather than names.
Summary (Key Points)from the README
Key features
- Multi-scale naming: Produces names from broad themes down to fine-grained topics across hierarchical cluster layers.
- Hierarchical clustering: Uses ToponymyClusterer to build a balanced, layered clustering of the documents.
- Multiple LLM backends: Supports Cohere, OpenAI, and Anthropic through service calls, plus local models via Huggingface and LlamaCpp.
- Connectivity check: The test_llm_connectivity() method verifies the LLM connection before a run.
- Worked example: Clusters the 20-Newsgroups dataset of 18,170 documents, with precomputed 768-dimensional vectors and 2-dimensional map coordinates.
- Labeled outputs: Returns topic_names per layer and topics_per_document, with a topic label for each document at each layer. Documents outside a cluster are labeled Unlabelled.
- Interactive maps: Recommends DataMapPlot to explore the document map and topic names across all layers.
- Unified verbosity: A single verbose parameter controls progress bars and messages, replacing the older verbose and show_progress_bar parameters.
Ways to install
| Platform or method | What it needs | Effort |
|---|---|---|
| Basic installation (package install command) | Not stated in the README | Not stated |
| Install latest version from source | Cloning the repository, then running the install command from it | Not stated |
Important
- Beta status: The README says this is a beta version and that things can and will break.
- LLM access: Naming requires an LLM. The OpenAI example needs a key stored in openai_key.txt and the openai package installed.
- Embedding model: An embedding model is required to pick the documents most relevant to each cluster. It does not have to match the one used for the documents, but it should be similar.
- Compute cost: Computing your own document vectors can be very expensive without a GPU, so the README recommends downloading the precomputed vectors.
- Device choice: Encoding speed depends on the device setting, which can be "cuda", "mps", "npu" or "cpu".
- Deprecated parameters: The legacy verbose and show_progress_bar parameters still work but show deprecation warnings.
Written by an AI model from the project’s README; not part of the review, and it can be wrong.
- Built for the exact problem of naming a tree at several levels, which is the shape of a drill-in map.
- MIT, and it reads the numeric text representations an existing pipeline already produces.
- From the group behind the two algorithms most clustering tools rely on.
- 102 stars and a small research team, so it is a technique rather than a safe dependency.
- A model call per group per layer, so a deep tree costs real money on every import.
- It names groups and cannot improve them; the quality of the groups still decides everything.
Clustering gives you groups; the label on the group is what makes it a map instead of a blob diagram.
source venv/bin/activate
pip install toponymy