In simple English
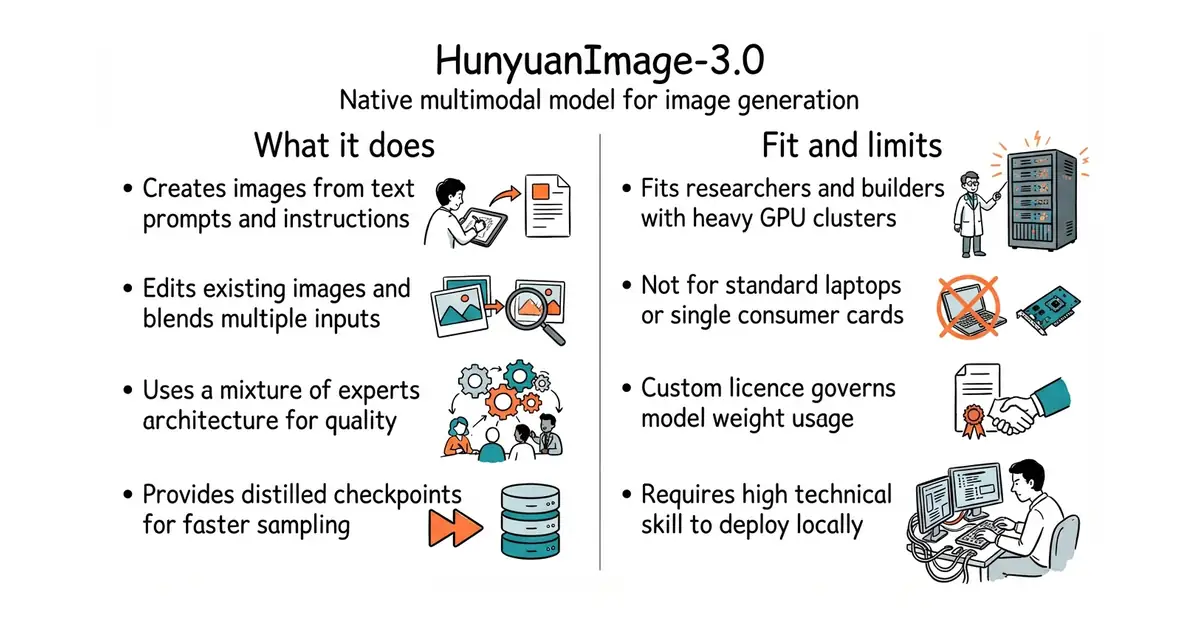
This is an artificial intelligence model that creates and edits images from text descriptions. You write a prompt, and the system generates a high-resolution picture. It can also take existing photos and modify them based on your instructions. Running it yourself requires powerful server hardware with multiple high-end graphics cards. The model files are free to download, but the computing cost to run them locally is very high.
What it is
HunyuanImage-3.0 is an 80-billion-parameter multimodal mixture-of-experts model created by Tencent for text-to-image and image-to-image generation. It processes text and images together through an autoregressive framework rather than traditional diffusion transformer layouts.
What it is good for
Solo builders and researchers who want to run a top-tier image generation model on their own infrastructure instead of paying a commercial API provider.
- Generates photorealistic images with strong text adherence and fine-grained details.
- Supports complex image editing, style transfer, and multi-image fusion.
- Offers a distilled checkpoint that cuts required sampling steps down to eight.
- Requires massive hardware resources, needing multiple enterprise-grade graphics cards with at least 80 GB of memory each.
- Initial model loading and kernel compilation with FlashInfer can take up to ten minutes.
- Custom licence terms apply to the model weights rather than standard open source terms.
Midjourney API
vllm
- black-forest-labs/flux26k stars
Another large open-weights image generation model that produces detailed visuals from text descriptions.

- ggml-org/llama.cpp132k stars
A C and C++ library and command-line tool for running language models locally.
- EleutherAI/lm-evaluation-harness14k stars
Runs standard question sets against a language model and reports the scores.
- mudler/LocalAI50k stars
Serves text, vision, speech, image and video models from one self-hosted service that imitates the paid interfaces.
git clone https://github.com/Tencent-Hunyuan/HunyuanImage-3.0.git
cd HunyuanImage-3.0/
pip install torch==2.8.0 torchvision==0.23.0 torchaudio==2.8.0 --index-url https://download.pytorch.org/whl/cu128
pip install -r requirements.txt