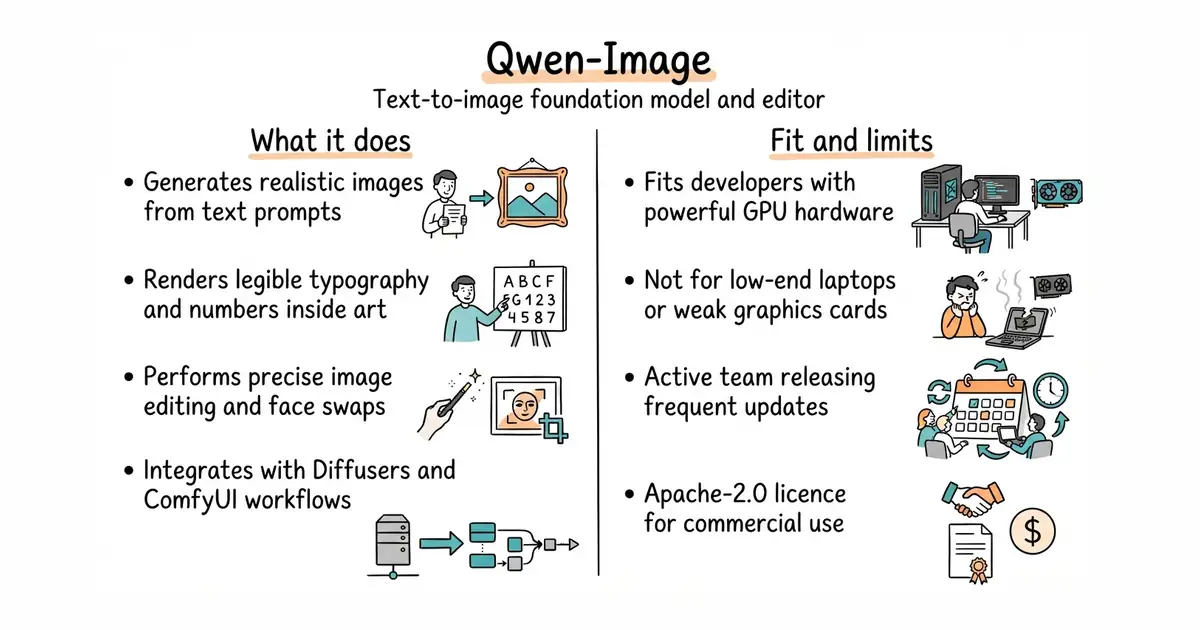
In simple English
This tool creates and edits pictures from text prompts. It writes clear words and numbers inside images better than most other open-source models. You can run it on your own server or use online demos. It needs a powerful computer with a dedicated graphics card to run locally. The project is free to use under an open-source licence.
What it is
Qwen-Image is a family of 20B MMDiT image foundation models for text-to-image generation and precise image editing. It provides Python pipelines and integrates with popular tools like Diffusers and ComfyUI.
What it is good for
Solo builders who need to generate promotional graphics, posters, or UI mockups with correct text in multiple languages without paying for closed-source APIs.
- Excels at rendering legible text, typography, and numbers inside generated images.
- Supports advanced image editing, multi-person consistency, and community LoRAs.
- Permissive Apache-2.0 licence allows commercial use and self-hosting.
- Requires a high-end GPU with substantial VRAM to run locally without offloading.
- Setting up Python environments and matching package versions can be difficult for non-programmers.
- Inference can be slow without optimization libraries like vLLM or DiffSynth.
Midjourney
ComfyUI
- Comfy-Org/ComfyUI141k stars
A node-based graphical interface for running diffusion models like Qwen-Image.


- ggml-org/llama.cpp132k stars
A C and C++ library and command-line tool for running language models locally.
- EleutherAI/lm-evaluation-harness14k stars
Runs standard question sets against a language model and reports the scores.
- mudler/LocalAI50k stars
Serves text, vision, speech, image and video models from one self-hosted service that imitates the paid interfaces.
pip install git+https://github.com/huggingface/diffusers