39.5k stars · MIT · v1.5.7 (2026-09-02) · Track this in Rising ↗
Entity-and-relationship graph over documents with local and global query modes — GraphRAG's structure at a fraction of the cost, stored in PostgreSQL.
Radar check
What we found when we opened it. Every bar is one fact, with its date.
Last code pushed 22 Oct 2026, 5 days before this check.
Latest release v1.5.7 on 2 Sep 2026.
Public since October 2024, about 2 years.
40,312 stars and 5,722 forks.
1,739 commits and 177 new issues in the last 90 days.
353 contributors. 370 pull requests merged in 90 days.
A security policy says how to report a problem. 23 published security advisories.
How the bars are scored
- Alive. Days since the last code push: a week or less 100, a month 90, three months 70, six months 50, a year 30, eighteen months 15, older 0.
- Releases. Age of the latest GitHub release, on a similar scale; no bar when the project publishes no releases.
- Maturity. Age of the project: eight years 100, five 90, three 70, two 55, one 40, six months 25, younger 10.
- Adoption. Stars on a log scale: 100,000 stars is 100, 10,000 is 80, 1,000 is 60, 100 is 40.
- Activity. Commits in the last 90 days: 300 or more 100, 100 85, 30 65, 10 45, any 25.
- Community. People who have contributed: 100 or more 100, 30 80, 10 60, 5 40, 2 25, one 10.
- Security. A published security policy 80, none 40; published advisories are listed, not scored.
Checked by Repo Radar on 25 Oct 2026 from the repository on GitHub. Covered in Edition 6.
▶Repo detailsthe review · specs · pros & cons · install
What it does
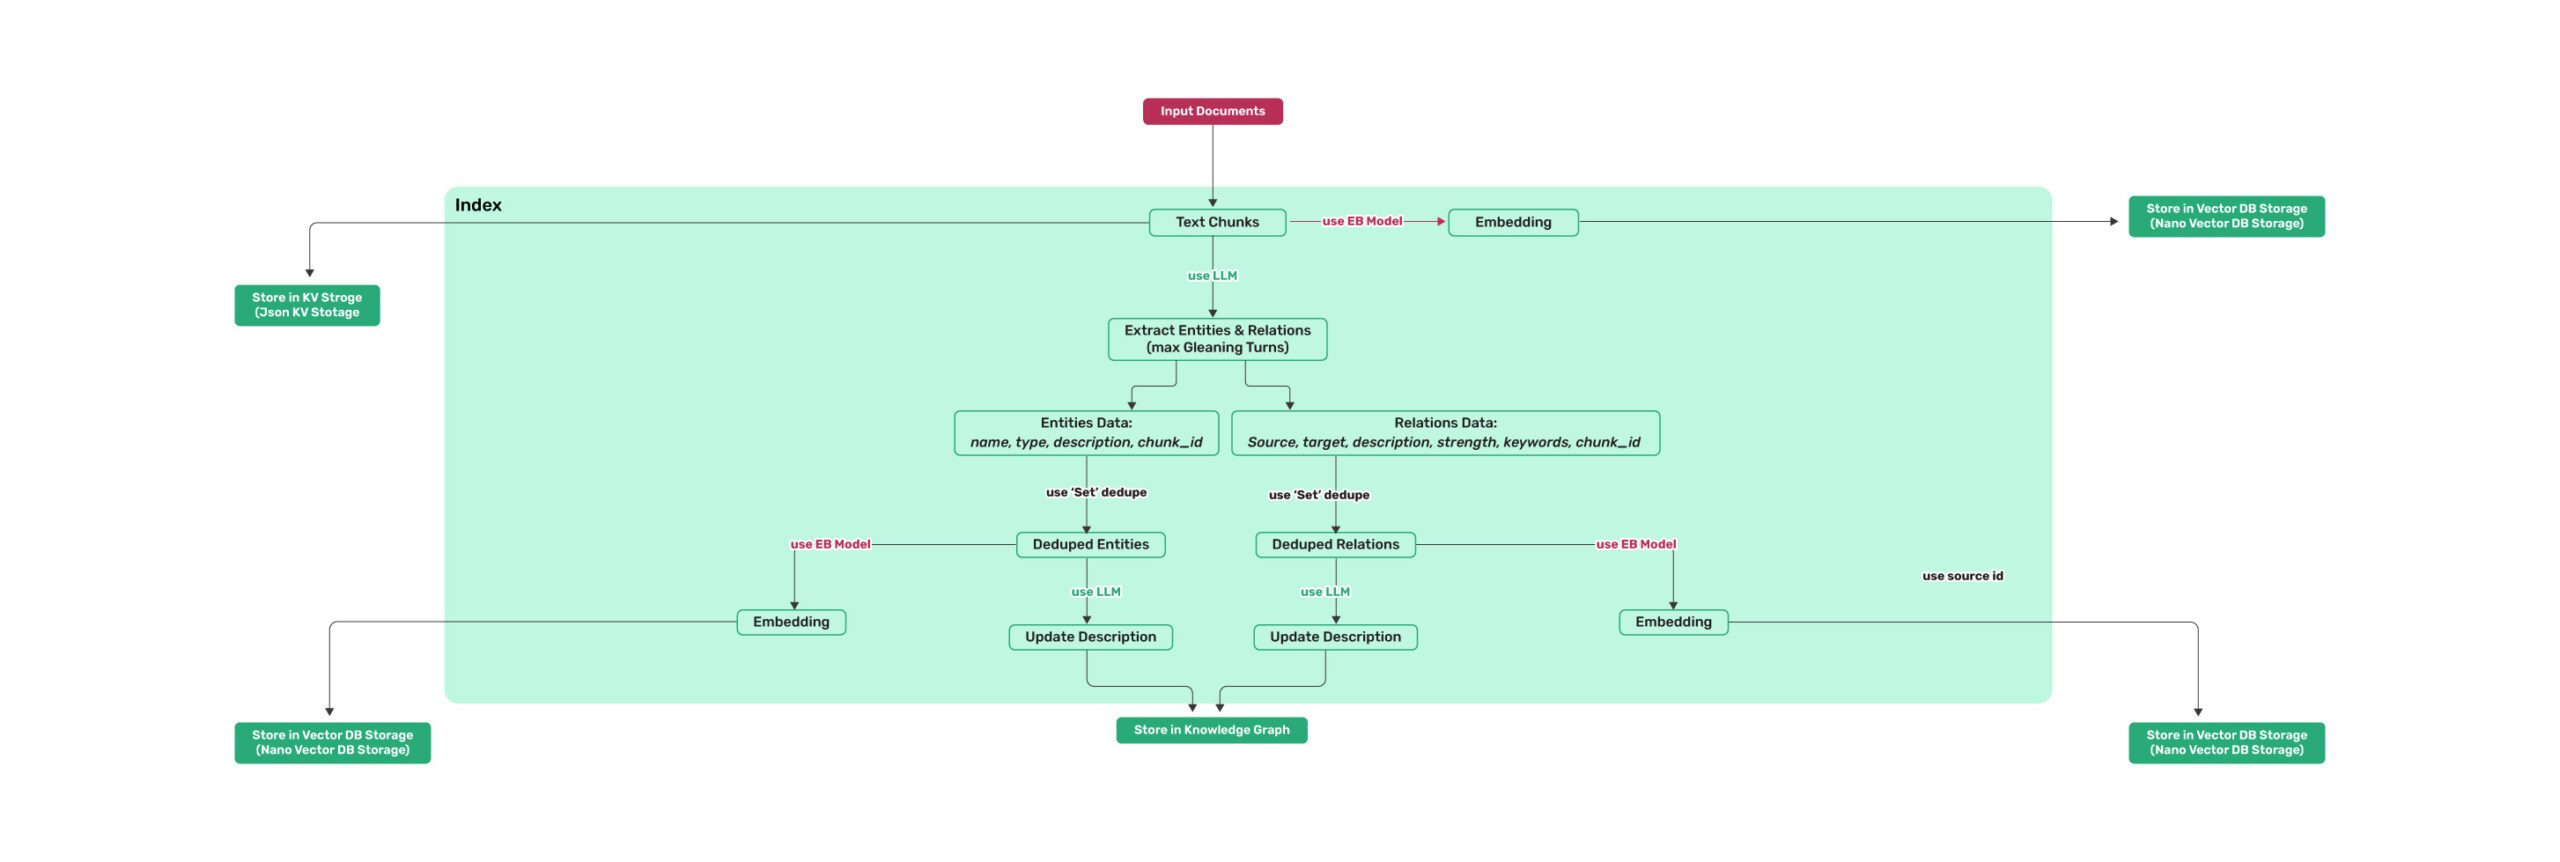
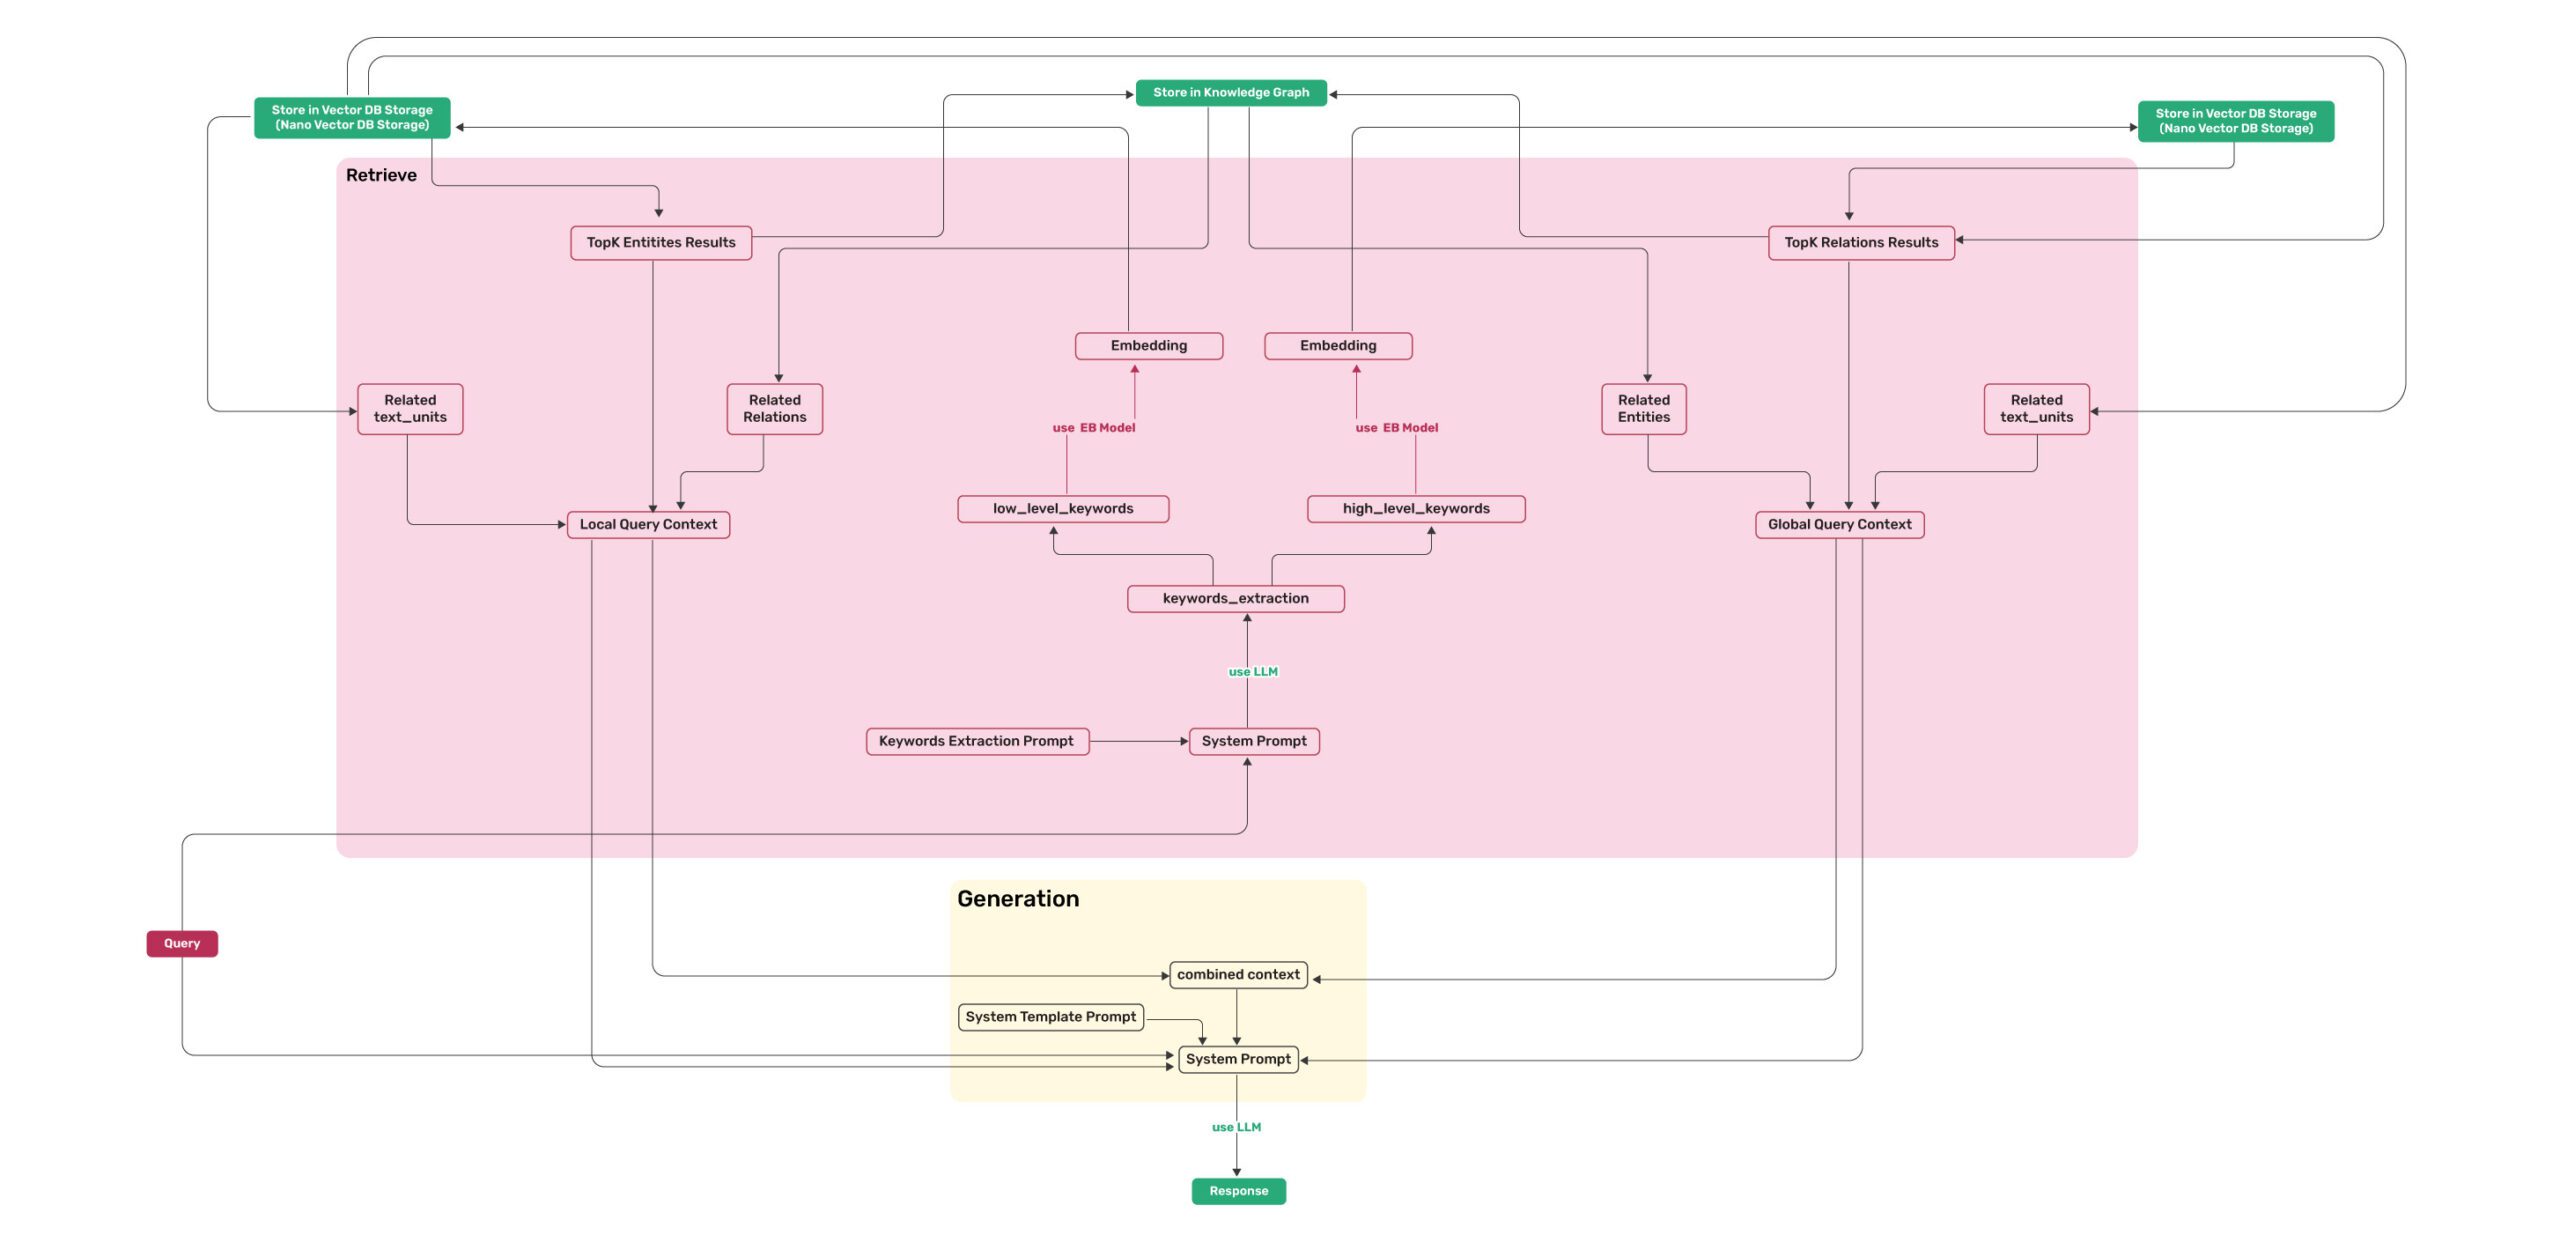
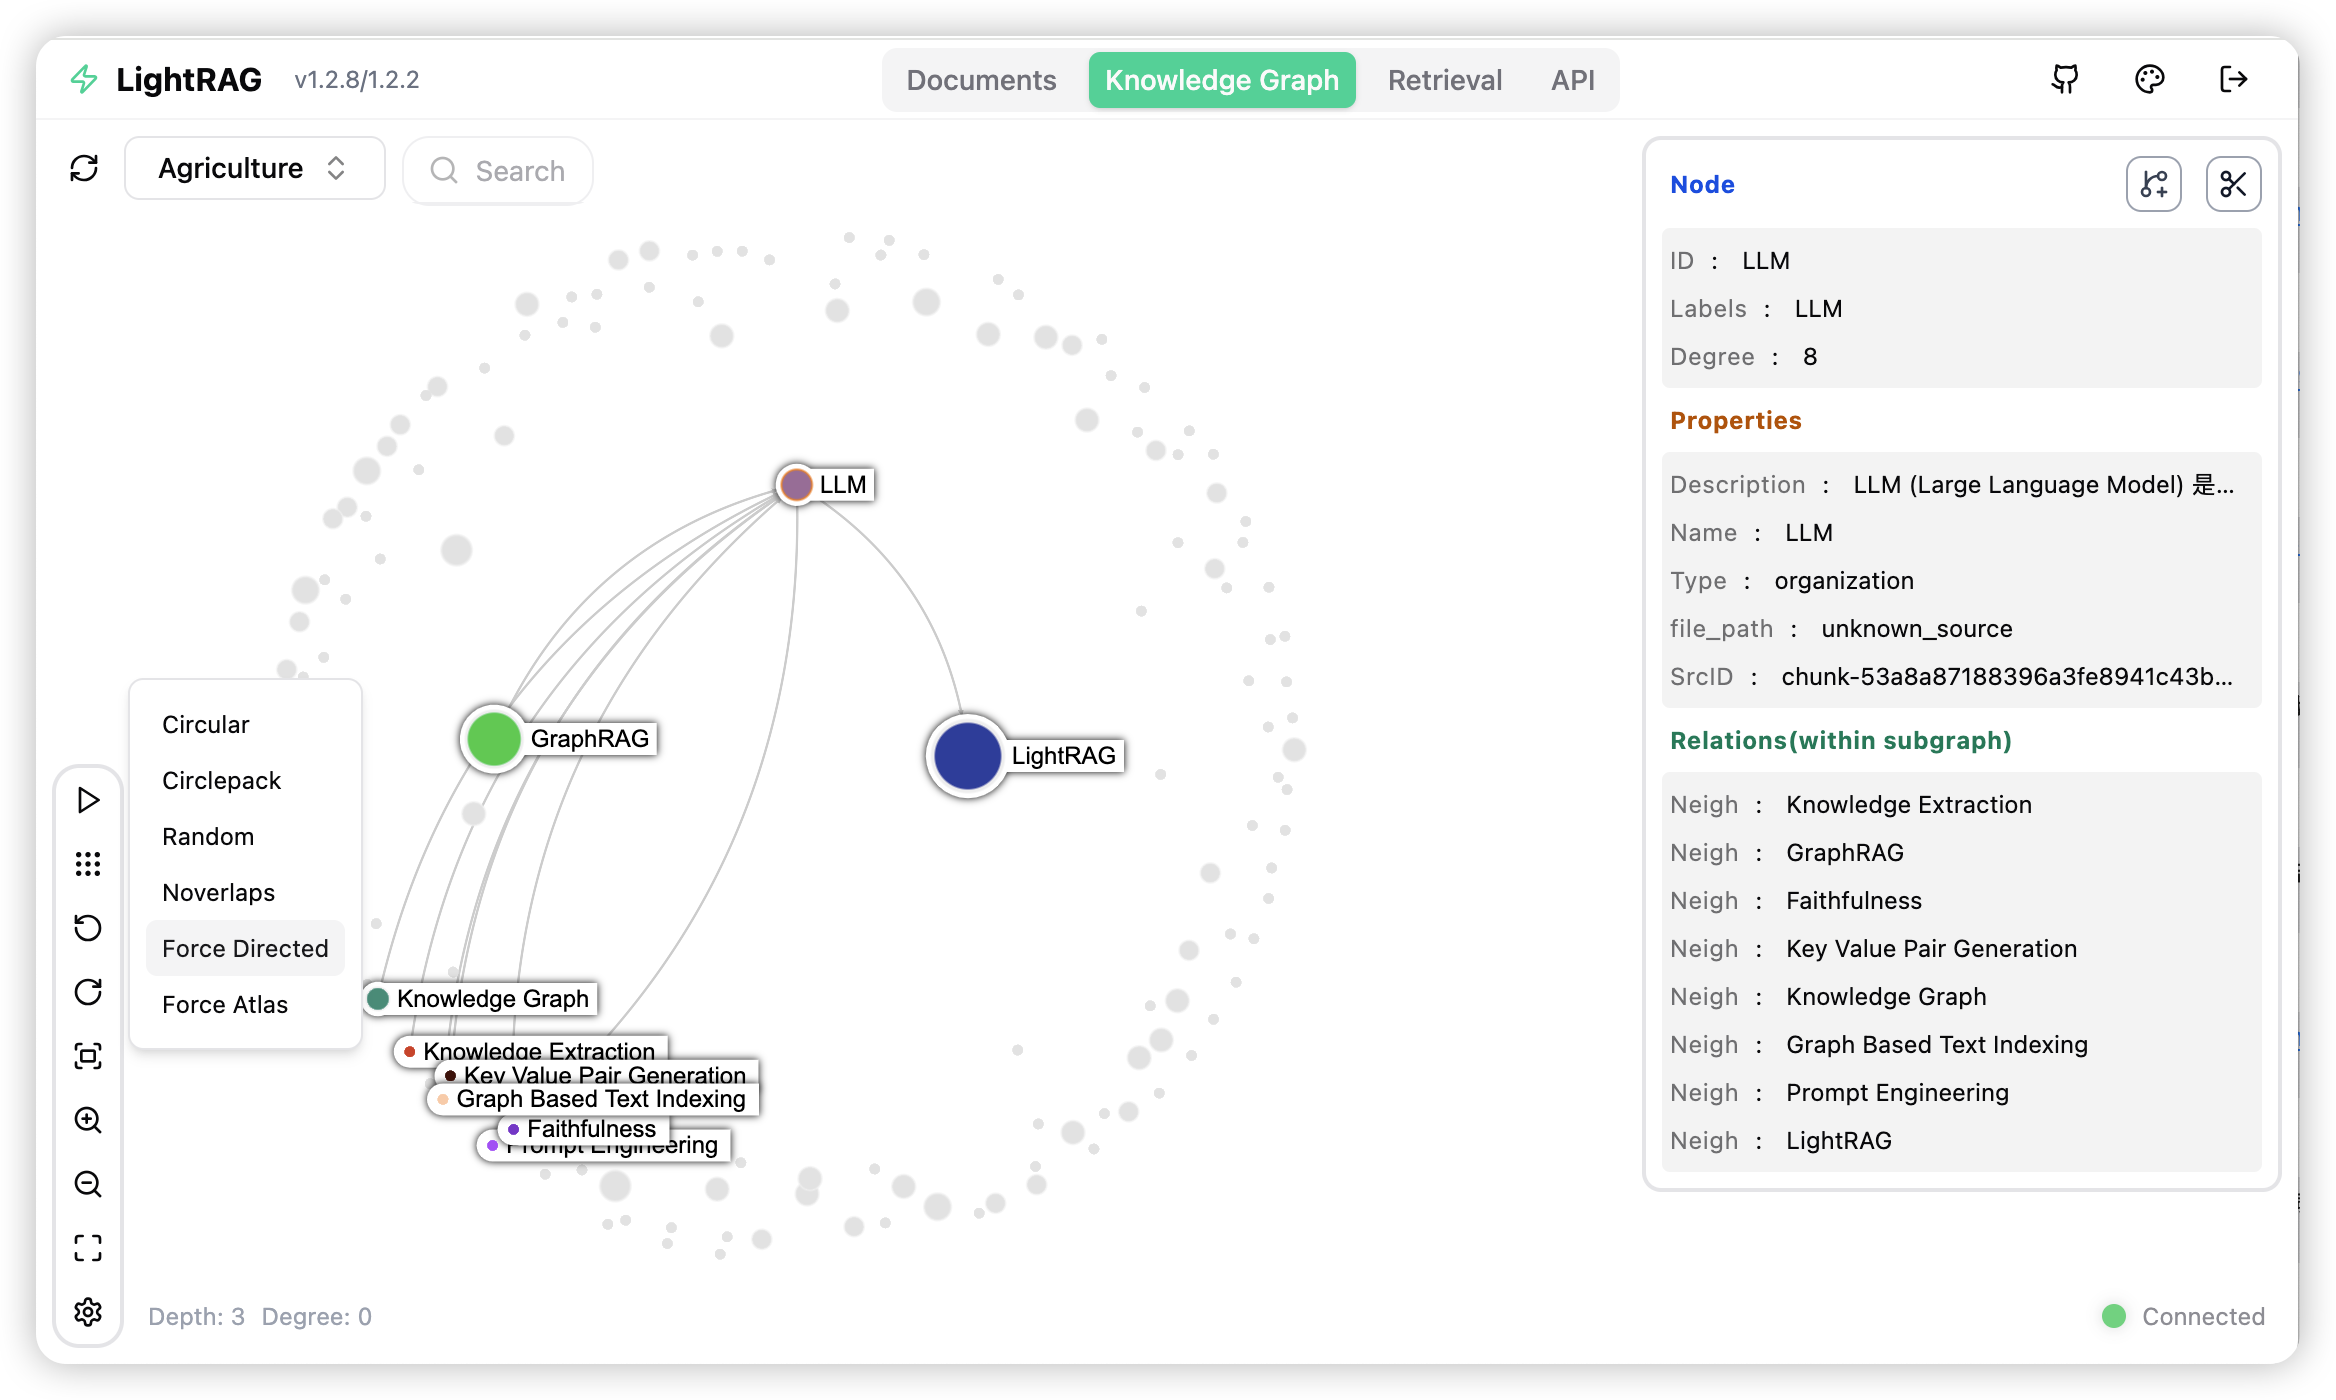
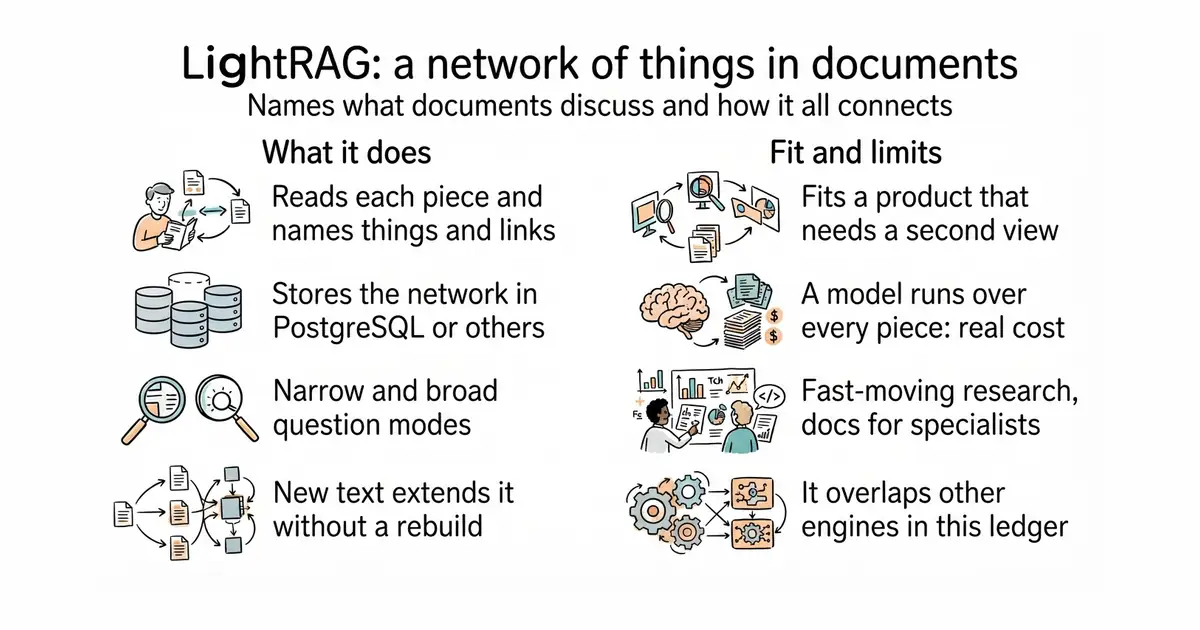
It reads each document in pieces, and for every piece it asks a language model to name the things in it and the links between them. Those names and links are stored as a network, in PostgreSQL, Neo4j, MongoDB or several other stores. Questions can be asked in two ways: narrow, about one named thing, or broad, about themes across everything. New text is added without reprocessing what is already there. It ships a server with a web page that draws the network. The licence is MIT and the newest release is v1.5.7, from 2 September 2026, with code changed later that month. What it does not avoid is cost: a model runs over every piece of every document, so a large first import is expensive.
Why it matters
Who it suits. Products that already search documents and want a second view of them: who and what is discussed, and how it connects, rather than which groups of messages exist. It suits teams who want to stay on one database, because the network can live in PostgreSQL next to everything else instead of in a second system to run and back up. Skip it if the collection is small enough that plain search already answers the questions.
Verdict. Worth a careful week, and worth a cost limit before the first large import rather than after the first bill. Cheaper than the best-known alternative is not the same as cheap. It is a fast-moving research project with a wide reach and documentation that assumes the reader already knows the field. One honest instruction: anyone now holding three candidate engines for the same job should run two of them over the same twenty conversations and delete the loser, because two engines is two things to debug at three in the morning. microsoft/graphrag is the heavier original of this idea.
Summary (Key Points)from the README
Key features
- Dual-layer graph retrieval: Manages both knowledge graphs and vector embeddings, aiming to bridge traditional vector RAG and graph-based RAG.
- Five query modes: local, global, hybrid, naive, and mix. The default is mix.
- Four chunking strategies: Fixed-length (F), Recursive character (R), Vector semantic (V), and Paragraph semantic (P).
- Multiple parsing engines: MinerU, Docling, and Native, which can be extended with third-party parsers. Native handles images, tables, and formulas in Word and Markdown files.
- Multimodal linking: Connects images, formulas, and tables to body text through the knowledge graph, starting with v1.5.
- Role-specific LLMs: Four roles (EXTRACT, QUERY, KEYWORD, VLM) can each use independent model settings.
- Incremental updates: Deleting a document reuses the indexing LLM cache to rebuild affected entities and relations.
- Reported benchmark results: The paper's evaluation shows overall win rates of 60.0% to 84.8% against NaiveRAG across agriculture, CS, legal, and mixed domains.
- Storage choice: Four storage types can be swapped, and PostgreSQL alone can serve all four in production.
- Two WebUI entries: /webui is the admin console and /workspace is a query-only chat interface.
Ways to install
| Platform or method | What it needs | Effort |
|---|---|---|
| Server from PyPI | uv (recommended) or pip | Not stated |
| Server from source | A source checkout and uv or pip | Not stated |
| Server via Docker Compose | Docker; the setup wizard can generate .env and docker-compose.final.yml | Not stated |
| Storage stack on Apple Silicon | Apple's native container runtime, without Docker Desktop | Not stated |
| SDK from PyPI or source | Python; the README recommends the REST API for integration | Not stated |
Important
- In-memory defaults: The default KV, vector, graph, and document-status stores keep the whole dataset in server RAM. The README says they are for small-scale testing only.
- Embedding model lock-in: Vectors must be rebuilt if the embedding model changes. The README points to lightrag-rebuild-vdb for this, and it requires the server to be stopped.
- Rerank latency: Enabling Rerank typically adds 1 to 2 seconds per query.
- Model demands: Entity extraction needs a capable model, and the README recommends a non-thinking extraction model. Models below about 50 tokens per second may time out on dense chunks.
- Optional system dependencies: The spaCy models for smart_heading are not on PyPI and need a separate install. SVG rasterization needs the native libcairo library. The lite Docker image does not include the spaCy models.
- Hosted MinerU limits: The cloud service has usage, file-size, and page-count limits, so the README recommends a local deployment.
- Access control: Hiding the admin UI through /workspace is not a security boundary. Query settings are stored per browser.
- Unsupported SDK samples: Only lightrag_openai_demo.py and lightrag_openai_compatible_demo.py are officially supported. Some SDK-only features may be experimental.
Written by an AI model from the project’s README; not part of the review, and it can be wrong.
- MIT, and it can keep the network in PostgreSQL rather than in a separate database.
- New text extends the network instead of forcing a full rebuild, which is the expensive part.
- Narrow and broad question modes match a drill-in view and a summary view directly.
- A model still runs over every piece of every document, so the first large import costs real money.
- A fast-moving research project with a wide reach and documentation written for specialists.
- It overlaps other tools in this ledger that do a similar job, and keeping two is a burden.
And its incremental insertion means adding new messages extends the graph instead of triggering a rebuild, which is what makes "map this conversation as it grows" a feature rather than a wish.
The PostgreSQL backend is the practical detail: the graph can live beside pgvector rather than in a Neo4j you would have to run, secure and back up separately.
source venv/bin/activate
pip install "lightrag-hku"