In simple English
ContextGem is a Python library that pulls specific facts, tables, and answers out of documents. You describe what you want in plain language instead of writing complicated instructions. The tool reads your file, extracts the data, and shows you the exact page or sentence where each fact came from. It helps you build automated pipelines that process contracts, reports, and forms without missing details. The project is free and open-source under the Apache 2.0 licence.
What it is
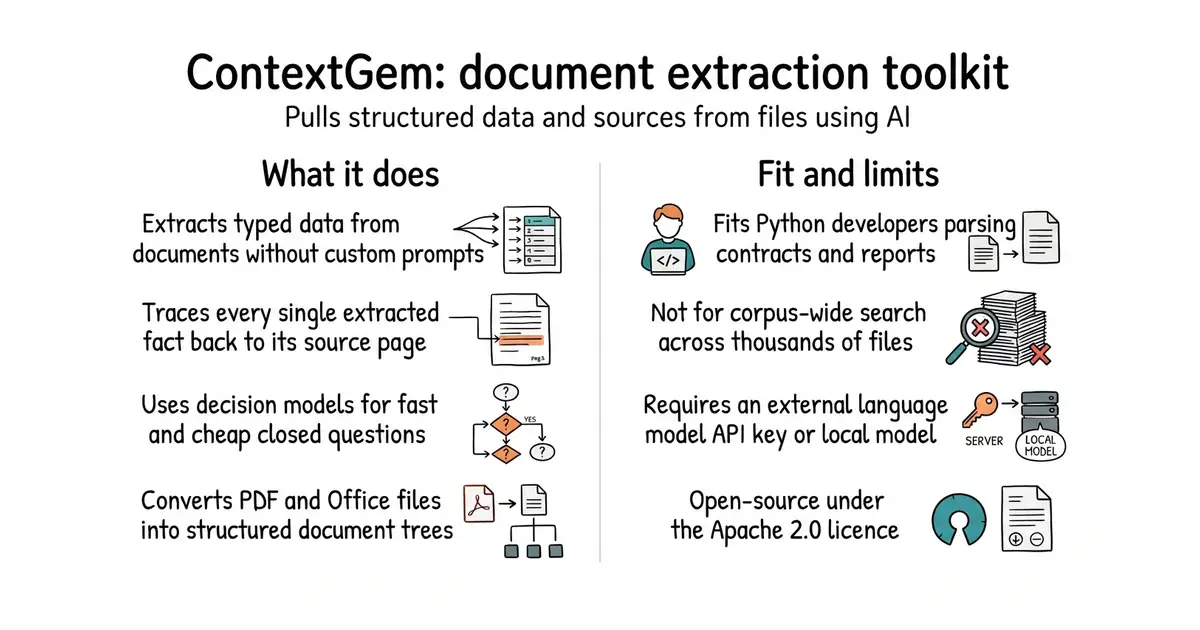
ContextGem is a Python framework for structured data extraction that combines large language models (a type of AI trained on vast amounts of text to understand and generate human language) with decision models to parse documents. It maps extracted items back to their source paragraphs and supports file conversion through Docling (a tool that turns PDFs and Office documents into structured text).
What it is good for
This is useful for solo builders who need to pull exact data from messy files like PDFs, Word documents, or spreadsheets without writing custom prompt templates for every single file type.
- Generates prompts automatically from plain-language descriptions of what you need.
- Traces every extracted fact back to the exact paragraph, sentence, or page number in the source file.
- Supports decision models that return fast, low-cost probabilities for yes-or-no questions and categories.
- Requires Python programming knowledge and an API key for a language model or decision model.
- Processes documents paragraph by paragraph, so it cannot search across a massive corpus like a traditional search index.
- Relies on third-party AI models whose costs and response times can vary.
Writing custom regular expressions and prompt templates for every document type.
Docling
- pydantic/pydantic-ai21k stars
Builds structured outputs from language models using Python types, but focuses on general agent workflows rather than in-depth document parsing.
- stanfordnlp/dspy39k stars
Optimizes prompts and weights for language model pipelines programmatically instead of using declarative document schemas.


- deepset-ai/haystack27k stars
A Python framework for joining language models, document search and tools into one working pipeline.
- Giskard-AI/giskard-oss5.9k stars
A Python library that writes tests for language-model programs and tries to break them on purpose.
- ggml-org/llama.cpp132k stars
A C and C++ library and command-line tool for running language models locally.
pip install contextgem
pip install "contextgem[docling]"