In simple English
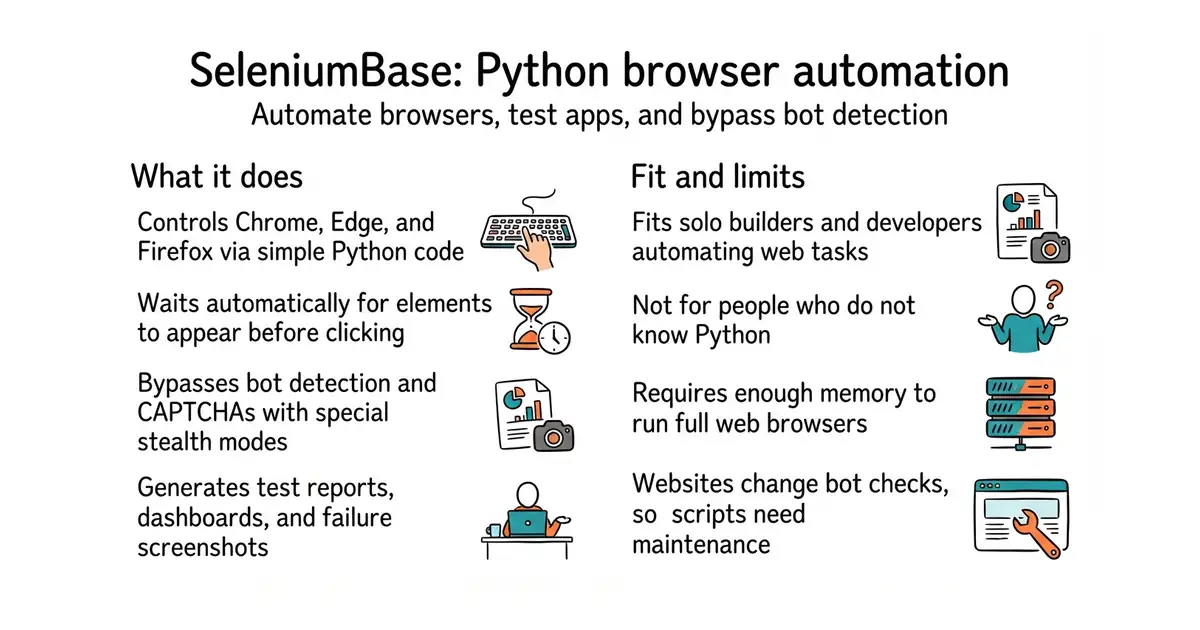
This tool lets you write short Python scripts to control web browsers automatically. It handles the boring parts of browser testing, like waiting for pages to load and taking screenshots when tests fail. It includes special anti-detection modes that help your scripts bypass bot blockers and CAPTCHAs on websites. You can use it to test your own web apps or to collect data from public sites. It is free to use and runs on your own computer or server.
What it is
SeleniumBase is an all-in-one Python framework built on top of standard browser automation tools. It combines test runners, automatic driver management, and stealth features into a single library.
What it is good for
Solo builders who need to write end-to-end tests for their web apps or scrape data from websites that block standard scrapers.
- Handles automatic waiting so your tests do not fail randomly when pages load slowly.
- Includes stealth modes that bypass common bot detection and CAPTCHAs.
- Provides built-in dashboards, report generation, and screenshot capture for failed tests.
- Requires comfort with Python programming and the command line.
- Running many browser instances at once consumes significant RAM and CPU.
- Websites frequently update their anti-bot measures, requiring regular updates to your scripts.
Raw Selenium scripts and manual browser testing
pytest
- microsoft/playwright-python15k stars
Microsoft's modern browser automation library, offering similar multi-browser support and fast execution.
- puppeteer/puppeteer96k stars
Node.js library for controlling Chrome and Firefox, popular for similar scraping and testing tasks.


- PrefectHQ/prefect24k stars
Adds scheduling, retries and a run history to Python functions you already have.
- alirezamika/autoscraper8.1k stars
A Python scraper that learns what to extract from one example you give it.
pip install seleniumbase
sbase get chromedriver stable