35.9k stars · MIT · v3.1.2 (2026-08-21) · Track this in Rising ↗
Builds a knowledge graph from text, clusters it into nested communities, writes a summary for each level.
Radar check
What we found when we opened it. Every bar is one fact, with its date.
Last code pushed 26 Oct 2026, one day before this check.
Latest release v3.3.0 on 8 Oct 2026.
Public since March 2024, a little over 2 years.
36,453 stars and 3,868 forks.
20 commits and 38 new issues in the last 90 days.
51 contributors. 19 pull requests merged in 90 days.
A security policy says how to report a problem. No published security advisories.
How the bars are scored
- Alive. Days since the last code push: a week or less 100, a month 90, three months 70, six months 50, a year 30, eighteen months 15, older 0.
- Releases. Age of the latest GitHub release, on a similar scale; no bar when the project publishes no releases.
- Maturity. Age of the project: eight years 100, five 90, three 70, two 55, one 40, six months 25, younger 10.
- Adoption. Stars on a log scale: 100,000 stars is 100, 10,000 is 80, 1,000 is 60, 100 is 40.
- Activity. Commits in the last 90 days: 300 or more 100, 100 85, 30 65, 10 45, any 25.
- Community. People who have contributed: 100 or more 100, 30 80, 10 60, 5 40, 2 25, one 10.
- Security. A published security policy 80, none 40; published advisories are listed, not scored.
Checked by Repo Radar on 26 Oct 2026 from the repository on GitHub. Covered in Edition 1.
▶Repo detailsthe review · specs · pros & cons · install
What it does
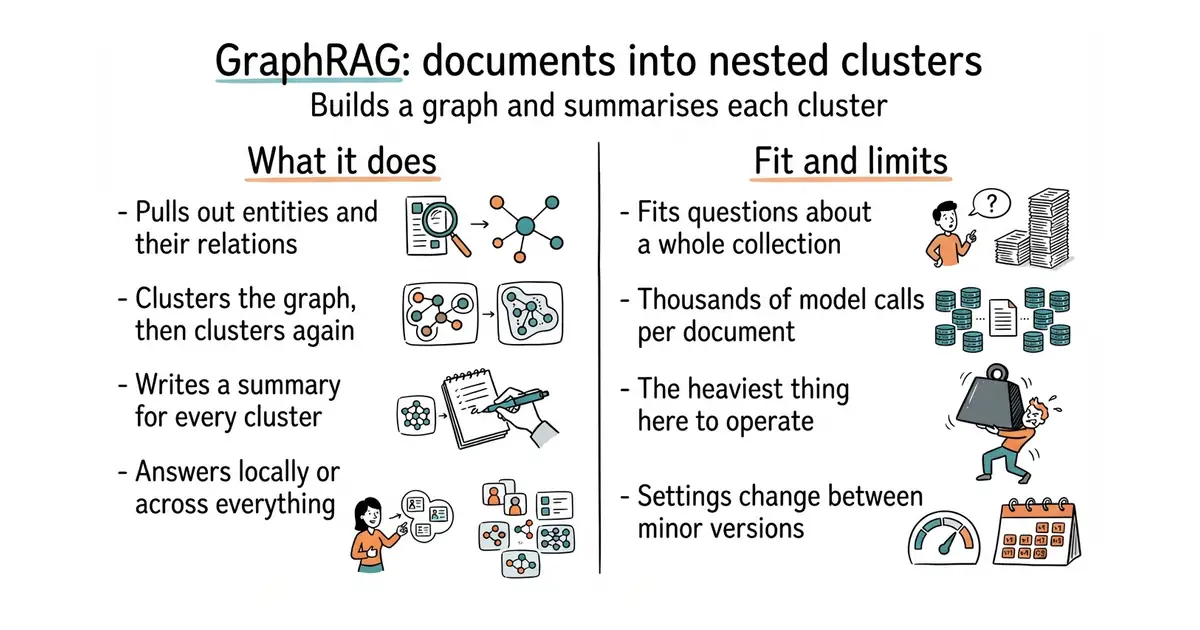
You put text files in a folder and run it. It uses a language model to extract entities and the relationships between them, assembles those into a graph, then clusters the graph into communities and clusters those communities again, producing a hierarchy. For each community at each level it writes a readable summary. Queries then run in one of two ways: a local search that answers from specific entities, or a global search that answers from the top-level summaries and so can address a question about the whole collection. It writes its results as data files you can read directly. What it does not do is come cheap: indexing one long document can mean thousands of calls to a language model, so every import has a real and measurable cost.
Why it matters
Who it suits. Anyone who needs an answer about a whole collection rather than a passage inside it. The question "summarise this entire thread" is the one plain keyword search cannot answer at all, and the global search mode is built for exactly that. It also suits anyone designing a system of this kind, because the cluster-and-summarise step is the clearest published reference for the idea. Skip it for short inputs, because the cost per document does not shrink. Skip it too if operations are not your strength, because this is config files, long-running jobs and data artifacts.
Verdict. Worth studying even if you never run it in production, and the reason is the design rather than the code. The hierarchy of clusters, each with a generated title and summary, is a product specification written out by a research team and given away under a plain MIT licence. At 36,287 stars it is well known, version 3.3.0 landed on 8 October 2026 and code the same day, so it is actively maintained. Three warnings, and they are the real content of this entry. The cost is the headline: indexing is thousands of model calls, and that is money per import, so measure it on one document before pointing it at a thousand. It is operationally the heaviest thing here. And the project warns to run graphrag init --root [path] --force between minor version changes, which tells you the configuration format moves. For something lighter with the same shape, HKUDS/LightRAG is the obvious comparison.
Summary (Key Points)from the README
Key features
- LLM-based data pipeline: Extracts structured data from unstructured text using LLMs, positioned as a data pipeline and transformation suite.
- Knowledge graph memory: Presents a methodology that uses knowledge graph memory structures to enhance LLM outputs.
- Private data reasoning: Aims to help an LLM reason about your own private data, which the README describes as the main use case.
- Command line quickstart: The recommended way to begin is the command line quickstart.
- Prompt tuning guide: The documentation includes a Prompt Tuning Guide, which the README strongly recommends following because default prompts may not give the best results.
- Config and migration support: `graphrag init --root [path] --force` refreshes the config format between minor versions, and a migration notebook is provided for major version bumps.
- Contribution and development docs: CONTRIBUTING.md and DEVELOPING.md cover contributing and development, and GitHub Discussions is open for feedback.
- Responsible AI documentation: RAI_TRANSPARENCY.md includes a Responsible AI FAQ covering intended uses, evaluation, limitations and operational factors.
Important
- Maintenance mode: The project is largely in maintenance mode, will not accept new PRs or implement new features, and will receive only bug fixes, dependency updates and CVE-related fixes.
- Research status: The README calls the project a research project and the code a demonstration that is not an officially supported Microsoft offering.
- Indexing cost: Indexing can be expensive, so the README advises reading all documentation on the process and costs first and starting small.
- Config overwrite: Running `graphrag init --force` overwrites your configuration and prompts, so back them up first.
- Re-indexing risk: Skipping the migration notebook at a major version bump may force you to re-index prior datasets.
- Out-of-box results: Default prompts may not yield the best results on your data, so prompt tuning is strongly recommended.
Written by an AI model from the project’s README; not part of the review, and it can be wrong.
- It produces both the hierarchy and the human-readable summaries in one run.
- The global query mode answers questions about a whole collection, which plain search cannot do at all.
- Plain MIT licence from a research team at a large company, with a release on 8 October 2026.
- Expensive: indexing one long document can mean thousands of language model calls, so every import costs money.
- Operationally the heaviest thing in this edition: configuration files, data artifacts and long-running jobs.
- The configuration format changes between minor versions, and the project tells you to reinitialise when it does.
python3 -m venv venv
source venv/bin/activate
python -m pip install graphrag
graphrag init          # writes the settings files
# put text files in the input folder and add your provider key
graphrag index         # builds the graph and the summaries
graphrag query "What are the main themes in these documents?"