44.9k stars · GPL-3.0 · v3.1.3 (2026-09-04), read from /releases/latest · Track this in Scout
It reads the words on your scans and invoices so you can search them like email.
▶Repo detailsthe review · specs · pros & cons · install
What it is
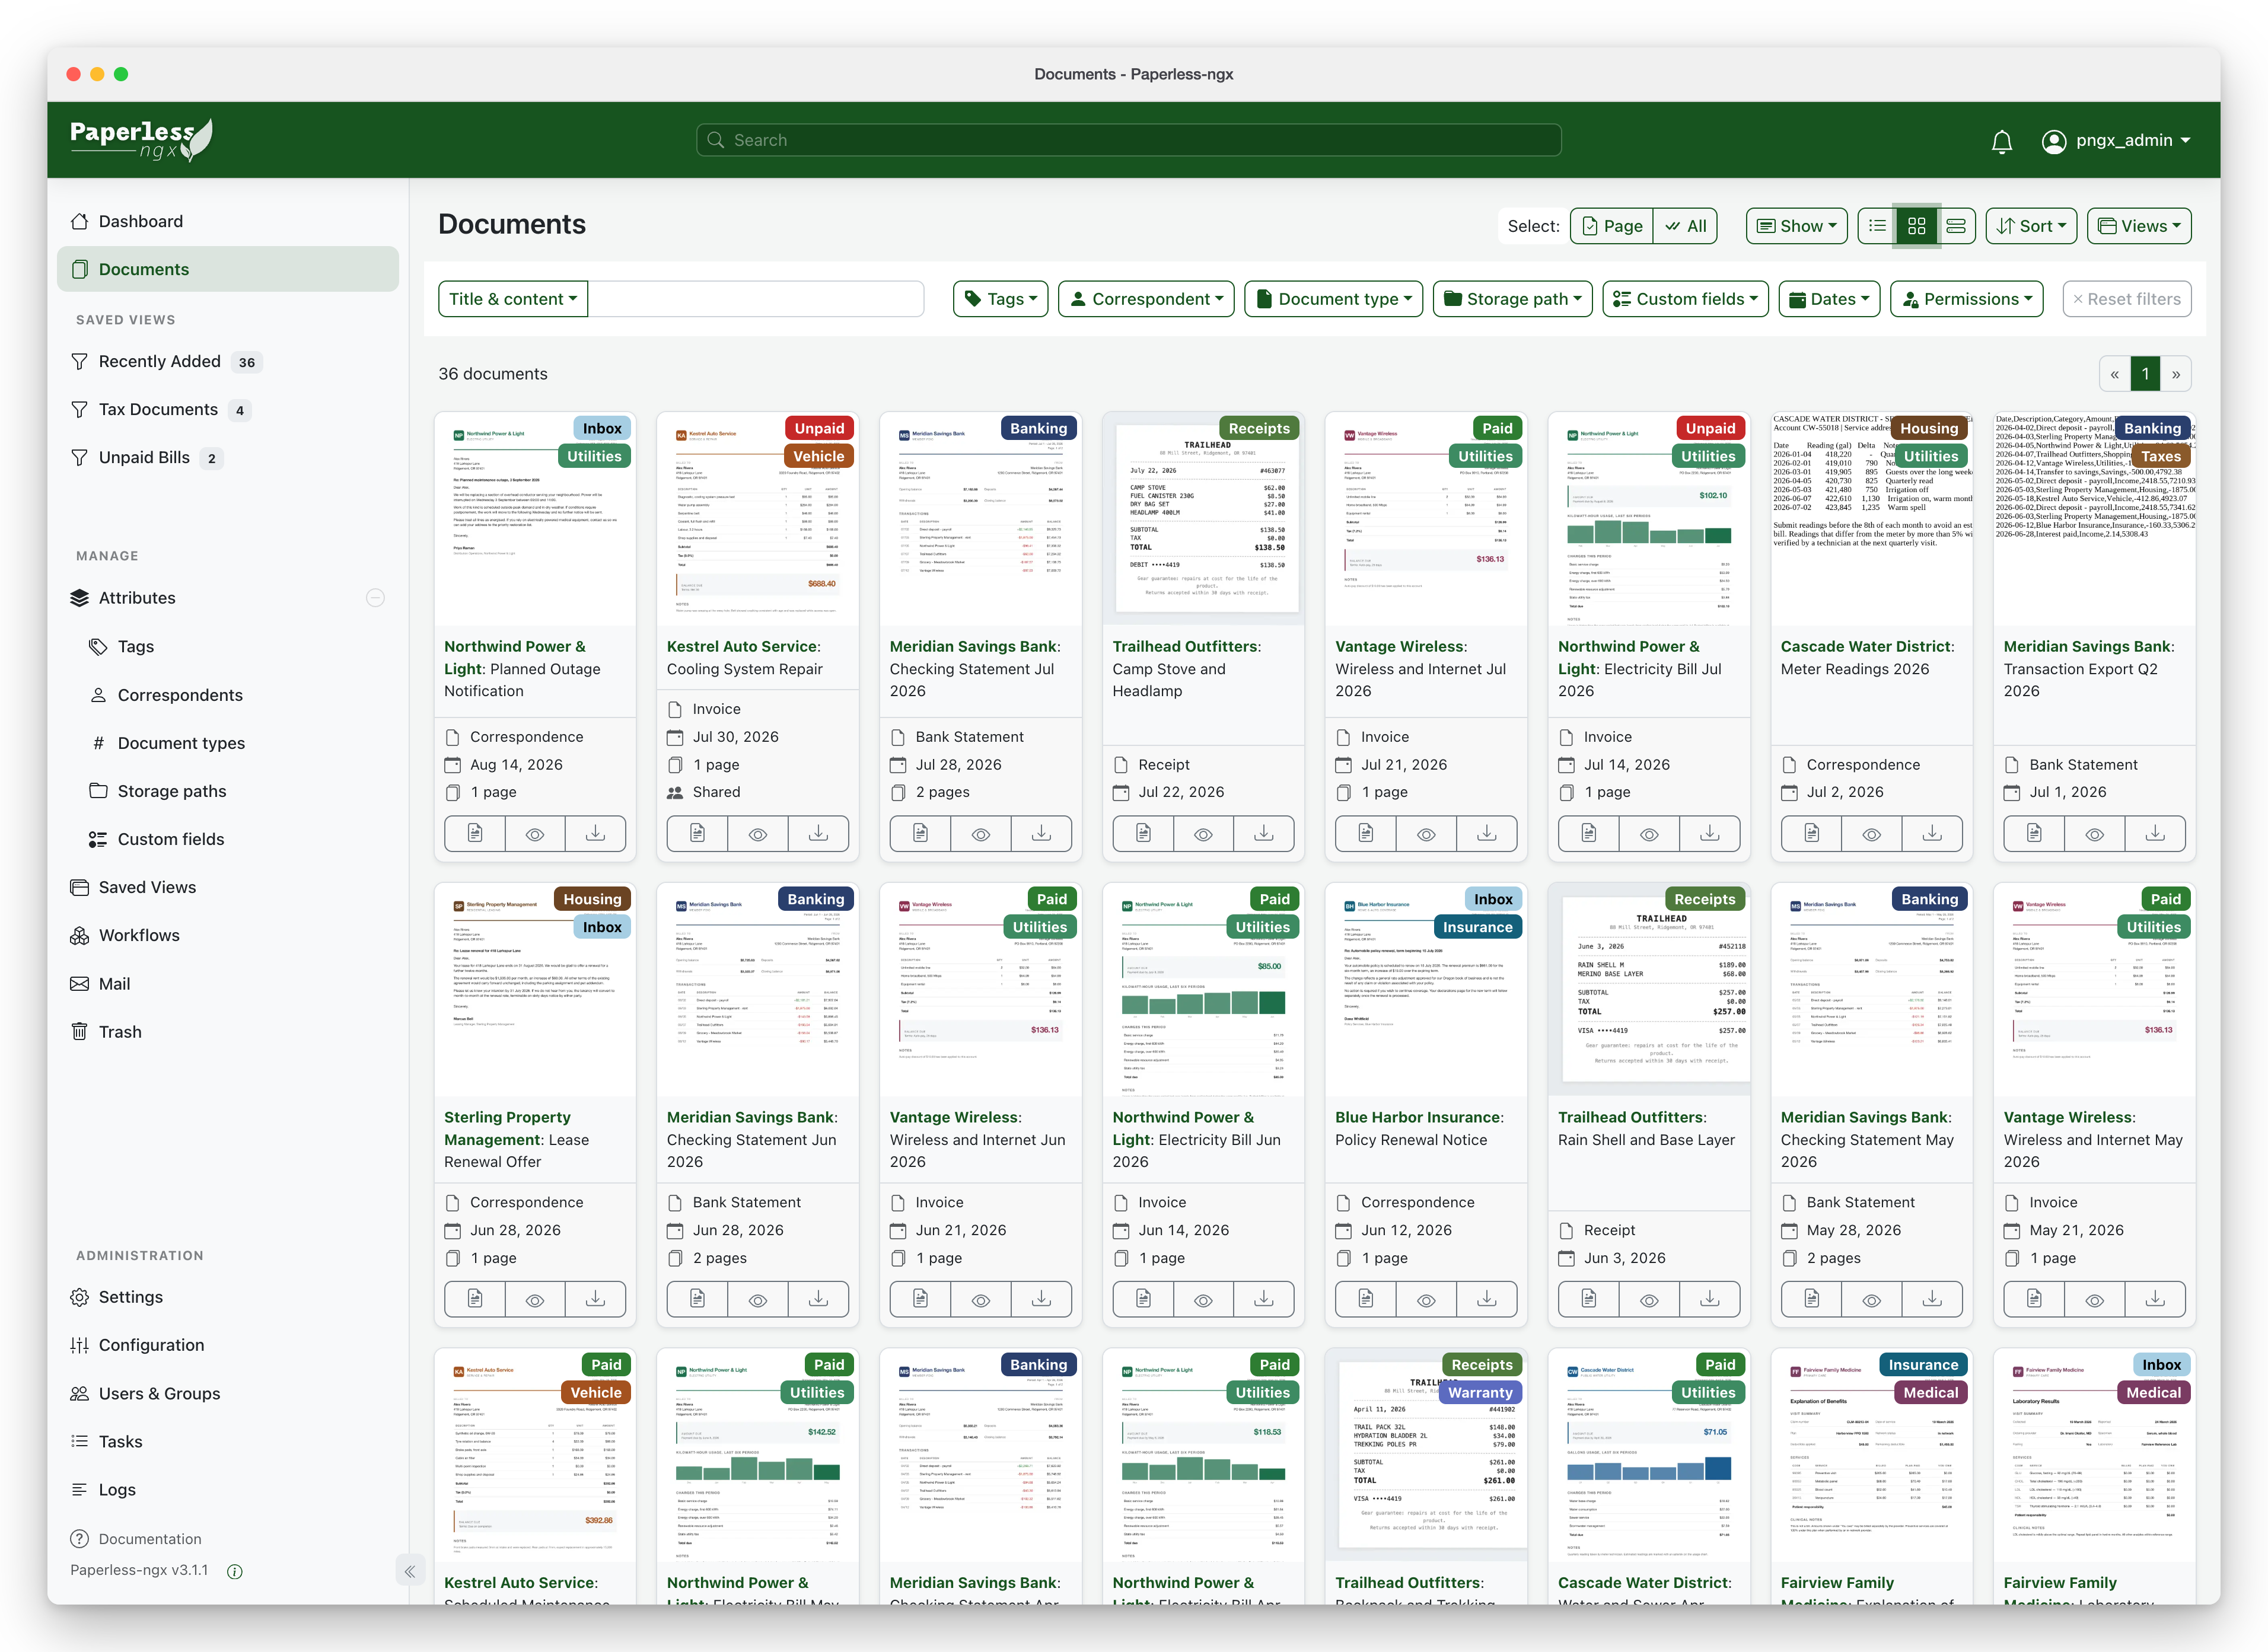
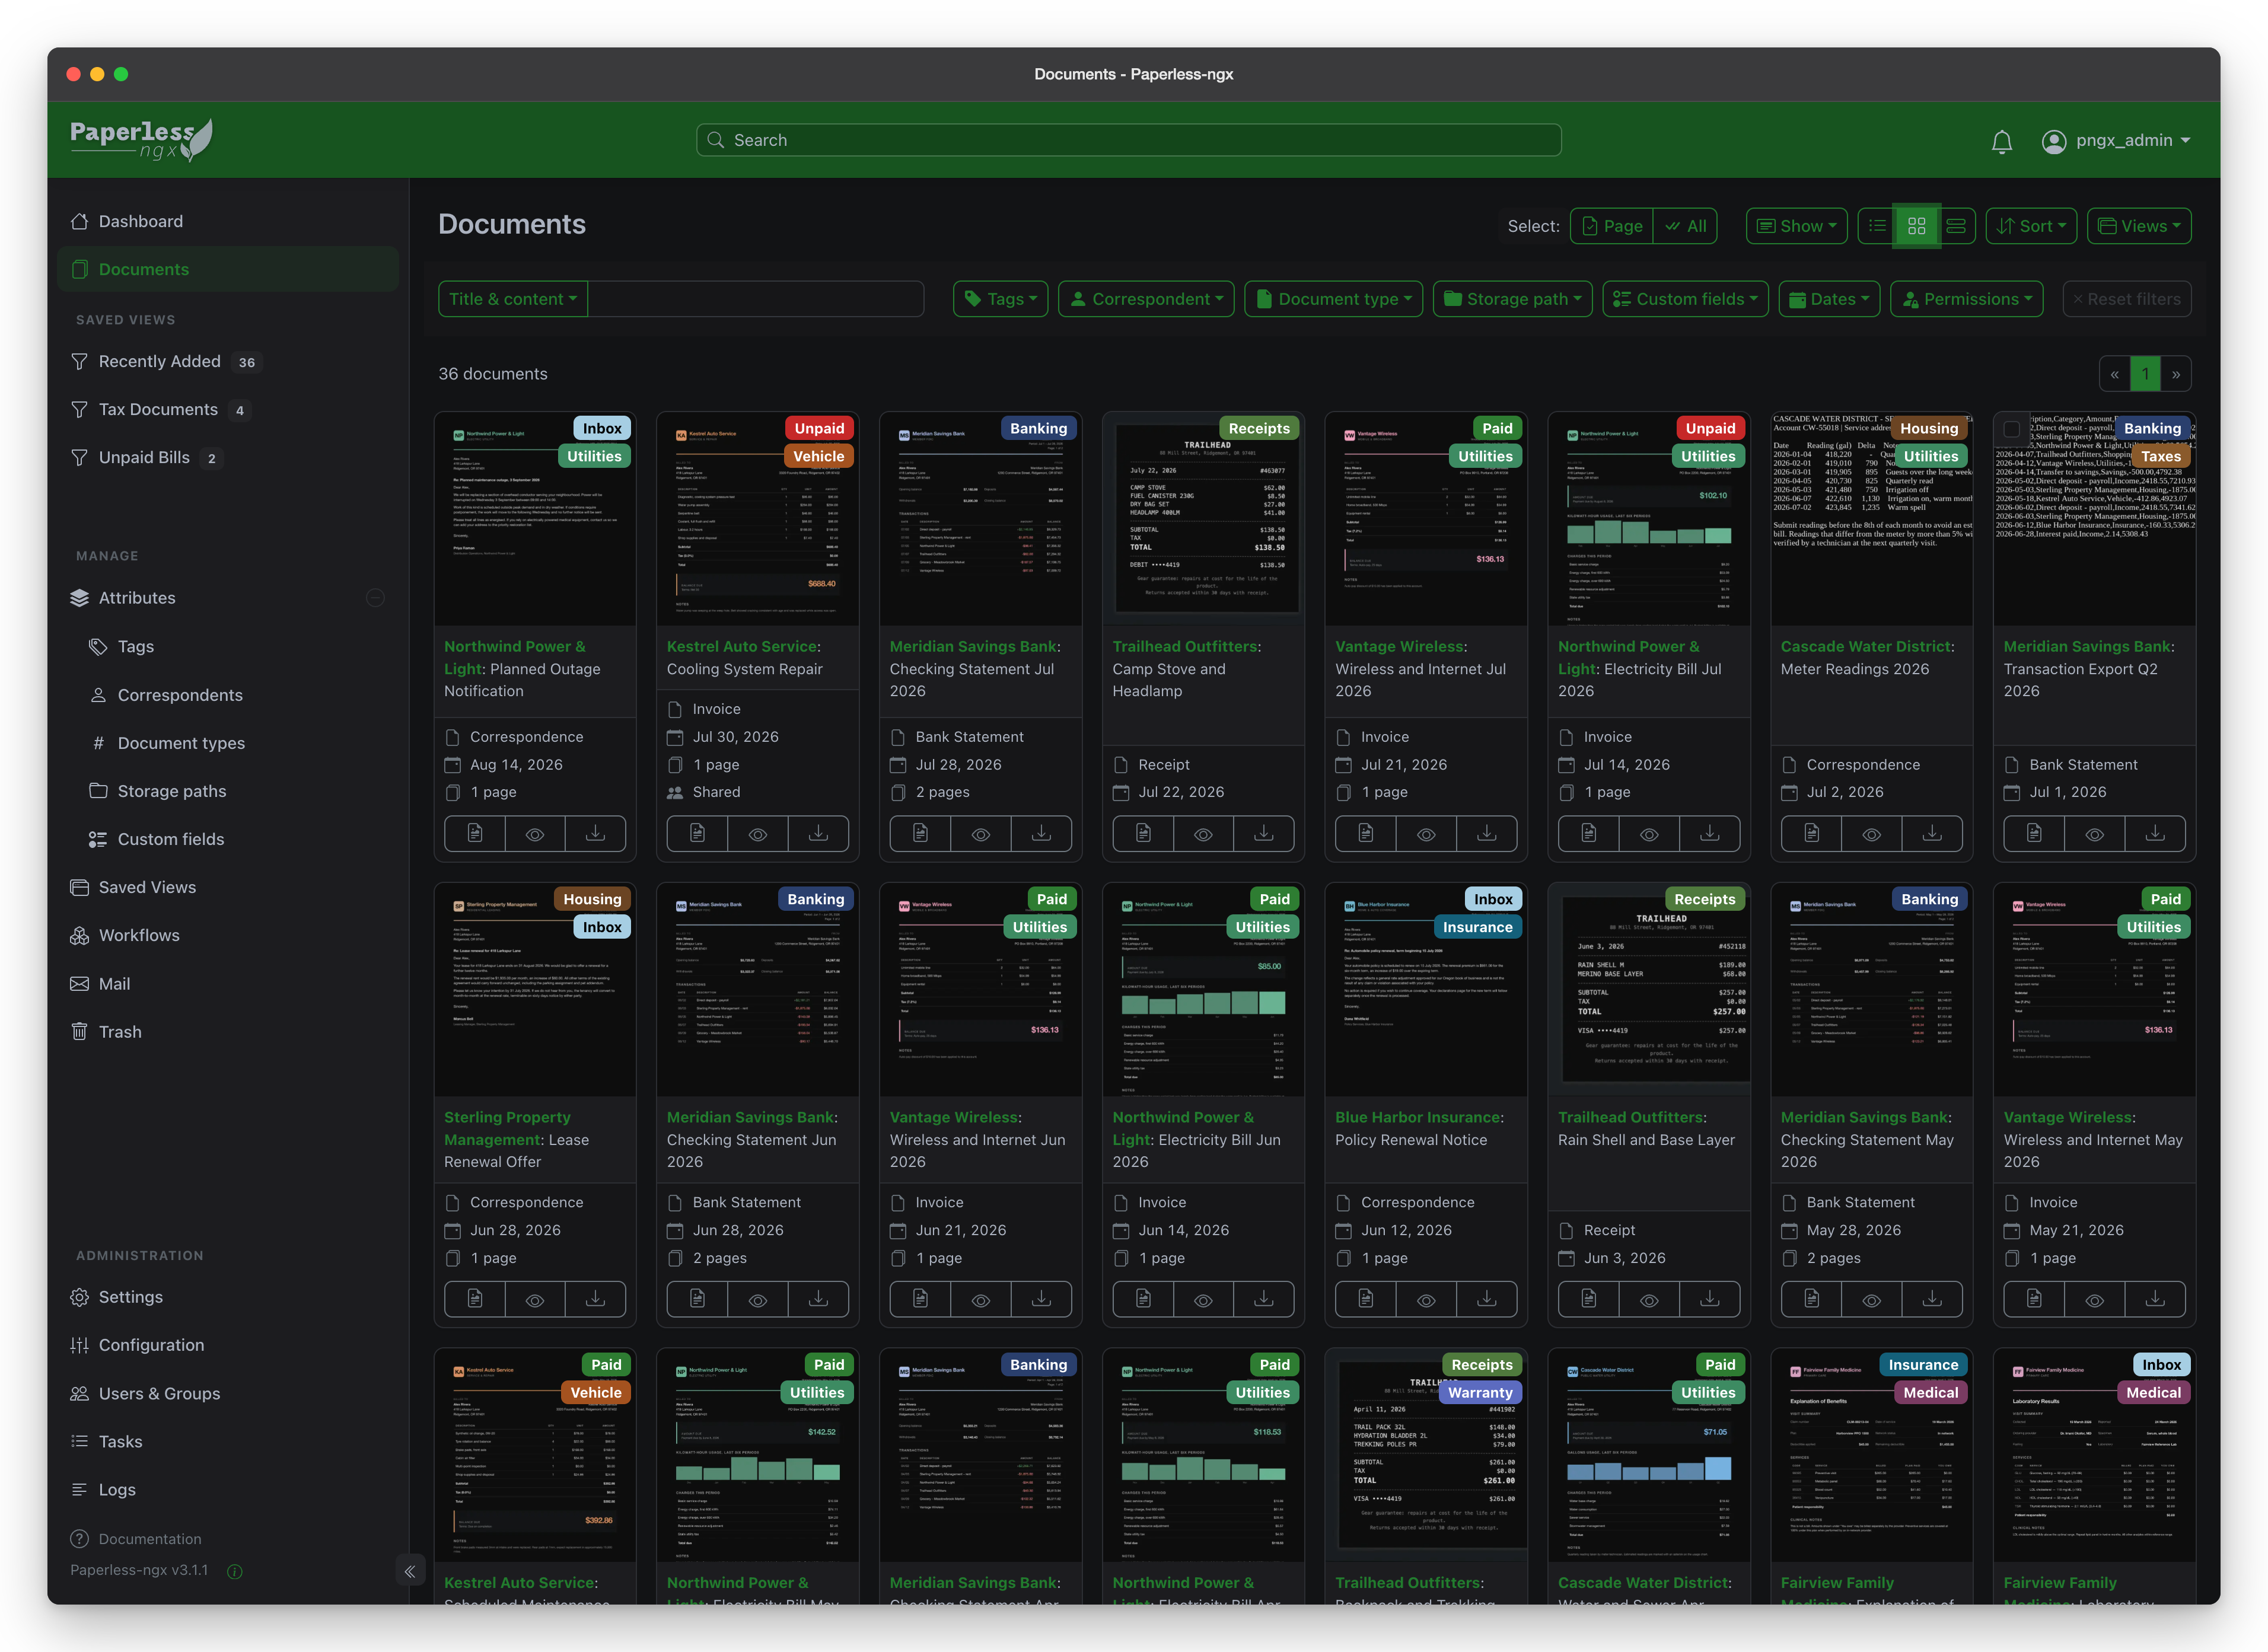
A self-hosted document management system written in Django. It watches a folder, runs OCR (reading text from a picture of a page) over anything that arrives, stores the original file plus a searchable PDF copy, and classifies each document by correspondent, document type and tags using a model that learns from your own corrections.
What it is good for. Anyone who is the only person responsible for their own paperwork, which is every solo founder. The problem it removes is the annual panic. Tax time stops being an archaeology project, and a supplier asking about an invoice from March takes ten seconds instead of an afternoon. It also works well for contracts, receipts and anything you scan once and need again in two years.
- It is honestly good at finding things. Full-text search across everything you have ever scanned, including the words inside pictures of pages.
- The classifier learns from you. After thirty corrections it starts filing new documents correctly on its own.
- Everything stays on your machine, and the original files are kept untouched beside the searchable copies.
- Setting it up means Docker Compose (a way of running several sealed programs together from one settings file). That is a real evening's work if you have never used it.
- The project states no minimum memory. Its own documentation has a section on running it on slower machines, which tells you that OCR is the heavy part, and a Raspberry Pi will be slow.
- GPL-3.0. Fine for running it yourself, and something to read carefully before building a product on top of it.
 eikek/docspell
Does the same job of reading, tagging and searching scanned documents, written in Scala and smaller in every way; its last release was March 2025, so check it before relying on it.
Track this in Scout sismics/docs
The project known as Teedy: document storage with OCR, full-text search, permissions and an approval workflow, aimed more at a small team than at one person.
Track this in Scout Stirling-Tools/Stirling-PDF
Not an archive at all, but the tool for everything you do to a PDF before filing it: split, merge, sign, compress, convert.
Track this in Scout
# The guided installer is the easiest route. It asks you questions
# and writes the files for you:
bash -c "$(curl --location --silent --show-error \
  https://raw.githubusercontent.com/paperless-ngx/paperless-ngx/main/install-paperless-ngx.sh)"
# By hand instead:
# 1. From https://github.com/paperless-ngx/paperless-ngx, in docker/compose/,
#    take ONE docker-compose.*.yml matching the database you want and save
#    it as docker-compose.yml. Pick the file with -tika in the name if you
#    also want Word documents read.
# 2. Take docker-compose.env and .env into the same folder.
# 3. Edit docker-compose.env. On Linux set USERMAP_UID and USERMAP_GID to
#    your own user and group, or the files it writes will not be yours.
docker compose pull
docker compose up -d